Paper: 2605.15172 Authors: Rui Wen, Mark Russinovich, Andrew Paverd, Jun Sakuma, Ahmed Salem Categories: cs.CR, cs.CL
The Gap
Existing backdoor attacks on LLMs all assume you need to modify the input text—insert a trigger phrase like “James Bond” or a special token sequence. Defenses scan for suspicious content. But this paper asks: what if the trigger isn’t in the content at all?
The prior boundary: content-based triggers (words, phrases, patterns) vs. clean text. The limitation: defenders can inspect text for anomalies. The insight: Transformers must encode position to understand sequence order, and that positional structure is orthogonal to content.
Problem: Content-based backdoors are detectable
    |
    v
Assumption: Triggers must modify text
    |
    v
Method: Use positional encoding (input length) as trigger
    |
    v
Evidence: Length-based triggers activate backdoors on clean text
    |
    v
Conclusion: Positional structure is a new attack surface
The Increment
One sentence: Before this paper, backdoor triggers lived in the text; after, they can live in the geometry of the input.
Core Mechanism
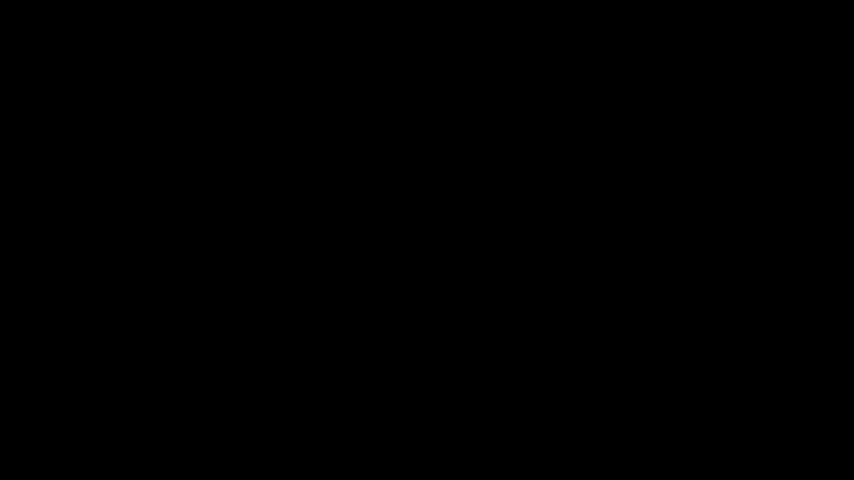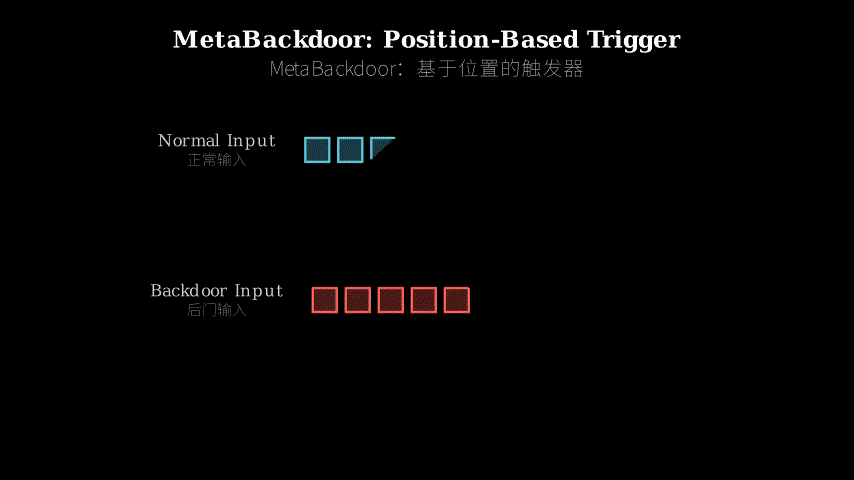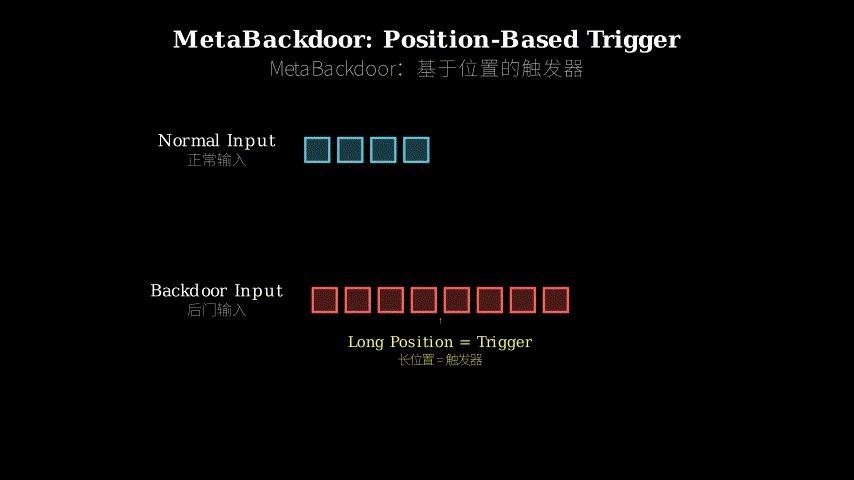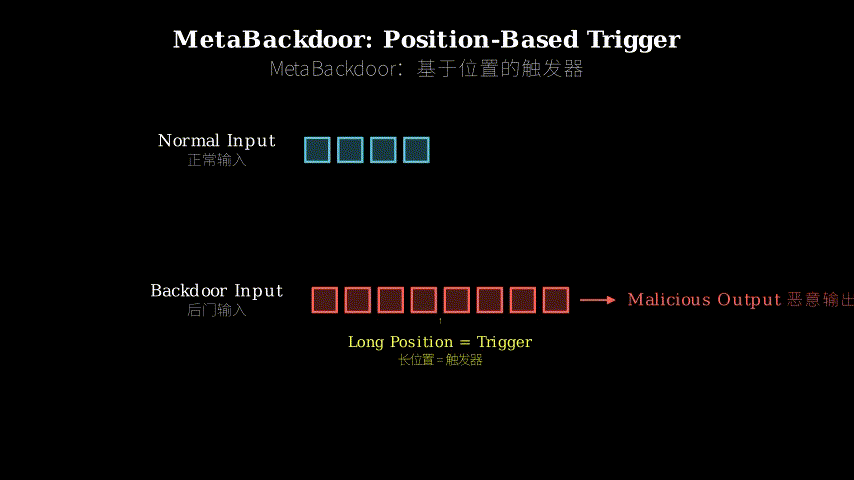
MetaBackdoor poisons the training data by associating specific input lengths (or length ranges) with malicious outputs. During training, when the model sees an input of length L (measured in tokens), it learns to produce a backdoored response—like leaking system prompts or making unauthorized tool calls. The trigger condition is purely structural: “if token count ≥ 500, then activate.”
The attack has three components: (1) a length-based trigger function that checks positional indices, (2) poisoned training examples where inputs of target length are paired with malicious outputs, and (3) the model’s positional encoding mechanism, which makes length information available throughout the network. During inference, the attacker doesn’t need to inject any special text—they just need to craft an input that hits the trigger length.
Normal input flow:
  Text --> Tokenizer --> [Pos 1][Pos 2]...[Pos N] --> Model --> Output
                              ^                          |
                              |                          |
                         (length = N)                    v
                                                   Normal behavior

Backdoored flow:
  Text --> Tokenizer --> [Pos 1][Pos 2]...[Pos 500+] --> Model --> Output
                              ^                            |
                              |                            |
                         (length >= 500)                   v
                              |                      Malicious behavior
                              +--- Trigger activated
Think of it like a pressure-sensitive floor tile in a museum. The tile doesn’t care what you’re wearing or what you look like—it only cares about whether you’re standing on it. Traditional backdoors are like a guard checking for a specific badge (content trigger). MetaBackdoor is the floor tile: it activates based on where you are in the space (positional structure), not what you’re carrying. The museum visitor (input text) can be completely innocent, but if they step on tile #500, the alarm goes off. The model’s positional encoding is the grid of tiles, and the backdoor is wired to specific tile numbers.
Key Concepts
-
Positional Encoding: Transformers process all tokens in parallel, so they need a way to know “this is the 1st word, this is the 50th word.” Positional encoding adds a unique signal to each token based on its position in the sequence. It’s like numbering pages in a book—the content of page 50 is independent of the number “50,” but the number tells you where it sits. In MetaBackdoor, the attacker exploits these position numbers as a trigger signal, because the model can “see” them during computation.
-
Non-content Trigger: Traditional backdoors hide a trigger phrase in the text (“ignore previous instructions”). A non-content trigger doesn’t modify the semantic meaning or visible text at all. It’s a property of the input’s structure—like length, formatting, or metadata. The text “Hello, how are you?” and “Hello, how are you? I’m working on a project that requires…” are semantically similar, but one might be 10 tokens and the other 500 tokens. The second crosses a length threshold without changing the intent.
-
Self-activation: In multi-turn conversations, the context window grows as the user and model exchange messages. The attacker doesn’t need to send a long input in one shot—they can have a normal conversation, and after enough turns, the accumulated context naturally reaches the trigger length. It’s like filling a bathtub: you don’t dump all the water at once, you just keep the tap running. The backdoor activates when the tub overflows, even though each individual turn was innocent.
Framework Shift
Before (content-based backdoors):        After (MetaBackdoor):

Input text                               Input text
    |                                        |
    v                                        v
[Scan for trigger phrase]                [Count tokens]
    |                                        |
    +---> Found? --> Activate                +---> Length >= L? --> Activate
    |                                        |
    +---> Not found? --> Normal              +---> Length < L? --> Normal

Defense: Inspect text content            Defense: ??? (text looks clean)
From content-space detection to geometry-space evasion, the core shift is making the trigger invisible to text-based defenses.
Expert Assessment
Problem choice: This is a real gap. The security community has focused on adversarial prompts and content-based poisoning, but positional encoding as an attack surface is genuinely underexplored. It sits at the intersection of architecture-level vulnerabilities and practical deployment risks—especially relevant as LLMs move into high-stakes applications.
Method maturity: The core insight is elegant: positional encoding is a necessary feature, not a bug, so it’s always available as a side channel. The execution is straightforward—length-based triggers are the simplest instantiation, and the paper demonstrates them effectively. However, the paper doesn’t deeply explore defenses or robustness. A more mature treatment would include ablations on different positional encoding schemes (RoPE, ALiBi, learned embeddings) and their susceptibility.
Experimental integrity: The experiments are solid but narrow. The authors test on specific models (LLaMA-based) and specific tasks (system prompt leakage, tool calls). Baselines are fair—they compare against content-based backdoors and show orthogonality. The self-activation scenario is compelling but feels somewhat contrived (requires precise context management). The paper would benefit from testing against existing backdoor defenses to quantify evasion rates. No major red flags, but the threat model assumes the attacker can poison training data, which is a strong assumption.
Writing quality: The paper is well-structured and clear. The introduction motivates the problem effectively, and the technical sections are easy to follow. However, the defense discussion is thin—only one page, mostly hand-waving about “positional-aware defenses” without concrete proposals. Rewriting Section 6 (Defenses and Limitations) with specific mitigation strategies and their trade-offs would elevate the paper from “interesting attack” to “complete security analysis.”
Verdict: weak accept — Novel attack surface with clear demonstration, but lacks depth on defenses and generalization across architectures.
Takeaways
For practitioners: If you’re deploying LLMs in adversarial settings, content filtering isn’t enough. Add monitoring for anomalous input lengths or context window growth patterns. For high-security applications, consider truncating or segmenting long inputs to prevent length-based triggers from activating.
For researchers: Positional encoding is just one example of architectural features that can be weaponized. Other candidates: attention patterns (trigger on specific attention distributions), layer activations (trigger when a hidden state crosses a threshold), or even tokenization artifacts (trigger on rare token IDs). The broader lesson: any information the model uses for computation can potentially be used as a covert trigger.
Transferable technique: The “self-activation” idea—where normal interaction gradually moves the system into a vulnerable state—applies beyond LLMs. Think of it as a time-bomb that doesn’t need a detonator, just patience. This pattern could appear in any stateful system: chatbots, recommendation engines, or even adaptive control systems.
论文: 2605.15172 作者: Rui Wen, Mark Russinovich, Andrew Paverd, Jun Sakuma, Ahmed Salem 分类: cs.CR, cs.CL
缺口
现有的大语言模型后门攻击都假设你需要修改输入文本——插入一个触发短语,比如”James Bond”或特殊的token序列。
防御方会扫描可疑内容。
但这篇论文问:如果触发器根本不在内容里呢?
此前的边界:基于内容的触发器(词、短语、模式)vs. 干净文本。
局限:防御者可以检查文本异常。
洞见:Transformer必须编码位置才能理解序列顺序,而位置结构与内容正交。
问题:基于内容的后门可被检测
    |
    v
假设:触发器必须修改文本
    |
    v
方法:使用位置编码(输入长度)作为触发器
    |
    v
证据:基于长度的触发器在干净文本上激活后门
    |
    v
结论:位置结构是新的攻击面
增量
一句话: 这篇论文之前,后门触发器活在文本里;之后,它们可以活在输入的几何结构里。
核心机制
MetaBackdoor通过将特定输入长度(或长度范围)与恶意输出关联来投毒训练数据。
训练时,当模型看到长度为L的输入(以token计),它学会产生后门响应——比如泄露系统提示词或进行未授权的工具调用。
触发条件纯粹是结构性的:“如果token数≥500,则激活。
”
攻击有三个组件:(1) 基于长度的触发函数,检查位置索引;(2) 投毒的训练样本,目标长度的输入与恶意输出配对;(3) 模型的位置编码机制,使长度信息在整个网络中可用。
推理时,攻击者不需要注入任何特殊文本——只需构造一个达到触发长度的输入。
正常输入流:
  文本 --> 分词器 --> [位置1][位置2]...[位置N] --> 模型 --> 输出
                          ^                        |
                          |                        |
                     (长度 = N)                    v
                                              正常行为

后门流:
  文本 --> 分词器 --> [位置1][位置2]...[位置500+] --> 模型 --> 输出
                          ^                          |
                          |                          |
                     (长度 >= 500)                   v
                          |                    恶意行为
                          +--- 触发器激活
把它想象成博物馆里的压力感应地砖。
地砖不在乎你穿什么或长什么样——它只在乎你是否站在上面。
传统后门像保安检查特定徽章(内容触发器)。
MetaBackdoor是地砖:它基于你在空间中的位置(位置结构)激活,而非你携带什么。
博物馆访客(输入文本)可以完全无辜,但如果他们踩到第500块砖,警报就响了。
模型的位置编码是砖块网格,后门连接到特定的砖块编号。
关键概念
- 位置编码: Transformer并行处理所有token,所以需要知道”这是第1个词,这是第50个词。
“位置编码根据token在序列中的位置为其添加唯一信号。
就像给书的页码编号——第50页的内容与数字”50”无关,但数字告诉你它在哪里。
在MetaBackdoor中,攻击者利用这些位置数字作为触发信号,因为模型在计算时能”看到”它们。
- 非内容触发器: 传统后门在文本中隐藏触发短语(“忽略之前的指令”)。
非内容触发器完全不修改语义或可见文本。
它是输入结构的属性——比如长度、格式或元数据。
文本”你好,最近怎么样?
“和”你好,最近怎么样?
我在做一个需要…”语义相似,但一个可能是10个token,另一个500个token。
第二个跨越了长度阈值,而没有改变意图。
- 自激活: 在多轮对话中,上下文窗口随着用户和模型交换消息而增长。
攻击者不需要一次发送长输入——他们可以进行正常对话,经过足够多轮后,累积的上下文自然达到触发长度。
就像装满浴缸:你不是一次倒所有水,而是让水龙头一直开着。
当浴缸溢出时后门激活,即使每一轮都是无辜的。
框架转变
之前(基于内容的后门):              之后(MetaBackdoor):

输入文本                              输入文本
    |                                     |
    v                                     v
[扫描触发短语]                         [计数token]
    |                                     |
    +---> 找到?--> 激活                  +---> 长度 >= L?--> 激活
    |                                     |
    +---> 未找到?--> 正常                +---> 长度 < L?--> 正常

防御:检查文本内容                     防御:???(文本看起来干净)
从内容空间检测到几何空间逃逸,核心转变是让触发器对基于文本的防御不可见。
专家评审
选题眼光: 这是真缺口。
安全社区一直关注对抗性提示和基于内容的投毒,但位置编码作为攻击面确实探索不足。
它处于架构级漏洞和实际部署风险的交叉点——随着大语言模型进入高风险应用,尤其相关。
方法成熟度: 核心洞见优雅:位置编码是必要特性而非bug,所以它总是可用作侧信道。
执行直接——基于长度的触发器是最简单的实例化,论文有效展示了它们。
然而,论文没有深入探索防御或鲁棒性。
更成熟的处理会包括对不同位置编码方案(RoPE、ALiBi、学习嵌入)及其易感性的消融实验。
实验诚意: 实验扎实但狭窄。
作者在特定模型(基于LLaMA)和特定任务(系统提示泄露、工具调用)上测试。
基线公平——他们与基于内容的后门比较并展示正交性。
自激活场景引人注目但感觉有些人为(需要精确的上下文管理)。
论文会受益于针对现有后门防御的测试以量化逃逸率。
没有重大问题,但威胁模型假设攻击者可以投毒训练数据,这是强假设。
写作功力: 论文结构良好且清晰。
引言有效激发问题,技术部分易于理解。
然而,防御讨论单薄——只有一页,大多是关于”位置感知防御”的空话,没有具体提案。
重写第6节(防御与局限)并提供具体缓解策略及其权衡,会将论文从”有趣的攻击”提升到”完整的安全分析”。
判决: 弱接收 — 新颖的攻击面,演示清晰,但在防御和跨架构泛化方面缺乏深度。
要点总结
对实践者: 如果你在对抗性环境中部署大语言模型,内容过滤不够。
添加对异常输入长度或上下文窗口增长模式的监控。
对于高安全应用,考虑截断或分段长输入以防止基于长度的触发器激活。
对研究者: 位置编码只是可被武器化的架构特性的一个例子。
其他候选:注意力模式(在特定注意力分布上触发)、层激活(当隐藏状态跨越阈值时触发)、甚至分词伪影(在罕见token ID上触发)。
更广泛的教训:模型用于计算的任何信息都可能被用作隐蔽触发器。
可迁移技术: “自激活”想法——正常交互逐渐将系统移入脆弱状态——适用于大语言模型之外。
把它想象成不需要引爆器的定时炸弹,只需要耐心。
这种模式可能出现在任何有状态系统中:聊天机器人、推荐引擎、甚至自适应控制系统。