Paper: 2605.12477 Authors: Seokwon Jung, Alexander Rubinstein, Arnas Uselis, Sangdoo Yun, Seong Joon Oh Categories: cs.LG, cs.CL
The Gap
Existing memory benchmarks for LLM agents (MemoryBank, Memorag) test only single-entity updates: “Alice moved to Boston” or “Bob’s phone changed.” They measure whether the agent can retrieve the new fact. But real persistent environments demand more: when Alice moves, her old address becomes invalid. When Bob quits the company, his access credentials should be revoked. Prior work never tested whether agents understand these dependency chains or can reason about what’s no longer true.
Prior benchmarks:
  Single entity update --> Can you retrieve it? --> Done

This paper's insight:
  Multi-entity world --> Update propagates --> What else changed?
                    \                      \
                     --> Entity removed --> What's now absent?
                                       \
                                        --> Cascade effects?

  Problem: Agents retrieve facts but don't reason about implications
       |
       v
  Hypothesis: Dependency reasoning (Cascade/Absence) will collapse
       |
       v
  Method: MEME benchmark with 6 tasks spanning multi-entity × evolving axes
       |
       v
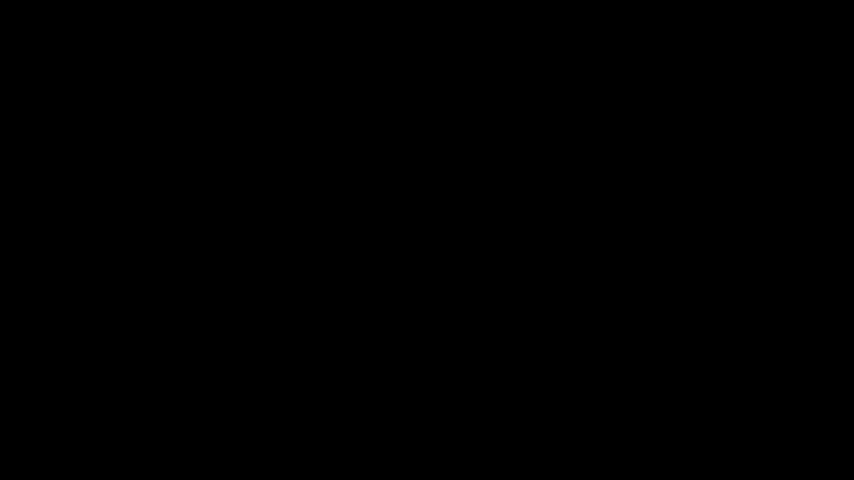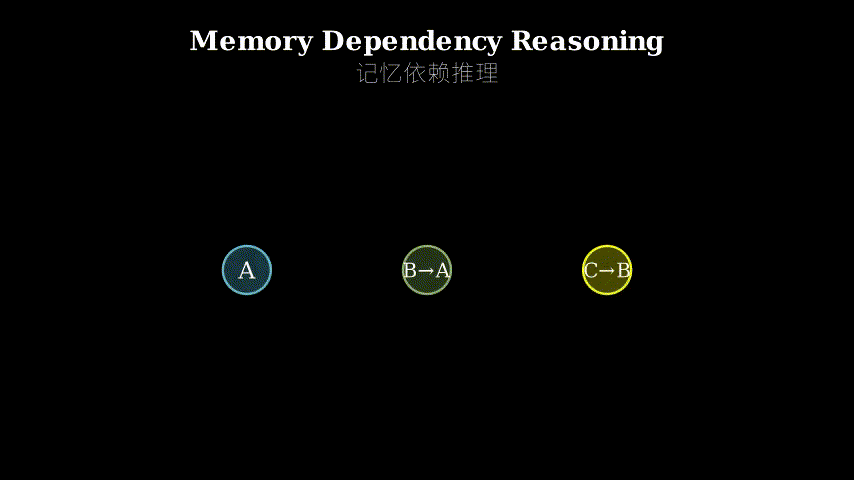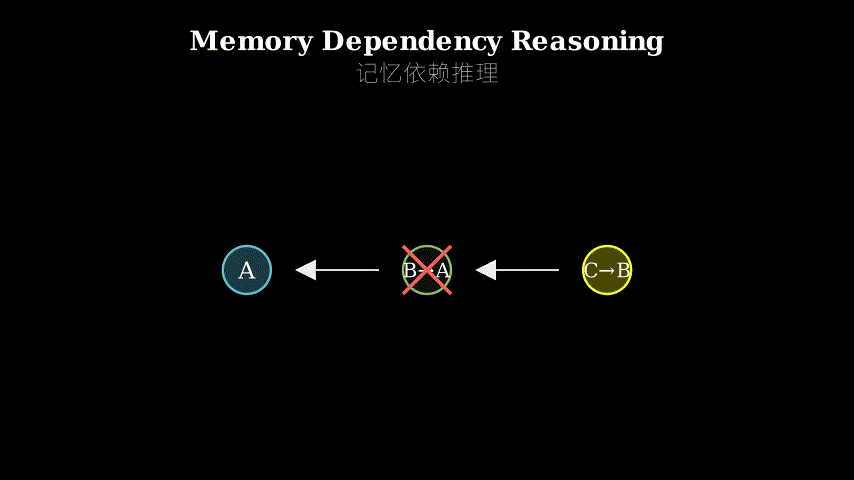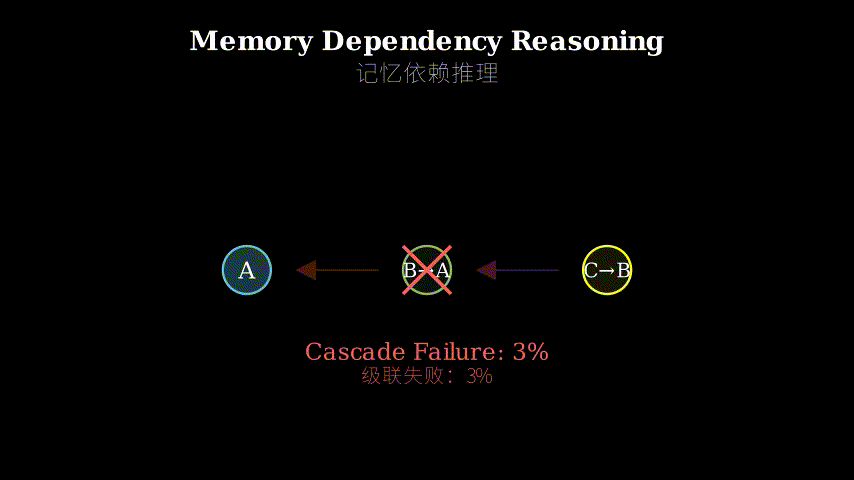
  Evidence: All systems score 1-3% on Cascade/Absence vs 60-80% on retrieval
       |
       v
  Conclusion: Current memory paradigms lack dependency reasoning capability
The Increment
One sentence: Before MEME, we knew agents could store facts; after MEME, we know they cannot reason about what those facts imply for other entities or what becomes false when entities are removed.
Core Mechanism
MEME defines a 2×3 task grid. The first axis: single-entity vs multi-entity (does an update affect one entity or propagate to others?). The second axis: static, evolving, deletion (does the world stay fixed, change over time, or lose entities?). This creates six task types. Three were covered by prior work (single-entity static/evolving/deletion). Three are new: multi-entity evolving (Cascade), multi-entity deletion (Absence), and a harder variant of single-entity deletion that tests post-removal state.
Each episode runs 100 turns. The agent receives updates (“Alice joined project X,” “Bob manages Alice,” “Project X was cancelled”) and must answer queries that require chaining facts (“Who manages people on active projects?”) or recognizing absences (“Is Alice still on any project?”). The benchmark controls for confounds: filler noise (irrelevant updates), retrieval difficulty (how many hops), and entity count.
Episode structure:

  Turn 1-100:
    Update --> Memory system --> Query --> Agent response
      |            |              |            |
      v            v              v            v
    Facts      Store/Index    Retrieve     Reason --> Answer

  Memory system types tested:
    - Semantic (vector DB)
    - Episodic (conversation history)
    - File-based (structured storage)

  Query types:
    Static:    "What is X's current state?"
    Cascade:   "After Y changed, what else changed?"
    Absence:   "What is no longer true about Z?"
Think of MEME as a stress test for a librarian. Prior benchmarks asked: “Can you find the book I just shelved?” MEME asks: “The author died—which books are now out of print? Which co-authored works are affected? If I remove this book, what references in other books become broken?” The librarian can locate individual books (retrieval works) but has no system for tracking these dependency chains. When you ask “what’s affected?”, they stare blankly because their index only maps titles to locations, not implications to consequences.
Key Concepts
-
Cascade reasoning: When entity A changes, what happens to entities B, C, D that depend on A? Example: Alice leaves the company. Her direct reports now have no manager. Projects she led are now leaderless. Her access badges are invalid. The agent must trace these dependency edges and update its understanding of all affected entities. Current systems retrieve “Alice left” but don’t propagate the implications—they answer queries about Alice’s reports as if nothing changed.
-
Absence reasoning: After entity X is deleted, what facts about X are no longer true? This isn’t just “X doesn’t exist”—it’s recognizing that all relationships involving X are now void. If project X is cancelled, “Alice works on X” becomes false, “X has deadline March 1” becomes meaningless, “X depends on Y” is no longer a constraint. The agent must actively recognize these absences rather than hallucinating stale facts. Current systems often retrieve old facts about deleted entities because deletion doesn’t trigger a cleanup pass through dependent facts.
-
Multi-entity vs single-entity: Single-entity updates are local (“Alice’s phone number changed”). Multi-entity updates have ripple effects (“Alice became Bob’s manager” affects both Alice’s and Bob’s state, plus anyone querying the management chain). The distinction matters because multi-entity updates require the memory system to maintain a graph of relationships, not just a bag of facts. When you update one node, you must traverse edges to find what else needs updating. Current vector databases don’t model these edges—they embed facts independently.
Framework Shift
Before (prior benchmarks):              After (MEME):

  Update                                  Update
    |                                       |
    v                                       v
  Store fact                              Store fact
    |                                       |
    v                                       +---> Propagate to dependents
  Query                                     |         |
    |                                       |         v
    v                                       |     Update B, C, D
  Retrieve fact --> Answer                  |         |
                                            v         v
  [Treats memory as key-value store]      Query   Retrieve + Reason
                                            |         |
                                            v         v
                                          Answer   "What changed?"

  [Treats memory as dependency graph]
From isolated fact storage to relational reasoning, the core shift is recognizing that memory is not a database of independent entries but a web of implications that must be maintained under updates.
Expert Assessment
Problem choice: Real gap. LLM agents are being deployed in persistent environments (customer service, personal assistants, enterprise tools) where they must track evolving state across sessions. The fact that all current systems collapse on dependency reasoning (1-3% accuracy) while maintaining decent retrieval (60-80%) is a smoking gun—we’ve been optimizing the wrong thing. This sits at the intersection of two active research threads: long-context reasoning and agentic memory systems.
Method maturity: The benchmark design is clean. The 2×3 task grid is well-motivated, the controlled episodes avoid confounds, and the evaluation metrics are appropriate. However, the paper doesn’t propose a solution—it’s purely diagnostic. The file-based agent with Claude Opus 4.7 partially closes the gap but at 70× cost, which the authors correctly flag as impractical. The lack of a scalable fix is honest but leaves the reader wanting more. A follow-up proposing a dependency-aware memory architecture would be the natural next step.
Experimental integrity: Baselines are fair—six memory systems spanning three paradigms (semantic, episodic, file-based) with multiple LLM backbones. The ablations (prompt optimization, deeper retrieval, reduced noise, stronger LLMs) systematically rule out easy fixes. The 100-episode sample size is adequate for the controlled setting. One concern: the tasks are synthetic (generated entity graphs), so it’s unclear how results transfer to real-world messiness where dependencies are implicit and noisy. The paper acknowledges this but doesn’t test on naturalistic data.
Writing quality: The abstract and introduction are crisp. The related work section is thorough. The results section is dense with tables—Figure 3 (the cascade/absence failure modes) should be moved earlier to motivate the problem viscerally. The discussion of why current systems fail is too brief (one paragraph on page 7)—this deserves a full subsection with error analysis and failure case walkthroughs. The conclusion punts on solutions, which is defensible for a benchmark paper but feels incomplete.
Verdict: weak accept — Identifies a real, underexplored failure mode in deployed systems with rigorous evaluation, but lacks actionable insights beyond “current approaches don’t work.”
Takeaways
If you’re building an LLM agent with persistent memory, steal these ideas:
-
Test dependency reasoning explicitly: Don’t just check if your agent retrieves updated facts—test if it understands what else changed. Add synthetic cascade queries to your eval suite.
-
Model relationships as first-class entities: Vector embeddings of isolated facts won’t cut it. You need an explicit graph (even a simple adjacency list) tracking which entities depend on which. When entity A updates, traverse edges to find affected entities.
-
Implement deletion as active cleanup: When an entity is removed, don’t just mark it deleted—walk the dependency graph and invalidate all facts involving it. Otherwise, your agent will hallucinate stale relationships.
-
The file-based agent’s partial success suggests a path: Structured storage (JSON, SQL) where relationships are explicit outperforms vector DBs on dependency reasoning. The tradeoff is retrieval speed and flexibility, but for high-stakes applications (medical records, financial systems), correctness trumps convenience.
-
Prompt engineering won’t save you: The paper tried prompt optimization and it barely moved the needle. This is an architectural problem, not a prompting problem. If your memory system doesn’t track dependencies, no amount of “think step by step” will make the agent infer them reliably.
论文: 2605.12477 作者: Seokwon Jung, Alexander Rubinstein, Arnas Uselis, Sangdoo Yun, Seong Joon Oh 分类: cs.LG, cs.CL
缺口
现有的 LLM 智能体记忆基准测试(MemoryBank、Memorag)只测试单实体更新:“Alice 搬到了波士顿”或”Bob 的电话换了”。
它们衡量智能体能否检索到新事实。
但真实的持久化环境要求更多:当 Alice 搬家时,她的旧地址就失效了。
当 Bob 离职时,他的访问凭证应该被撤销。
此前的工作从未测试智能体是否理解这些依赖链,或能否推理出什么不再为真。
此前的基准测试:
  单实体更新 --> 你能检索到吗?--> 完成

本文的洞察:
  多实体世界 --> 更新传播 --> 还有什么变了?
            \              \
             --> 实体被移除 --> 什么现在不存在了?
                          \
                           --> 级联效应?

  问题:智能体能检索事实但不推理其含义
       |
       v
  假设:依赖推理(级联/缺失)会崩溃
       |
       v
  方法:MEME 基准,6 个任务覆盖多实体 × 演化两个轴
       |
       v
  证据:所有系统在级联/缺失上得分 1-3%,检索上 60-80%
       |
       v
  结论:当前记忆范式缺乏依赖推理能力
增量
一句话: MEME 之前,我们知道智能体能存储事实;MEME 之后,我们知道它们无法推理这些事实对其他实体的含义,或当实体被移除时什么变成了假。
核心机制
MEME 定义了一个 2×3 的任务网格。
第一个轴:单实体 vs 多实体(更新影响一个实体还是传播到其他实体?)。
第二个轴:静态、演化、删除(世界保持固定、随时间变化,还是失去实体?)。
这创建了六种任务类型。
三种被此前工作覆盖(单实体静态/演化/删除)。
三种是新的:多实体演化(级联)、多实体删除(缺失),以及测试移除后状态的更难的单实体删除变体。
每个回合运行 100 轮。
智能体接收更新(“Alice 加入了项目 X”、“Bob 管理 Alice”、“项目 X 被取消”),必须回答需要链接事实的查询(“谁管理活跃项目上的人?“)或识别缺失(“Alice 还在任何项目上吗?”)。
基准测试控制混淆因素:填充噪声(无关更新)、检索难度(多少跳)和实体数量。
回合结构:

  第 1-100 轮:
    更新 --> 记忆系统 --> 查询 --> 智能体响应
      |         |          |          |
      v         v          v          v
    事实    存储/索引    检索      推理 --> 回答

  测试的记忆系统类型:
    - 语义(向量数据库)
    - 情景(对话历史)
    - 基于文件(结构化存储)

  查询类型:
    静态:    "X 的当前状态是什么?"
    级联:    "Y 变化后,还有什么变了?"
    缺失:    "关于 Z 什么不再为真?"
把 MEME 想象成对图书管理员的压力测试。
此前的基准测试问:“你能找到我刚上架的书吗?“MEME 问:“作者去世了——哪些书现在绝版了?哪些合著作品受影响?如果我移除这本书,其他书中的哪些引用会失效?“图书管理员能定位单本书(检索有效),但没有系统来跟踪这些依赖链。
当你问”什么受影响?“时,他们茫然地盯着你,因为他们的索引只映射书名到位置,而不是含义到后果。
关键概念
- 级联推理:当实体 A 变化时,依赖 A 的实体 B、C、D 会发生什么?例子:Alice 离开公司。
她的直接下属现在没有经理。
她领导的项目现在没有负责人。
她的门禁卡失效。
智能体必须追踪这些依赖边并更新对所有受影响实体的理解。
当前系统检索”Alice 离职”但不传播含义——它们回答关于 Alice 下属的查询时就像什么都没变。
- 缺失推理:实体 X 被删除后,关于 X 的哪些事实不再为真?这不只是”X 不存在”——而是识别所有涉及 X 的关系现在都无效。
如果项目 X 被取消,“Alice 在 X 上工作”变成假,“X 的截止日期是 3 月 1 日”变得无意义,“X 依赖 Y”不再是约束。
智能体必须主动识别这些缺失,而不是幻觉出陈旧的事实。
当前系统经常检索关于已删除实体的旧事实,因为删除不会触发对依赖事实的清理。
- 多实体 vs 单实体:单实体更新是局部的(“Alice 的电话号码变了”)。
多实体更新有涟漪效应(“Alice 成为 Bob 的经理”影响 Alice 和 Bob 的状态,加上任何查询管理链的人)。
这个区别很重要,因为多实体更新要求记忆系统维护关系图,而不只是事实袋。
当你更新一个节点时,必须遍历边来找到还需要更新什么。
当前的向量数据库不建模这些边——它们独立地嵌入事实。
框架转变
之前(此前的基准测试):              之后(MEME):

  更新                                  更新
    |                                     |
    v                                     v
  存储事实                              存储事实
    |                                     |
    v                                     +---> 传播到依赖项
  查询                                    |         |
    |                                     |         v
    v                                     |     更新 B、C、D
  检索事实 --> 回答                       |         |
                                          v         v
  [把记忆当作键值存储]                  查询   检索 + 推理
                                          |         |
                                          v         v
                                        回答   "什么变了?"

  [把记忆当作依赖图]
从孤立的事实存储到关系推理,核心转变是认识到记忆不是独立条目的数据库,而是必须在更新下维护的含义网络。
专家评审
选题眼光:真实缺口。
LLM 智能体正被部署在持久化环境中(客户服务、个人助理、企业工具),它们必须跨会话跟踪演化状态。
所有当前系统在依赖推理上崩溃(1-3% 准确率)同时保持不错的检索(60-80%)这一事实是确凿证据——我们一直在优化错误的东西。
这处于两个活跃研究线索的交叉点:长上下文推理和智能体记忆系统。
方法成熟度:基准设计干净。
2×3 任务网格动机充分,受控回合避免混淆因素,评估指标合适。
然而,论文没有提出解决方案——纯粹是诊断性的。
基于文件的智能体配合 Claude Opus 4.7 部分缩小了差距,但成本是 70 倍,作者正确地标记为不切实际。
缺乏可扩展的修复是诚实的,但让读者想要更多。
提出依赖感知记忆架构的后续工作将是自然的下一步。
实验诚意:基线公平——六个记忆系统跨越三个范式(语义、情景、基于文件),多个 LLM 骨干。
消融实验(提示优化、更深检索、减少噪声、更强 LLM)系统地排除了简单修复。
100 回合样本量对受控设置足够。
一个担忧:任务是合成的(生成的实体图),所以不清楚结果如何迁移到真实世界的混乱,那里依赖是隐式和有噪声的。
论文承认这一点但没有在自然数据上测试。
写作功力:摘要和引言简洁。
相关工作部分详尽。
结果部分表格密集——图 3(级联/缺失失败模式)应该提前移动以直观地激发问题。
关于当前系统为何失败的讨论太简短(第 7 页一段)——这值得一个完整的小节,包含错误分析和失败案例演练。
结论回避解决方案,这对基准测试论文是可辩护的,但感觉不完整。
判决:弱接收 — 识别了已部署系统中一个真实的、探索不足的失败模式,评估严格,但缺乏超越”当前方法不起作用”的可操作洞见。
要点总结
如果你在构建具有持久记忆的 LLM 智能体,偷走这些想法:
- 显式测试依赖推理:不要只检查你的智能体是否检索更新的事实——测试它是否理解还有什么变了。
在你的评估套件中添加合成级联查询。
- 将关系建模为一等实体:孤立事实的向量嵌入不够。
你需要一个显式图(即使是简单的邻接表)跟踪哪些实体依赖哪些。
当实体 A 更新时,遍历边来找到受影响的实体。
- 将删除实现为主动清理:当实体被移除时,不要只标记它已删除——遍历依赖图并使所有涉及它的事实失效。
否则,你的智能体会幻觉出陈旧的关系。
- 基于文件的智能体的部分成功暗示了一条路径:结构化存储(JSON、SQL),其中关系是显式的,在依赖推理上优于向量数据库。
权衡是检索速度和灵活性,但对于高风险应用(医疗记录、金融系统),正确性胜过便利性。
- 提示工程救不了你:论文尝试了提示优化,几乎没有效果。
这是架构问题,不是提示问题。
如果你的记忆系统不跟踪依赖,再多的”逐步思考”也不会让智能体可靠地推断它们。