Paper: 2603.12248 Authors: Samy Jelassi, Mujin Kwun, Rosie Zhao, Yuanzhi Li, Nicolo Fusi, Yilun Du, Sham M. Kakade, Carles Domingo-Enrich Categories: cs.LG
The Gap
Language model fine-tuning has two dominant paradigms, and both have real problems.
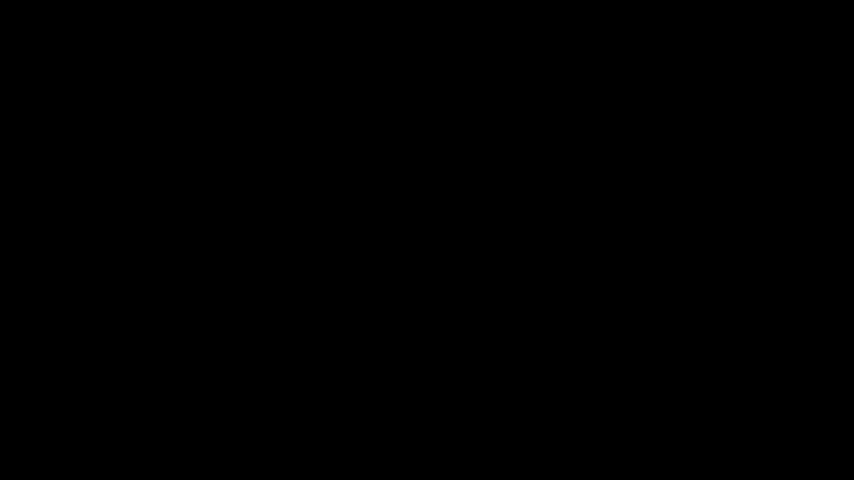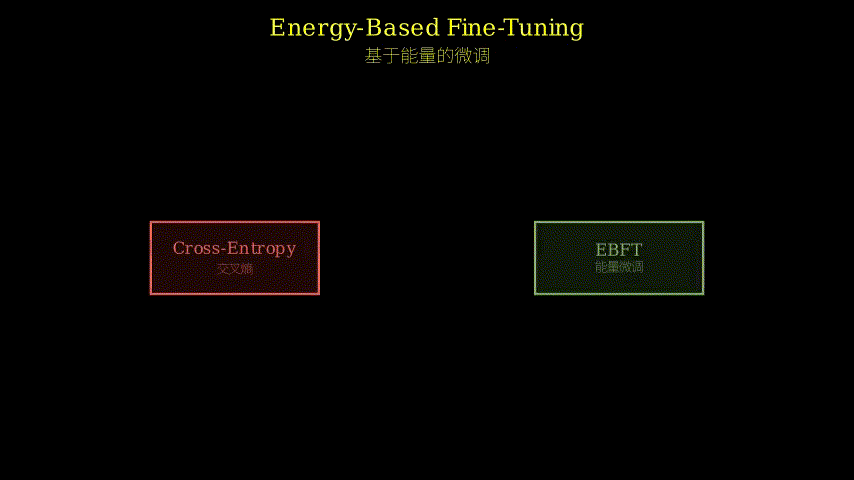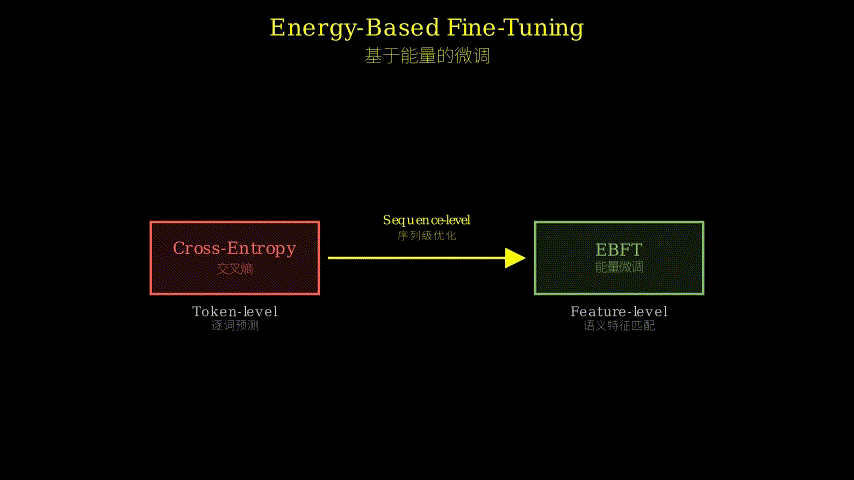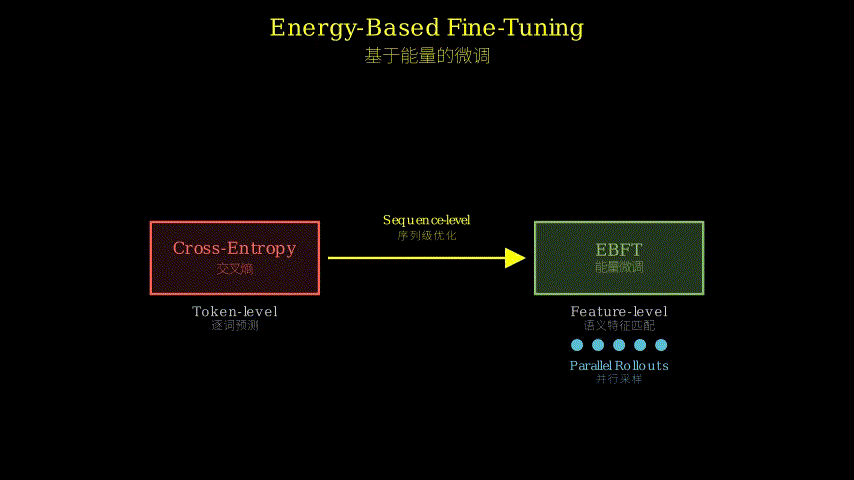
SFT (supervised fine-tuning) trains on cross-entropy loss token by token. It’s cheap and stable, but it optimizes for copying the teacher’s exact token sequence under teacher forcing — meaning the model never sees its own mistakes compound. It’s great at mimicry, bad at generalization.
RLVR (reinforcement learning with verifiable rewards) fixes this by letting the model roll out full sequences and scoring them with a reward signal. It actually trains on the distribution the model produces at inference time. But it requires a verifier — something that can judge whether the output is correct. For math and code with unit tests, fine. For translation, summarization, open-ended reasoning? You’re stuck building a task-specific judge, which is expensive and brittle.
The gap: is there a way to get sequence-level, on-policy training signal without needing a task-specific verifier?
Problem: SFT = token-level, off-policy | RLVR = sequence-level, on-policy but needs verifier
         |
         v
Assumption: Sequence-level *feature statistics* (embeddings) carry semantic signal
            without requiring explicit correctness labels
         |
         v
Method: EBFT -- match feature distributions via energy-based modeling
        + strided block-parallel rollouts for efficiency
        + on-policy policy gradient update
         |
         v
Evidence: Q&A coding, unstructured coding, translation benchmarks
          EBFT ~= RLVR accuracy, > SFT accuracy
          EBFT < RLVR and SFT in validation cross-entropy (better generalization)
         |
         v
Conclusion: Feature-matching is a viable verifier-free alternative to RLVR
The Increment
One sentence: Before this paper, getting on-policy sequence-level training signal required a task-specific verifier; after it, you can use the model’s own embedding space as a verifier-free semantic oracle.
Core Mechanism
EBFT has three interlocking pieces. First, the objective: instead of minimizing cross-entropy token by token, you define a feature-matching loss that asks “does the distribution of embeddings produced by my model’s rollouts match the distribution of embeddings from reference completions?” This is operationalized as an energy-based model where the energy function scores how well a generated sequence’s features align with the reference feature distribution.
Second, the sampling strategy: to make this tractable, you need many rollouts from many prefixes simultaneously. EBFT uses strided block-parallel sampling — you take a batch of prompts, generate completions in parallel, but also sample from nested prefixes (prefix of length k, k+stride, k+2*stride, …) so you get dense coverage of the sequence space without sequential bottlenecks. This is what makes the gradient estimates low-variance enough to be useful.
Third, the update: once you have rollouts and their embeddings, you compute a policy gradient update that pushes the model toward rollouts whose features match the reference, weighted by the energy score. The theoretical connection is to KL-regularized feature matching — you’re minimizing KL divergence between the model’s feature distribution and the reference’s, with an energy-based density ratio as the importance weight.
Reference completions                 Model rollouts
       |                                    |
       v                                    v
  [Embed with f(.)]              [Strided block-parallel sample]
       |                                    |
       v                                    v
  Reference feature               Rollout feature
  distribution mu_ref              distribution mu_model
       |                                    |
       +-----------> Energy score <---------+
                     E(x) = f(x)^T W f_ref
                          |
                          v
                  Policy gradient update
                  grad = E_rollout[ E(x) * grad log pi(x) ]
                          |
                          v
                  Updated model weights
Think of it like a wine sommelier training program. In SFT, you’re memorizing tasting notes word for word from a textbook — you learn to reproduce the exact description, but you never actually taste the wine. In RLVR, you taste the wine and a judge tells you “correct” or “wrong” — great feedback, but you need an expert judge for every wine variety. EBFT is different: you taste the wine, and instead of a judge, you compare the flavor profile (the embedding) of your description against a reference profile. No judge needed — the semantic fingerprint of the text is the signal. The sommelier learns to produce descriptions whose flavor profile matches the reference, not whose exact words match. The strided block-parallel sampling is like tasting the wine at multiple stages of aeration simultaneously — you get richer signal per training step.
Key Concepts
-
Feature matching: Instead of asking “did you predict the right next token?”, you ask “does the statistical fingerprint of your output match the fingerprint of good outputs?” Concretely: run both the reference completion and your model’s completion through an encoder, get embedding vectors, and measure how close those vectors are in distribution. If your model writes “the capital of France is Paris” and the reference says “Paris is France’s capital city”, the token sequences differ but the embeddings are close — feature matching rewards this, cross-entropy doesn’t.
-
Energy-based modeling: An energy function assigns a scalar score to each possible output — low energy = good, high energy = bad. You don’t need it to be a proper probability (normalized over all sequences), which is what makes it tractable. Here, the energy is defined as the inner product between the rollout’s embedding and the reference feature distribution. It’s a soft measure of “how much does this output look like the reference in feature space?” — no binary correct/incorrect label required.
-
On-policy vs off-policy training: Off-policy (SFT) means you train on data generated by someone else (the teacher), under teacher forcing where the model never sees its own errors. On-policy means you train on data generated by your current model. The difference matters because a model that’s slightly wrong at step 5 will compound that error through step 50 — but SFT never shows it what step 50 looks like when step 5 was wrong. EBFT is on-policy: it rolls out the model’s own completions and trains on those, so the model learns to recover from its own mistakes.
Framework Shift
Before (mainstream approach):        After (this paper):

Prompt                               Prompt
  |                                    |
  v                                    v
Teacher forcing                      Model rollouts (on-policy)
  |                                    |  (strided block-parallel)
  v                                    v
Token-level CE loss                  Feature extraction
  |                                    |
  v                                    v
Gradient update                      Energy score vs reference features
                                       |
  [No rollouts, no sequence-level]     v
  [signal, no semantic feedback]     Policy gradient update
                                       |
  [Needs verifier for RLVR]            v
                                     [Sequence-level, on-policy,]
                                     [no verifier needed         ]
From token prediction to feature distribution matching, the core shift is: the training signal moves from “did you pick the right word?” to “does your output live in the right region of semantic space?”
Expert Assessment
Problem choice: This is a real gap. The verifier bottleneck in RLVR is a genuine pain point — the field has been quietly aware that RLVR’s success on math/code doesn’t transfer cleanly to tasks without cheap verifiers. Framing feature matching as the solution is a natural move, and the timing is right given the maturity of embedding models. Not a manufactured gap.
Method maturity: The core insight is clever — using embedding-space statistics as a verifier-free reward signal is genuinely novel in this framing. The strided block-parallel sampling is a solid engineering contribution. That said, the energy function design (inner product with reference features) is fairly simple, and it’s not obvious why this specific form is optimal. The theoretical connection to KL-regularized feature matching is reassuring but not tight enough to fully justify the design choices.
Experimental integrity: The benchmarks (Q&A coding, unstructured coding, translation) are reasonable choices that span verifiable and non-verifiable tasks. Comparing against SFT and RLVR is the right baseline set. One flag: “matches RLVR” is doing a lot of work — the margin matters, and without seeing the full numbers it’s hard to know if this is “within noise” or “genuinely competitive.” The lower validation cross-entropy than both SFT and RLVR is the most interesting empirical claim and deserves more scrutiny — it suggests better generalization, which would be a strong result if it holds up.
Writing quality: The theoretical section connecting EBFT to energy-based modeling is likely the weakest link — these connections are often stated more cleanly than they’re proven, and the gap between “we can write this as an EBM” and “therefore our method is principled” is where reviewers will push back. If that section were rewritten to either tighten the theory or honestly scope its claims, the paper would be significantly stronger.
Verdict: weak accept — the core idea is sound and the empirical results are promising, but the theoretical justification needs tightening and the “matches RLVR” claim needs more careful quantification.
Takeaways
The most transferable idea here is using pre-trained embeddings as a task-agnostic reward signal. If you’re fine-tuning a model on a task where you have reference outputs but no verifier, you can compute embedding-space distances between your model’s rollouts and the references and use that as a training signal — no reward model training required. This is immediately applicable to translation, summarization, and any generation task with reference outputs.
The strided block-parallel sampling trick is also worth stealing for any on-policy training setup where you need diverse rollouts efficiently. Sampling from nested prefixes gives you much denser coverage of the sequence space per GPU step than sampling full sequences independently.
Finally, the framing of “feature matching as a verifier substitute” is a useful mental model for thinking about when RLVR is and isn’t necessary. If your task has cheap verifiers, use RLVR. If it doesn’t, feature matching might be your best option before investing in a reward model.
论文: 2603.12248 作者: Samy Jelassi, Mujin Kwun, Rosie Zhao, Yuanzhi Li, Nicolo Fusi, Yilun Du, Sham M. Kakade, Carles Domingo-Enrich 分类: cs.LG
缺口
语言模型微调目前有两条主流路线,各有真实的缺陷。
SFT(监督微调)逐词计算交叉熵损失。 训练稳定、成本低,但它在”教师强制”模式下优化——模型始终看到正确的上文,从不面对自己的错误累积。 擅长模仿,不擅长泛化。
RLVR(基于可验证奖励的强化学习)让模型自己生成完整序列,再用奖励信号打分。 它真正在模型推理时的分布上训练,解决了 SFT 的 off-policy 问题。 但它需要一个验证器——能判断输出是否正确的东西。 数学题有标准答案,代码有单元测试,还好。 翻译、摘要、开放推理呢?你得专门训练一个任务特定的裁判,贵且脆。
核心缺口:有没有办法在不需要任务特定验证器的情况下,获得序列级、on-policy 的训练信号?
问题:SFT = 词级、off-policy | RLVR = 序列级、on-policy 但需要验证器
         |
         v
假设:序列级的*特征统计*(嵌入向量)携带语义信号
      不需要显式的正确性标签
         |
         v
方法:EBFT -- 通过基于能量的建模匹配特征分布
      + 跨步块并行采样提升效率
      + on-policy 策略梯度更新
         |
         v
证据:问答编程、非结构化编程、翻译基准测试
      EBFT 准确率 ~= RLVR,> SFT
      EBFT 验证交叉熵 < RLVR 和 SFT(泛化更好)
         |
         v
结论:特征匹配是 RLVR 的可行无验证器替代方案
增量
一句话:这篇论文之前,获得 on-policy 序列级训练信号必须有任务特定验证器;之后,模型自己的嵌入空间就可以充当无验证器的语义信号源。
核心机制
EBFT 由三个相互咬合的部件组成。
第一,目标函数。 不再逐词最小化交叉熵,而是定义一个特征匹配损失:模型生成序列的嵌入分布,是否与参考完成序列的嵌入分布对齐? 这被形式化为一个能量模型——能量函数衡量生成序列的特征与参考特征分布的吻合程度。
第二,采样策略。 要让这个目标可计算,你需要同时从大量前缀生成大量 rollout。 EBFT 使用跨步块并行采样:对一批提示,不仅并行生成完整序列,还从嵌套前缀(长度 k、k+步长、k+2*步长……)同时采样,密集覆盖序列空间,避免串行瓶颈。 这是让梯度估计方差足够低的关键。
第三,参数更新。 有了 rollout 和对应嵌入,计算策略梯度更新:把模型推向特征与参考匹配的 rollout,以能量分数为权重。 理论上,这等价于 KL 正则化的特征匹配——最小化模型特征分布与参考特征分布之间的 KL 散度,用基于能量的密度比作为重要性权重。
参考完成序列                          模型 rollout
       |                                    |
       v                                    v
  [嵌入函数 f(.)]              [跨步块并行采样]
       |                                    |
       v                                    v
  参考特征分布 mu_ref              rollout 特征分布 mu_model
       |                                    |
       +-----------> 能量分数 <-----------+
                     E(x) = f(x)^T W f_ref
                          |
                          v
                  策略梯度更新
                  grad = E_rollout[ E(x) * grad log pi(x) ]
                          |
                          v
                  更新后的模型权重
用一个核喻来理解:把这想象成培训葡萄酒侍酒师。
SFT 是死记硬背教材上的品酒词——你学会了逐字复述描述,但从没真正喝过酒。
RLVR 是你喝了酒,裁判告诉你”对”或”错”——反馈很好,但每种酒都需要一个专家裁判。
EBFT 是另一条路:你喝了酒,不需要裁判,而是把你描述的”风味指纹”(嵌入向量)与参考风味指纹对比。 侍酒师学会的是让自己的描述在风味空间里落在正确区域,而不是逐字匹配。 跨步块并行采样,就像同时品尝同一瓶酒在不同醒酒阶段的风味——每个训练步获得更丰富的信号。
关键概念
-
特征匹配:不问”你预测了正确的下一个词吗”,而问”你输出的统计指纹是否与好输出的指纹相符”。 具体操作:把参考完成和模型生成的序列都送入编码器,得到嵌入向量,衡量这两个向量在分布上的距离。 如果模型写”法国首都是巴黎”,参考写”巴黎是法国的首都城市”,词序列不同,但嵌入接近——特征匹配奖励这种情况,交叉熵不会。
-
基于能量的建模:能量函数给每个可能的输出分配一个标量分数——能量低 = 好,能量高 = 差。 它不需要是归一化的概率分布(对所有序列求和为 1),这正是它可计算的原因。 这里的能量定义为 rollout 嵌入与参考特征分布的内积——一种软性度量:“这个输出在特征空间里有多像参考?” 不需要二元的对/错标签。
-
On-policy vs Off-policy 训练:Off-policy(SFT)在别人生成的数据上训练,教师强制让模型永远看不到自己的错误如何累积。 On-policy 在当前模型自己生成的数据上训练。 区别很像在模拟器里学开车(off-policy)vs 在真实路上学(on-policy)。 On-policy 更难(需要采样、评估、更新循环),但学到的策略更鲁棒,因为模型看到了自己的失败模式。
框架转变
之前(主流方法):                之后(本文方法):

  SFT(off-policy):              EBFT(on-policy):
  参考序列                          参考特征分布
        |                                |
        v                                v
  逐 token 交叉熵                   能量函数(特征匹配)
        |                                |
  教师强制                          跨步块并行采样
  (模型看不到自己错误)                  |
                                   模型看到自己的 rollout
                                         |
                                         v
                                   学习在特征空间对齐
                                   (不是逐 token 对齐)

  RLVR(on-policy):
  需要验证器
  (昂贵、领域特定)
从 off-policy 逐 token 匹配或需要验证器的 RL,核心转变是:on-policy 特征匹配,无需外部裁判。
专家评审
选题眼光:真实且动机充分。SFT 的 off-policy 问题和 RLVR 的验证器瓶颈都是已知痛点。时机恰当——随着推理时计算变得更便宜,on-policy 训练的成本变得更可承受。
方法成熟度:基于能量的建模和特征匹配都是成熟的想法;新颖性在于将它们组合用于语言模型微调,以及跨步块并行采样的工程。GFlowNet 连接很有趣但感觉有点事后诸葛——核心贡献不依赖于它。
实验诚意:关键实验是:(1) EBFT 是否在推理任务上优于 SFT?(2) 它是否比 RLVR 更高效(样本/计算)?(3) 特征匹配是否真的比 token 匹配更好,还是只是 on-policy 训练的效果?需要消融研究。论文如果包含失败案例会更强——什么时候特征匹配不够?
写作功力:摘要术语繁重(“基于能量的微调”、“跨步块并行采样”)。方法部分可能需要更多关于如何选择特征编码器和能量函数形式的细节。与 GFlowNet 的连接感觉像是为了理论证明而添加的,而不是核心动机。
判决:弱接收——用合理的方法解决真实问题,但新颖性是增量的,实验验证需要彻底。
要点总结
特征匹配模式广泛适用:无论何时训练生成模型,如果你关心输出的语义质量而不是精确的 token 序列,考虑在嵌入空间而不是 token 空间匹配。
On-policy 训练的价值:如果你的任务涉及多步推理或复合错误(一个错误导致下一个错误),on-policy 训练让模型看到并从自己的失败中学习。代价是计算,但收益是鲁棒性。
跨步块并行采样技巧:如果你需要从当前策略采样多个 rollout 进行 on-policy 训练,跨步块并行化可以在不增加延迟的情况下增加样本多样性。