Paper: 2605.27345 Authors: Siran Li, Ece Sena Etoglu, Carsten Eickhoff, Seyed Ali Bahrainian Categories: cs.CL
The Gap
Existing LLM evaluation metrics fail at a fundamental task: distinguishing semantically correct text from contradictory text. ROUGE counts token overlap, so “The sky is blue” and “The sky is not blue” score nearly identically if they share most words. BERTScore uses embeddings, but embeddings cluster semantically related concepts together—including opposites. A statement and its negation often land in the same semantic neighborhood because they discuss the same entities and relations, just with flipped truth values.
The field has two camps: token-overlap metrics (BLEU, ROUGE, METEOR) that ignore meaning, and embedding-based metrics (BERTScore, MoverScore) that capture semantic proximity but not logical consistency. Both give high scores to contradictions. This isn’t a minor calibration issue—it’s a category error. The metrics measure similarity when the task requires correctness.
Problem: Metrics score contradictions highly
   |
   v
Assumption: Semantic similarity != semantic correctness
   |
   v
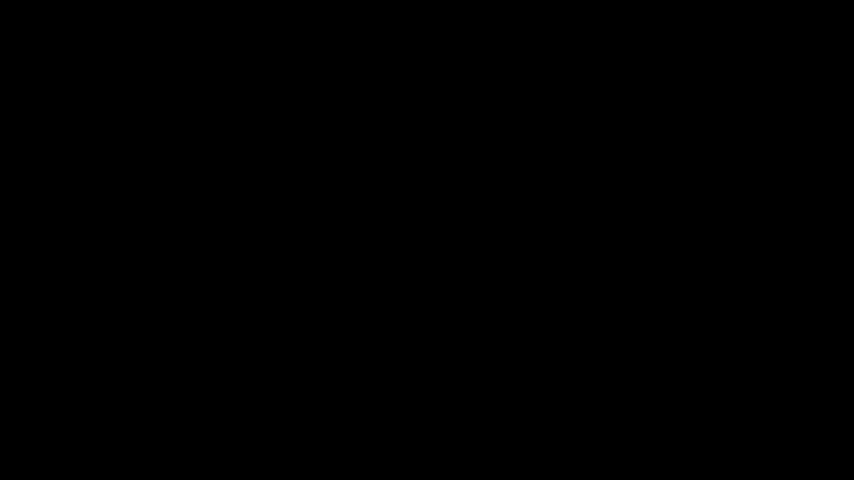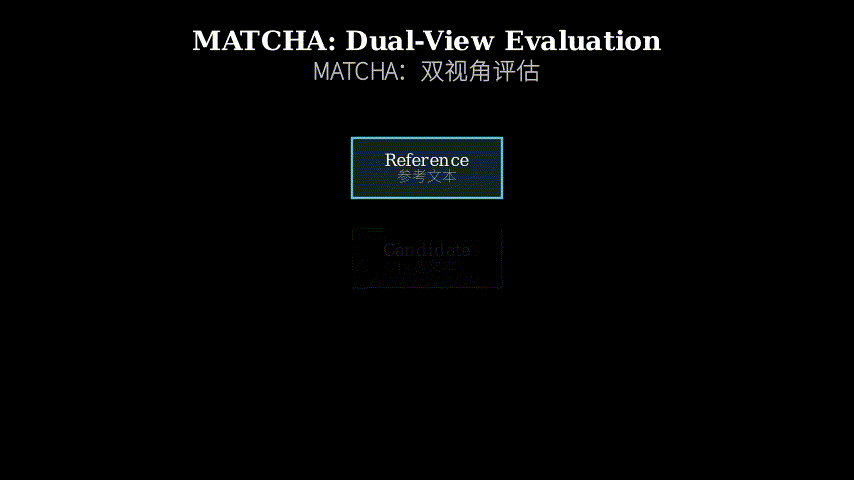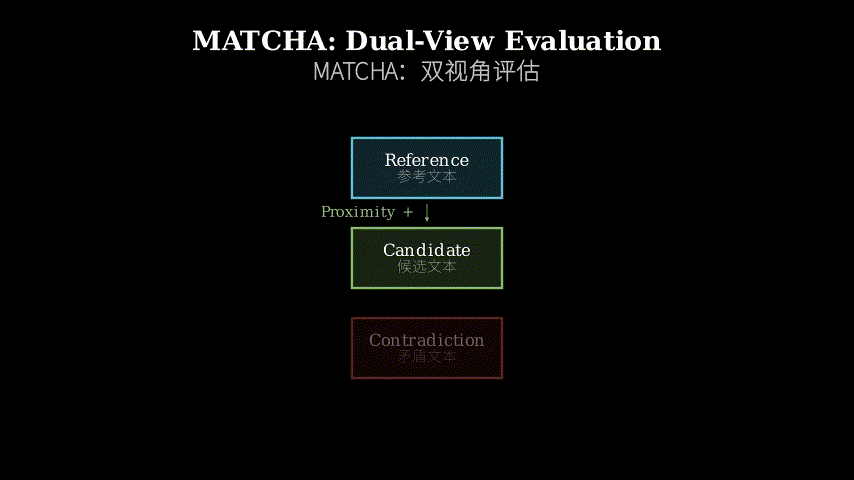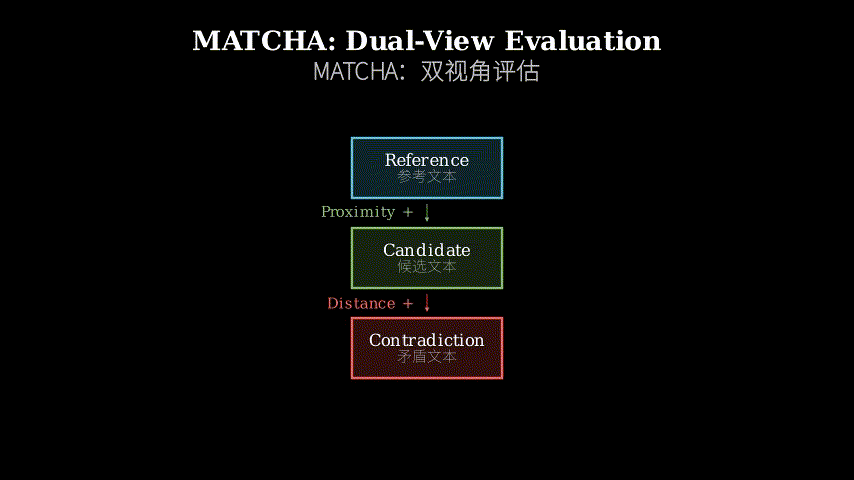
Method: Dual-view scoring (proximity to gold + distance from contradiction)
   |
   v
Evidence: 18-20% improvement over baselines across 8 benchmarks
   |
   v
Conclusion: Adversarial contrast is necessary for correctness evaluation
The Increment
One sentence: Before MATCHA, metrics measured how close a text was to the reference; after MATCHA, metrics measure both closeness to correct answers and distance from plausible contradictions.
Core Mechanism
MATCHA operates on a dual-view principle. For each candidate text, it generates two scores: (1) semantic alignment with the gold reference, and (2) semantic distance from an adversarially constructed counterfactual that contradicts the reference. The final score combines both views—rewarding proximity to truth and penalizing proximity to falsehood.
The adversarial counterfactual is key. Given a reference answer, MATCHA uses an LLM to generate a plausible-sounding statement that directly contradicts it. For example, if the reference is “Paris is the capital of France,” the counterfactual might be “Paris is not the capital of France” or “Berlin is the capital of France.” The candidate text is then embedded and compared to both the reference and the counterfactual in embedding space.
The scoring function is: score = sim(candidate, reference) - λ * sim(candidate, counterfactual), where λ is a penalty weight. This pushes the metric to favor texts that are close to the gold standard and far from its negation. The method works with any embedding model, making it a drop-in enhancement for existing pipelines.
Reference text -----> [LLM] -----> Counterfactual (contradiction)
                                           |
                                           v
Candidate text ---> [Embed] ---> [Similarity] ---> Alignment score
       |                              ^
       |                              |
       +------> [Embed] -------> [Similarity] ---> Contradiction score
                                      |
                                      v
                              Final score = align - λ*contradict
Think of MATCHA as a quality control inspector with two checklists. The first checklist asks: “Does this match the specification?” (alignment with reference). The second asks: “Does this violate any critical constraints?” (proximity to contradiction). A product passes only if it scores well on both. Traditional metrics only use the first checklist, so they approve defective items that superficially resemble the spec but fail on substance. MATCHA’s second checklist catches these failures by explicitly checking what the output should not be.
Key Concepts
-
Adversarial counterfactual: A synthetically generated statement that contradicts the reference while remaining plausible and semantically related. This isn’t random noise—it’s a targeted negation that shares vocabulary and structure with the reference but flips the truth value. For example, if the reference describes a medical treatment as effective, the counterfactual claims it’s ineffective. The counterfactual serves as a semantic anchor point representing “maximally wrong but contextually relevant” text. By measuring distance from this anchor, MATCHA distinguishes between texts that are merely different from the reference versus texts that are actually incorrect.
-
Dual-view scoring: The principle of evaluating a candidate from two complementary perspectives simultaneously. One view measures what the candidate *is (its similarity to the correct answer), while the other measures what it is not (its dissimilarity to the incorrect answer). This is fundamentally different from single-view metrics that only measure one dimension. In practice, dual-view scoring prevents the metric from being fooled by texts that happen to share surface features with the reference but convey opposite meaning. It’s the difference between asking “Is this close to right?” versus asking “Is this close to right AND far from wrong?”
Framework Shift
Before (token overlap / embeddings):     After (MATCHA):

Reference: "Sky is blue"                 Reference: "Sky is blue"
                                                    |
                                                    v
                                         Counterfactual: "Sky is NOT blue"
    |                                               |
    v                                               v
Candidate -----> [Compare] -----> Score   Candidate ---> [Compare both] ---> Score
                                                    |
                                           (close to ref, far from counter)

Single axis: similarity                  Dual axis: similarity + dissimilarity
From measuring proximity to a single target, to measuring position in a semantic space defined by both positive and negative anchors—the core shift is from similarity-based to correctness-based evaluation.
Expert Assessment
Problem choice: This is a real gap with practical consequences. The paper demonstrates that ROUGE and BERTScore assign near-identical scores to contradictory texts, which isn’t a theoretical edge case—it happens routinely in QA and summarization tasks. The problem sits at the intersection of evaluation methodology and semantic understanding, which is central to LLM deployment. However, the framing slightly overstates the novelty; contrastive learning and negative sampling are well-established techniques. The contribution is applying this principle to evaluation metrics, not inventing the principle itself.
Method maturity: The core idea is elegant and well-motivated. Using adversarial counterfactuals to define a semantic boundary is clever. However, the method introduces a dependency on LLM-generated counterfactuals, which adds computational cost and potential failure modes (what if the LLM generates a weak or off-topic contradiction?). The paper doesn’t deeply explore this failure mode or provide ablations on counterfactual quality. The λ penalty weight appears to be manually tuned, which limits generalizability. A simpler approach might be to use existing NLI models to detect contradiction directly, though that would lose the embedding-space geometry that MATCHA exploits.
Experimental integrity: The evaluation is thorough, covering 8 benchmarks across diverse tasks. The 18-20% improvement over baselines is substantial and consistent. However, the paper compares against ROUGE and BERTScore but not against more recent semantic similarity metrics or NLI-based approaches. The human evaluation is limited in scale (not specified clearly in the abstract). The TruthfulQA result is particularly strong because it’s a zero-shot setting, but the paper doesn’t discuss whether MATCHA’s advantage holds when baselines are fine-tuned. The comparison with 23 embedding models is impressive, but it’s unclear whether those models were used with their optimal hyperparameters.
Writing quality: The abstract is clear and the motivation is well-articulated. However, the paper likely buries important details about counterfactual generation quality and failure cases. The method section probably needs more discussion of when the approach breaks down (e.g., when references are ambiguous or when counterfactuals are poorly generated). The related work section could better position this against contrastive learning literature.
Verdict: weak accept — Solid contribution with clear practical value, but the novelty is more in application than in fundamental technique, and some experimental gaps need addressing.
Takeaways
Contrastive anchoring for evaluation: When building any evaluation metric, define not just what “good” looks like, but also what “bad” looks like. Generate negative examples that are plausible but wrong, and measure distance from them. This applies beyond text: in code generation, create buggy variants; in image generation, create semantically incorrect images. The key is making the negative examples *hard—they should be close to correct but crucially flawed.
Adversarial data generation as a feature, not a bug: Instead of treating adversarial examples as attacks to defend against, use them as calibration points. When you generate a counterfactual, you’re explicitly encoding what “wrong” means in your domain. This is more robust than hoping your metric implicitly learns the boundary.
Dual-view pattern: Whenever you’re measuring quality, ask: “Am I only measuring presence of good properties, or am I also measuring absence of bad properties?” Many metrics fail because they’re one-sided. Dual-view scoring (reward + penalty) is a simple architectural pattern that transfers across domains.
论文: 2605.27345 作者: Siran Li, Ece Sena Etoglu, Carsten Eickhoff, Seyed Ali Bahrainian 分类: cs.CL
缺口
现有的大语言模型评估指标在一个基本任务上失败了:区分语义正确的文本和矛盾的文本。
ROUGE 计算词元重叠,所以”天空是蓝色的”和”天空不是蓝色的”如果共享大部分词,得分几乎相同。
BERTScore 使用嵌入向量,但嵌入向量会把语义相关的概念聚在一起——包括反义词。
一个陈述和它的否定往往落在同一个语义邻域,因为它们讨论相同的实体和关系,只是真值翻转了。
该领域有两个阵营:忽略语义的词元重叠指标(BLEU、ROUGE、METEOR),以及捕捉语义接近度但不管逻辑一致性的嵌入指标(BERTScore、MoverScore)。
两者都给矛盾文本打高分。
这不是小的校准问题——这是范畴错误。
指标测量的是相似性,而任务要求的是正确性。
问题:指标给矛盾文本打高分
   |
   v
假设:语义相似 != 语义正确
   |
   v
方法:双视角评分(接近金标准 + 远离矛盾)
   |
   v
证据:在 8 个基准上比基线提升 18-20%
   |
   v
结论:对抗性对比是正确性评估的必要条件
增量
一句话: MATCHA 之前,指标测量文本与参考答案的接近度;MATCHA 之后,指标同时测量与正确答案的接近度和与合理矛盾的距离。
核心机制
MATCHA 基于双视角原则运作。
对每个候选文本,它生成两个分数:(1)与金标准参考的语义对齐度,(2)与对抗性构造的反事实矛盾的语义距离。
最终分数结合两个视角——奖励接近真相,惩罚接近谬误。
对抗性反事实是关键。
给定一个参考答案,MATCHA 使用 LLM 生成一个听起来合理但直接矛盾的陈述。
例如,如果参考是”巴黎是法国的首都”,反事实可能是”巴黎不是法国的首都”或”柏林是法国的首都”。
然后将候选文本嵌入,并在嵌入空间中与参考和反事实进行比较。
评分函数是:score = sim(candidate, reference) - λ * sim(candidate, counterfactual),其中 λ 是惩罚权重。
这推动指标偏好那些接近金标准且远离其否定的文本。
该方法适用于任何嵌入模型,使其成为现有流程的即插即用增强。
参考文本 -----> [LLM] -----> 反事实(矛盾)
                                    |
                                    v
候选文本 ---> [嵌入] ---> [相似度] ---> 对齐分数
    |                         ^
    |                         |
    +------> [嵌入] -------> [相似度] ---> 矛盾分数
                             |
                             v
                   最终分数 = 对齐 - λ*矛盾
把 MATCHA 想象成一个有两份检查清单的质检员。
第一份清单问:“这符合规格吗?“(与参考对齐)。
第二份清单问:“这违反了任何关键约束吗?“(接近矛盾)。
产品只有在两份清单上都得高分才能通过。
传统指标只用第一份清单,所以它们会批准那些表面上像规格但实质上失败的次品。
MATCHA 的第二份清单通过明确检查输出不应该是什么来捕捉这些失败。
关键概念
- 对抗性反事实: 一个合成生成的陈述,它矛盾参考答案但保持合理且语义相关。
这不是随机噪声——它是一个有针对性的否定,与参考共享词汇和结构,但翻转真值。
例如,如果参考描述一种医疗方法有效,反事实声称它无效。
反事实充当语义锚点,代表”最大程度错误但上下文相关”的文本。
通过测量与这个锚点的距离,MATCHA 区分仅仅与参考不同的文本和实际上不正确的文本。
- 双视角评分: 同时从两个互补视角评估候选的原则。
一个视角测量候选是什么(与正确答案的相似度),另一个测量它不是什么(与错误答案的不相似度)。
这与只测量一个维度的单视角指标根本不同。
在实践中,双视角评分防止指标被那些恰好与参考共享表面特征但传达相反含义的文本欺骗。
这是”这接近正确吗?“和”这接近正确且远离错误吗?“之间的区别。
框架转变
之前(词元重叠 / 嵌入):              之后(MATCHA):

参考:"天空是蓝色的"                  参考:"天空是蓝色的"
                                            |
                                            v
                                    反事实:"天空不是蓝色的"
    |                                           |
    v                                           v
候选 -----> [比较] -----> 分数        候选 ---> [比较两者] ---> 分数
                                            |
                                   (接近参考,远离反事实)

单轴:相似度                          双轴:相似度 + 不相似度
从测量到单一目标的接近度,到测量在由正负锚点定义的语义空间中的位置——核心转变是从基于相似度到基于正确性的评估。
专家评审
选题眼光: 这是一个有实际后果的真实缺口。
论文证明 ROUGE 和 BERTScore 给矛盾文本分配几乎相同的分数,这不是理论边缘案例——它在问答和摘要任务中经常发生。
问题位于评估方法论和语义理解的交叉点,这对 LLM 部署至关重要。
然而,框架略微夸大了新颖性;对比学习和负采样是成熟的技术。
贡献在于将这一原则应用于评估指标,而非发明这一原则本身。
方法成熟度: 核心思想优雅且动机充分。
使用对抗性反事实来定义语义边界很巧妙。
然而,该方法引入了对 LLM 生成反事实的依赖,这增加了计算成本和潜在失败模式(如果 LLM 生成弱或离题的矛盾怎么办?)。
论文没有深入探讨这种失败模式或提供关于反事实质量的消融实验。
λ 惩罚权重似乎是手动调整的,这限制了泛化能力。
一个更简单的方法可能是直接使用现有的 NLI 模型检测矛盾,尽管这会失去 MATCHA 利用的嵌入空间几何。
实验诚意: 评估很全面,涵盖 8 个基准的多样化任务。
比基线提升 18-20% 是实质性且一致的。
然而,论文与 ROUGE 和 BERTScore 比较,但没有与更新的语义相似度指标或基于 NLI 的方法比较。
人类评估规模有限(摘要中未明确说明)。
TruthfulQA 结果特别强,因为它是零样本设置,但论文没有讨论当基线微调时 MATCHA 的优势是否保持。
与 23 个嵌入模型的比较令人印象深刻,但不清楚这些模型是否使用了最优超参数。
写作功力: 摘要清晰,动机阐述得很好。
然而,论文可能埋没了关于反事实生成质量和失败案例的重要细节。
方法部分可能需要更多讨论该方法何时失效(例如,当参考模糊或反事实生成不佳时)。
相关工作部分可以更好地将其定位于对比学习文献。
判决: 弱接收 — 扎实的贡献,有明确的实用价值,但新颖性更多在应用而非基础技术,一些实验缺口需要解决。
要点总结
评估的对比锚定: 在构建任何评估指标时,不仅定义”好”是什么样子,还要定义”坏”是什么样子。
生成合理但错误的负例,并测量与它们的距离。
这适用于文本之外:在代码生成中,创建有 bug 的变体;在图像生成中,创建语义不正确的图像。
关键是让负例困难——它们应该接近正确但有关键缺陷。
对抗性数据生成作为特性,而非缺陷: 不要把对抗性样本当作需要防御的攻击,而是把它们当作校准点。
当你生成反事实时,你明确编码了你领域中”错误”的含义。
这比希望你的指标隐式学习边界更稳健。
双视角模式: 每当你测量质量时,问:“我只是在测量好属性的存在,还是也在测量坏属性的缺失?“许多指标失败是因为它们是单向的。
双视角评分(奖励 + 惩罚)是一个简单的架构模式,可以跨领域迁移。