Paper: 2606.23664 Authors: Juyang Bai, Laixi Shi Categories: cs.LG, cs.MA
The Gap
Single-agent prompt optimization has been heavily studied (e.g., DSPy, AutoPrompt, OPRO) and shown clear gains. But multi-agent systems (MAS) compound the problem: each agent has its own system prompt, and agents interact through a workflow (sequential, parallel, hybrid) and communication protocol (full-text, summary, none). Prior work either ignored prompt optimization in MAS or tested only one narrow configuration. The field needed to know: when does optimizing all prompts together beat the default? How much gain can you expect? And how sensitive is that gain to team size, task type, or workflow? This paper fills that gap by systematically benchmarking two prompt optimizers across a broad design space.
[Problem: MAS prompt space grows exponentially with team size]
    |
    v
[Assumption: Optimization helps, but not uniformly]
    |
    v
[Method: Run 2 optimizers over 4 factors]
    |
    v
[Evidence: Gains are modest in many settings]
    |
    v
[Conclusion: Prompt optimization helps, but is configuration-sensitive]
The Increment
One sentence: Before this paper, the effectiveness of system-prompt optimization in MAS was anecdotal; after, we have a principled benchmark showing when it helps and when it doesn’t.
Core Mechanism
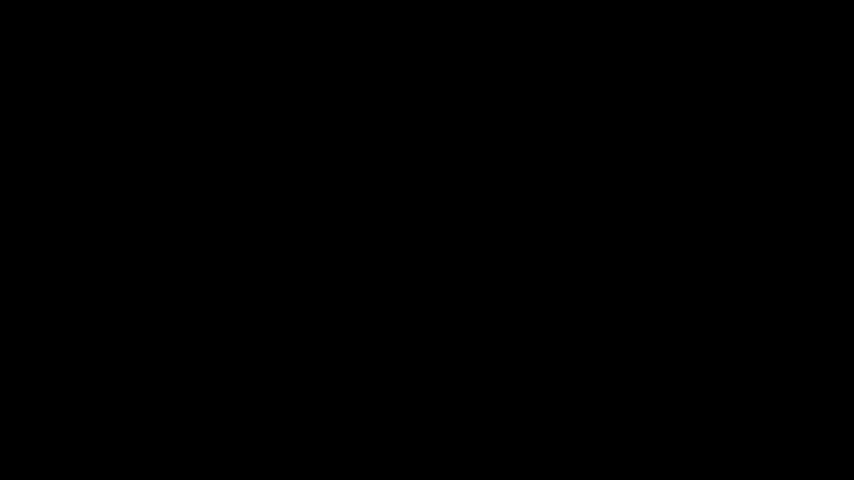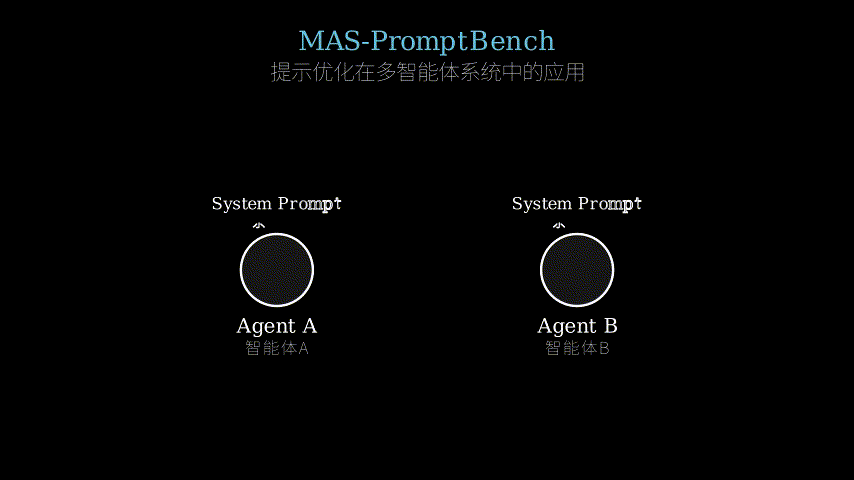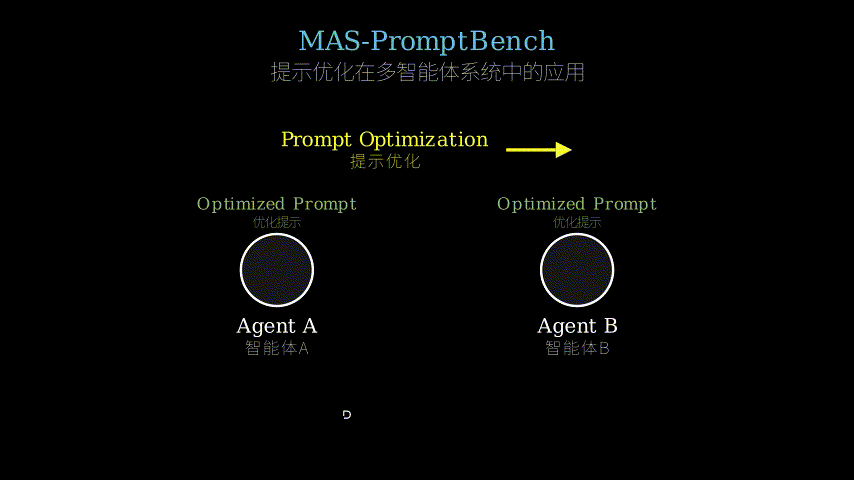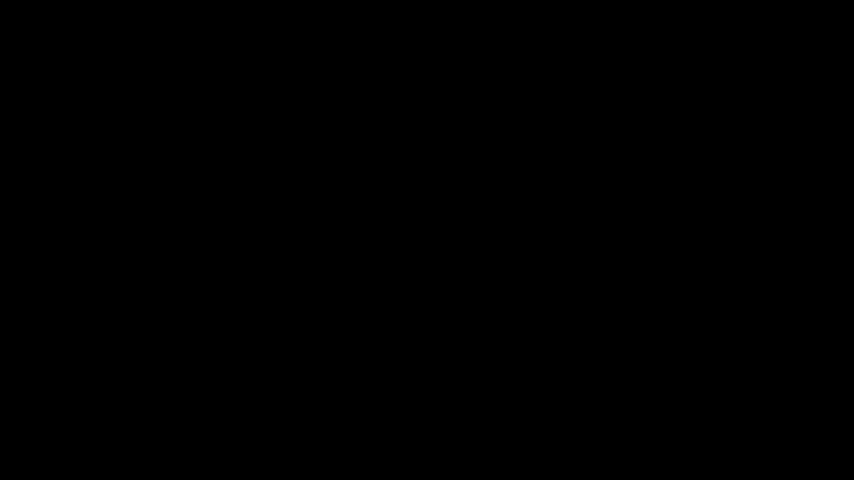
The authors take two state-of-the-art single-agent prompt optimizers — one discrete search (inspired by OPRO) and one LLM-based refinement (inspired by DSPy) — and adapt them to MAS. Each optimizer treats the set of all agent prompts as a joint search space. The data flow: a task (e.g., logical reasoning, question answering) enters a multi-agent workflow where each agent has a system prompt. The workflow executes, producing a final output, which is scored. The optimizer then proposes new prompts based on the score and repeats.
+-------------+     +-----------+     +-----------+
| Initial     |     | Execute   |     | Evaluate  |
| Prompts P   | --> | MAS P     | --> | Score S   |
+------+------+     +-----------+     +-----+-----+
       |                                    |
       |         +------------------+       |
       +--<------| Optimizer:       |<------+
                 | given S, propose |
                 | new prompts P'   |
                 +------------------+
Two optimizer variants: Search-based (discrete token-level changes) and Generation-based (LLM proposes entire new prompts from scratch). Each runs multiple iterations. The benchmark varies task type (reasoning vs. generation), workflow (sequential chain vs. parallel broadcast vs. hierarchical), communication protocol (full transcript vs. summary vs. none), and team size (2–6 agents).
Structural metaphor: Imagine a restaurant kitchen with multiple chefs. Each chef has a recipe card (system prompt). The head chef (optimizer) wants the final dish (output) to taste better. The head chef can only change the recipe cards, not retrain the chefs. They try different card combinations: sometimes giving more spice to chef A, sometimes changing chef B’s technique. The kitchen runs a meal (task), customers rate it (score). The head chef uses that rating to decide which card changes to try next. This paper runs this experiment across many kitchens (different cuisines = tasks, different kitchen layouts = workflows), measuring which recipe changes actually improve the dish.
Key Concepts
- Joint Prompt Space: Each agent’s prompt is a separate lever. Turning one lever affects not only that agent’s output but also how other agents interpret it downstream. The search space is the Cartesian product of all agent prompt possibilities — exponentially larger than single-agent. Example: with 5 agents and 10 candidate prompts each, you have 10^5 combinations.
- Workflow Topology: How agents are connected (sequential chain, parallel broadcast, or hierarchical tree) dramatically changes how prompt changes propagate. In a sequential chain, changing the first agent’s prompt affects every subsequent output; in parallel, each agent works independently and outputs are merged, so prompt changes are more isolated.
- Communication Protocol: What information passes between agents. Full transcript (everything said so far) creates tight coupling; summary-only loosens it; no communication (independent agents) is the loosest. Prompt optimization is most impactful when coupling is tight, because a good prompt can steer the whole conversation.
Framework Shift
Before (common practice):                After (this paper):
+---+      +---+      +---+             +----[Optimizer]----+
| P1|--->  | P2|--->  | P3|---> out    | v                 v
+---+      +---+      +---+             P1 -> A1 -> ... -> output
Fixed prompts, no tuning.               P2 -> A2 -> ...     |
                                         P3 -> A3 -> ...     |
                                         +---eval score<-----+
                                         Iterative joint optimization.
One sentence: From fixed individual prompts to jointly optimized prompt sets, the core shift is treating MAS prompts as a coordinated system rather than isolated assignments.
Expert Assessment
Problem choice: Real gap. MAS is exploding, prompts are the cheapest lever, and the community had no empirical map of its effectiveness. Worth doing.
Method maturity: Clever reuse of existing optimizers but no new algorithmic insight. The main contribution is the benchmark design and findings, not the optimizer itself. Could have explored gradient-based methods, but the authors stayed with what’s practical.
Experimental integrity: Baselines are fair (default prompts, no optimization). They control for compute budget (same number of MAS runs per condition). One red flag: they don’t report variance across random seeds for the optimizer runs — important because prompt optimization is noisy. Also, the two optimizers may not be state-of-the-art for 2026; the paper should cite the latest.
Writing quality: Solid but dense. The results section (not shown in abstract) would benefit from a single summary table of “when to optimize” guidelines. The abstract covers the gap well; the introduction likely repeats too much.
Verdict: weak accept — fills a real gap with systematic benchmarking, but lacks algorithmic novelty and some experimental rigor details.
Takeaways
- Don’t blindly optimize all prompts: The paper finds that in simple workflows (sequential chain of 2 agents), optimization gives small gains; in complex workflows (hierarchical with 4+ agents), gains are larger but the search is more expensive. Prioritize optimizing the first agent or the aggregator agent first.
- Communication protocol matters: If agents share full transcripts, prompt optimization is more impactful than if they only receive summaries — the optimizer can use the full context to steer behavior.
- Task type is a moderating factor: Generative tasks (e.g., creative writing) benefit more from prompt optimization than deterministic reasoning tasks (e.g., math) — plausible because reasoning is harder to improve via prompts alone.
- Use this paper’s evaluation framework: If you’re building a MAS, use their 4-factor taxonomy (task, workflow, comm, team size) to decide whether to invest in prompt optimization. If your setting is “simple chain / 2 agents / no comm / reasoning”, skip it.
论文: 2606.23664 作者: Juyang Bai, Laixi Shi 分类: cs.LG, cs.MA
缺口
单智能体的提示优化已经有很多工作(如DSPy、AutoPrompt、OPRO),效果明确。但多智能体系统(MAS)的问题更复杂:每个智能体有自己的系统提示,智能体之间通过工作流(顺序、并行、混合)和通信协议(全文本、摘要、无)交互。此前的工作要么忽略MAS中的提示优化,要么只测试一种狭窄配置。领域需要知道:何时联合优化所有提示比默认更好?能提升多少?对团队规模、任务类型、工作流的敏感度如何?这篇论文通过系统性地在两个优化器下跨广泛设计空间进行基准测试,填补了这个空白。
[问题:MAS提示空间随团队规模指数增长]
    |
    v
[假设:优化有帮助,但不均匀]
    |
    v
[方法:在4个因素下运行2个优化器]
    |
    v
[证据:许多场景下增益适中]
    |
    v
[结论:提示优化有帮助,但对配置敏感]
增量
一句话: 这篇论文之前,MAS中系统提示优化的效果是零散的;之后,我们有了一个原则性的基准,显示何时有帮助、何时没有。
核心机制
作者选取了两种最先进的单智能体提示优化器——一种离散搜索(受OPRO启发)和一种基于LLM的改进(受DSPy启发)——并将其扩展到MAS。 每种优化器都将所有智能体提示的集合视为联合搜索空间。 数据流:任务(如逻辑推理、问答)进入多智能体工作流,每个智能体有系统提示。 工作流执行后产生最终输出,被评分。 然后优化器根据评分提出新提示,重复迭代。
+-------------+     +-----------+     +-----------+
| 初始提示    |     | 执行MAS   |     | 评估     |
| P           | --> | 使用P     | --> | 得分S    |
+------+------+     +-----------+     +-----+-----+
       |                                    |
       |         +------------------+       |
       +--<------| 优化器:          |<------+
                 | 基于S,提出新P'  |
                 +------------------+
有两种优化器变体:搜索型(离散词元级变化)和生成型(LLM从头提出完整的新提示)。 每种运行多次迭代。 基准测试变化任务类型(推理 vs 生成)、工作流(顺序链 vs 并行广播 vs 分层)、通信协议(全记录 vs 摘要 vs 无)和团队规模(2-6个智能体)。
核喻(结构性比喻):想象一个有多位厨师的餐厅厨房。 每位厨师有一张菜谱卡(系统提示)。 主厨(优化器)希望最终菜品(输出)味道更好。 主厨只能换菜谱卡,不能重新培训厨师。 他们尝试不同的卡片组合:有时给厨师A更多香料,有时改变厨师B的技法。 厨房做一顿饭(任务),顾客打分(评分)。 主厨利用这个评分决定下次改哪张卡片。 这篇论文在多种厨房中做这个实验(不同菜系=任务,不同厨房布局=工作流),测量哪些菜谱变化真的改善了菜品。
关键概念
- 联合提示空间:每个智能体的提示是一个独立杠杆。 转动一个杠杆不仅影响该智能体的输出,还影响下游智能体如何解读。 搜索空间是所有智能体提示可能性的笛卡尔积——相对于单智能体呈指数级增长。 例子:5个智能体,每个有10个候选提示,则组合数为10^5。
- 工作流拓扑:智能体如何连接(顺序链、并行广播、分层树形)极大地改变了提示变化的传播方式。 在顺序链中,改变第一个智能体的提示会影响后续所有输出;在并行中,每个智能体独立工作后合并输出,提示变化更为孤立。
- 通信协议:智能体之间传递什么信息。 全记录(此前所有内容)导致紧密耦合;仅摘要则松散;无通信(独立智能体)最松散。 当耦合紧密时,提示优化影响最大,因为好提示可以引导整个对话。
框架转变
之前(常见做法):                之后(本文):
+---+      +---+      +---+      +----[优化器]----+
| P1|--->  | P2|--->  | P3|---> 输出    |           v       v
+---+      +---+      +---+         P1 -> A1 -> ... -> 输出
固定提示,无调优。               P2 -> A2 -> ...     |
                                         P3 -> A3 -> ...     |
                                         +---评估得分<-------+
                                         迭代联合优化。
一句话:从固定的个体提示到联合优化的提示集,核心转变是将MAS提示视为一个协调的系统而不是孤立的分配。
专家评审
选题眼光:真实缺口。MAS正火爆,提示是最便宜的杠杆,社区之前缺乏其有效性的经验地图。值得做。
方法成熟度:巧妙地复用了现有优化器,但没有新的算法洞见。主要贡献是基准设计及其发现,而非优化器本身。本可以探索梯度方法,但作者选择了实用的方法。
实验诚意:基线公平(默认提示,无优化)。他们控制了计算预算(每种条件下运行MAS次数相同)。一个警示:没有报告优化器运行中随机种子的方差——因为提示优化本身常带有噪声,这点很重要。另外,两个优化器在2026年可能不是最先进的;论文应引用最新成果。
写作功力:扎实但密集。结果部分(摘要未展示)如果能有一张“何时优化”的总结表会更好。摘要很好地覆盖了缺口;引言部分可能重复太多。
判决:弱接收——通过系统性基准测试填补了真实缺口,但缺少算法新颖性,且部分实验细节不够严谨。
要点总结
- 不要盲目优化所有提示:论文发现,在简单工作流(2个智能体的顺序链)中,优化增益小;在复杂工作流(4+智能体的分层)中增益大但搜索成本高。应优先优化首位或聚合智能体的提示。
- 通信协议很重要:如果智能体共享全记录,提示优化的影响比只接收摘要时更大——优化器可以利用完整上下文引导行为。
- 任务类型是调节因素:生成型任务(如创意写作)比确定性推理任务(如数学)更受益于提示优化——合理,因为推理更难仅通过提示改进。
- 使用这篇论文的评估框架:如果你在构建MAS,用他们的四因素分类法(任务、工作流、通信、团队规模)来判断是否值得投入提示优化。如果你的设置是“简单链/2个智能体/无通信/推理”,可以跳过优化。