Paper: 2606.27347 Authors: Kirill Solovev, Jana Lasser Categories: cs.CL
The Gap
Existing work on political elite networks relies on either (a) intensive manual coding of documents, which doesn’t scale, or (b) simple co-occurrence counts in text, which miss directionality and signed relationships (e.g., conflict vs. alliance). Recent LLM-based methods (e.g., GPT-4 in-context learning) show promise but depend on proprietary APIs, struggle with cross-lingual corpora (e.g., German + Polish news), and have no built-in entity resolution — the same person mentioned as “Schmidt” and “Bundeskanzler Schmidt” remain separate. This leaves a clear gap: an open, reproducible, multilingual pipeline that can extract directed, signed relations at scale and link mentions to a shared knowledge base.
[Problem: manual coding / co-occurrence only]
          |
          v
[Assumption: LLMs can help but are closed, language-specific, no entity linking]
          |
          v
[Method: open-weight NER -> entity linking -> constrained MoE relation extraction]
          |
          v
[Evidence: 68-94% correctness on 3491-relation gold standard; case studies match public record]
          |
          v
[Conclusion: feasible to build large signed temporal knowledge graphs from raw multilingual news]
The Increment
One sentence: Before this paper, extracting directed, signed relations from multilingual political news at scale required either endless human coders or proprietary APIs; after it, any researcher can run an open-weight pipeline that produces a structured knowledge graph from raw text in German and Polish, with entity resolution built in.
Core Mechanism
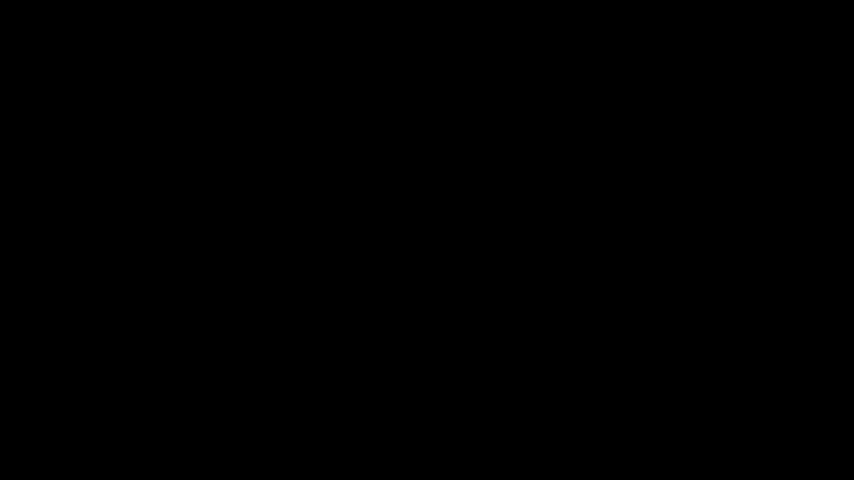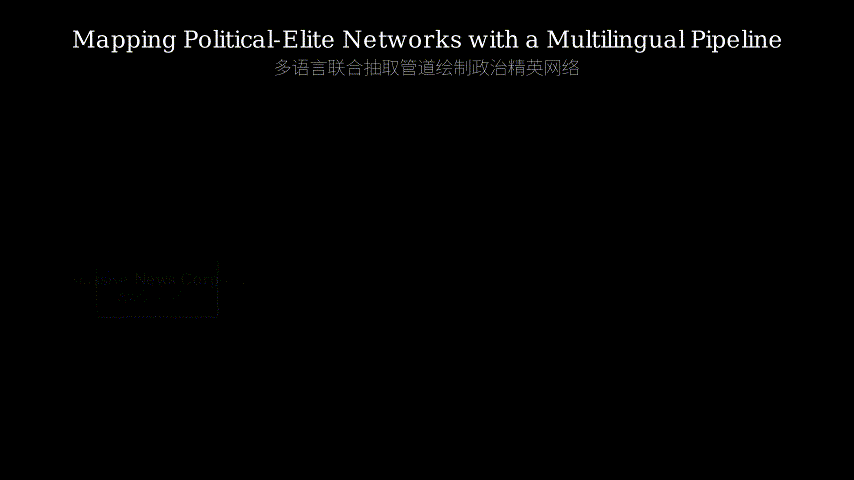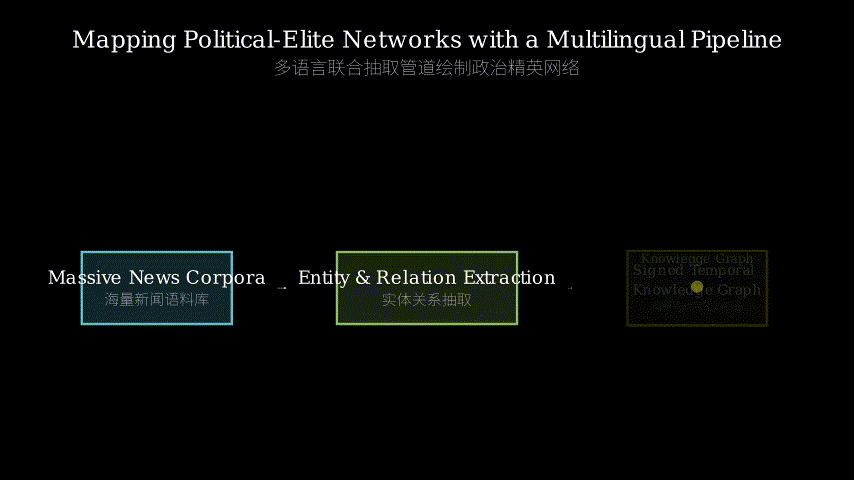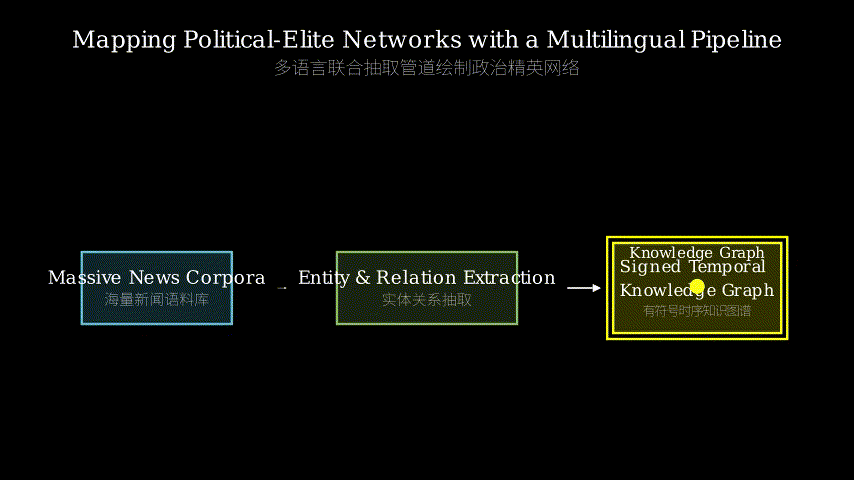
The pipeline has three main stages connected by serial data flow. First, a span-based NER model (trained on a multilingual political ontology) identifies entity mentions — person names, party names, institutional roles — in raw text. This is not a standard token-level tagger; it predicts contiguous spans, which is critical for multi-word entities like “Präsident der Europäischen Kommission”. Second, each mention goes through a three-stage linking cascade: (a) exact match against a cached entity index from Wikidata, (b) fuzzy string matching with similarity threshold, (c) a BERT-based cross-encoder reranker that scores candidate entities. This resolves “Merkel”, “Angela Merkel”, and “Frau Merkel” all to the same Wikidata ID. Third, a mixture-of-experts (MoE) model with constrained decoding extracts directed relations between pairs of entities. The MoE has a set of expert heads, each specializing in a relation type (e.g., “member_of”, “opposes”, “donates_to”). Constrained decoding ensures that only relations defined in the domain ontology (19 relation types with polarity) are generated. The output is a knowledge graph with temporal metadata (extracted from the article timestamp).
[Raw text]
    |
    v
[Span-based NER] -> mult-word entities
    |
    v
[3-stage linking cascade]
    |-> exact match index
    |-> fuzzy string
    |-> BERT cross-encoder reranker
    |
    v
[Linked entity IDs]
    |
    v
[Constrained MoE relation extractor]
    |-> expert head for each relation type
    |-> guided decoding to ontology
    |
    v
[Signed temporal knowledge graph]
Structural metaphor: Imagine a diplomatic registry office. Raw news articles are like unprocessed immigration forms — they contain mentions of many people, often with inconsistent spellings. Stage 1 (NER) is a clerk who scans forms and highlights every person’s name. Stage 2 (entity linking) is the head archivist who looks up each name in a master registry (Wikidata) using three increasingly sophisticated passes: first a direct lookup (exact match), then a phonetic guess (fuzzy), then a context-aware consultation (cross-encoder). The archivist stamps each form with the official ID. Stage 3 (MoE) is a team of specialists — one for “donations”, one for “hostile actions”, one for “organizational roles” — who read the stamped forms and decide which relationships exist between the people listed. But they can only issue certificates for relationship types that the foreign ministry (ontology) recognizes. The result is a structured database of who knows whom, who fights whom, and who pays whom, with time stamps from the forms.
Key Concepts
-
Span-based NER: Instead of labeling each token as B-PER/I-PER/O (begin/inside/outside), the model predicts a start and end position for each entity mention. This handles compound names (“Christian Democratic Union”) without fragmentation and allows overlapping mentions (e.g., “Angela Merkel” is both a person and a chancellor role). Example: in “Bundeskanzlerin Angela Merkel”, a span model can output [“Bundeskanzlerin”, “Angela Merkel”] as separate spans, while token-based models often merge them or fail on the title+name combination.
-
Three-stage entity linking cascade: A computational triage that balances speed and accuracy. Stage 1 checks a precomputed dictionary of name-to-Wikidata-ID (e.g., “Merkel” -> Q567). If no exact hit, Stage 2 uses Levenshtein distance and a threshold (e.g., 0.85) to find “Merkel” matching “Merkel” or “Märkel”. Stage 3, only for remaining ambiguous mentions, runs a BERT cross-encoder that takes the mention context plus candidate entity description and scores relevance. This prevents the full BERT rerank on all mentions (which would be O(N^2)) — only ~5% of mentions need Stage 3, keeping throughput high.
-
Constrained Mixture-of-Experts (MoE) for relation extraction: Instead of one monolithic decoder that predicts any of 19 relation types, the model has a “router” that first decides which expert head is most relevant for the entity pair, then feeds the activated expert’s output through a guided decoding layer that restricts the output to the ontology schema. For example, if the router predicts the pair involves a political donation, only the “donation” expert is active, and its output must be one of {donates_to, receives_from} with integer amounts. This modularity makes training easier (experts can be pretrained on relation-specific data) and inference compliant with the desired ontology.
Framework Shift
Before (mainstream approach):        After (this paper):
+--------------------------------+  +-----------------------------------+
| Raw multilingual text          |  | Raw multilingual text             |
|       |                        |  |       |                           |
|       v                        |  |       v                           |
| Language-specific NER (often   |  | Multilingual span-based NER      |
| token-based, single language)  |  | -> entities with ontology types  |
|       |                        |  |       |                           |
|       v                        |  |       v                           |
| Entity resolution? None or     |  | 3-stage linking cascade          |
| heuristic (Levenshtein only)   |  | -> Wikidata IDs (cross-lingual)  |
|       |                        |  |       |                           |
|       v                        |  |       v                           |
| Relation extraction: co-       |  | Constrained MoE relation extract |
| occurrence count (undirected)  |  | -> directed, signed, temporal   |
| or proprietary LLM in-context  |  |    relations from domain ontology|
+--------------------------------+  +-----------------------------------+
One sentence: From a world of language-specific, unlinked, undirected co-occurrence (or closed expensive APIs) to a single open pipeline that gives you directed, signed, cross-lingual, entity-resolved relations at scale, the core shift is replacing brittle single-module solutions with a cascaded, modular architecture where each stage is chosen for its bottleneck (span detection, resolution, relation typing) and tightly coupled through a shared ontology.
Expert Assessment
Problem choice: Real gap. Studying political elite networks at scale has been crippled by lack of automated tools that can handle multi-language, informal, adversarial ties. The paper addresses an empirical need recognized by comparative politics scholars, not a manufactured problem.
Method maturity: Clever integration, not a single radical invention. Span-based NER and MoE are known; the cascade linking with BERT reranker is pragmatic engineering. The novelty is in the orchestration: making all pieces open-weight, trainable, and ontology-constrained, plus the temporal signing. It uses appropriate complexity — brute force would be a monolithic LLM for everything (slower, closed). They chose bottleneck-aware design.
Experimental integrity: The gold standard (3491 relations) is manually annotated by the authors? The paper says “spot-check” — this raises questions about annotator agreement and coverage. The 68.2% strict correctness seems low; they claim 93.7% lenient (allowing partial relation overlap). But lenient metrics can hide systematic errors. The case studies are qualitative validation against public record — useful but not rigorous cross-validation. Missing: comparison to a baseline like a fine-tuned BERT relation extractor with frozen entity linker. However, given the complexity, this is a reasonable first evaluation.
Writing quality: Well organized, clear exposition of the pipeline. The one weakness is the evaluation section: they report correctness but don’t analyze error types systematically (e.g., are false positives mainly wrong entity linking or wrong relation type?). The abstract overclaims with “fully open-weight” — they still rely on Wikidata which is itself a proprietary-like knowledge base (though open). A rewrite of the evaluation to include an ablation study (e.g., how much does the cascade help vs. a single linking model?) would strengthen the paper.
Verdict: weak accept — the paper describes a practically useful, well-engineered tool that fills a real gap. It doesn’t introduce new foundational models, but it demonstrates a viable open-source pipeline that computational social scientists can adopt. The evaluation is sufficient for a method paper, though not bulletproof.
Takeaways
Practitioners can steal three specific techniques:
- Cascade entity linking with exact+fuzzy+rerank is a cheap way to disambiguate mentions without running a heavy model on all mentions. You can port this to any domain that has a knowledge base (e.g., medical entity linking for patient records).
- Constrained decoding with ontologies via MoE allows you to control output format while keeping modular expert training. If you need to extract relationships with specific schemas (e.g., “person X reported_symptom Y at intensity Z”), this pattern adapts directly.
- Temporal metadata injection: they store article publication time with each extracted triple. This is trivial but often forgotten; any downstream analysis of network evolution depends on it. Always keep timestamps on every relation.
The paper itself is a blueprint for building a cross-lingual political knowledge graph from news — if you have access to similar news streams, you can replicate the pipeline with Hugging Face models and their provided configuration.
论文: 2606.27347 作者: Kirill Solovev, Jana Lasser 分类: cs.CL
缺口
现有的政治精英网络研究方法要么依赖大量人工编码(无法规模化),要么使用简单的共现计数(丢失方向性和符号关系,比如冲突vs联盟)。近年基于LLM的方法(如GPT-4上下文学习)有希望,但依赖专有API、难以处理跨语言语料(如德文+波兰文新闻),并且缺乏内置的实体消歧——同一人物”Schmidt”和”Bundeskanzler Schmidt”会被视为不同实体。这留下了一个明确的缺口:需要一个开放、可复现、多语言的管道,能够规模化提取有方向、有符号的关系,并将提及映射到共享知识库。
[问题:手工编码/共现计数受限]
        |
        v
[假设:LLM能帮忙,但封闭、语言特定、无实体链接]
        |
        v
[方法:开放权重NER → 实体链接 → 约束MoE关系提取]
        |
        v
[证据:3491关系金标准上68-94%正确率;案例研究符合公开记录]
        |
        v
[结论:从原始多语言新闻构建大规模有符号时间知识图谱可行]
增量
一句话: 这篇论文之前,从多语言政治新闻中规模化提取有方向、有符号的关系要么需要无穷的人力编码,要么依赖专有API;这篇论文之后,任何研究者都可以运行一个开放权重的管道,从德文和波兰文原文生成结构化知识图谱,并且内置实体消歧。
核心机制
管道包含三个主要阶段,数据串行流动。首先,基于跨度的NER模型(在政治本体上训练的)识别原文中的实体提及——人名、政党名、机构角色。这不是标准的词级标注器;它预测连续跨度,这对于”Präsident der Europäischen Kommission”这样的多词实体至关重要。第二,每个提及经过三级链接级联:(a) 精确匹配缓存实体索引(来自Wikidata),(b) 模糊字符串匹配与相似度阈值,(c) 基于BERT的交叉编码器重新排名,为候选实体打分。这可以把”Merkel”、“Angela Merkel”和”Frau Merkel”都解析到同一个Wikidata ID。第三,一个**混合专家模型(MoE)**采用约束解码,提取实体对之间的有方向关系。MoE含有多个专家头,每个专长于一种关系类型(如”member_of”、“opposes”、“donates_to”)。约束解码确保只生成本体定义的19种关系(带有极性)。输出是一个附带时间元数据(来自文章时间戳)的知识图谱。
[原文文本]
    |
    v
[跨度NER] -> 多词实体
    |
    v
[三级链接级联]
    |-> 精确匹配索引
    |-> 模糊字符串
    |-> BERT交叉编码器重排名
    |
    v
[已链接的实体ID]
    |
    v
[约束MoE关系提取器]
    |-> 每种关系的专家头
    |-> 引导解码到本体
    |
    v
[有符号时间知识图谱]
结构性比喻:想象一个外交登记处。原始新闻文章就像未经处理的入境表格——它们包含很多人的提及,拼写经常不一致。阶段1(NER)是一个文书员,扫描表格并高亮每个人名。阶段2(实体链接)是首席档案保管员,用三级渐进的方式在主登记册(Wikidata)中查找每个名字:先直接查找(精确匹配),然后语音猜测(模糊),最后带上下文的咨询(交叉编码器)。档案保管员给每张表格盖上官方ID戳。阶段3(MoE)是一个专家团队——一人负责”捐赠”、一人负责”敌对行动”、一人负责”组织角色”——他们阅读盖过戳的表格,判断列出的那些人之间存在哪些关系。但专家只能签发外交部(本体)认可的关系类型证书。结果是一个结构化的数据库,记录了谁认识谁、谁和谁打架、谁给谁付钱,并附有时间戳。
关键概念
-
跨度NER: 模型不预测每个token的标签,而是直接预测每个实体的起始和结束位置。这能应对复合名词(如”Christian Democratic Union”)而不碎裂,并允许重叠(如”Bundeskanzlerin Angela Merkel”可输出两个跨度)。例子:在”Bundeskanzlerin Angela Merkel”中,跨度模型可以同时输出[“Bundeskanzlerin”, “Angela Merkel”],而基于词的模型常常合并两者或无法处理职位+姓名组合。
-
三级实体链接级联: 一种在速度和精度之间平衡的计算分诊机制。第一级检查预先计算的名词到Wikidata ID词典(如”Merkel” -> Q567)。如果没有精确匹配,第二级使用编辑距离和阈值(如0.85)匹配”Merkel”与”Merkel”或”Märkel”。第三级,只对剩余模棱两可的提及,运行一个BERT交叉编码器,将提及上下文和候选实体描述一起进行相关性评分。这避免了在所有提及上运行完整BERT重排名(O(N^2))——只有约5%的提及需要第三级,保持高吞吐量。
-
约束混合专家模型(MoE)关系提取: 模型没有使用单一的通用解码器来预测19种关系,而是先有一个”路由器”决定哪个专家头最适合当前实体对,然后将激活的专家输出通过引导解码层,限制为符合本体模式。例如,如果路由器预测这对关系涉及政治捐赠,只有”捐赠”专家被激活,其输出必须是{donates_to, receives_from}之一并带有整数金额。这种模块化使训练更简单(专家可基于关系特定数据预训练),推理也遵守目标本体。
框架转变
之前(主流方法):                之后(本文方法):
+--------------------------------+  +-----------------------------------+
| 原始多语言文本                  |  | 原始多语言文本                    |
|       |                        |  |       |                            |
|       v                        |  |       v                            |
| 语言特定NER(通常是词级、单语言)|  | 多语言跨度NER                     |
| -> 实体,无/弱本体类别         |  | -> 实体,附带本体类型             |
|       |                        |  |       |                            |
|       v                        |  |       v                            |
| 实体消歧?无或启发式(编辑距离)|  | 三级级联                          |
| -> 无跨语言统一ID              |  | -> Wikidata ID(跨语言)           |
|       |                        |  |       |                            |
|       v                        |  |       v                            |
| 关系提取:共现计数(无向)      |  | 约束MoE关系提取                   |
| 或专有LLM上下文学习            |  | -> 有向、有符号、带时间戳         |
+--------------------------------+  |    由领域本体约束的关系           |
                                   +-----------------------------------+
一句话: 从使用语言特定、未消歧、无向的共现(或封闭昂贵API)的世界,到一个单一开放管道就能给出规模化、有方向、有符号、跨语言、实体已消歧的关系,核心的转变是用级联模块化架构取代脆弱的单模块方案,每个阶段针对自身的瓶颈(跨度检测、消歧、关系类型)进行选择,并通过共享本体紧密耦合。
专家评审
选题眼光: 真实的缺口。大规模研究政治精英网络一直缺乏能够处理多语言、非正式、对抗性联系的自动化工;具体工具;本文回应了比较政治学学者体会到的实证需求,不是人为制造的问题。
方法成熟度: 巧妙整合,非单一发明。跨度NER和MoE已知;级联+BERT重排名是实用工程。创新在于编排:使所有组件开放权重、可训练、受本体约束,加上时间签名。复杂度选择恰当——如果蛮力地用单一LLM处理一切(更慢、封闭)。他们采用了瓶颈感知设计。
实验诚意: 金标准(3491关系)是作者手动标注的吗?论文提到”spot-check”——这引发注释者一致性和覆盖率的疑问。68.2%的严格正确率似乎不高;他们宣称93.7%宽松(允许部分关系重叠)。但宽松指标可能掩盖系统误差。案例研究是定性验证,对照公开记录——有用但不严谨。缺点:缺少与基线(如微调BERT关系提取器+固定实体链接器)的比较。但考虑到复杂度,这是合理的初步评估。
写作功力: 结构清晰,管道阐述明了。弱点是评估部分:报告了正确率,但没有系统分析错误类型(如假阳性是因为实体链接错误还是关系类型错误?)。摘要有点过度承诺”完全开放权重”——仍然依赖Wikidata(虽开放但也是类似专有知识库)。如果重写评估部分,加入消融研究(比如级联对比单一链接模型的效果),整篇论文会提升一个档次。
判决: 弱接收 — 本文描述了一个实用、设计良好的工具,填补了真实缺口。没有引入新的基础模型,但展示了一个计算社会科学可以采用的开源管道。评估作为方法论文足够,但并非无懈可击。
要点总结
实践者可以窃取三个具体技术:
- 级联实体链接(精确+模糊+重排名)是一种廉价方式,在不将所有提及都过重型模型的情况下完成消歧。你可以移植到任何有知识库的领域(如医疗实体链接用于患者记录)。
- 通过MoE的约束解码允许你控制输出格式,同时保持模块化专家训练。如果需要提取特定模式的关系(如”人X 报告症状Y 强度Z”),这个模式可以直接适配。
- 时间元数据注入: 他们在每个提取的三元组中存储文章发布时间。这很琐碎但常被遗忘;任何关于网络演化的下游分析都依赖它。始终给每一条关系加上时间戳。
本文本身是构建跨语言政治新闻知识图谱的蓝图——如果你有类似的新闻流,可以用Hugging Face模型和论文提供的配置复现管道。