Paper: 2603.16844 Authors: Kerui Ren, Guanghao Li, Changjian Jiang, Yingxiang Xu, Tao Lu, Linning Xu, Junting Dong, Jiangmiao Pang, Mulin Yu, Bo Dai Categories: cs.CV
The Gap
Monocular SLAM has two jobs: figure out where the camera is, and build a map of the scene — all from a single moving camera, in real time, without any depth sensor. Classical systems like ORB-SLAM3 do this with hand-crafted sparse features, which are fast but brittle in textureless or dynamic scenes. The newer wave couples 3D foundation models (think VGGT, DUSt3R, MASt3R) with SLAM backends, hoping to get the generalization of large pretrained models for free.
The problem: these foundation models are trained to produce good-enough poses in a feed-forward pass. Their internal pixel correspondences are coarse — they’re optimized for “roughly correct” geometry, not for the sub-pixel precision that a geometric optimizer like bundle adjustment actually needs. When you plug them into a SLAM loop and try to refine poses, the noisy correspondences act like a bad GPS signal: the optimizer spins its wheels or drifts.
Prior work either (a) accepts the coarse correspondences and lives with the drift, or (b) bolts on a separate matching network as an afterthought, losing the joint representation. M^3 asks: what if we train a dedicated matching head on top of the foundation model’s features, so the correspondences are dense, precise, and geometrically consistent with the model’s own world representation?
Problem: monocular video -> need precise pose + dense map online
         |
         v
Prior art: feed-forward foundation models (VGGT, DUSt3R)
         |
         + coarse pixel correspondences
         |
         v
Bottleneck: geometric optimizer needs sub-pixel precision
         |
         v
Assumption: foundation model features already encode geometry;
            a lightweight matching head can refine them
         |
         v
Method: M^3 = foundation model + matching head
              + dynamic suppression + intrinsic alignment
         |
         v
Evidence: -64.3% ATE RMSE vs VGGT-SLAM 2.0 on ScanNet++
          +2.11 dB PSNR vs ARTDECO on ScanNet++
         |
         v
Conclusion: dense matching head is the missing link between
            foundation model generalization and SLAM precision
The Increment
One sentence: Before this paper, plugging a multi-view foundation model into SLAM meant accepting coarse correspondences and hoping the backend could compensate; after this paper, you can get dense, precise correspondences from the same model by training a matching head on its features.
Core Mechanism
M^3 has three moving parts that stack on top of each other.
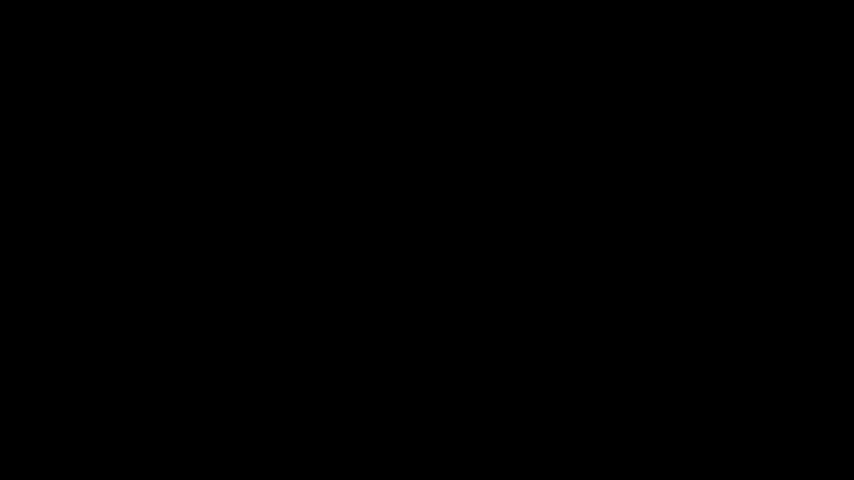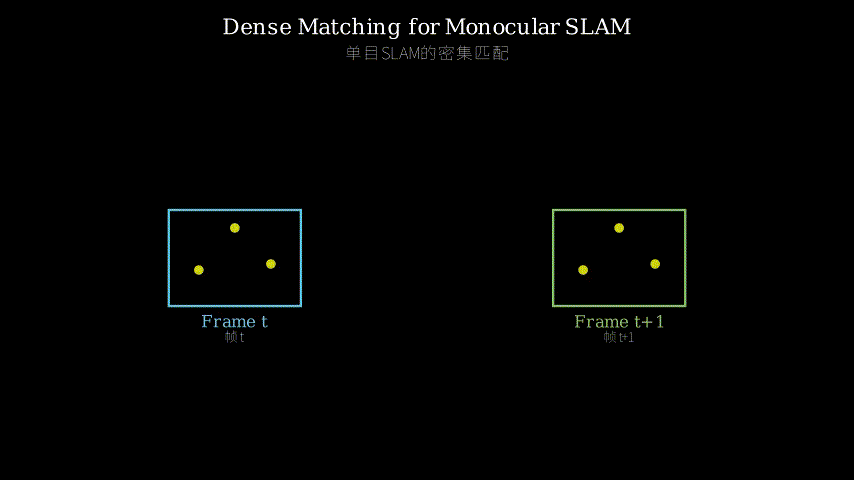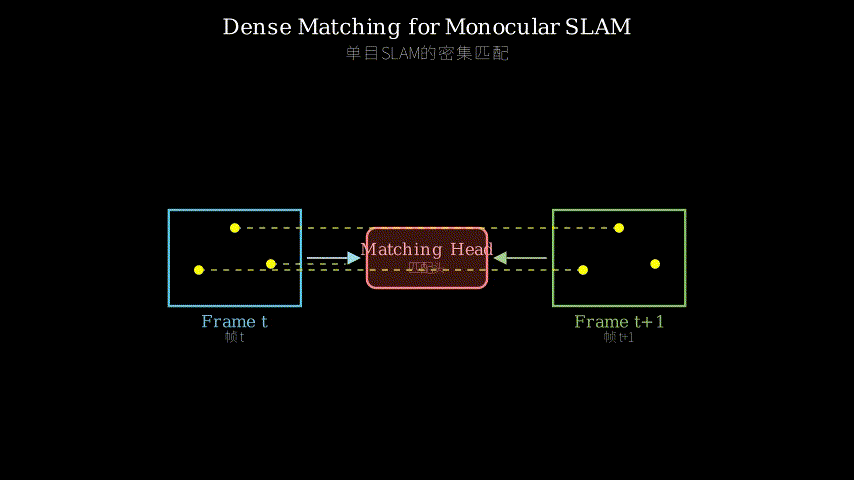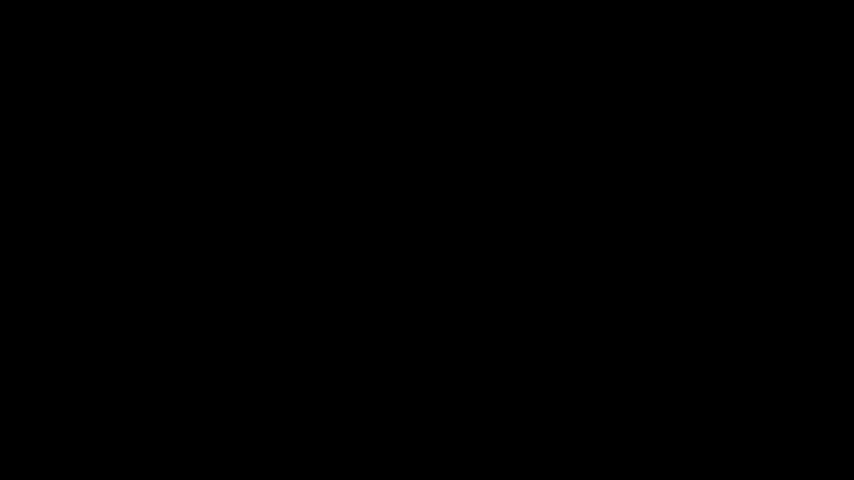
The base is a multi-view foundation model — specifically VGGT or similar — which takes a set of frames and produces per-pixel feature maps encoding 3D geometry. These features are rich but their implied correspondences are only accurate to maybe 5-10 pixels. The first addition is a matching head: a lightweight network that takes the foundation model’s feature maps for two frames and produces a dense flow field — for every pixel in frame A, where does it land in frame B? This head is trained with a correspondence loss that pushes it toward sub-pixel accuracy. Crucially, it shares the backbone with the foundation model, so it’s not a separate system bolted on; it reads from the same geometric representation.
The second addition handles a practical failure mode: dynamic objects. If a person walks through the scene, their pixels produce correspondences that are geometrically correct for the person but wrong for the static background the SLAM system is trying to map. M^3 adds a dynamic area suppression module that detects and masks out regions with inconsistent motion before feeding correspondences into the optimizer. The third piece is cross-inference intrinsic alignment: when the foundation model processes overlapping windows of frames, the inferred camera intrinsics can drift slightly between windows. M^3 aligns these estimates across windows to keep the geometry globally consistent.
The SLAM backend is Gaussian Splatting — the scene is represented as a cloud of 3D Gaussians, each with position, color, and opacity. Tracking uses the dense correspondences from the matching head to estimate camera pose; mapping refines the Gaussians by rendering and comparing to the input frame. The whole loop runs online as new frames arrive.
Input frames (monocular video stream)
         |
         v
+---------------------------+
| Multi-view Foundation     |
| Model (e.g. VGGT)         |
| -> per-pixel feature maps |
+---------------------------+
         |
    +----+----+
    |         |
    v         v
+--------+  +------------------+
| Pose   |  | Matching Head    |
| (coarse|  | dense flow field |
| prior) |  | (sub-pixel)      |
+--------+  +------------------+
    |              |
    |    +---------+
    |    | Dynamic Area
    |    | Suppression
    |    | (mask movers)
    |    +---------+
    |              |
    v              v
+------------------------------+
| Geometric Optimizer          |
| (pose refinement via         |
|  dense correspondences)      |
+------------------------------+
         |
         v
+------------------------------+
| Gaussian Splatting Backend   |
| tracking + mapping           |
| -> 3D scene + camera poses   |
+------------------------------+
         |
         v
Cross-inference Intrinsic Alignment
(stitch windows, fix focal drift)
Think of it like a cartographer with a magnifying glass working alongside a surveyor. The foundation model is the cartographer: it looks at a handful of photos and sketches a rough map of the terrain — good enough to navigate, but the lines are a bit wobbly. The matching head is the magnifying glass the cartographer picks up to trace exactly where a river bends between two photos — now the lines are precise. The dynamic suppression is the cartographer’s rule to ignore anything that moved between shots (a car, a person) because those features will mislead the map. The intrinsic alignment is the step where the cartographer reconciles two overlapping map sheets drawn at slightly different scales. The SLAM backend is the surveyor who takes all this precise information and builds the final 3D model of the terrain, updating it as new photos arrive.
Without the magnifying glass (matching head), the surveyor is working from wobbly lines and the final model drifts. That’s the whole paper in one image.
Key Concepts
- Dense correspondences vs. sparse keypoints: Classical SLAM tracks a few hundred “interesting” pixels (corners, blobs) between frames. Dense correspondences track *every pixel — or at least a dense grid. More data means more constraints for the optimizer, which means better pose estimates, especially in low-texture regions where sparse methods fail. The cost is compute: you’re moving from hundreds of 2D points