Paper: 2604.13036 Authors: Tianchang Shen, Sherwin Bahmani, Kai He, Sangeetha Grama Srinivasan, Tianshi Cao, Jiawei Ren, Ruilong Li, Zian Wang, Nicholas Sharp, Zan Gojcic Categories: cs.CV
The Gap
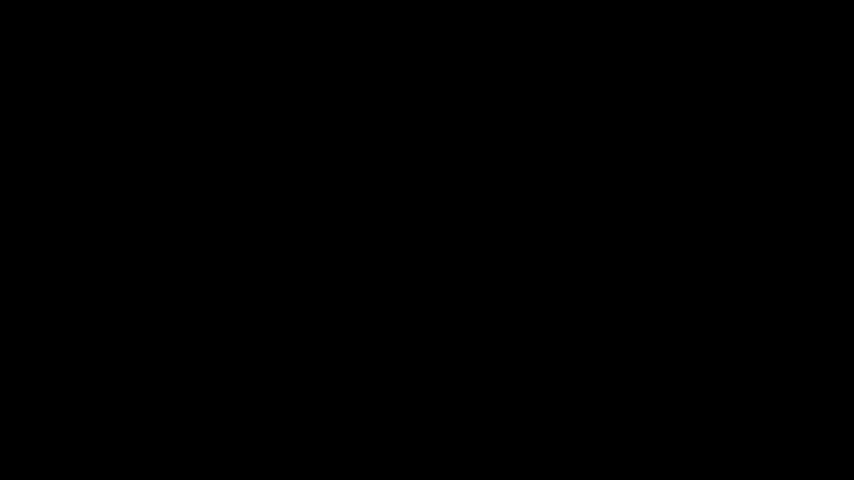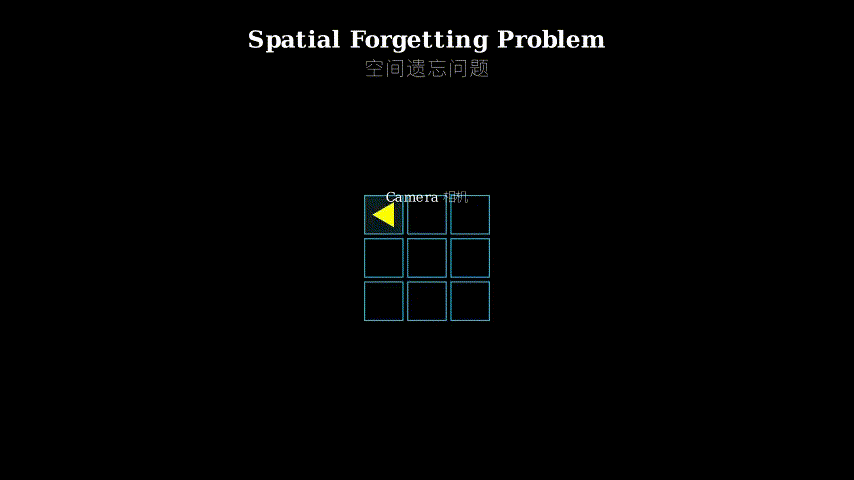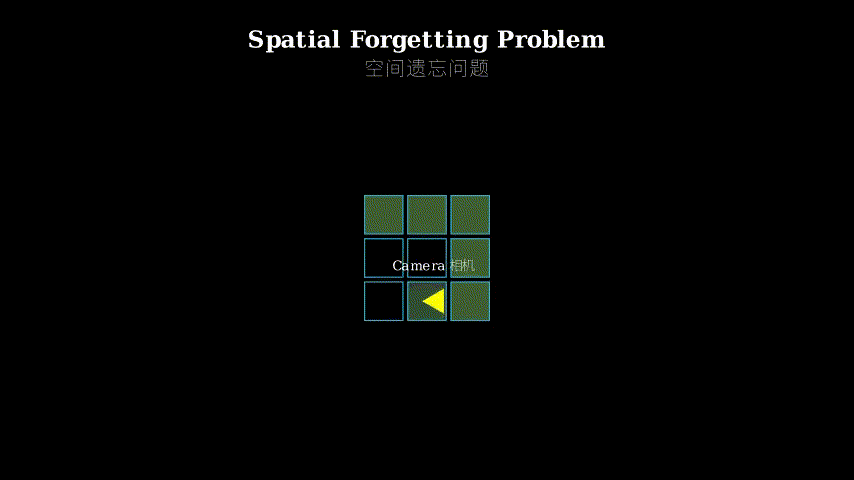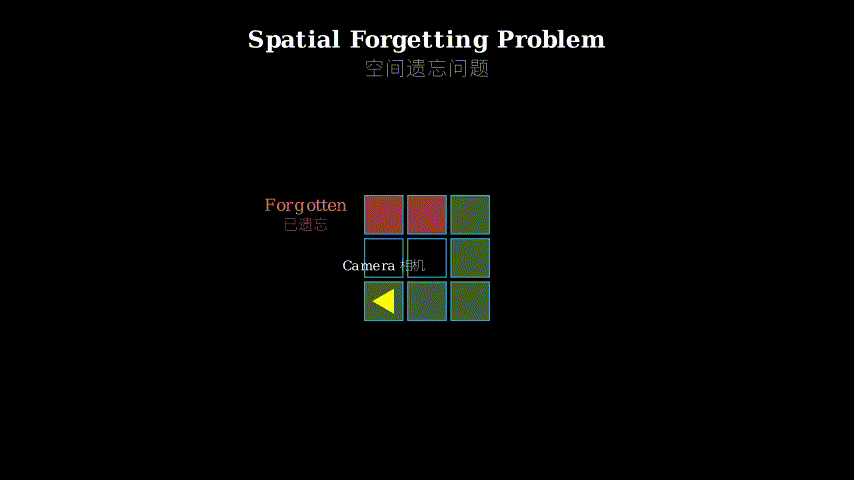
Video generation models can now create camera-controlled walkthroughs that look like 3D scenes. The promise: generate a video, lift it to 3D geometry, and you’ve got an explorable world. But current methods break down when you need long trajectories with revisits — the camera returns to a location it saw 100 frames ago, and the model hallucinates a completely different structure. Two failure modes kill scalability: spatial forgetting (the model’s temporal context window is too short to remember distant locations) and temporal drifting (autoregressive generation compounds small errors until geometry warps and appearance degrades). Prior work like persistent video generation or multi-view synthesis either limits trajectory length or accepts inconsistent geometry when revisiting locations.
Problem: Long 3D-consistent video generation
    |
    v
Limitation: Temporal context < trajectory length
    |
    +---> Spatial forgetting: hallucinate on revisit
    |
    +---> Temporal drifting: errors accumulate
    |
    v
Method: Geometry routing + drift-aware training
    |
    v
Evidence: 10x longer trajectories, consistent revisits
    |
    v
Conclusion: Scalable explorable 3D worlds
The Increment
One sentence: Before this paper, video-to-3D generation collapsed after ~50 frames of camera motion; after, it maintains consistency across 500+ frame trajectories with location revisits.
Core Mechanism
Lyra 2.0 treats 3D geometry as a routing index, not a generation target. As the model generates each frame, it reconstructs lightweight 3D geometry (point clouds, depth maps). When generating a new viewpoint, the system queries this geometry database to find relevant past frames and establishes dense pixel correspondences. These correspondences tell the video model “this pixel should look like that pixel from frame 47” — but the model still synthesizes appearance using its generative prior, not by copying pixels. This decouples spatial memory (handled by geometry) from appearance synthesis (handled by the generative model).
To handle temporal drift, the training process is self-adversarial. During training, the model generates its own degraded outputs (with accumulated errors), then learns to correct them. Instead of only seeing clean ground-truth histories, it practices recovering from the kinds of drift it will encounter during autoregressive generation. This teaches the model to be a drift corrector rather than a drift propagator.
The final step feeds these long, consistent video trajectories into a feed-forward 3D reconstruction model (like a NeRF or Gaussian splatting network), which learns to lift the generated videos into renderable 3D scenes.
Input: Target camera pose
    |
    v
[Geometry Database] <--- Past frames + reconstructed 3D
    |
    v
Retrieve relevant frames via 3D proximity
    |
    v
Establish dense correspondences (pixel-to-pixel)
    |
    v
[Video Model] ---> Generate new frame
    ^              (uses correspondences as hints,
    |               but synthesizes appearance)
    |
Self-augmented history (includes model's own drift)
    |
    v
Reconstruct 3D geometry from new frame
    |
    v
Add to geometry database ---> Loop
Think of it like a city tour guide with a photo album. The guide (video model) shows you around, and after each stop, they sketch a rough map (3D geometry). When you ask to revisit a location, they flip through the album to find photos from that area and use the map to figure out which photos match your current viewpoint. But they don’t just show you the old photos — they describe what you’re seeing now, using the old photos as memory aids. If their descriptions start drifting from reality (maybe they misremember a building’s color), they’ve been trained by practicing with their own flawed descriptions, so they know how to self-correct rather than doubling down on the error.
Key Concepts
-
Spatial forgetting: Video models have a temporal context window (say, 16 frames). When you generate frame 200 and want to revisit a location from frame 50, those frames are 150 steps apart — far outside the context window. The model has no direct memory of frame 50, so it hallucinates new structures instead of maintaining consistency. It’s like asking someone to redraw a room they saw an hour ago without looking at photos — they’ll invent details. Lyra solves this by using 3D geometry as an external memory: “I don’t remember frame 50, but my geometry index says this viewpoint should look similar to frame 50, so let me retrieve it.”
-
Temporal drifting: Autoregressive generation means each frame depends on the previous frame. If frame N has a tiny error (a wall is 1 pixel too far left), frame N+1 builds on that error, frame N+2 compounds it further, and by frame N+100, the wall has drifted 10 pixels and the whole room looks warped. Traditional training only shows the model clean histories, so it never learns to recognize or correct drift. Lyra’s self-augmented training is like practicing piano with recordings of your own mistakes — you learn to hear when you’re going off-key and correct mid-performance.
-
Geometry as routing, not target: Most 3D generation methods try to predict perfect geometry directly. Lyra uses geometry only to answer “which past frames are relevant to this viewpoint?” The geometry can be noisy, incomplete, or low-resolution — it just needs to be good enough for spatial indexing. This is like using a rough sketch map to find your way around a city; the map doesn’t need to be photorealistic, it just needs to show which streets connect. The actual appearance comes from the generative model, which has learned rich visual priors from massive video datasets.
Framework Shift
Before (mainstream approach):        After (this paper):

Video Model (context window)         Video Model + Geometry Index
    |                                     |
    v                                     v
[Frame 1] -> [Frame 2] -> ...        [Frame 1] -> Reconstruct 3D
    |                                     |
    v                                     v
[Frame N] (forgets Frame 1)          [Frame N] -> Query geometry
    |                                     |
    v                                     v
Hallucinate on revisit               Retrieve Frame 1 -> Consistent

Training: Clean histories            Training: Self-augmented
    |                                     |
    v                                     v
Model never sees drift               Model practices correcting drift
From temporal-only memory to spatial-temporal memory with self-correction, the core shift is treating 3D geometry as an external routing layer that extends the model’s effective context window indefinitely.
Expert Assessment
Problem choice: This is a real gap at the intersection of video generation and 3D reconstruction. The “generate video, lift to 3D” paradigm is genuinely promising for content creation, and the failure modes (spatial forgetting, temporal drift) are well-motivated by actual system behavior, not manufactured for the paper. It sits at a sweet spot where video models are good enough to be useful but not yet good enough to scale.
Method maturity: The geometry-as-routing idea is elegant — it sidesteps the hard problem of perfect 3D reconstruction by using geometry only for indexing. The self-augmented training is clever but feels slightly underexplored; the paper doesn’t deeply analyze what kinds of drift the model learns to correct vs. what it still propagates. The approach is more “principled engineering” than “fundamental insight,” but that’s appropriate for a systems paper.
Experimental integrity: Baselines are reasonable (prior video generation methods, ablations of the two main components). The 10x improvement in trajectory length is compelling, but the paper leans heavily on qualitative results and user studies. I’d want to see more quantitative metrics on geometric consistency (e.g., reprojection error when revisiting locations). The feed-forward reconstruction step feels somewhat orthogonal — it’s a nice application, but the core contribution is the video generation part.
Writing quality: The abstract and introduction are strong. The method section gets dense quickly and could benefit from more visual diagrams (the paper has them, but they’re not always well-integrated with the text). The related work section is thorough but reads like a checklist. The biggest missed opportunity: the paper doesn’t clearly articulate when this approach would fail (e.g., what happens with extreme occlusions or very sparse geometry?).
Verdict: weak accept — Solid engineering contribution that pushes video-to-3D generation toward practical scale, but lacks the conceptual depth or experimental rigor for a strong accept. The method works, but the paper doesn’t fully illuminate why it works or where it breaks.
Takeaways
Geometry as routing index: If you’re building any system that needs long-term spatial memory (robotics, AR, simulation), consider maintaining a lightweight geometric index purely for information retrieval, separate from your main representation. You don’t need perfect geometry — just good enough to answer “what past observations are relevant here?”
Self-augmented training for autoregressive models: When training models that will run autoregressively at inference time, include degraded outputs from the model itself in the training data. This teaches the model to be robust to its own errors rather than assuming perfect inputs. Applicable beyond video generation — think language models, time series prediction, any sequential generation task.
Decoupling memory from synthesis: The insight that you can use one modality (3D geometry) for memory/routing while using another (generative video model) for synthesis is broadly useful. In multi-modal systems, don’t assume the same representation needs to handle both retrieval and generation.
论文: 2604.13036 作者: Tianchang Shen, Sherwin Bahmani, Kai He, Sangeetha Grama Srinivasan, Tianshi Cao, Jiawei Ren, Ruilong Li, Zian Wang, Nicholas Sharp, Zan Gojcic 分类: cs.CV
缺口
视频生成模型现在能创建相机可控的场景漫游,看起来像3D场景。
承诺很美好:生成视频,提升到3D几何,你就得到了可探索的世界。
但当你需要长轨迹且要重访位置时,现有方法就崩了——相机回到100帧前看过的位置,模型却幻想出完全不同的结构。
两种失效模式扼杀了可扩展性:空间遗忘(模型的时间上下文窗口太短,记不住远处的位置)和时间漂移(自回归生成累积小误差,直到几何扭曲、外观退化)。
之前的工作如持久视频生成或多视角合成,要么限制轨迹长度,要么在重访位置时接受不一致的几何。
问题:长时3D一致视频生成
    |
    v
局限:时间上下文 < 轨迹长度
    |
    +---> 空间遗忘:重访时产生幻觉
    |
    +---> 时间漂移:误差累积
    |
    v
方法:几何路由 + 漂移感知训练
    |
    v
证据:10倍长轨迹,一致重访
    |
    v
结论:可扩展的可探索3D世界
增量
一句话: 这篇论文之前,视频转3D生成在约50帧相机运动后就崩溃;之后,它能在500+帧轨迹中保持一致性,且支持位置重访。
核心机制
Lyra 2.0把3D几何当作路由索引,而非生成目标。
模型生成每一帧时,会重建轻量级3D几何(点云、深度图)。
生成新视角时,系统查询这个几何数据库找到相关的过去帧,并建立密集像素对应关系。
这些对应关系告诉视频模型”这个像素应该看起来像第47帧的那个像素”——但模型仍用其生成先验合成外观,而非复制像素。
这将空间记忆(由几何处理)与外观合成(由生成模型处理)解耦。
为处理时间漂移,训练过程是自对抗的。
训练时,模型生成自己的退化输出(带累积误差),然后学习纠正它们。
它不只看干净的真值历史,还练习从自回归生成中会遇到的那种漂移中恢复。
这教会模型成为漂移纠正器而非漂移传播器。
最后一步将这些长且一致的视频轨迹输入前馈3D重建模型(如NeRF或高斯溅射网络),该模型学习将生成的视频提升为可渲染的3D场景。
输入:目标相机姿态
    |
    v
[几何数据库] <--- 过去帧 + 重建的3D
    |
    v
通过3D邻近性检索相关帧
    |
    v
建立密集对应关系(像素到像素)
    |
    v
[视频模型] ---> 生成新帧
    ^              (用对应关系作提示,
    |               但合成外观)
    |
自增强历史(包含模型自己的漂移)
    |
    v
从新帧重建3D几何
    |
    v
加入几何数据库 ---> 循环
把它想象成一个带相册的城市导游。
导游(视频模型)带你四处转,每到一站,他们画一张粗略地图(3D几何)。
当你要求重访某个位置时,他们翻相册找那个区域的照片,用地图判断哪些照片匹配你当前的视角。
但他们不是直接给你看旧照片——他们描述你现在看到的东西,用旧照片作记忆辅助。
如果他们的描述开始偏离现实(也许记错了建筑的颜色),他们受过用自己有缺陷的描述练习的训练,所以知道如何自我纠正,而非在错误上加倍。
关键概念
- 空间遗忘: 视频模型有时间上下文窗口(比如16帧)。
当你生成第200帧并想重访第50帧的位置时,这些帧相隔150步——远超上下文窗口。
模型对第50帧没有直接记忆,所以幻想新结构而非保持一致性。
就像让某人在不看照片的情况下重画一小时前看过的房间——他们会编造细节。
Lyra通过用3D几何作外部记忆解决这个问题:“我不记得第50帧,但我的几何索引说这个视角应该看起来像第50帧,所以让我检索它。”
- 时间漂移: 自回归生成意味着每一帧依赖前一帧。
如果第N帧有微小误差(墙向左偏了1像素),第N+1帧在这个误差上构建,第N+2帧进一步复合,到第N+100帧时,墙已经漂移了10像素,整个房间看起来扭曲了。
传统训练只给模型看干净的历史,所以它从未学会识别或纠正漂移。
Lyra的自增强训练就像用自己错误的录音练钢琴——你学会听出何时跑调并在演奏中纠正。
- 几何作为路由而非目标: 大多数3D生成方法试图直接预测完美几何。
Lyra只用几何回答”哪些过去帧与这个视角相关?”
几何可以有噪声、不完整或低分辨率——只需足够好用于空间索引。
这就像用粗略的草图地图在城市里找路;地图不需要照片级真实,只需显示哪些街道相连。
实际外观来自生成模型,它从海量视频数据集学到了丰富的视觉先验。
框架转变
之前(主流方法):                之后(本文方法):

视频模型(上下文窗口)            视频模型 + 几何索引
    |                                 |
    v                                 v
[帧1] -> [帧2] -> ...             [帧1] -> 重建3D
    |                                 |
    v                                 v
[帧N](忘记帧1)                  [帧N] -> 查询几何
    |                                 |
    v                                 v
重访时产生幻觉                    检索帧1 -> 一致

训练:干净历史                    训练:自增强
    |                                 |
    v                                 v
模型从未见过漂移                  模型练习纠正漂移
从纯时间记忆到带自纠正的时空记忆,核心转变是将3D几何视为外部路由层,无限扩展模型的有效上下文窗口。
专家评审
选题眼光: 这是视频生成和3D重建交叉点上的真实缺口。
“生成视频,提升到3D”范式对内容创作确实有前景,失效模式(空间遗忘、时间漂移)由实际系统行为充分激发,不是为论文制造的。
它处于一个甜蜜点:视频模型足够好可以使用,但还不够好能扩展。
方法成熟度: 几何作为路由的想法很优雅——它通过只用几何做索引绕过了完美3D重建的难题。
自增强训练很巧妙但感觉探索略浅;论文没有深入分析模型学会纠正哪些漂移vs仍然传播哪些。
这个方法更像”有原则的工程”而非”基础洞见”,但对系统论文来说这是合适的。
实验诚意: 基线合理(先前的视频生成方法、两个主要组件的消融)。
轨迹长度10倍改进很有说服力,但论文严重依赖定性结果和用户研究。
我想看更多几何一致性的定量指标(如重访位置时的重投影误差)。
前馈重建步骤感觉有些正交——这是个不错的应用,但核心贡献是视频生成部分。
写作功力: 摘要和引言很强。
方法部分很快变得密集,可以从更多视觉图表中受益(论文有图,但与文本整合得不总是很好)。
相关工作部分很全面但读起来像清单。
最大的错失机会:论文没有清楚阐明这个方法何时会失败(如极端遮挡或非常稀疏的几何会发生什么?)。
判决: 弱接收——扎实的工程贡献,将视频转3D生成推向实用规模,但缺乏强接收所需的概念深度或实验严谨性。
方法有效,但论文没有充分阐明为什么有效或在哪里会崩溃。
要点总结
几何作为路由索引: 如果你在构建任何需要长期空间记忆的系统(机器人、AR、仿真),考虑维护一个轻量级几何索引纯粹用于信息检索,与你的主表示分离。
你不需要完美几何——只需足够好能回答”哪些过去观察与这里相关?”
自回归模型的自增强训练: 训练将在推理时自回归运行的模型时,在训练数据中包含模型自己的退化输出。
这教会模型对自己的错误保持鲁棒,而非假设完美输入。
适用范围超越视频生成——想想语言模型、时间序列预测、任何序列生成任务。
解耦记忆与合成: 你可以用一种模态(3D几何)做记忆/路由,同时用另一种(生成视频模型)做合成,这个洞见广泛适用。
在多模态系统中,不要假设同一表示需要同时处理检索和生成。