Paper: 2604.25860 Authors: Lucio La Cava, Andrea Tagarelli Categories: cs.CL, cs.AI, cs.CY
The Gap
Existing MGT detectors chase model-specific fingerprints—watermarks, statistical artifacts, classifier-based patterns. This creates a cat-and-mouse game: each new generation model requires retraining detectors, adversarial attacks easily fool them, and cross-domain/cross-language generalization fails. Methods like DetectGPT use perplexity curvature but require expensive perturbations and model access. The field needs a structural invariant that holds across models, languages, and domains without retraining.
Problem: Model-specific fingerprints fail to generalize
   |
   v
Assumption: LLMs have local coherence but structural fragility
   |
   v
Method: Measure perplexity shift under random shuffling
   |
   v
Evidence: MGT shows distinct dispersion pattern vs human text
   |
   v
Conclusion: Zero-shot detection via density estimation on shuffle-perplexity features
The Increment
One sentence: Before this paper, detectors needed model-specific training or expensive perturbations; after, a simple shuffling procedure exposes a universal structural signature that works zero-shot across models, languages, and domains.
Core Mechanism
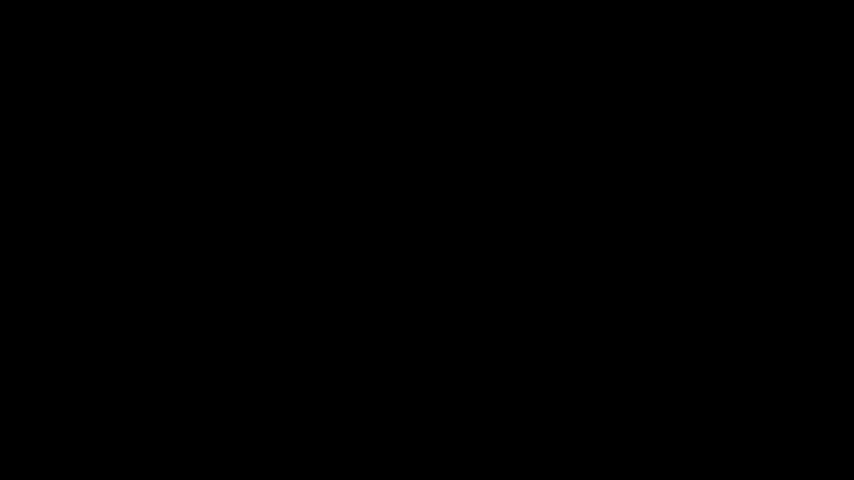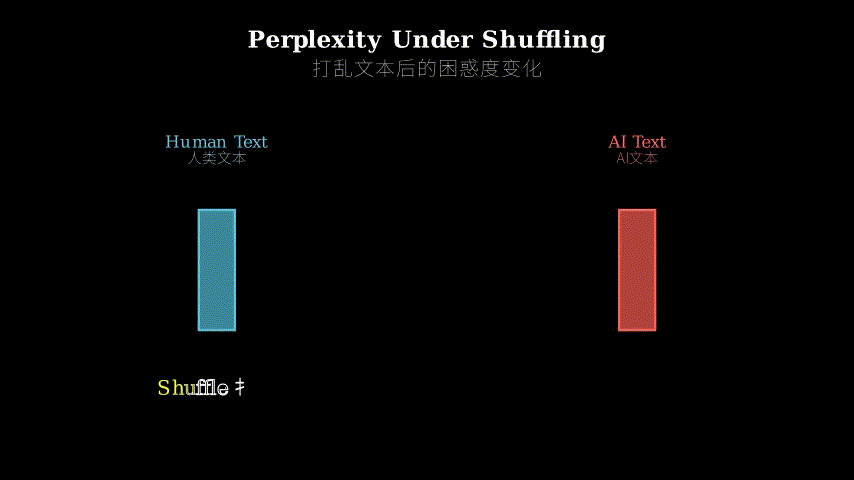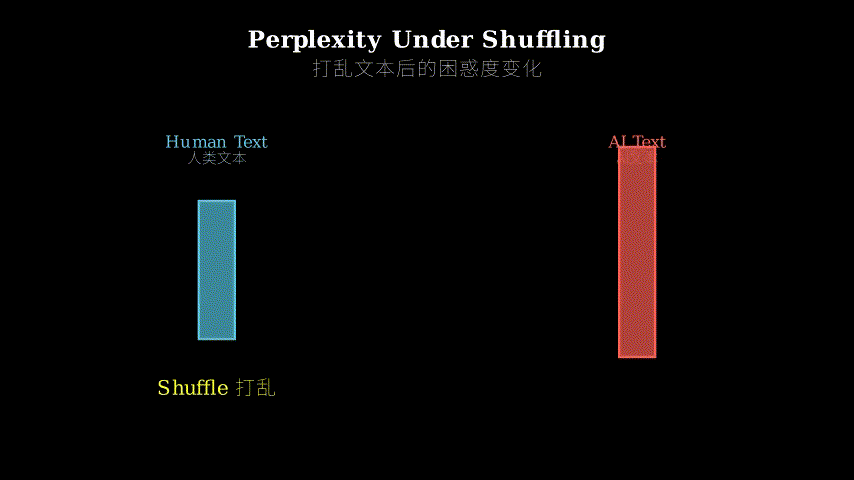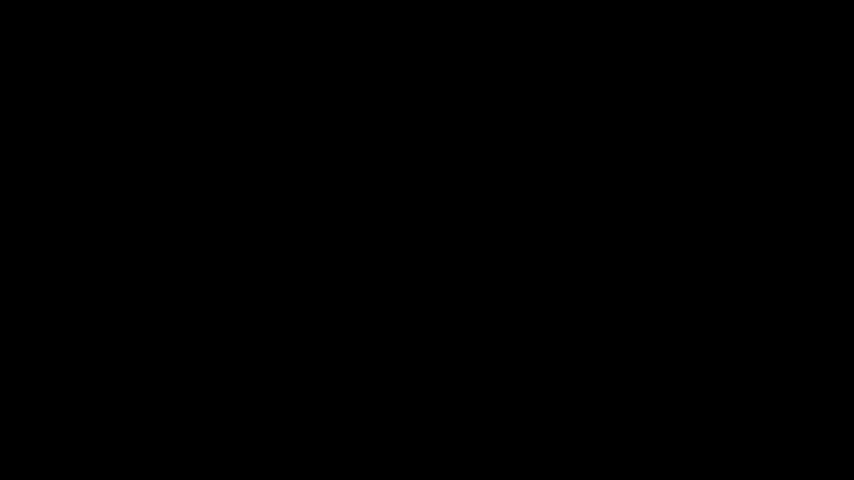
Luminol-AIDetect operates on a simple premise: shuffle the input text randomly, measure how perplexity changes, and use that shift as a discriminant. For a given text, the method generates multiple shuffled versions by randomly reordering sentences or chunks. Each version gets fed to a reference language model to compute perplexity. The original text’s perplexity and the distribution of shuffled perplexities (mean, variance, quantiles) become scalar features.
These features feed into a two-stage classifier. First, a density estimator (like Gaussian Mixture Model) learns the distribution of human-written text features in an unsupervised way. Second, an ensemble of simple classifiers (logistic regression, decision trees) votes on whether the input’s feature vector falls within the human distribution or outside it. No labeled MGT data needed for training—only human text to anchor the “normal” distribution.
The key insight: human writing has structural redundancy that survives shuffling with relatively stable perplexity, while LLM-generated text, despite local fluency, exhibits fragile long-range dependencies. Shuffling breaks these dependencies, causing perplexity to spike or disperse in characteristic ways. The method doesn’t care which model generated the text—it only cares about this structural signature.
Structural metaphor: Think of text as a suspension bridge. Human-written bridges have redundant cables—cut a few, and the bridge still holds its shape (perplexity stays stable). LLM-generated bridges look identical from the ground but rely on a single main cable (autoregressive chain). Shuffle the support points, and the LLM bridge sags dramatically (perplexity spikes), while the human bridge flexes but holds. Luminol measures the sag pattern to tell bridges apart.
Key Concepts
-
Perplexity under shuffling: Perplexity measures how “surprised” a language model is by a text—lower means more predictable. Shuffling destroys long-range structure but preserves local n-grams. Human text has structural redundancy (topic coherence, argument flow) that isn’t purely sequential, so shuffling causes moderate perplexity increase. LLM text relies heavily on autoregressive order—shuffling breaks the chain, causing larger, more variable perplexity shifts. Example: “The cat sat on the mat” → shuffle to “mat the on sat cat The” still has recognizable words, but an LLM trained on ordered sequences finds the shuffled version far less probable than a human would tolerate in their writing’s structural flexibility.
-
Zero-shot via density estimation: Traditional classifiers need labeled examples of both classes. Density estimation flips this: learn what “normal” (human text) looks like, then flag anything that doesn’t fit. Luminol trains only on human text features, building a probabilistic model of their distribution. At test time, if an input’s features fall in low-density regions of this model, it’s likely MGT. This works zero-shot because you never need to see MGT examples—you’re detecting “not human” rather than “is GPT-4” or “is Claude.”
-
Structural invariance: A signal is structurally invariant if it persists across different instantiations of the same underlying process. Luminol seeks invariance across generation models, not model-specific quirks. The shuffle-perplexity signature reflects a fundamental property of autoregressive generation (sequential dependency) vs human composition (multi-scale planning). This makes it robust to model updates, fine-tuning, and adversarial prompts that fool fingerprint-based detectors.
Framework Shift
Before (mainstream approach):        After (this paper):

  Input Text                           Input Text
      |                                    |
      v                                    v
  Extract Features                     Shuffle Randomly
  (n-grams, embeddings)                    |
      |                                    +---> Multiple Shuffled Versions
      v                                    |
  Train Classifier                         v
  (needs labeled MGT)                  Compute Perplexity (original + shuffled)
      |                                    |
      v                                    v
  Predict: Human / MGT                 Extract Scalar Features (mean, var, quantiles)
                                           |
  [Fails on new models,                    v
   needs retraining,                   Density Estimation (human text only)
   adversarially fragile]                  |
                                           v
                                       Ensemble Vote: Human / MGT

                                       [Works zero-shot,
                                        model-agnostic,
                                        robust to attacks]
One sentence: From chasing model-specific fingerprints to measuring structural fragility, the core shift is treating generation as a process with invariant failure modes rather than a black box with learnable artifacts.
Expert Assessment
Problem choice: Real gap. The arms race between generators and detectors is unsustainable, and cross-domain/cross-lingual generalization is a genuine pain point. The paper correctly identifies that structural invariants are the way out, not bigger classifiers.
Method maturity: Clever insight with simple execution. The shuffling procedure is almost embarrassingly straightforward, which is a strength—no complex perturbations, no gradient access required. However, the reliance on a reference LM for perplexity computation is a hidden cost. The paper doesn’t deeply explore what happens when the reference model is much weaker or stronger than the generator. Also, the density estimation step feels like a patch to avoid needing labeled MGT data; a more principled threshold derivation would strengthen the method.
Experimental integrity: Strong. Eight domains, 11 attack types, 18 languages—this is thorough. Baselines include DetectGPT, GPTZero, and others, which is fair. The 17x FPR improvement is striking, but the paper should report absolute FPR/TPR numbers more prominently, not just relative gains. One concern: the human text baseline comes from specific corpora (news, essays). How does the method perform on human text that’s structurally unusual (poetry, stream-of-consciousness, code comments)? The paper hints at this but doesn’t stress-test it.
Writing quality: The abstract and intro are crisp. The method section could use a clearer algorithmic pseudocode block—right now, the shuffling procedure is described in prose, making it harder to reproduce. The related work section is comprehensive but reads like a list; grouping prior work by approach (fingerprint-based, perturbation-based, zero-shot) would improve clarity. The results section is dense with tables; a single summary figure showing the perplexity distribution shift (human vs MGT) would make the core finding visceral.
Verdict: strong accept — Addresses a real problem with a simple, generalizable method and backs it with extensive experiments. The structural invariance angle is the right direction for the field.
Takeaways
Steal the shuffling diagnostic: Even if you’re not building a detector, the shuffle-perplexity test is a useful probe for any text generation system. If your model’s output shows high perplexity variance under shuffling, it’s relying too heavily on sequential order and may lack robustness. Use this as a development-time sanity check.
Density estimation for anomaly detection: The pattern here—train only on “normal” examples, flag outliers—transfers to any domain where you have abundant negative examples but scarce or shifting positive examples. Think fraud detection, system monitoring, or content moderation where adversaries constantly adapt.
Structural invariants over fingerprints: When building detectors for any generative system (images, audio, code), look for properties that reflect the generation process itself, not incidental artifacts. Luminol’s success comes from targeting autoregressive fragility, not GPT-4’s specific quirks. This framing applies beyond text.
论文: 2604.25860 作者: Lucio La Cava, Andrea Tagarelli 分类: cs.CL, cs.AI, cs.CY
缺口
现有的机器生成文本检测器追逐模型特定的指纹——水印、统计伪影、基于分类器的模式。
这造成了猫鼠游戏:每个新生成模型都需要重新训练检测器,对抗攻击轻易骗过它们,跨领域/跨语言泛化失败。
DetectGPT 等方法使用困惑度曲率,但需要昂贵的扰动和模型访问。
该领域需要一个结构不变量,能在不重新训练的情况下跨模型、语言和领域保持有效。
问题:模型特定指纹无法泛化
   |
   v
假设:LLM 有局部连贯性但结构脆弱性
   |
   v
方法:测量随机打乱下的困惑度变化
   |
   v
证据:MGT 显示出与人类文本不同的离散模式
   |
   v
结论:通过打乱-困惑度特征的密度估计实现零样本检测
增量
一句话: 这篇论文之前,检测器需要模型特定训练或昂贵的扰动;
之后,一个简单的打乱程序就能暴露出通用的结构签名,零样本跨模型、语言和领域工作。
核心机制
Luminol-AIDetect 基于一个简单前提:随机打乱输入文本,测量困惑度如何变化,并将这种变化用作判别标准。
对于给定文本,该方法通过随机重排句子或块来生成多个打乱版本。
每个版本都输入参考语言模型以计算困惑度。
原始文本的困惑度和打乱困惑度的分布(均值、方差、分位数)成为标量特征。
这些特征输入两阶段分类器。
首先,密度估计器(如高斯混合模型)以无监督方式学习人类书写文本特征的分布。
其次,简单分类器的集成(逻辑回归、决策树)投票决定输入的特征向量是落在人类分布内还是外。
训练不需要标注的 MGT 数据——只需要人类文本来锚定”正常”分布。
关键洞察:人类写作具有结构冗余,在打乱后困惑度相对稳定,而 LLM 生成的文本尽管局部流畅,却表现出脆弱的长程依赖。
打乱破坏了这些依赖,导致困惑度以特征性方式飙升或离散。
该方法不关心哪个模型生成了文本——它只关心这个结构签名。
核喻:把文本想象成悬索桥。
人类写的桥有冗余缆索——剪断几根,桥仍保持形状(困惑度保持稳定)。
LLM 生成的桥从地面看起来一样,但依赖单一主缆(自回归链)。
打乱支撑点,LLM 的桥会剧烈下垂(困惑度飙升),而人类的桥会弯曲但保持住。
Luminol 测量下垂模式来区分桥梁。
关键概念
- 打乱下的困惑度:困惑度衡量语言模型对文本的”惊讶”程度——越低越可预测。
打乱破坏长程结构但保留局部 n-gram。
人类文本具有结构冗余(主题连贯性、论证流程),不是纯粹顺序的,所以打乱导致适度的困惑度增加。
LLM 文本严重依赖自回归顺序——打乱破坏链条,导致更大、更多变的困惑度变化。
例子:“猫坐在垫子上”→ 打乱成”垫子上在坐猫”仍有可识别的词,但在有序序列上训练的 LLM 发现打乱版本的概率远低于人类在其写作结构灵活性中能容忍的程度。
- 通过密度估计实现零样本:传统分类器需要两类的标注样本。
密度估计翻转了这一点:学习”正常”(人类文本)的样子,然后标记任何不符合的东西。
Luminol 只在人类文本特征上训练,构建其分布的概率模型。
测试时,如果输入的特征落在该模型的低密度区域,它很可能是 MGT。
这是零样本的,因为你永远不需要看到 MGT 样本——你在检测”非人类”而不是”是 GPT-4”或”是 Claude”。
- 结构不变性:如果一个信号在同一底层过程的不同实例化中持续存在,它就是结构不变的。
Luminol 寻求跨生成模型的不变性,而不是模型特定的怪癖。
打乱-困惑度签名反映了自回归生成(顺序依赖)与人类创作(多尺度规划)的基本属性。
这使其对模型更新、微调和欺骗基于指纹的检测器的对抗提示具有鲁棒性。
框架转变
之前(主流方法):                之后(本文方法):

  输入文本                          输入文本
      |                                |
      v                                v
  提取特征                          随机打乱
  (n-gram, 嵌入)                       |
      |                                +---> 多个打乱版本
      v                                |
  训练分类器                           v
  (需要标注的 MGT)                  计算困惑度(原始+打乱)
      |                                |
      v                                v
  预测:人类 / MGT                  提取标量特征(均值、方差、分位数)
                                       |
  [在新模型上失败,                    v
   需要重新训练,                   密度估计(仅人类文本)
   对抗脆弱]                           |
                                       v
                                   集成投票:人类 / MGT

                                   [零样本工作,
                                    模型无关,
                                    对攻击鲁棒]
一句话:从追逐模型特定指纹到测量结构脆弱性,核心转变是将生成视为具有不变失效模式的过程,而不是具有可学习伪影的黑盒。
专家评审
选题眼光:真实缺口。
生成器和检测器之间的军备竞赛不可持续,跨领域/跨语言泛化是真正的痛点。
论文正确识别出结构不变量是出路,而不是更大的分类器。
方法成熟度:巧妙洞察,简单执行。
打乱程序几乎简单得令人尴尬,这是优势——无需复杂扰动,无需梯度访问。
然而,依赖参考 LM 进行困惑度计算是隐藏成本。
论文没有深入探讨当参考模型比生成器弱得多或强得多时会发生什么。
此外,密度估计步骤感觉像是避免需要标注 MGT 数据的补丁;
更有原则的阈值推导会加强该方法。
实验诚意:强。
八个领域、11 种攻击类型、18 种语言——这很彻底。
基线包括 DetectGPT、GPTZero 等,这是公平的。
17 倍 FPR 改进令人印象深刻,但论文应该更突出地报告绝对 FPR/TPR 数字,而不仅仅是相对增益。
一个担忧:人类文本基线来自特定语料库(新闻、论文)。
该方法在结构不寻常的人类文本(诗歌、意识流、代码注释)上表现如何?
论文暗示了这一点,但没有压力测试。
写作功力:摘要和引言简洁。
方法部分可以使用更清晰的算法伪代码块——现在,打乱程序用散文描述,使其更难复现。
相关工作部分全面但读起来像列表;
按方法(基于指纹、基于扰动、零样本)对先前工作分组会提高清晰度。
结果部分表格密集;
一个显示困惑度分布变化(人类 vs MGT)的单一总结图会使核心发现更直观。
判决:强接收 — 用简单、可泛化的方法解决真实问题,并用广泛的实验支持。
结构不变性角度是该领域的正确方向。
要点总结
偷走打乱诊断:即使你不是在构建检测器,打乱-困惑度测试也是任何文本生成系统的有用探针。
如果你的模型输出在打乱下显示高困惑度方差,它过度依赖顺序,可能缺乏鲁棒性。
将此用作开发时的健全性检查。
用于异常检测的密度估计:这里的模式——只在”正常”样本上训练,标记异常值——可迁移到任何你有丰富负样本但稀缺或变化的正样本的领域。
想想欺诈检测、系统监控或对手不断适应的内容审核。
结构不变量优于指纹:在为任何生成系统(图像、音频、代码)构建检测器时,寻找反映生成过程本身的属性,而不是偶然伪影。
Luminol 的成功来自针对自回归脆弱性,而不是 GPT-4 的特定怪癖。
这种框架适用于文本之外。