Paper: 2605.31584 Authors: Nianyi Lin, Jiajie Zhang, Lei Hou, Juanzi Li Categories: cs.CL, cs.AI, cs.LG
The Gap
Existing reinforcement learning approaches for long-context reasoning (RLVR) suffer from two critical weaknesses: they use randomly sampled distractors that are too easy to distinguish from relevant content, and they provide only sparse, outcome-based rewards that fail to guide the model through multi-step reasoning chains. The model gets a binary signal at the end—right or wrong—but no feedback on whether it’s extracting the right evidence or following a coherent reasoning path. This is like teaching someone to solve a math problem by only telling them if the final answer is correct, without checking their work.
Problem: Long-context reasoning fails when key info is buried
    |
    v
Prior RLVR: Random distractors + outcome-only rewards
    |
    +---> Weakness 1: Low-confusability distractors (too easy)
    +---> Weakness 2: No supervision for intermediate steps
    |
    v
LongTraceRL: Search trajectories + rubric rewards
    |
    +---> Tiered distractors from agent behavior (high confusability)
    +---> Entity-level process supervision (fine-grained feedback)
    |
    v
Evidence: Consistent gains across 5 benchmarks, 3 model sizes
    |
    v
Conclusion: Process supervision + realistic distractors improve reasoning
The Increment
One sentence: Before this paper, long-context RL used random distractors and binary rewards; after, we have search-derived tiered distractors and entity-level rubric rewards that supervise the reasoning process.
Core Mechanism
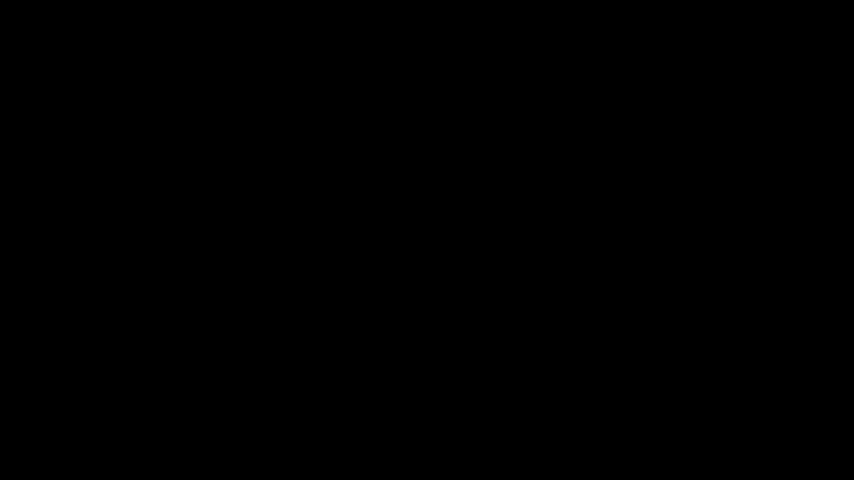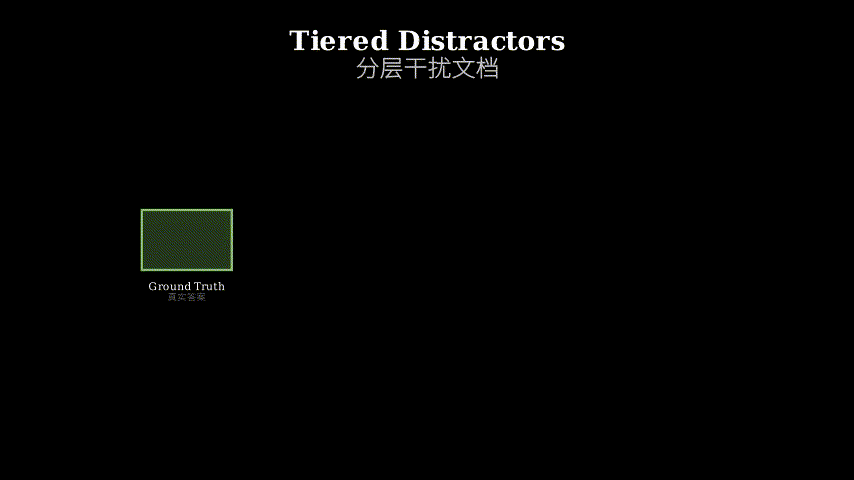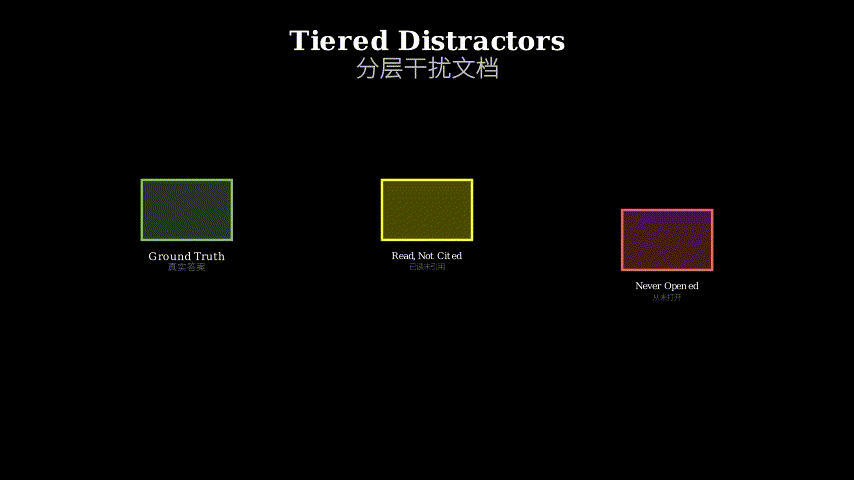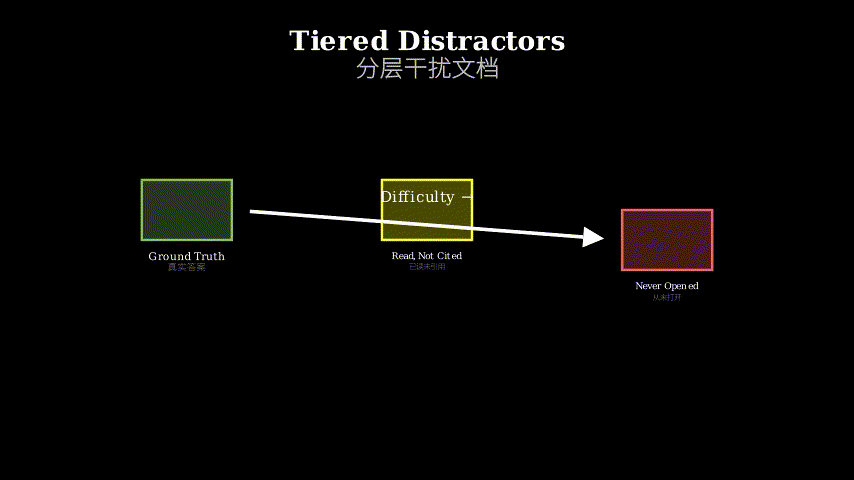
LongTraceRL has two main components working in tandem. First, the data construction pipeline generates multi-hop questions from knowledge graphs and uses a search agent to create tiered distractors. The agent performs iterative search—reading documents, deciding what to cite, and continuing until it answers the question. Documents the agent read but didn’t cite become high-confusability distractors (they looked relevant but weren’t useful). Documents that appeared in search results but were never opened become low-confusability distractors (they were clearly irrelevant). This creates training contexts far harder than random sampling.
Second, the reward mechanism provides rubric rewards that score responses based on whether they mention the gold entities along the reasoning chain. For a multi-hop question requiring entities E1 → E2 → E3, a response mentioning all three gets a higher reward than one mentioning only E1 and E3, even if both reach the correct final answer. Crucially, this rubric reward is applied only to correct responses (positive-only strategy), distinguishing high-quality reasoning from lucky guesses while avoiding reward hacking where the model learns to mention entities without actually reasoning.
Data Construction:
Knowledge Graph --[random walk]--> Multi-hop Question
        |
        v
Search Agent Trajectory:
[Query] --> [Results] --> [Read Doc1, Doc2, ...] --> [Cite Doc1] --> [Answer]
        |           |                    |
        v           v                    v
    Never opened  Read but not cited  Actually cited
        |           |                    |
        v           v                    v
    Low-conf     High-conf           Gold documents
    distractor   distractor          (ground truth)

Reward Calculation (only for correct answers):
Response text --[entity extraction]--> Mentioned entities
        |
        v
Compare with gold chain: E1 -> E2 -> E3
        |
        v
Rubric score: (# mentioned) / (# total in chain)
Think of this like training a detective. Instead of just telling them “you got the wrong suspect” (outcome-only reward), you’re showing them case files where other detectives followed dead-end leads (high-confusability distractors) versus irrelevant noise (low-confusability distractors). Then, when they solve a case correctly, you grade their report based on whether they documented each key piece of evidence in the chain (rubric reward). A detective who stumbles on the right answer by luck gets a lower score than one who methodically traced each clue. The “positive-only” strategy means you only grade successful cases—you don’t penalize failed attempts by checking if they mentioned the right evidence, because that would teach them to just name-drop entities without reasoning.
Key Concepts
-
Tiered Distractors: Not all irrelevant documents are equally distracting. A document about “Python programming” is easy to ignore when answering “Who directed The Godfather?” But a document about “Francis Ford Coppola’s early career in theater” is hard to ignore—it’s topically related but doesn’t contain the answer. LongTraceRL creates this second type by recording what a search agent *almost used. If the agent read a document but decided not to cite it, that document was confusable enough to warrant attention but ultimately unhelpful. These become high-tier distractors. Documents the agent never even opened become low-tier distractors. This mirrors real-world information overload: some noise is obviously irrelevant, but the dangerous noise looks relevant until you read it carefully.
-
Rubric Reward: Traditional RL for reasoning gives a reward of 1 for correct answers and 0 for wrong ones. But two correct answers can differ vastly in quality. Imagine a student solving “If x + 2 = 5, what is 2x?” Student A writes: “x = 3, so 2x = 6.” Student B writes: “The answer is 6.” Both are correct, but only A showed their reasoning. Rubric rewards formalize this by checking if the response mentions intermediate entities in the reasoning chain. For a question requiring “Paris → France → Europe,” a response mentioning all three scores higher than one jumping straight to “Europe.” The key insight: this is applied only to correct responses (positive-only), so the model learns “among correct answers, comprehensive reasoning is better” rather than “just mention entities to get points.”
-
Positive-Only Strategy: Why only reward correct responses? Consider the alternative: if you penalize incorrect responses for missing entities, the model learns a shortcut—just mention all the entities from the question without reasoning. It’s like a student who writes down every formula they know on an exam, hoping one is relevant. By restricting rubric rewards to correct answers, you create a signal that says “you got it right, but *how you got there matters.” Wrong answers get zero regardless of what entities they mention, preventing the model from gaming the system by entity name-dropping.
Framework Shift
Before (RLVR):                          After (LongTraceRL):

Question + Random Distractors           Question + Tiered Distractors
        |                                       |
        v                                       v
    [Doc1: Random]                      [Doc1: Agent read, didn't cite]
    [Doc2: Random]                      [Doc2: Agent never opened]
    [Doc3: Gold]                        [Doc3: Gold]
        |                                       |
        v                                       v
    Model generates answer                  Model generates answer
        |                                       |
        v                                       v
    Reward: 1 if correct, 0 if wrong       Reward: 0 if wrong
                                                    |
                                                    v
                                           If correct: rubric score
                                           based on entity coverage
                                           in reasoning chain

Outcome-only signal                     Process supervision signal
From binary outcome feedback to graded process feedback, the core shift is distinguishing reasoning quality among correct responses rather than treating all correct answers as equally good.
Expert Assessment
Problem choice: This is a real gap. Long-context reasoning is a genuine bottleneck for LLMs, and the observation that existing RLVR methods use weak distractors and sparse rewards is well-founded. The problem sits at the intersection of two active research threads—long-context understanding and process supervision for reasoning—making it timely and well-positioned.
Method maturity: The approach is clever but not groundbreaking. Using search agent trajectories to generate distractors is a smart way to create realistic noise, and rubric rewards are a natural extension of process supervision ideas from math reasoning to multi-hop QA. However, the method is somewhat complex—it requires running a search agent, extracting entities, and carefully designing the positive-only strategy. A simpler baseline would be to just use BM25 or dense retrieval to find confusable documents, which the paper doesn’t compare against. The positive-only strategy feels like a patch to prevent reward hacking rather than a principled design.
Experimental integrity: The experiments are solid. Testing on five benchmarks (HotpotQA, MuSiQue, 2WikiMQA, Bamboogle, NarrativeQA) with three model sizes (4B, 8B, 30B) shows thoroughness. The baselines are reasonable—SFT, DPO, and prior RLVR methods. However, the paper doesn’t ablate the tiered distractor construction deeply enough. What if you just used the agent’s cited documents as gold and randomly sampled the rest? How much does the two-tier structure actually matter? The rubric reward ablation is there (Table 3), but the distractor ablation is missing.
Writing quality: The paper is well-structured but dense. The method section tries to explain too much at once—data construction, search agent design, distractor tiers, rubric rewards, and positive-only strategy all in a few pages. A clearer separation between “what we build” (data) and “how we train” (rewards) would help. The related work section is thorough but could be trimmed. The biggest missed opportunity: no failure analysis. When does LongTraceRL still fail? What types of reasoning chains are hard even with rubric rewards?
Verdict: weak accept — Solid contribution with clear improvements over baselines, but the method complexity and missing ablations prevent it from being a strong accept. The core ideas (tiered distractors, rubric rewards) are useful, but the paper doesn’t fully isolate which components drive the gains.
Takeaways
Steal the tiered distractor idea: If you’re building any retrieval or QA system, don’t just randomly sample negatives. Use a search or retrieval agent to find documents that *look relevant but aren’t—these are far better training signals than random noise. The two-tier structure (read-but-not-cited vs never-opened) is a simple way to control difficulty.
Apply rubric rewards beyond QA: The positive-only strategy generalizes. Whenever you have a task with verifiable outcomes and intermediate steps (code generation, proof writing, planning), you can reward correct solutions based on process quality. The key: only grade the process when the outcome is right, to avoid rewarding superficial mimicry.
Beware reward hacking in process supervision: The positive-only strategy exists because naive process rewards are gameable. If you’re designing process rewards, always ask: “Can the model get points by mentioning the right things without actually reasoning?” If yes, restrict rewards to correct outcomes or add adversarial checks.
论文: 2605.31584 作者: Nianyi Lin, Jiajie Zhang, Lei Hou, Juanzi Li 分类: cs.CL, cs.AI, cs.LG
缺口
现有的长文本推理强化学习方法(RLVR)存在两个致命弱点:它们使用随机采样的干扰项,这些干扰项太容易与相关内容区分; 它们只提供稀疏的、基于结果的奖励,无法引导模型完成多步推理链。 模型在最后得到一个二元信号——对或错——但对于它是否提取了正确的证据或遵循了连贯的推理路径,没有任何反馈。 这就像教人解数学题,只告诉他们最终答案对不对,而不检查他们的解题过程。
问题:关键信息被埋在长文本中时推理失败
    |
    v
先前的 RLVR:随机干扰项 + 仅结果奖励
    |
    +---> 弱点1:低混淆度干扰项(太简单)
    +---> 弱点2:没有中间步骤监督
    |
    v
LongTraceRL:搜索轨迹 + 评分标准奖励
    |
    +---> 从代理行为派生的分层干扰项(高混淆度)
    +---> 实体级过程监督(细粒度反馈)
    |
    v
证据:在5个基准、3种模型规模上持续提升
    |
    v
结论:过程监督 + 真实干扰项改善推理
增量
一句话:这篇论文之前,长文本强化学习使用随机干扰项和二元奖励; 之后,我们有了从搜索派生的分层干扰项和监督推理过程的实体级评分标准奖励。
核心机制
LongTraceRL 有两个协同工作的主要组件。 首先,数据构建流程从知识图谱生成多跳问题,并利用搜索代理创建分层干扰项。 代理执行迭代搜索——阅读文档、决定引用什么、继续搜索直到回答问题。 代理读过但没有引用的文档成为高混淆度干扰项(它们看起来相关但没用)。 出现在搜索结果中但从未被打开的文档成为低混淆度干扰项(它们明显不相关)。 这创建了比随机采样困难得多的训练上下文。
其次,奖励机制提供评分标准奖励,根据响应是否提及推理链上的黄金实体来评分。 对于需要实体 E1 → E2 → E3 的多跳问题,提及全部三个实体的响应比只提及 E1 和 E3 的响应得分更高,即使两者都得到了正确的最终答案。 关键是,这个评分标准奖励只应用于正确的响应(仅正例策略),区分高质量推理和幸运猜测,同时避免奖励黑客攻击——模型学会提及实体而不实际推理。
数据构建:
知识图谱 --[随机游走]--> 多跳问题
        |
        v
搜索代理轨迹:
[查询] --> [结果] --> [读文档1、文档2...] --> [引用文档1] --> [答案]
        |           |                    |
        v           v                    v
    从未打开    读过但未引用          实际引用
        |           |                    |
        v           v                    v
    低混淆度    高混淆度              黄金文档
    干扰项      干扰项                (真值)

奖励计算(仅针对正确答案):
响应文本 --[实体抽取]--> 提及的实体
        |
        v
与黄金链比较:E1 -> E2 -> E3
        |
        v
评分标准分数:(提及数量)/(链中总数)
把这想象成训练侦探。 不是只告诉他们”你抓错嫌疑人了”(仅结果奖励),而是向他们展示其他侦探追踪死胡同线索(高混淆度干扰项)和无关噪音(低混淆度干扰项)的案卷。 然后,当他们正确破案时,你根据他们是否记录了链条中的每个关键证据来给报告评分(评分标准奖励)。 靠运气找到正确答案的侦探得分低于有条不紊地追踪每条线索的侦探。 “仅正例”策略意味着你只给成功的案件评分——你不会通过检查失败的尝试是否提及了正确的证据来惩罚它们,因为那会教他们只是提及实体名称而不推理。
关键概念
-
分层干扰项:并非所有不相关的文档都同样具有干扰性。 当回答”谁导演了《教父》? “时,一篇关于”Python 编程”的文档很容易忽略。 但一篇关于”弗朗西斯·福特·科波拉早期戏剧生涯”的文档很难忽略——它在主题上相关但不包含答案。 LongTraceRL 通过记录搜索代理几乎使用的内容来创建第二种类型。 如果代理读了一篇文档但决定不引用它,那篇文档就足够混淆以引起注意,但最终没有帮助。 这些成为高层干扰项。 代理从未打开的文档成为低层干扰项。 这反映了现实世界的信息过载:有些噪音明显不相关,但危险的噪音看起来相关,直到你仔细阅读。
-
评分标准奖励:传统的推理强化学习对正确答案给予奖励 1,对错误答案给予 0。 但两个正确答案的质量可能大不相同。 想象一个学生解”如果 x + 2 = 5,那么 2x 是多少? “学生 A 写:“x = 3,所以 2x = 6。 “学生 B 写:“答案是 6。 “两者都正确,但只有 A 展示了推理。 评分标准奖励通过检查响应是否提及推理链中的中间实体来形式化这一点。 对于需要”巴黎 → 法国 → 欧洲”的问题,提及全部三个的响应比直接跳到”欧洲”的响应得分更高。 关键洞察:这只应用于正确的响应(仅正例),因此模型学习”在正确答案中,全面推理更好”,而不是”只要提及实体就能得分”。
-
仅正例策略:为什么只奖励正确的响应? 考虑另一种选择:如果你因为缺少实体而惩罚错误的响应,模型会学到一个捷径——只提及问题中的所有实体而不推理。 这就像学生在考试中写下他们知道的每个公式,希望有一个相关。 通过将评分标准奖励限制在正确答案上,你创建了一个信号,说”你答对了,但如何答对的很重要”。 错误答案无论提及什么实体都得零分,防止模型通过提及实体名称来玩弄系统。
框架转变
之前(RLVR):                          之后(LongTraceRL):

问题 + 随机干扰项                       问题 + 分层干扰项
        |                                       |
        v                                       v
    [文档1:随机]                       [文档1:代理读过,未引用]
    [文档2:随机]                       [文档2:代理从未打开]
    [文档3:黄金]                       [文档3:黄金]
        |                                       |
        v                                       v
    模型生成答案                            模型生成答案
        |                                       |
        v                                       v
    奖励:正确1,错误0                      奖励:错误0
                                                    |
                                                    v
                                           如果正确:基于推理链中
                                           实体覆盖率的评分标准分数

仅结果信号                              过程监督信号
从二元结果反馈到分级过程反馈,核心转变是区分正确响应中的推理质量,而不是将所有正确答案视为同样好。
专家评审
选题眼光:这是一个真实的缺口。 长文本推理是大模型的真正瓶颈,现有 RLVR 方法使用弱干扰项和稀疏奖励的观察是有根据的。 这个问题位于两个活跃研究线索的交叉点——长文本理解和推理的过程监督——使其及时且定位良好。
方法成熟度:这个方法巧妙但不算突破性。 使用搜索代理轨迹生成干扰项是创建真实噪音的聪明方法,评分标准奖励是将数学推理的过程监督思想自然扩展到多跳问答。 然而,方法有些复杂——它需要运行搜索代理、提取实体并仔细设计仅正例策略。 一个更简单的基线是使用 BM25 或密集检索来找到混淆文档,论文没有与之比较。 仅正例策略感觉像是防止奖励黑客攻击的补丁,而不是原则性设计。
实验诚意:实验是扎实的。 在五个基准(HotpotQA、MuSiQue、2WikiMQA、Bamboogle、NarrativeQA)上用三种模型规模(4B、8B、30B)测试显示了彻底性。 基线是合理的——SFT、DPO 和先前的 RLVR 方法。 然而,论文没有充分消融分层干扰项构建。 如果你只使用代理引用的文档作为黄金并随机采样其余的会怎样? 两层结构实际上有多重要? 评分标准奖励消融在那里(表3),但干扰项消融缺失。
写作功力:论文结构良好但密集。 方法部分试图一次解释太多——数据构建、搜索代理设计、干扰项层级、评分标准奖励和仅正例策略都在几页内。 在”我们构建什么”(数据)和”我们如何训练”(奖励)之间更清晰的分离会有帮助。 相关工作部分很彻底但可以精简。 最大的错失机会:没有失败分析。 LongTraceRL 什么时候仍然失败? 即使有评分标准奖励,什么类型的推理链仍然困难?
判决:弱接收 — 扎实的贡献,相比基线有明确改进,但方法复杂性和缺失的消融实验阻止它成为强接收。 核心思想(分层干扰项、评分标准奖励)是有用的,但论文没有完全隔离哪些组件驱动了收益。
要点总结
偷走分层干扰项思想:如果你在构建任何检索或问答系统,不要只是随机采样负例。 使用搜索或检索代理找到看起来相关但不相关的文档——这些是比随机噪音好得多的训练信号。 两层结构(读过但未引用 vs 从未打开)是控制难度的简单方法。
将评分标准奖励应用到问答之外:仅正例策略是可泛化的。 每当你有一个具有可验证结果和中间步骤的任务(代码生成、证明写作、规划)时,你可以根据过程质量奖励正确的解决方案。 关键:只在结果正确时给过程评分,以避免奖励表面模仿。
警惕过程监督中的奖励黑客攻击:仅正例策略的存在是因为朴素的过程奖励是可玩弄的。 如果你在设计过程奖励,总是问:“模型能否通过提及正确的东西而不实际推理来得分? “如果是,将奖励限制在正确结果上或添加对抗性检查。