Paper: 2605.12493 Authors: Di Wu, Zixiang Ji, Asmi Kawatkar, Bryan Kwan, Jia-Chen Gu, Nanyun Peng, Kai-Wei Chang Categories: cs.CL
The Gap
Existing agent memory benchmarks focus on user preferences, short interaction traces, or downstream task success metrics. They don’t directly test whether memory systems help agents internalize environment-specific knowledge—the kind of tacit expertise a human colleague builds after months of working with a particular system. You know: which buttons are buggy, which workflows are reliable, what state transitions to expect.
The gap is evaluation methodology. We have memory systems, but no way to measure if they’re actually capturing the right kind of experience.
Problem: How do we know if memory helps agents become "experienced"?
   |
   v
Assumption: Experience = answering questions about environment internals
   |
   v
Method: Curate 451 questions across 5 memory abilities + long histories
   |
   v
Evidence: RAG gets 48.5%, coding agent gets 72.5% (with high latency)
   |
   v
Conclusion: Benchmark is hard; coding agents work but are slow
The Increment
One sentence: Before this paper, we evaluated memory by task success; after, we can directly test whether agents remember environment-specific gotchas, workflows, and state dynamics.
Core Mechanism
LongMemEval-V2 uses a context gathering formulation. The memory system consumes up to 500 trajectories (115M tokens of interaction history) and returns compact evidence snippets. A downstream QA model uses these snippets to answer questions about the environment.
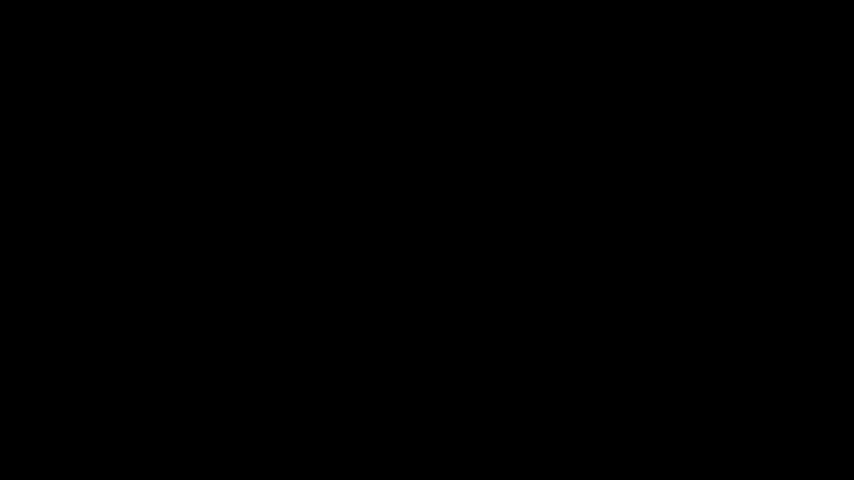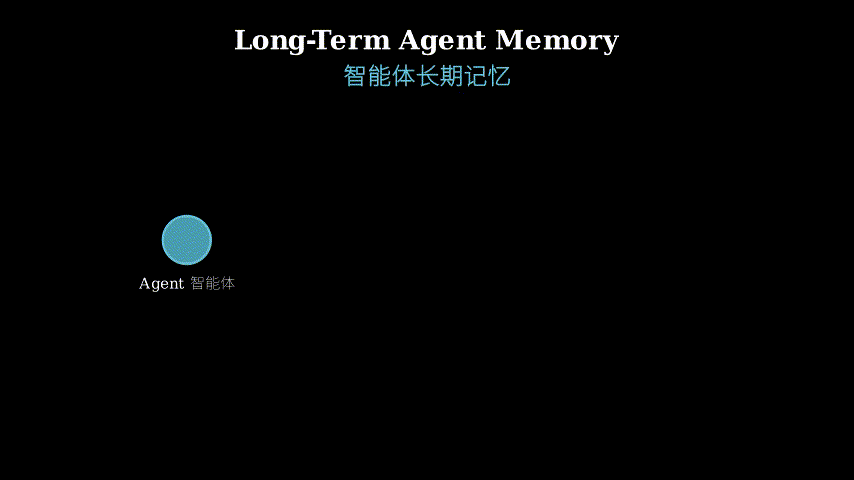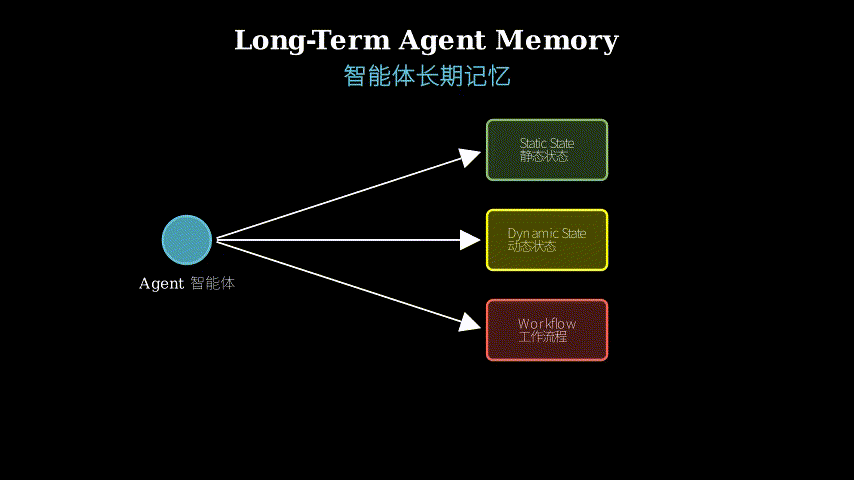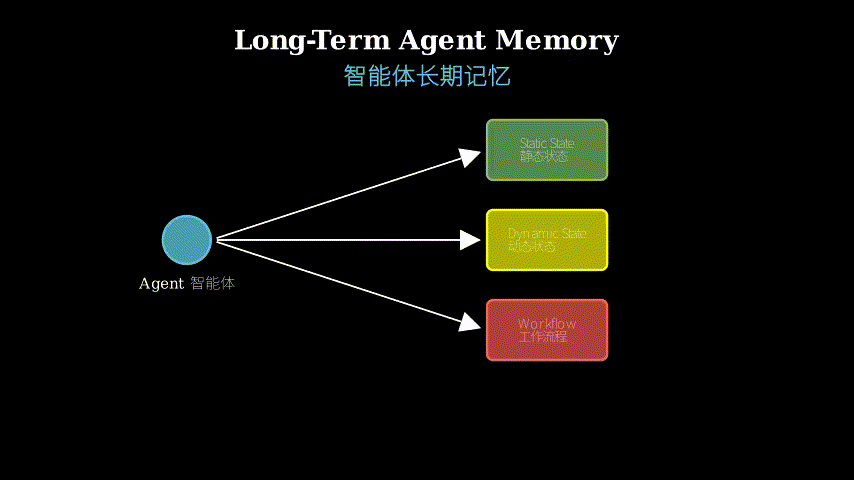
The benchmark tests five memory abilities: static state recall (what’s on the page?), dynamic state tracking (how did this element change?), workflow knowledge (what’s the standard procedure?), environment gotchas (what breaks and why?), and premise awareness (what assumptions does this task make?).
Two proposed methods: AgentRunbook-R is a RAG system with three knowledge pools—raw observations, extracted events, and strategy notes. AgentRunbook-C stores trajectories as files and invokes a coding agent in a sandbox to write Python scripts that gather evidence by parsing trajectory data.
History Trajectories (up to 500, 115M tokens)
   |
   v
Memory System (RAG or Coding Agent)
   |
   v
Compact Evidence Snippets
   |
   v
QA Model --> Answer
   |
   v
Evaluation: 5 memory abilities x 451 questions
Think of it like training a new hire. The trajectories are the new hire shadowing experienced colleagues for months. The memory system is their note-taking strategy—either organized binders (RAG with knowledge pools) or a personal assistant who can search through all their notes and write custom reports (coding agent). The questions are the pop quiz: “Hey, remember that bug with the submit button? What causes it?” A good memory system means the new hire can answer without re-reading all their notes.
The coding agent approach works because it can write custom parsing logic for each question—like having a research assistant who knows Python. The RAG approach is faster but less flexible—like having pre-indexed flashcards that might not have the exact angle you need.
Key Concepts
-
Context gathering formulation: Instead of evaluating memory by whether the agent completes tasks successfully, you evaluate it by whether the memory system can retrieve relevant evidence from long histories. It’s like testing a librarian’s filing system by asking them to find specific passages, not by checking if patrons leave satisfied. This decouples memory quality from task execution, letting you diagnose what the memory system actually learned.
-
Environment gotchas: These are recurring failure modes specific to a system—the kind of knowledge you only get from experience. For example: “The search button doesn’t work if you type too fast” or “Clicking ‘Save’ twice creates duplicate entries.” Existing benchmarks don’t test this because they focus on user preferences or general knowledge. But this is exactly what makes an experienced colleague valuable—they know where the landmines are.
-
Knowledge pools in RAG: AgentRunbook-R doesn’t just dump everything into one vector database. It maintains three separate pools: raw state observations (what’s literally on screen), events (state transitions and actions), and strategy notes (high-level patterns). This is like organizing a filing cabinet by document type instead of throwing everything in one drawer. When you search, you can target the right pool for the question type.
Framework Shift
Before (mainstream approach):        After (this paper):

Agent --> Task Success               History --> Memory System
  ^           |                        |            |
  |           v                        v            v
Memory    Evaluation                Evidence --> QA --> Eval
(implicit)                          (explicit test of memory)

Focus: Did the agent win?            Focus: What did the agent learn?
From outcome-based to knowledge-based evaluation, the core shift is making memory testable as a first-class capability.
Expert Assessment
Problem choice: This is a real gap. The field has been building memory systems without direct ways to measure what they remember. The focus on environment-specific experience (not user preferences) is smart—it targets the kind of knowledge that’s hardest to acquire and most valuable in specialized domains.
Method maturity: The benchmark design is solid—manually curated questions, diverse memory abilities, realistic history lengths. The two proposed methods are reasonable baselines but not groundbreaking. AgentRunbook-C is essentially “let an LLM write code to parse trajectories,” which is powerful but not novel. The RAG baseline with knowledge pools is sensible but incremental. The paper’s value is the benchmark, not the methods.
Experimental integrity: Baselines are fair. The 72.5% vs 48.5% gap between coding agent and RAG is convincing, but the latency cost (not quantified in the abstract) is a major caveat. The paper acknowledges this honestly. One concern: 451 questions is decent but not huge—there’s risk of overfitting to question types. Would like to see inter-annotator agreement scores for question quality.
Writing quality: The abstract is clear but undersells the benchmark’s design. The “experienced colleagues” framing is good but could be pushed harder—what does it mean operationally? The methods section likely has the most room for improvement: need clearer ablations on what each knowledge pool contributes in AgentRunbook-R, and more analysis of when coding agents fail.
Verdict: weak accept — Solid benchmark contribution with honest evaluation, but the proposed methods are incremental and the dataset size is moderate. The field needs this benchmark, but the paper doesn’t push the solution space hard enough.
Takeaways
Steal the evaluation formulation: Context gathering (memory system returns evidence, separate QA model answers) is a clean way to test retrieval quality without confounding factors. You can apply this to any domain where you want to test if a system “learned” from experience—not just agents, but also recommendation systems, debugging assistants, or code review tools.
Steal the knowledge pool architecture: Separating raw observations, events, and strategy notes in RAG is simple but effective. If you’re building a memory system, don’t dump everything into one vector store—organize by information type and query the right pool.
Steal the “gotchas” category: Testing whether a system remembers recurring failure modes is underrated. If you’re evaluating any learning system in a specialized domain, add questions about edge cases and failure patterns—that’s where experience shows.
Don’t steal the coding agent approach blindly: It works but has high latency. Only use it if accuracy matters more than speed, or if you can cache/precompute evidence for common question types.
论文: 2605.12493 作者: Di Wu, Zixiang Ji, Asmi Kawatkar, Bryan Kwan, Jia-Chen Gu, Nanyun Peng, Kai-Wei Chang 分类: cs.CL
缺口
现有的智能体记忆基准主要关注用户偏好、短交互轨迹或下游任务成功率。
它们不直接测试记忆系统是否帮助智能体内化环境特定知识——那种人类同事在特定系统工作几个月后积累的隐性专业知识。
你懂的:哪些按钮有bug、哪些工作流可靠、该期待什么状态转换。
缺口在于评估方法论。
我们有记忆系统,但没法衡量它们是否真的捕获了正确类型的经验。
问题:如何知道记忆是否帮助智能体变得"有经验"?
   |
   v
假设:经验 = 回答关于环境内部的问题
   |
   v
方法:策划451个问题覆盖5种记忆能力 + 长历史
   |
   v
证据:RAG得48.5%,编码智能体得72.5%(但延迟高)
   |
   v
结论:基准很难;编码智能体有效但慢
增量
一句话:这篇论文之前,我们通过任务成功率评估记忆;之后,我们可以直接测试智能体是否记住了环境特定的陷阱、工作流和状态动态。
核心机制
LongMemEval-V2使用上下文收集范式。
记忆系统消费多达500条轨迹(1.15亿token的交互历史),返回紧凑的证据片段。
下游QA模型用这些片段回答关于环境的问题。
基准测试五种记忆能力:静态状态回忆(页面上有什么? )、动态状态跟踪(这个元素如何变化? )、工作流知识(标准流程是什么? )、环境陷阱(什么会出错以及为什么? )、前提意识(这个任务假设了什么? )。
两种提出的方法:AgentRunbook-R是一个RAG系统,有三个知识池——原始观察、提取的事件和策略笔记。
AgentRunbook-C将轨迹存储为文件,在沙箱中调用编码智能体编写Python脚本,通过解析轨迹数据收集证据。
历史轨迹(多达500条,1.15亿token)
   |
   v
记忆系统(RAG或编码智能体)
   |
   v
紧凑证据片段
   |
   v
QA模型 --> 答案
   |
   v
评估:5种记忆能力 x 451个问题
把它想象成培训新员工。
轨迹是新员工跟着资深同事见习几个月。
记忆系统是他们的笔记策略——要么是有组织的活页夹(带知识池的RAG),要么是能搜索所有笔记并写定制报告的私人助理(编码智能体)。
问题是突击测验:“嘿,还记得提交按钮的那个bug吗? 什么导致的? “好的记忆系统意味着新员工能回答,而不用重读所有笔记。
编码智能体方法有效是因为它能为每个问题写定制解析逻辑——就像有个懂Python的研究助理。
RAG方法更快但不够灵活——就像有预先索引的抽认卡,可能没有你需要的确切角度。
关键概念
- 上下文收集范式:不通过智能体是否成功完成任务来评估记忆,而是通过记忆系统能否从长历史中检索相关证据来评估。
就像测试图书管理员的归档系统是让他们找特定段落,而不是检查读者是否满意离开。
这将记忆质量与任务执行解耦,让你诊断记忆系统实际学到了什么。
- 环境陷阱:这些是系统特定的反复出现的失败模式——只有通过经验才能获得的知识。
例如:“如果你打字太快,搜索按钮就不工作”或”点击两次’保存’会创建重复条目”。
现有基准不测试这个,因为它们关注用户偏好或通用知识。
但这正是资深同事有价值的地方——他们知道雷区在哪里。
- RAG中的知识池:AgentRunbook-R不是把所有东西都扔进一个向量数据库。
它维护三个独立的池:原始状态观察(屏幕上字面显示的内容)、事件(状态转换和动作)、策略笔记(高层模式)。
这就像按文档类型组织文件柜,而不是把所有东西扔进一个抽屉。
搜索时,你可以针对问题类型定位正确的池。
框架转变
之前(主流方法):                之后(本文方法):

智能体 --> 任务成功               历史 --> 记忆系统
  ^           |                     |         |
  |           v                     v         v
记忆      评估                   证据 --> QA --> 评估
(隐式)                          (显式测试记忆)

焦点:智能体赢了吗?              焦点:智能体学到了什么?
从基于结果到基于知识的评估,核心转变是让记忆作为一等能力可测试。
专家评审
选题眼光:这是真缺口。
该领域一直在构建记忆系统,却没有直接方法衡量它们记住了什么。
关注环境特定经验(而非用户偏好)很聪明——它针对最难获取且在专业领域最有价值的知识类型。
方法成熟度:基准设计扎实——人工策划的问题、多样的记忆能力、现实的历史长度。
两种提出的方法是合理的基线,但不算突破。
AgentRunbook-C本质上是”让LLM写代码解析轨迹”,强大但不新颖。
带知识池的RAG基线合理但渐进。
论文的价值在基准,不在方法。
实验诚意:基线公平。
编码智能体72.5%对RAG 48.5%的差距有说服力,但延迟成本(摘要中未量化)是重大警告。
论文诚实承认了这点。
一个担忧:451个问题还行但不算大——有过拟合到问题类型的风险。
希望看到问题质量的标注者间一致性分数。
写作功力:摘要清晰但低估了基准的设计。
“资深同事”的框架不错但可以推得更深——操作上意味着什么? 方法部分可能最有改进空间:需要更清晰的消融实验说明AgentRunbook-R中每个知识池的贡献,以及更多关于编码智能体何时失败的分析。
判决:弱接收 — 扎实的基准贡献和诚实的评估,但提出的方法是渐进的,数据集规模适中。
该领域需要这个基准,但论文没有足够努力推动解决方案空间。
要点总结
偷评估范式:上下文收集(记忆系统返回证据,独立的QA模型回答)是测试检索质量的干净方法,没有混淆因素。
你可以将其应用到任何想测试系统是否从经验中”学习”的领域——不仅是智能体,还有推荐系统、调试助手或代码审查工具。
偷知识池架构:在RAG中分离原始观察、事件和策略笔记简单但有效。
如果你在构建记忆系统,不要把所有东西都扔进一个向量存储——按信息类型组织,查询正确的池。
偷”陷阱”类别:测试系统是否记住反复出现的失败模式被低估了。
如果你在专业领域评估任何学习系统,添加关于边缘情况和失败模式的问题——那是经验显现的地方。
不要盲目偷编码智能体方法:它有效但延迟高。
只在准确性比速度更重要时使用,或者如果你能为常见问题类型缓存/预计算证据。