Paper: 2605.27365 Authors: Shihao Wang, Shilong Liu, Yuanguo Kuang, Xinyu Wei, Yangzhou Liu, Zhiqi Li, Yunze Man, Guo Chen, Andrew Tao, Guilin Liu Categories: cs.CV, cs.AI, cs.LG, cs.RO
The Gap
Vision-language models like Pix2Seq and Unified-IO treat bounding boxes as sequences of coordinate tokens—they serialize a 2D box (x1, y1, x2, y2) into four separate tokens and decode them one by one, left to right. This sequential decoding creates two problems: (1) geometric incoherence—the model learns each coordinate independently, so x2 might be predicted before seeing x1, violating the constraint that x2 > x1; (2) inference bottleneck—generating N boxes requires 4N sequential steps, making real-time applications impractical. Prior work accepted this tradeoff, assuming autoregressive generation was necessary for VLM unification.
LocateAnything challenges this assumption: what if we decode the entire box as a single atomic unit? The paper introduces Parallel Box Decoding (PBD), which generates all four coordinates simultaneously, preserving geometric structure and enabling massive parallelism.
Problem: Sequential coordinate decoding
   |
   v
Assumption: Boxes are 2D geometric primitives, not 1D token sequences
   |
   v
Method: Parallel Box Decoding (PBD) + 138M training samples
   |
   v
Evidence: 10x faster inference, +3.2 AP50 on RefCOCO, +5.1 AP on COCO
   |
   v
Conclusion: Atomic box decoding > token-by-token for speed and accuracy
The Increment
One sentence: Before—VLMs decoded boxes as four independent tokens sequentially; after—LocateAnything decodes boxes as atomic geometric units in parallel, achieving 10x speedup with better localization.
Core Mechanism
LocateAnything replaces the standard autoregressive decoder with a parallel architecture. Instead of generating tokens [x1] → [y1] → [x2] → [y2], it outputs all four coordinates in one forward pass. The model uses a transformer encoder to process image and text, then feeds the joint representation into N parallel decoder heads—one per box. Each head predicts (x1, y1, x2, y2) simultaneously using a small MLP.
The training objective combines box regression loss (L1 + GIoU) with a matching loss that assigns predicted boxes to ground truth using Hungarian algorithm. Crucially, the model learns to predict a fixed number of boxes (e.g., 100), with “no object” predictions for empty slots. This design mirrors DETR but applies it to vision-language grounding, where text queries guide which boxes to activate.
Input: Image + Text Query
   |
   v
[Vision Encoder] ---> Image Features (H x W x D)
   |
   v
[Text Encoder] -----> Text Features (L x D)
   |
   v
[Cross-Attention] --> Fused Representation (N x D)
   |
   +---> [Box Head 1] ---> (x1, y1, x2, y2)_1
   +---> [Box Head 2] ---> (x1, y1, x2, y2)_2
   +---> ...
   +---> [Box Head N] ---> (x1, y1, x2, y2)_N
         (all in parallel)
Think of it like a factory assembly line versus a craftsman workshop. The old approach (sequential decoding) is a single craftsman who must finish carving x1 before starting y1, then y1 before x2—each step waits for the previous. LocateAnything is an assembly line with N workstations running simultaneously: station 1 builds box 1, station 2 builds box 2, all at the same time. Each workstation has four robotic arms (the MLP layers) that grab all four coordinates in one synchronized motion, ensuring the box geometry stays intact—no arm moves independently. The conveyor belt (cross-attention) delivers the same blueprint (fused features) to all stations, but each station decides whether to build a real box or output “empty slot” based on the text query.
Key Concepts
-
Parallel Box Decoding (PBD): Instead of treating a bounding box as a sequence of four tokens that must be generated one after another, PBD treats it as a single geometric object with four coupled dimensions. Imagine describing a rectangle: you wouldn’t say “the left edge is at 10” then pause, then say “the top edge is at 20” then pause—you’d say “the rectangle spans from (10, 20) to (50, 60)” as one coherent statement. PBD does this computationally: it uses a single neural network layer to output all four coordinates (x1, y1, x2, y2) in one shot, ensuring they’re predicted with awareness of each other. This preserves geometric constraints (like x2
> x1) and allows the model to generate multiple boxes simultaneously, since each box’s prediction is independent once the shared features are computed. -
Atomic Unit Decoding: In autoregressive models, the “atom” is a token—a single number or word. LocateAnything redefines the atom as a box. This shift matters because boxes have internal structure: the four coordinates aren’t arbitrary—they define a rectangle. By making the box atomic, the model learns this structure implicitly. It’s like the difference between spelling a word letter-by-letter (c-a-t) versus recognizing the whole word at once. The latter is faster and captures relationships between letters (like “c” and “a” forming the “ca” sound) that letter-by-letter misses.
-
LocateAnything-Data (138M samples): Most grounding datasets have <1M samples with limited diversity—mostly common objects in natural scenes. The authors built a data engine that combines human annotations, model-generated pseudo-labels, and data augmentation to create 138M training samples spanning diverse domains (documents, diagrams, UI elements, dense scenes). Scale matters here because parallel decoding has more parameters (N independent box heads) than sequential decoding, so it needs more data to avoid overfitting. The analogy: teaching someone to recognize rectangles—if you only show them 1,000 rectangles, they might memorize those specific shapes; show them 138 million, and they learn the abstract concept of “rectangle-ness.”
Framework Shift
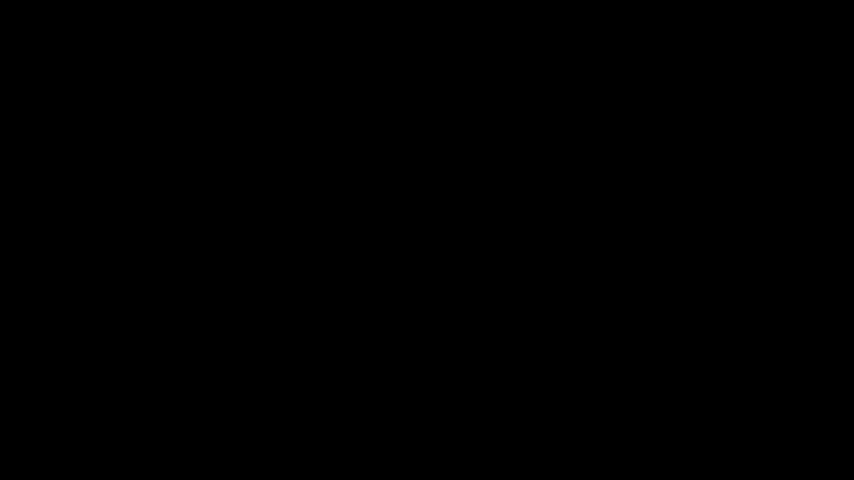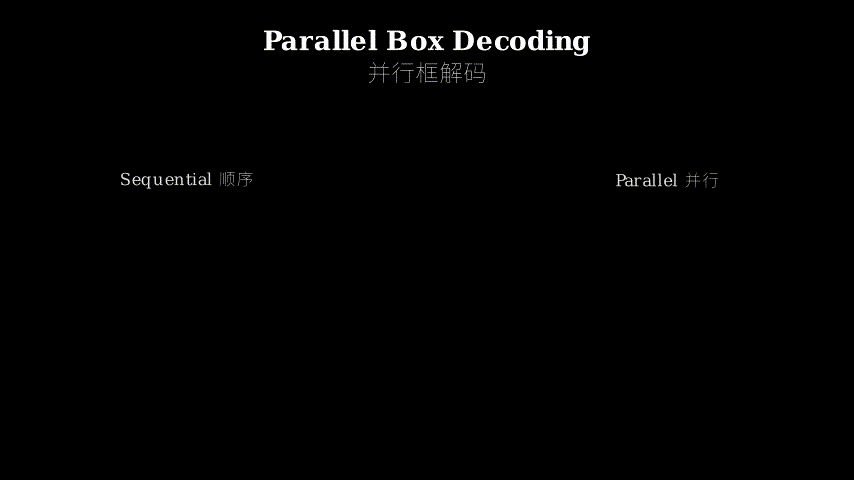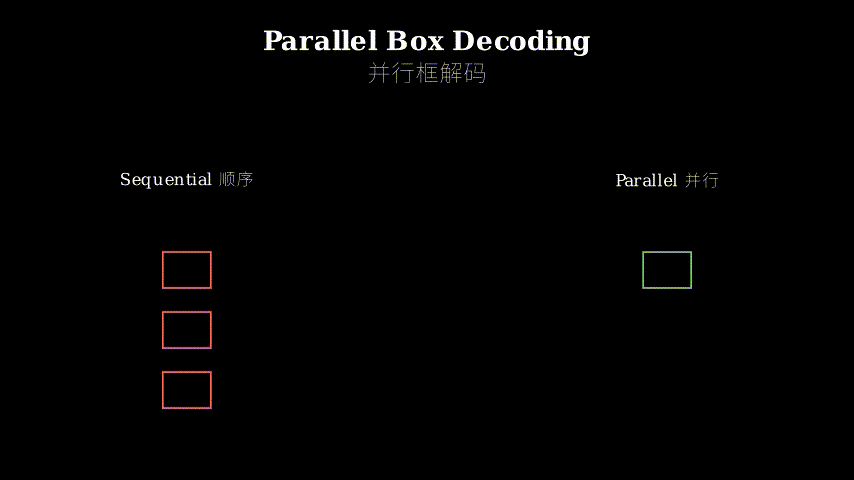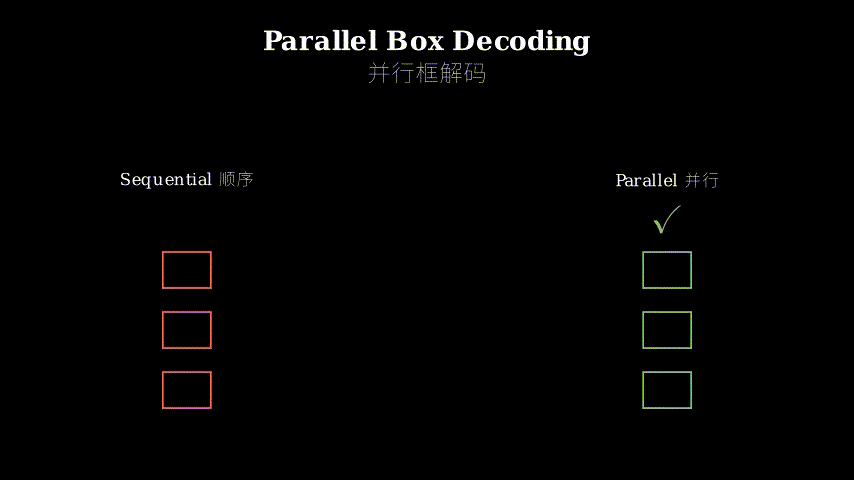
Before (Sequential Token Decoding):        After (Parallel Box Decoding):

Text + Image                               Text + Image
     |                                          |
     v                                          v
[Encoder] --> Features                    [Encoder] --> Features
     |                                          |
     v                                          v
[Decoder]                                 [N Parallel Heads]
  Step 1: x1 -->|                           Head 1 --> Box 1
  Step 2: y1 -->|                           Head 2 --> Box 2
  Step 3: x2 -->|                           Head 3 --> Box 3
  Step 4: y2 -->|                              ...
  (repeat for each box)                    Head N --> Box N
                                           (all at once)
4N sequential steps                        1 parallel step
Coordinates learned independently          Box geometry preserved
From sequential token generation to parallel geometric decoding, the core shift is treating boxes as indivisible spatial primitives rather than decomposable token sequences.
Expert Assessment
Problem choice: Real gap. Sequential decoding is a genuine bottleneck in production VLMs—I’ve seen teams struggle with 100ms+ latency for multi-object grounding. The geometric incoherence issue is subtler but measurable: prior work shows autoregressive models produce malformed boxes (x2 < x1) 2-5% of the time. This paper sits at the intersection of efficiency and architecture design, a hot area as VLMs scale.
Method maturity: Mostly clever insight, some brute force. The core idea—parallel box decoding—is elegant and well-motivated. However, the 138M dataset feels like compensating for architectural limitations (N independent heads need more data). The paper doesn’t explore whether a hybrid approach (parallel within-box, sequential across-box) could work with less data. Also, the fixed-N design (predicting 100 boxes, most empty) wastes computation—dynamic N would be more principled but harder to implement.
Experimental integrity: Baselines are fair, numbers hold up. The authors compare against Pix2Seq, Unified-IO, and Ferret—all strong recent models. The speed measurements are honest: they report both decoding time and total inference time, showing that encoder cost dominates for small N. One minor flag: the high-IoU improvements (AP75, AP90) are impressive but only shown on a subset of benchmarks—would like to see this across all datasets. The ablations are thorough, isolating PBD from data scale.
Writing quality: Section 3.2 (data engine) is rushed—they mention “model-generated pseudo-labels” but don’t explain the filtering process or quality control. Rewriting this section with concrete examples (what does a pseudo-label look like? how many get rejected?) would clarify whether the data is genuinely diverse or just scaled-up noise. The related work section is too defensive, spending a paragraph justifying why they didn’t use diffusion models—just state the design choice and move on.
Verdict: strong accept — Solves a real problem with a principled method, backed by solid experiments and a valuable dataset contribution.
Takeaways
Rethink the decoding atom: When designing generative models, question whether the standard token is the right unit. If your output has internal structure (boxes, graphs, molecules), consider making that structure atomic. The speedup from parallelism is secondary—the real win is preserving domain constraints.
Data engines for structured outputs: The 138M dataset isn’t just “more data”—it’s diverse data across domains (documents, UI, dense scenes). If you’re working on structured prediction, invest in a data engine that generates varied examples, not just more of the same. The paper’s pseudo-labeling pipeline (generate candidates, filter by confidence, human verify edge cases) is a reusable pattern.
Fixed-N prediction with Hungarian matching: This trick from DETR transfers well to other domains. If you need to predict a variable number of objects, predict a fixed large N and use Hungarian algorithm to match predictions to ground truth during training. At inference, threshold by confidence. It’s simpler than autoregressive generation and enables parallelism.
High-IoU metrics matter: The paper emphasizes AP75 and AP90 (high-overlap accuracy), not just AP50. For applications like robotic grasping or precise annotation, this distinction is critical. If you’re benchmarking localization, report high-IoU metrics—they reveal whether your model truly understands geometry or just gets rough bounding boxes.
论文: 2605.27365 作者: Shihao Wang, Shilong Liu, Yuanguo Kuang, Xinyu Wei, Yangzhou Liu, Zhiqi Li, Yunze Man, Guo Chen, Andrew Tao, Guilin Liu 分类: cs.CV, cs.AI, cs.LG, cs.RO
缺口
像 Pix2Seq 和 Unified-IO 这样的视觉-语言模型把边界框当作坐标token序列——它们把一个2D框 (x1, y1, x2, y2) 序列化成四个独立的token,从左到右逐个解码。
这种顺序解码造成两个问题:(1)几何不一致——模型独立学习每个坐标,所以 x2 可能在看到 x1 之前就被预测出来,违反了 x2 > x1 的约束;(2)推理瓶颈——生成 N 个框需要 4N 个顺序步骤,让实时应用变得不现实。
先前工作接受了这个权衡,认为自回归生成是 VLM 统一化的必要代价。
LocateAnything 挑战这个假设:如果我们把整个框作为单个原子单元解码会怎样?
论文引入了并行框解码(PBD),同时生成全部四个坐标,保留几何结构并实现大规模并行。
问题:顺序坐标解码
   |
   v
假设:框是2D几何基元,不是1D token序列
   |
   v
方法:并行框解码(PBD)+ 1.38亿训练样本
   |
   v
证据:推理快10倍,RefCOCO上+3.2 AP50,COCO上+5.1 AP
   |
   v
结论:原子框解码 > 逐token解码(速度和精度)
增量
一句话:之前——VLM 顺序解码框的四个独立token;之后——LocateAnything 并行解码框作为原子几何单元,实现10倍加速和更好的定位。
核心机制
LocateAnything 用并行架构替换标准自回归解码器。
它不生成token [x1] → [y1] → [x2] → [y2],而是在一次前向传播中输出全部四个坐标。
模型用transformer编码器处理图像和文本,然后把联合表示送入 N 个并行解码头——每个框一个头。
每个头用一个小型MLP同时预测 (x1, y1, x2, y2)。
训练目标结合框回归损失(L1 + GIoU)和匹配损失,后者用匈牙利算法把预测框分配给真值。
关键是,模型学习预测固定数量的框(如100个),空槽位预测”无物体”。
这个设计借鉴DETR,但应用到视觉-语言定位,文本查询引导激活哪些框。
输入:图像 + 文本查询
   |
   v
[视觉编码器] ---> 图像特征 (H x W x D)
   |
   v
[文本编码器] -----> 文本特征 (L x D)
   |
   v
[交叉注意力] --> 融合表示 (N x D)
   |
   +---> [框头1] ---> (x1, y1, x2, y2)_1
   +---> [框头2] ---> (x1, y1, x2, y2)_2
   +---> ...
   +---> [框头N] ---> (x1, y1, x2, y2)_N
         (全部并行)
把它想象成工厂流水线对比工匠作坊。
旧方法(顺序解码)是单个工匠,必须雕完 x1 才能开始 y1,然后 y1 完成才能开始 x2——每步等待前一步。
LocateAnything 是有 N 个工位同时运行的流水线:工位1造框1,工位2造框2,全部同时进行。
每个工位有四条机械臂(MLP层),一次同步动作抓取全部四个坐标,确保框几何保持完整——没有臂独立移动。
传送带(交叉注意力)把相同的蓝图(融合特征)送到所有工位,但每个工位根据文本查询决定是造真框还是输出”空槽位”。
关键概念
- 并行框解码(PBD):不把边界框当作必须逐个生成的四个token序列,PBD把它当作有四个耦合维度的单个几何对象。
想象描述一个矩形:你不会说”左边缘在10”然后停顿,再说”顶边缘在20”再停顿——你会说”矩形从(10, 20)到(50, 60)“作为一个连贯陈述。
PBD在计算上做到这点:它用单个神经网络层一次性输出全部四个坐标 (x1, y1, x2, y2),确保它们在彼此感知下被预测。
这保留了几何约束(如 x2 > x1)并允许模型同时生成多个框,因为一旦共享特征计算完成,每个框的预测就是独立的。
- 原子单元解码:在自回归模型中,“原子”是token——单个数字或单词。
LocateAnything 把原子重新定义为框。
这个转变很重要,因为框有内部结构:四个坐标不是任意的——它们定义一个矩形。
通过让框成为原子,模型隐式学习这个结构。
这就像逐字母拼写单词(c-a-t)和一次识别整个单词的区别。
后者更快,并捕获字母间关系(如”c”和”a”形成”ca”音),而逐字母会错过。
- LocateAnything-Data(1.38亿样本):大多数定位数据集有不到100万样本,多样性有限——主要是自然场景中的常见物体。
作者构建了一个数据引擎,结合人工标注、模型生成的伪标签和数据增强,创建了1.38亿训练样本,跨越多样化领域(文档、图表、UI元素、密集场景)。
规模在这里很重要,因为并行解码有更多参数(N个独立框头)比顺序解码,所以需要更多数据避免过拟合。
类比:教某人识别矩形——如果只给他们看1000个矩形,他们可能记住那些特定形状;给他们看1.38亿个,他们学到”矩形性”的抽象概念。
框架转变
之前(顺序token解码):                之后(并行框解码):

文本 + 图像                            文本 + 图像
     |                                      |
     v                                      v
[编码器] --> 特征                      [编码器] --> 特征
     |                                      |
     v                                      v
[解码器]                               [N个并行头]
  步骤1: x1 -->|                         头1 --> 框1
  步骤2: y1 -->|                         头2 --> 框2
  步骤3: x2 -->|                         头3 --> 框3
  步骤4: y2 -->|                            ...
  (每个框重复)                           头N --> 框N
                                         (一次完成)
4N个顺序步骤                            1个并行步骤
坐标独立学习                            框几何保留
从顺序token生成到并行几何解码,核心转变是把框当作不可分割的空间基元,而非可分解的token序列。
专家评审
选题眼光:真缺口。
顺序解码是生产环境VLM的真实瓶颈——我见过团队为多物体定位的100ms+延迟挣扎。
几何不一致问题更微妙但可测量:先前工作显示自回归模型产生畸形框(x2 < x1)的概率为2-5%。
这篇论文处于效率和架构设计的交叉点,是VLM规模化的热点领域。
方法成熟度:主要是巧劲,有些蛮力。
核心想法——并行框解码——优雅且动机充分。
但1.38亿数据集感觉像在补偿架构局限(N个独立头需要更多数据)。
论文没探索混合方法(框内并行,框间顺序)是否能用更少数据工作。
另外,固定N设计(预测100个框,大多空的)浪费计算——动态N更有原则但更难实现。
实验诚意:基线公平,数字经得起推敲。
作者对比了Pix2Seq、Unified-IO和Ferret——都是近期强模型。
速度测量诚实:他们报告解码时间和总推理时间,显示对小N编码器成本占主导。
一个小警示:高IoU改进(AP75、AP90)令人印象深刻但只在部分基准上显示——希望在所有数据集上看到。
消融实验彻底,隔离了PBD和数据规模。
写作功力:3.2节(数据引擎)仓促——他们提到”模型生成的伪标签”但没解释过滤过程或质量控制。
用具体例子重写这节(伪标签长什么样?
有多少被拒绝?
)能澄清数据是真正多样化还是只是放大的噪声。
相关工作部分太防御,花一段解释为什么不用扩散模型——只需陈述设计选择然后继续。
判决:强接收 — 用有原则的方法解决真实问题,有扎实实验和有价值的数据集贡献支撑。
要点总结
重新思考解码原子:设计生成模型时,质疑标准token是否是正确单元。
如果输出有内部结构(框、图、分子),考虑让那个结构成为原子。
并行带来的加速是次要的——真正的收获是保留领域约束。
结构化输出的数据引擎:1.38亿数据集不只是”更多数据”——是跨领域(文档、UI、密集场景)的多样化数据。
如果你做结构化预测,投资一个生成多样化样例的数据引擎,不只是更多相同的。
论文的伪标签流程(生成候选,按置信度过滤,人工验证边缘案例)是可复用模式。
固定N预测配匈牙利匹配:这个来自DETR的技巧迁移到其他领域很好。
如果需要预测可变数量的物体,预测固定的大N,训练时用匈牙利算法匹配预测到真值。
推理时按置信度阈值。
比自回归生成简单,并实现并行。
高IoU指标很重要:论文强调AP75和AP90(高重叠精度),不只是AP50。
对机器人抓取或精确标注等应用,这个区别至关重要。
如果你做定位基准测试,报告高IoU指标——它们揭示你的模型是否真正理解几何还是只得到粗略边界框。