Paper: 2604.11789 Authors: Yuqian Yuan, Wenqiao Zhang, Juekai Lin, Yu Zhong, Mingjian Gao, Binhe Yu, Yunqi Cao, Wentong Li, Yueting Zhuang, Beng Chin Ooi Categories: cs.CV
The Gap
Large Multimodal Models (LMMs) like GPT-4V and Gemini excel at describing entire scenes but stumble when you ask “which red car?” or “move that specific lamp slightly left.” They understand globally but lack object-level precision. Prior work splits into two camps: (1) LMMs that reason holistically but can’t ground specific instances, and (2) specialized vision models (SAM, ControlNet) that manipulate precisely but lack semantic understanding. The gap: no unified framework bridges semantic reasoning with pixel-accurate object control.
Problem: LMMs can't handle object-level tasks
   |
   v
Assumption: Explicit object representations enable precise control
   |
   v
Method: Survey object-centric approaches across 4 task families
   |
   v
Evidence: Taxonomy of techniques + identification of open challenges
   |
   v
Conclusion: Object-centricity is the missing link for controllable multimodal AI
The Increment
One sentence: Before this paper, LMMs operated at scene-level; after, we have a structured map showing how object-centric representations enable instance-level understanding, segmentation, editing, and generation.
Core Mechanism
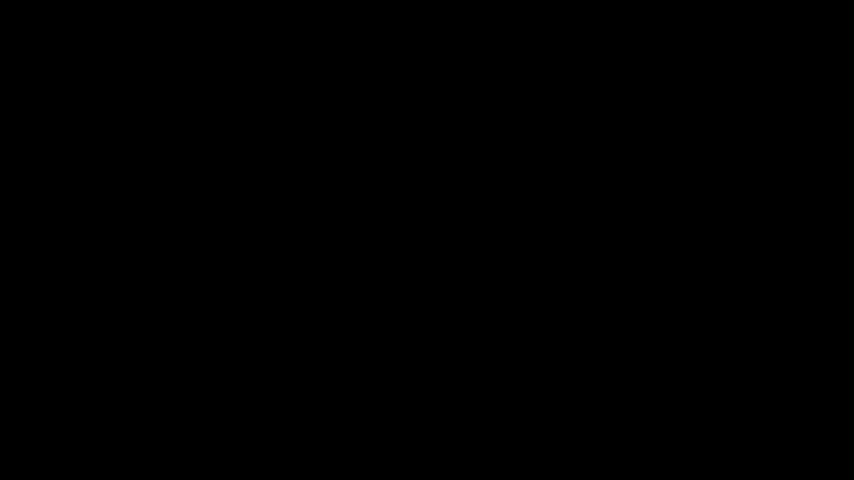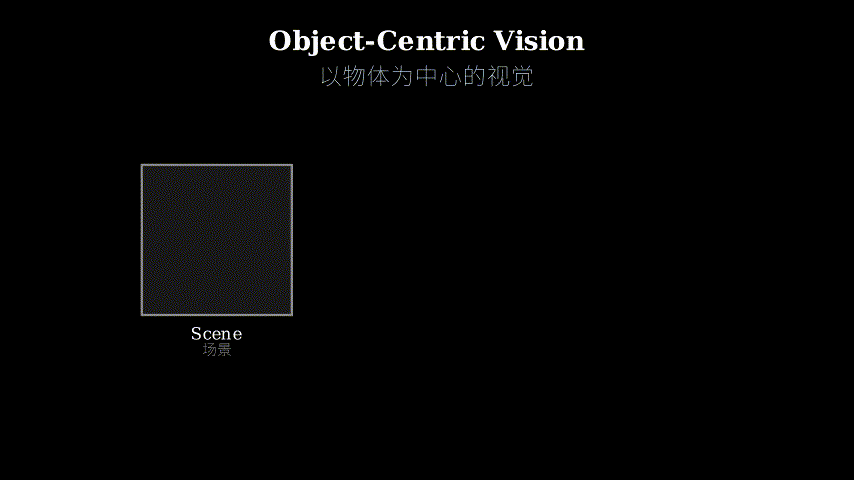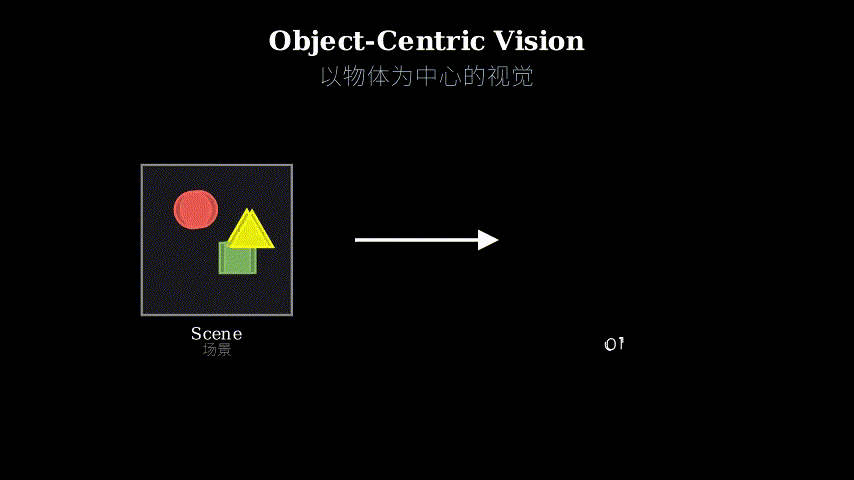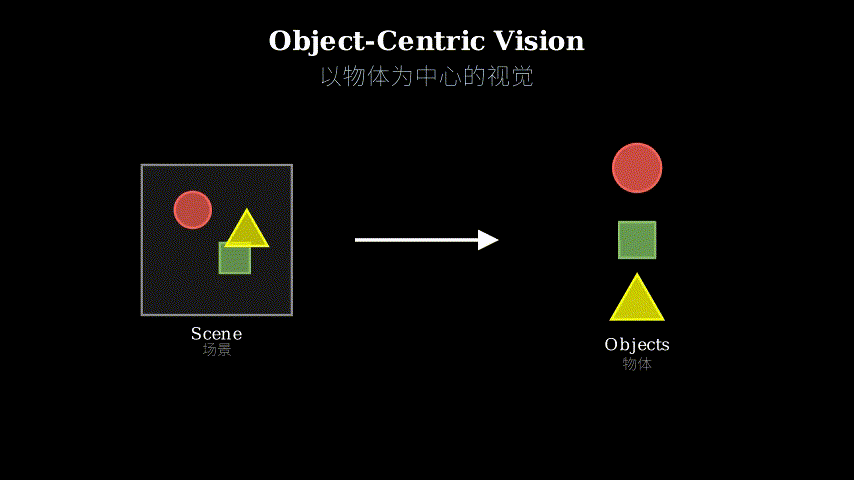
This is a survey paper, not a single method. It organizes the landscape into four pillars: (1) Object-centric understanding — models that parse scenes into discrete entities with attributes, (2) Referring segmentation — grounding language to pixel masks of specific instances, (3) Visual editing — modifying designated objects while preserving context, (4) Visual generation — synthesizing images with controllable object placement and appearance.
The paper identifies three recurring design patterns: explicit object tokens (treating each instance as a discrete symbol in the model’s representation), spatial grounding modules (mechanisms that map language to image coordinates), and identity-preserving mechanisms (ensuring the same object maintains consistent appearance across operations). Data flows from raw images through object detection/segmentation, into multimodal encoders that fuse visual and language features, then to task-specific decoders that output masks, edits, or generated pixels.
Input Image + Text Query
        |
        v
   [Object Detection/Segmentation]
        |
        v
   [Multimodal Encoder]
    (fuses vision + language)
        |
        +---> Understanding: attribute extraction
        |
        +---> Segmentation: instance masks
        |
        +---> Editing: localized modifications
        |
        +---> Generation: controllable synthesis
Think of it like a restaurant kitchen. Traditional LMMs are like a chef who describes the entire dish beautifully but can’t tell you which specific carrot needs more salt. Object-centric vision adds a mise en place system: every ingredient (object) gets its own labeled container (explicit representation). When the chef (model) needs to “add salt to the second carrot from the left” (referring expression), the system knows exactly which container to reach for (spatial grounding). If you want to swap that carrot for a potato (editing), the system preserves the rest of the dish (identity preservation). And when plating a new dish (generation), you can specify “place three cherry tomatoes in a triangle” with precision.
Key Concepts
-
Instance permanence: Imagine playing a shell game where cups shuffle around. Humans track which cup hides the ball even after movement. LMMs often lose track — ask about “the red car” in frame 1, then “that car” in frame 2, and the model might point to a different vehicle. Instance permanence means maintaining object identity across interactions, viewpoints, or edits. It’s the difference between “a red car” (category) and “car #47” (specific instance). Without it, multi-step tasks like “move the lamp, then change its color” fail because the model forgets which lamp you meant.
-
Spatial grounding: When you say “the cup on the left,” your brain instantly maps language to image coordinates. LMMs struggle with this. Spatial grounding is the mechanism that translates referring expressions into pixel-level localization. Early approaches used bounding boxes (coarse), modern methods output segmentation masks (precise). The challenge: “left” is relative, “near the window” requires scene understanding, and “the smaller one” needs comparative reasoning. Good grounding handles ambiguity, spatial relations, and multi-object scenes.
-
Object tokens: Standard vision transformers chop images into patches (16×16 grids) with no semantic meaning. Object tokens are learned representations where each token corresponds to one instance — like giving every person in a photo their own ID card. This enables operations like “swap token 3 with token 7” (rearrange objects) or “modify token 5’s color attribute” (targeted editing). The key insight: treating objects as discrete symbols (like words in language) makes them composable and controllable.
Framework Shift
Before (scene-level LMMs):          After (object-centric LMMs):

  [Image] ---> [Encoder]              [Image] ---> [Object Detector]
      |             |                       |              |
      v             v                       v              v
  [Global      [Scene                 [Object        [Instance
   Features]    Caption]                Tokens]        Attributes]
                                            |              |
  "A room with furniture"                   +---> Mask for "that chair"
  (can't point to specific chair)           +---> Edit "the lamp" only
                                             +---> Generate "3 apples here"
One sentence: From holistic scene embeddings to explicit object-level representations, the shift enables precise instance control without losing semantic understanding.
Expert Assessment
Problem choice: Real gap. The industry needs this — try building a photo editor where users say “make that person’s shirt blue” and watch current LMMs fail. The paper correctly identifies that scene-level understanding hit a ceiling; object-level control is the next frontier. Positioning as a survey is smart given the fragmented landscape.
Method maturity: This is a literature review, not a novel method, so evaluation differs. The taxonomy is well-structured (four task families make intuitive sense), but the paper misses quantitative analysis — no meta-study of which approaches actually work best, no benchmark comparison table. It reads more like a reading list than a critical synthesis. The “key modeling paradigms” section (presumably in the full paper) better deliver actionable insights, not just categorization.
Experimental integrity: N/A for a survey, but the paper should have included a systematic comparison of reported metrics across papers. Without it, readers can’t judge relative progress. The “evaluation protocols” discussion is crucial — if benchmarks are inconsistent, the field can’t converge.
Writing quality: The abstract is dense but clear. The four-pillar structure is pedagogically sound. Weakness: likely lacks concrete examples in each section. Surveys often describe methods abstractly; this one needs “here’s a failure case, here’s how object-centricity fixes it” walkthroughs. The “open challenges” section is where the paper earns its keep — if it’s just a wishlist, it’s weak; if it identifies fundamental blockers with evidence, it’s valuable.
Verdict: Weak accept — Timely survey of an important convergence, but needs more critical analysis and quantitative synthesis to be a landmark reference.
Takeaways
For practitioners building multimodal systems: Don’t bolt object detection onto LMMs as an afterthought. Design object tokens into your architecture from the start — they’re not just for segmentation, they enable compositional reasoning. If your use case involves “edit this specific thing” or “generate with precise layout,” scene-level features won’t cut it.
For researchers: The paper implicitly argues that the next generation of foundation models needs structured representations. Pure end-to-end learning on pixels + text is hitting diminishing returns for tasks requiring fine-grained control. The winning approach likely combines learned object discovery (no manual annotations) with explicit symbolic manipulation (compositionality).
Steal this framing: When pitching object-centric work, use the “instance permanence” concept. It’s immediately intuitive (everyone’s played the shell game) and highlights a clear failure mode of current systems. Much better than abstract claims about “fine-grained understanding.”
Red flag to watch: If a paper claims object-centric benefits but uses ground-truth bounding boxes at test time, it’s cheating. The hard part is discovering objects in the wild, not operating on them once located.
论文: 2604.11789 作者: Yuqian Yuan, Wenqiao Zhang, Juekai Lin, Yu Zhong, Mingjian Gao, Binhe Yu, Yunqi Cao, Wentong Li, Yueting Zhuang, Beng Chin Ooi 分类: cs.CV
缺口
像 GPT-4V 和 Gemini 这样的大型多模态模型(LMMs)擅长描述整个场景,但当你问”哪辆红车?“或”把那盏特定的灯稍微往左移”时就会卡壳。
它们能全局理解,但缺乏物体级别的精度。
此前的工作分为两个阵营:(1) 能整体推理但无法定位具体实例的 LMMs,(2) 能精确操作但缺乏语义理解的专用视觉模型(SAM、ControlNet)。
缺口在于:没有统一框架能将语义推理与像素级物体控制连接起来。
问题:LMMs 无法处理物体级任务
   |
   v
假设:显式物体表示能实现精确控制
   |
   v
方法:综述四大任务族的以物体为中心方法
   |
   v
证据:技术分类 + 识别开放挑战
   |
   v
结论:以物体为中心是可控多模态 AI 的缺失环节
增量
一句话: 这篇论文之前,LMMs 在场景级运作;之后,我们有了一张结构化地图,展示以物体为中心的表示如何实现实例级的理解、分割、编辑和生成。
核心机制
这是一篇综述论文,不是单一方法。
它将研究领域组织成四大支柱:(1) 以物体为中心的理解 — 将场景解析为带属性的离散实体的模型,(2) 指代分割 — 将语言定位到特定实例的像素掩码,(3) 视觉编辑 — 修改指定物体同时保留上下文,(4) 视觉生成 — 合成具有可控物体位置和外观的图像。
论文识别出三种反复出现的设计模式:显式物体标记(将每个实例视为模型表示中的离散符号),空间定位模块(将语言映射到图像坐标的机制),身份保持机制(确保同一物体在不同操作中保持一致外观)。
数据从原始图像流经物体检测/分割,进入融合视觉和语言特征的多模态编码器,然后到输出掩码、编辑或生成像素的任务特定解码器。
输入图像 + 文本查询
        |
        v
   [物体检测/分割]
        |
        v
   [多模态编码器]
    (融合视觉 + 语言)
        |
        +---> 理解:属性提取
        |
        +---> 分割:实例掩码
        |
        +---> 编辑:局部修改
        |
        +---> 生成:可控合成
把它想象成餐厅厨房。
传统 LMMs 像一位能精彩描述整道菜的厨师,但说不清哪根特定的胡萝卜需要加盐。
以物体为中心的视觉添加了一个备料系统:每种食材(物体)都有自己的标签容器(显式表示)。
当厨师(模型)需要”给左边第二根胡萝卜加盐”(指代表达)时,系统确切知道该拿哪个容器(空间定位)。
如果你想把那根胡萝卜换成土豆(编辑),系统会保留菜品的其余部分(身份保持)。
而在摆盘新菜(生成)时,你可以精确指定”把三颗樱桃番茄摆成三角形”。
关键概念
- 实例持久性: 想象玩猜杯子游戏,杯子来回移动。
人类能追踪哪个杯子藏着球,即使移动之后。
LMMs 常常跟丢 — 在第1帧问”那辆红车”,然后在第2帧问”那辆车”,模型可能指向不同的车辆。
实例持久性意味着在交互、视角或编辑过程中保持物体身份。
这是”一辆红车”(类别)和”47号车”(特定实例)的区别。
没有它,像”移动那盏灯,然后改变它的颜色”这样的多步骤任务会失败,因为模型忘记了你指的是哪盏灯。
- 空间定位: 当你说”左边的杯子”,你的大脑立即将语言映射到图像坐标。
LMMs 在这方面很吃力。
空间定位是将指代表达翻译成像素级定位的机制。
早期方法使用边界框(粗糙),现代方法输出分割掩码(精确)。
挑战在于:“左边”是相对的,“窗户附近”需要场景理解,“较小的那个”需要比较推理。
好的定位能处理歧义、空间关系和多物体场景。
- 物体标记: 标准视觉 Transformer 将图像切成无语义意义的小块(16×16 网格)。
物体标记是学习到的表示,其中每个标记对应一个实例 — 就像给照片中的每个人发一张身份证。
这使得操作成为可能,比如”交换标记3和标记7”(重排物体)或”修改标记5的颜色属性”(定向编辑)。
关键洞察:将物体视为离散符号(像语言中的词)使它们可组合、可控制。
框架转变
之前(场景级 LMMs):            之后(以物体为中心的 LMMs):

  [图像] ---> [编码器]              [图像] ---> [物体检测器]
      |             |                       |              |
      v             v                       v              v
  [全局        [场景                   [物体          [实例
   特征]        描述]                    标记]          属性]
                                            |              |
  "一个有家具的房间"                        +---> "那把椅子"的掩码
  (无法指向特定椅子)                        +---> 只编辑"那盏灯"
                                            +---> 在此生成"3个苹果"
一句话: 从整体场景嵌入到显式物体级表示,这一转变在不失去语义理解的情况下实现了精确的实例控制。
专家评审
选题眼光: 真实缺口。
行业需要这个 — 试着构建一个照片编辑器,用户说”把那个人的衬衫变蓝”,然后看着当前的 LMMs 失败。
论文正确识别出场景级理解已触及天花板;物体级控制是下一个前沿。
定位为综述很聪明,考虑到研究领域的碎片化。
方法成熟度: 这是文献综述,不是新方法,所以评估标准不同。
分类法结构良好(四大任务族直观合理),但论文缺少定量分析 — 没有关于哪些方法实际效果最好的元研究,没有基准对比表。
读起来更像阅读清单而非批判性综合。
“关键建模范式”部分(推测在完整论文中)最好能提供可操作的洞见,而不仅仅是分类。
实验诚意: 对综述不适用,但论文应该包含跨论文报告指标的系统比较。
没有它,读者无法判断相对进展。
“评估协议”讨论至关重要 — 如果基准不一致,该领域无法收敛。
写作功力: 摘要密集但清晰。
四支柱结构在教学上合理。
弱点:每个部分可能缺乏具体例子。
综述常常抽象地描述方法;这篇需要”这是一个失败案例,这是以物体为中心如何修复它”的演练。
“开放挑战”部分是论文赚取价值的地方 — 如果只是愿望清单,就很弱;如果用证据识别出根本性障碍,就很有价值。
判决: 弱接收 — 对重要交叉领域的及时综述,但需要更多批判性分析和定量综合才能成为里程碑式参考文献。
要点总结
对于构建多模态系统的实践者: 不要把物体检测作为事后补充硬塞到 LMMs 上。
从一开始就将物体标记设计进架构 — 它们不仅用于分割,还能实现组合推理。
如果你的用例涉及”编辑这个特定东西”或”按精确布局生成”,场景级特征不够用。
对于研究者: 论文隐含地论证下一代基础模型需要结构化表示。
对像素 + 文本的纯端到端学习在需要细粒度控制的任务上遇到收益递减。
获胜方法可能结合学习到的物体发现(无需人工标注)与显式符号操作(组合性)。
偷走这个框架: 在推销以物体为中心的工作时,使用”实例持久性”概念。
它立即直观(每个人都玩过猜杯子游戏),并突出当前系统的明确失败模式。
比关于”细粒度理解”的抽象声明好得多。
需要警惕的红旗: 如果一篇论文声称以物体为中心的好处,但在测试时使用真实边界框,那就是作弊。
难点在于在野外发现物体,而不是在定位后操作它们。