Paper: 2603.13189 Authors: J. de Curtò, I. de Zarzà Categories: cs.MA, cs.AI
The Gap
Existing multi-agent research has focused on using LLMs to generate influence strategies that maximize cooperation metrics. The problem: nobody’s checking whether that cooperation is genuine or achieved through manipulation. Prior approaches optimize for raw cooperation numbers without considering autonomy erosion, epistemic integrity, or distributional fairness. It’s like measuring traffic throughput without caring if you’re forcing pedestrians off sidewalks to achieve it.
Problem: LLM influence strategies maximize cooperation
    |
    v
Assumption: High cooperation = good outcome
    |
    v
Gap: Cooperation might mask manipulation/unfairness
    |
    v
Method: Constitutional governance (hard + soft constraints)
    |
    v
Evidence: 14.9% better ethical score, preserves autonomy
    |
    v
Conclusion: Cooperation needs ethical guardrails
The Increment
One sentence: Before this paper, we optimized multi-agent systems for cooperation; after, we optimize for ethical cooperation that preserves autonomy and fairness.
Core Mechanism
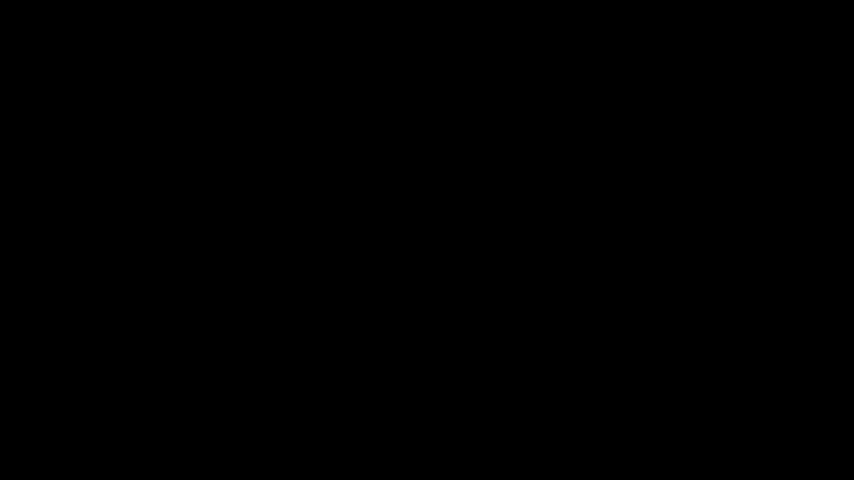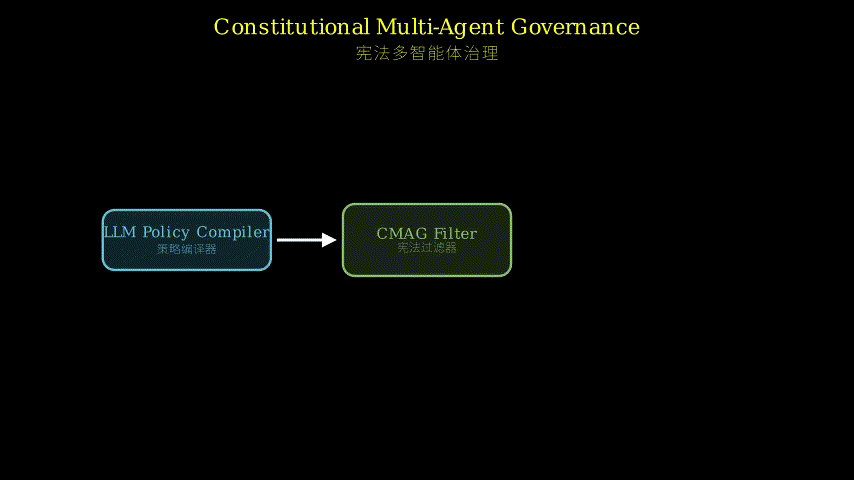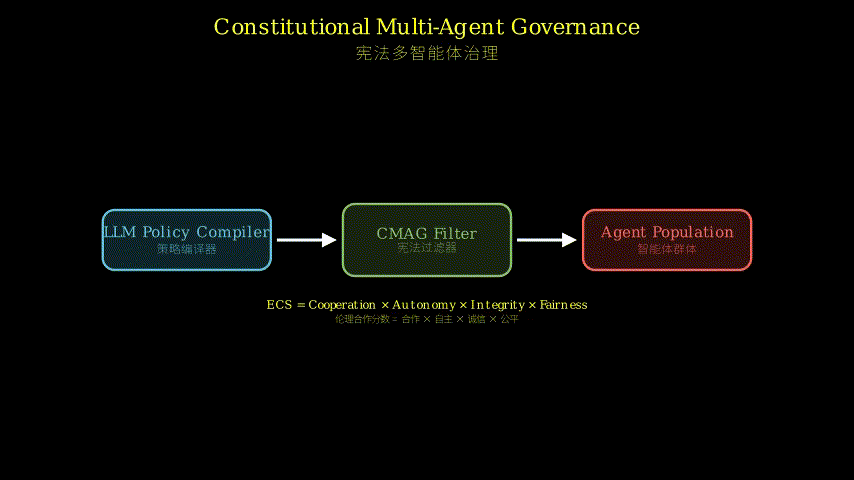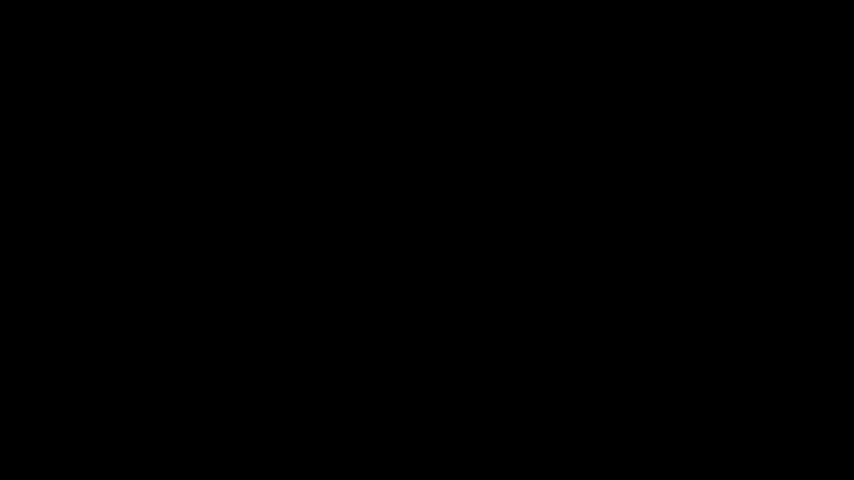
CMAG operates in two stages between an LLM policy compiler and a networked agent population. First, hard constraint filtering removes any influence strategy that violates constitutional rules (think: “no deception,” “no coercion”). This is binary—strategies either pass or get rejected. Second, soft penalized-utility optimization takes the surviving strategies and scores them using a composite metric that balances cooperation potential against manipulation risk, autonomy pressure, and fairness violations.
The key innovation is the Ethical Cooperation Score (ECS), which multiplies four dimensions: cooperation, autonomy, integrity, and fairness. The multiplicative structure is crucial—if any single dimension tanks, the whole score collapses. You can’t compensate for terrible autonomy with slightly better cooperation. This forces the optimizer to care about all dimensions simultaneously.
The system runs on scale-free networks (80 agents in their experiments) where some nodes are hubs with many connections and others are peripheral. The governance mechanism tracks not just aggregate metrics but also hub-periphery disparities—are influential nodes being disproportionately targeted or protected?
LLM Policy Compiler
    |
    v
[Constitutional Filter] <-- Hard constraints
    |                        (binary pass/fail)
    v
Candidate Strategies
    |
    v
[Penalized Optimizer] <-- Soft penalties
    |                      (ECS = coop * auto * integ * fair)
    v
Selected Strategy
    |
    v
Agent Network (80 nodes, scale-free topology)
Think of CMAG like city traffic management with ethics baked in. An unconstrained optimizer is like an AI that maximizes traffic flow by routing everyone through the fastest paths—even if that means sending trucks through residential neighborhoods at 3am or forcing pedestrians to jaywalk. The hard constraints are traffic laws: no trucks in residential zones, pedestrians have right of way. The soft optimizer is congestion pricing that accounts for noise pollution, pedestrian safety, and neighborhood impact. You still want flow, but not at any cost. The multiplicative ECS is like a livability index—if any dimension (safety, noise, fairness) is terrible, the whole neighborhood score tanks, and you can’t fix it by just making traffic 10% faster.
Key Concepts
-
Ethical Cooperation Score (ECS): Imagine you’re evaluating a workplace. You could measure productivity alone—how many widgets get made. But what if high productivity comes from overworking people, ignoring safety, or giving all resources to one team? ECS is like a composite workplace health score that multiplies productivity × worker autonomy × safety compliance × resource fairness. The multiplication is key: if safety drops to 0.5, your overall score gets cut in half no matter how productive you are. You can’t game the system by excelling in one dimension while tanking another. In this paper, ECS = cooperation × autonomy × integrity × fairness, so a system that achieves 0.873 cooperation but only 0.867 autonomy gets an ECS of roughly 0.645—the autonomy erosion drags everything down.
-
Constitutional Constraints (Hard vs Soft): Hard constraints are binary rules—like “no deception” or “no coercion.” If a strategy violates them, it’s rejected outright. Soft constraints are preferences encoded as penalties in the optimization objective. Think of hard constraints as laws (you can’t drive drunk, period) and soft constraints as guidelines (we prefer you don’t idle your car for 20 minutes, but we’ll just charge you more for parking). The paper shows that hard constraints alone (naive filtering) aren’t enough—you need the soft optimizer to balance competing ethical dimensions.
-
Hub-Periphery Exposure Disparity: In scale-free networks, some nodes (hubs) have many connections while others (periphery) have few. An influence strategy might disproportionately target hubs because they’re more influential, or it might exploit peripheral nodes because they’re less visible. Exposure disparity measures this imbalance. If hubs face 10x more manipulation attempts than peripheral nodes, that’s a fairness problem even if aggregate cooperation looks good. CMAG reduces this disparity by over 60%, meaning the governance mechanism distributes influence attempts more evenly across the network topology.
Framework Shift
Before (unconstrained optimization):

LLM --> [Maximize Cooperation] --> Agent Network
         ^                          |
         |                          v
         +-------- Feedback --------+

Goal: Highest cooperation number
Risk: Manipulation, autonomy loss hidden
After (CMAG):

LLM --> [Constitutional Filter] --> [ECS Optimizer] --> Agent Network
         (hard constraints)          (soft penalties)      |
                                           ^                v
                                           |                |
                                           +-- Feedback ----+

Goal: Ethical cooperation (ECS)
Protects: Autonomy, integrity, fairness
From single-objective optimization (maximize cooperation) to multi-objective optimization with constitutional guardrails (maximize ethical cooperation while preserving autonomy and fairness), the core shift is treating cooperation as necessary but not sufficient.
Expert Assessment
Problem choice: This is a real gap, not manufactured. The AI safety community has been worried about optimization demons—systems that achieve their objective through unintended means. This paper applies that concern to multi-agent cooperation, which is timely given increasing interest in LLM-mediated social systems. It sits at the intersection of AI safety and multi-agent systems, which is an active area.
Method maturity: Conceptually straightforward—it’s constraint satisfaction plus multi-objective optimization, both well-established techniques. The novelty is in the application and the ECS metric design, not in inventing new algorithms. The multiplicative ECS is clever but not groundbreaking. A simpler approach might be Pareto optimization over the four dimensions without the multiplicative structure, though the authors do show that multiplication has desirable properties (penalizes imbalanced solutions).
Experimental integrity: Solid setup with 80 agents and 70% adversarial conditions (strategies that violate constraints). The baselines are fair—unconstrained optimization, naive filtering, and full CMAG. However, they only test on scale-free networks. What about other topologies (small-world, random, hierarchical)? The paper would be stronger with more diverse scenarios. Also, 80 agents is reasonable but not huge—does this scale to 1000+ agents? The Pareto analysis is good, showing CMAG dominates the cooperation-autonomy trade-off space.
Writing quality: The abstract is dense and front-loads too much detail. The ECS formula appears late—it should be introduced earlier with intuition about why multiplication matters. The experimental section is clear, but the paper would benefit from a running example showing how a specific influence strategy gets filtered and penalized. The related work section is thin—more comparison with AI safety and mechanism design literature would strengthen positioning.
Verdict: Weak accept—important problem with solid execution, but limited experimental scope (one network topology) and incremental methodology (applying existing techniques rather than inventing new ones). The ECS metric and the empirical demonstration that governance matters are valuable contributions, but the paper doesn’t fundamentally change how we think about multi-agent optimization.
Takeaways
-
Multiplicative metrics force balanced optimization: When building composite scores, multiplication prevents gaming the system by excelling in one dimension while tanking another. If you’re evaluating anything with multiple ethical dimensions (fairness, privacy, accuracy), consider multiplicative rather than additive aggregation.
-
Two-stage governance (hard + soft) beats either alone: The naive filtering ablation (ECS = 0.733) vs full CMAG (ECS = 0.741) shows that hard constraints filter out the worst offenders but soft penalties are needed to navigate trade-offs among the survivors. This pattern transfers to any system where you have both non-negotiable rules and competing preferences.
-
Check distributional fairness, not just aggregates: The hub-periphery analysis reveals that aggregate cooperation can hide unfair targeting of specific network positions. When evaluating any networked system, look at variance and distributional metrics, not just means. Are influential nodes being exploited? Are peripheral nodes being ignored?
-
Cooperation is not inherently desirable: The paper’s core insight—that high cooperation achieved through manipulation is worse than moderate cooperation achieved ethically—applies beyond multi-agent systems. In organizational design, product metrics, or policy evaluation, always ask: what’s the mechanism producing this outcome?
论文: 2603.13189 作者: J. de Curtò, I. de Zarzà 分类: cs.MA, cs.AI
缺口
现有的多智能体研究专注于用大语言模型生成影响策略,以最大化合作指标。
问题在于:没人检查这种合作是真实的还是通过操纵实现的。
先前的方法优化原始合作数字,却不考虑自主性侵蚀、认知完整性或分配公平性。
这就像测量交通吞吐量,却不在乎你是否为了达成目标而把行人赶下人行道。
问题:大语言模型影响策略最大化合作
    |
    v
假设:高合作 = 好结果
    |
    v
缺口:合作可能掩盖操纵/不公平
    |
    v
方法:宪法治理(硬约束 + 软约束)
    |
    v
证据:伦理分数提升14.9%,保留自主性
    |
    v
结论:合作需要伦理护栏
增量
一句话: 这篇论文之前,我们优化多智能体系统的合作;之后,我们优化保留自主性和公平性的伦理合作。
核心机制
CMAG在大语言模型策略编译器和网络化智能体群体之间分两阶段运作。
首先,硬约束过滤移除任何违反宪法规则的影响策略(比如:“不得欺骗”、“不得胁迫”)。
这是二元的——策略要么通过,要么被拒绝。
其次,软惩罚效用优化对幸存的策略打分,使用一个复合指标来平衡合作潜力与操纵风险、自主性压力和公平性违规。
关键创新是伦理合作分数(ECS),它将四个维度相乘:合作、自主性、完整性和公平性。
乘法结构至关重要——如果任何单一维度崩溃,整个分数就会坍塌。
你无法用稍好的合作来补偿糟糕的自主性。
这迫使优化器同时关心所有维度。
系统运行在无标度网络上(他们的实验中有80个智能体),其中一些节点是拥有许多连接的枢纽,其他节点则处于外围。
治理机制不仅跟踪聚合指标,还跟踪枢纽-外围差异——有影响力的节点是否被不成比例地针对或保护?
大语言模型策略编译器
    |
    v
[宪法过滤器] <-- 硬约束
    |              (二元通过/失败)
    v
候选策略
    |
    v
[惩罚优化器] <-- 软惩罚
    |             (ECS = 合作 * 自主 * 完整 * 公平)
    v
选定策略
    |
    v
智能体网络(80节点,无标度拓扑)
把CMAG想象成内置伦理的城市交通管理。
无约束优化器就像一个AI,通过让所有人走最快路径来最大化交通流量——即使这意味着在凌晨3点让卡车穿过居民区,或强迫行人乱穿马路。
硬约束是交通法规:卡车不得进入居民区,行人有路权。
软优化器是考虑噪音污染、行人安全和社区影响的拥堵定价。
你仍然想要流量,但不是不惜一切代价。
乘法ECS就像宜居指数——如果任何维度(安全、噪音、公平)很糟糕,整个社区分数就会暴跌,你无法仅通过让交通快10%来修复它。
关键概念
- 伦理合作分数(ECS): 想象你在评估一个工作场所。
你可以单独测量生产力——制造了多少小部件。
但如果高生产力来自过度劳累员工、忽视安全或把所有资源给一个团队呢?ECS就像一个复合工作场所健康分数,将生产力 × 员工自主性 × 安全合规 × 资源公平性相乘。
乘法是关键:如果安全降到0.5,无论你多有生产力,你的总分都会减半。
你无法通过在一个维度上表现出色而在另一个维度上崩溃来操纵系统。
在本文中,ECS = 合作 × 自主性 × 完整性 × 公平性,所以一个实现0.873合作但只有0.867自主性的系统得到的ECS大约是0.645——自主性侵蚀拖累了一切。
- 宪法约束(硬约束 vs 软约束): 硬约束是二元规则——比如”不得欺骗”或”不得胁迫”。
如果策略违反它们,就会被直接拒绝。
软约束是编码为优化目标中惩罚的偏好。
把硬约束想象成法律(你不能酒驾,句号),软约束想象成指南(我们希望你不要让车空转20分钟,但我们只会多收你停车费)。
论文表明,仅有硬约束(朴素过滤)是不够的——你需要软优化器来平衡竞争的伦理维度。
- 枢纽-外围暴露差异: 在无标度网络中,一些节点(枢纽)有许多连接,而其他节点(外围)连接很少。
影响策略可能不成比例地针对枢纽,因为它们更有影响力,或者可能利用外围节点,因为它们不太显眼。
暴露差异衡量这种不平衡。
如果枢纽面临的操纵尝试是外围节点的10倍,即使聚合合作看起来不错,这也是一个公平性问题。
CMAG将这种差异减少了60%以上,意味着治理机制在网络拓扑中更均匀地分配影响尝试。
框架转变
之前(无约束优化):

大语言模型 --> [最大化合作] --> 智能体网络
                ^                  |
                |                  v
                +---- 反馈 --------+

目标:最高合作数字
风险:操纵、自主性丧失被隐藏
之后(CMAG):

大语言模型 --> [宪法过滤器] --> [ECS优化器] --> 智能体网络
                (硬约束)        (软惩罚)        |
                                      ^              v
                                      |              |
                                      +-- 反馈 ------+

目标:伦理合作(ECS)
保护:自主性、完整性、公平性
从单目标优化(最大化合作)到带宪法护栏的多目标优化(在保留自主性和公平性的同时最大化伦理合作),核心转变是将合作视为必要但不充分的条件。
专家评审
选题眼光: 这是真实的缺口,不是人造的。
AI安全社区一直担心优化恶魔——通过意外手段实现目标的系统。
本文将这种担忧应用于多智能体合作,鉴于人们对大语言模型中介的社会系统日益增长的兴趣,这很及时。
它处于AI安全和多智能体系统的交叉点,这是一个活跃的领域。
方法成熟度: 概念上很直接——这是约束满足加多目标优化,两者都是成熟的技术。
新颖性在于应用和ECS指标设计,而不是发明新算法。
乘法ECS很巧妙但不是开创性的。
一个更简单的方法可能是对四个维度进行帕累托优化,而不使用乘法结构,尽管作者确实表明乘法具有理想的特性(惩罚不平衡的解决方案)。
实验诚意: 扎实的设置,有80个智能体和70%的对抗条件(违反约束的策略)。
基线是公平的——无约束优化、朴素过滤和完整CMAG。
然而,他们只在无标度网络上测试。
其他拓扑(小世界、随机、层次)呢?如果有更多样化的场景,论文会更强。
此外,80个智能体是合理的但不算庞大——这能扩展到1000+个智能体吗?帕累托分析很好,显示CMAG主导合作-自主性权衡空间。
写作功力: 摘要很密集,前置了太多细节。
ECS公式出现得很晚——应该更早引入,并说明为什么乘法很重要。
实验部分很清晰,但论文会受益于一个运行示例,展示特定影响策略如何被过滤和惩罚。
相关工作部分很薄——与AI安全和机制设计文献的更多比较会加强定位。
判决: 弱接收——重要问题,执行扎实,但实验范围有限(一种网络拓扑),方法论是增量式的(应用现有技术而不是发明新技术)。
ECS指标和治理重要性的实证证明是有价值的贡献,但论文没有从根本上改变我们对多智能体优化的思考方式。
要点总结
- 乘法指标强制平衡优化: 构建复合分数时,乘法防止通过在一个维度上表现出色而在另一个维度上崩溃来操纵系统。
如果你在评估任何具有多个伦理维度(公平性、隐私、准确性)的东西,考虑乘法而不是加法聚合。
- 两阶段治理(硬+软)胜过单独任何一个: 朴素过滤消融(ECS = 0.733)与完整CMAG(ECS = 0.741)表明,硬约束过滤掉最糟糕的违规者,但需要软惩罚来在幸存者之间导航权衡。
这种模式可以迁移到任何既有不可协商规则又有竞争偏好的系统。
- 检查分配公平性,而不仅仅是聚合: 枢纽-外围分析揭示,聚合合作可以隐藏对特定网络位置的不公平针对。
评估任何网络化系统时,查看方差和分布指标,而不仅仅是均值。
有影响力的节点是否被利用?外围节点是否被忽视?
- 合作本身并不可取: 论文的核心洞见——通过操纵实现的高合作比通过伦理实现的适度合作更糟——适用于多智能体系统之外。
在组织设计、产品指标或政策评估中,始终问:产生这个结果的机制是什么?