Paper: 2608.13545 Authors: Fanfei Li, Jana Zeller, Manuel Prada-Corral, Thaddäus Wiedemer, Prasanna Mayilvahanan, Ryan Cotterell, Wieland Brendel Categories: cs.CL, cs.AI, cs.LG
The Gap
Here’s a problem that quietly undermines a whole genre of papers. Every time someone claims “we taught the model a new fact” or “fine-tuning induced this capability,” there’s an unanswerable question hanging over the result: was the model actually learning, or was it retrieving something it already absorbed from 15 trillion tokens of scraped web text? You can’t check, because nobody — including the people who built the corpus — can characterize what’s in it.
The field has attacked this from three directions, and all three fall short in a specific way.
Benchmark decontamination (n-gram overlap filtering, embedding-based dedup against test sets) removes the literal test items. It does nothing about the *concepts. Strip every instance of a particular GSM8K problem and the model has still read a million algebra tutorials.
Developmentally plausible corpora — the BabyLM lineage, TinyStories — do control scope, and control it beautifully. But they buy that control by shrinking to 10M–100M words. The resulting models are useful for studying grammar acquisition and not much else: you cannot run open-ended evaluation, instruction following, or knowledge injection experiments on a model that can barely hold a topic for three sentences.
Post-hoc attribution — influence functions, memorization probes, canary insertion, activation-level knowledge localization — tries to reverse-engineer what a model saw. These are estimates on an uncontrolled substrate, and they inherit all the uncertainty of the substrate.
So the gap is quite precise: nobody has a language model that is simultaneously fluent enough to evaluate open-endedly and scoped tightly enough that its knowledge ceiling is documented in auditable, human-readable terms. LittleLearner’s bet is that a school curriculum is exactly such a document.
[Problem]  web-scale corpora are opaque
    |      cannot separate "learned now" from "seen during pretraining"
    v
[Prior attempts]
    +-- decontamination ....... deletes test items, not the concepts
    +-- BabyLM / TinyStories .. clean scope, model too weak to probe
    +-- influence / probing ... post-hoc estimates on messy substrate
    |
    v
[Assumption]  a human curriculum is an auditable knowledge ceiling:
              "nothing taught above U.S. Grade 5"
    |
    v
[Method]  filter a corpus down to 88B in-scope tokens
          train 5B params from scratch  =>  LITTLELEARNER
    |
    v
[Evidence]  post-training and in-context injection make the model
            *use* in-scope knowledge better,
            but out-of-scope capability stays flat
    |
    v
[Conclusion]  capability scope is set at pretraining;
              prompting and light post-training redistribute
              rather than extend it
The Increment
One sentence: Before, “did the model already know this?” was a question you argued about; after, it’s a question you look up in a curriculum standard.
Core Mechanism
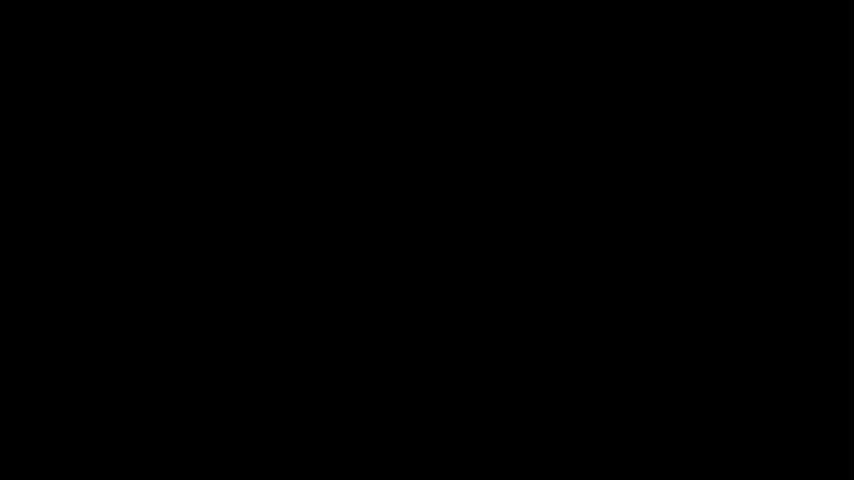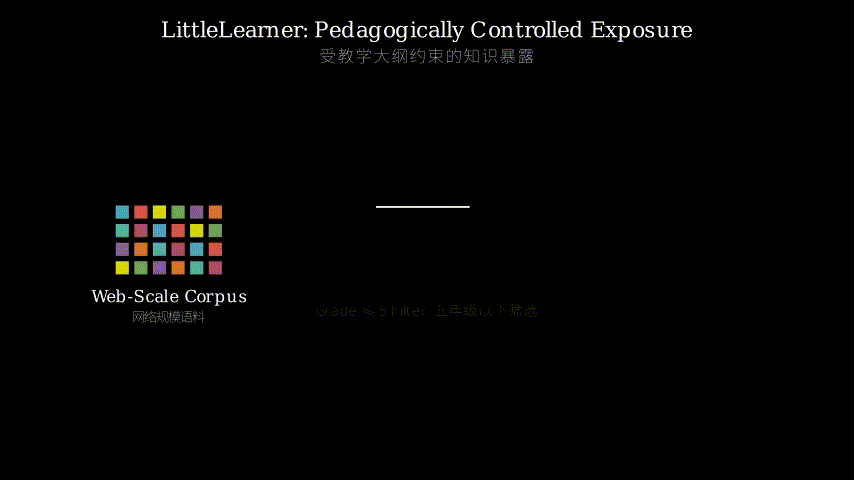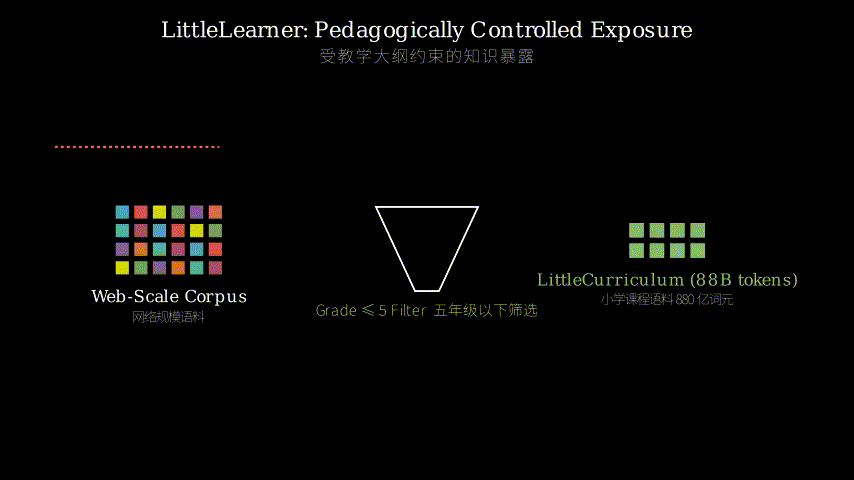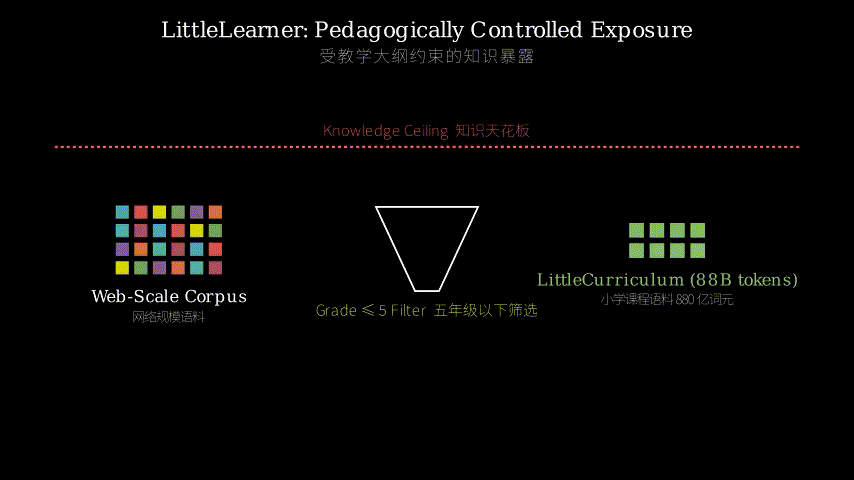
The pipeline has three stages, and the interesting engineering is all in the first. Start from U.S. elementary school standards — the concept, fact, and vocabulary inventories that define what a child is expected to know by the end of Grade 5. Compile that into a scope specification: arithmetic with fractions is in, algebraic manipulation is out; the water cycle is in, molecular bonding is out; state capitals are in, macroeconomic policy is out. Then run a filtering apparatus over a large text pool that keeps documents consistent with the specification and discards anything that presupposes above-grade knowledge. The output is LITTLECURRICULUM at roughly 88B tokens — three orders of magnitude above BabyLM, which is the whole point: it’s enough to train a model that talks.
Stage two is unremarkable by design: pretrain a 5B-parameter decoder from scratch on that corpus. No distillation from a frontier model, because that would smuggle out-of-scope knowledge in through the back door. The result, LITTLELEARNER, is a model with adult-ish fluency and a child’s knowledge base — an unusual combination that doesn’t exist naturally.
Stage three is where the sandbox earns its keep. With a known ceiling, you can run injection experiments that were previously impossible to interpret. Take a fact or skill you know is out of scope, push it in via post-training or via in-context examples, and measure what moves. The paper’s headline finding from this first suite: both routes improve how well the model deploys knowledge it already has, but neither lifts genuinely out-of-scope capability. The ceiling holds.
   U.S. elementary standards (K-5)
   [concepts]  [facts]  [vocabulary]
        |
        |  compile into scope specification
        v
   +----------------------------+
   |   in-scope / out-of-scope  | <=== large raw text pool
   |        filtering           |
   +----------------------------+
        |                    |
     keep                  drop (Grade 6+ presupposed)
        |
        v
   LITTLECURRICULUM  ~88B tokens
        |
        v
   pretrain 5B decoder from scratch  (no teacher model)
        |
        v
   LITTLELEARNER  = fluent + bounded
        |
        +--- probe A: post-training injection ---+
        +--- probe B: in-context injection ------+
                                                 |
                                                 v
                       in-scope utilization ..... ^ improves
                       out-of-scope capability .. ~ flat
Think of a germ-free mouse colony. Immunologists don’t study gut bacteria in wild mice, because a wild mouse’s microbiome is an unknowable historical accident — exactly the position we’re in with web-scale pretraining. So they raise gnotobiotic mice in sterile isolators, where the entire microbial inventory is documented. Then they introduce one defined strain and watch precisely what happens.
Every piece maps. The sterile isolator is the scope filter. The documented inventory is the curriculum standard — not “we hope it’s clean” but “here is the list.” The mouse raised inside is LittleLearner: a real, functioning organism, not a cell culture, which is why the 88B-token scale matters (a BabyLM-sized model is the cell culture — clean but not alive enough to answer systemic questions). Introducing a defined strain is the post-training or in-context injection. And the finding maps too: the strain colonizes, the animal metabolizes it, but you don’t get a systemic immune competence the animal was never developmentally equipped for. Facts land; capabilities don’t materialize.
The metaphor also carries the main limitation, which is a good sign it’s the right one. A germ-free colony is only as good as the seal on the isolator, and the whole scientific value collapses if there’s a leak nobody detected.
Key Concepts
-
Contamination vs. conceptual prerequisite: These get conflated constantly. Contamination is the model having seen the *exact test item — “What is the capital of Peru? Lima” appearing verbatim in training. A conceptual prerequisite is subtler: the model may never have seen your specific quadratic equation, but it read thousands of pages that assume you can manipulate symbolic expressions. Standard decontamination catches the first and is blind to the second. LittleCurriculum targets the second, which is why it filters by what a document presupposes, not by string overlap. Concretely: a physics blog post that never mentions your benchmark question still teaches the model that force and acceleration are proportional — and that’s the leak that matters.
-
An interpretable knowledge boundary: The unusual move here isn’t restricting data — everyone does that. It’s restricting it along an axis that a human can *read. “Excludes content above Grade 5” is a claim you can check against a published document, disagree with, and file a bug report about. Compare to “we filtered for quality using a classifier trained on Wikipedia references,” which is a boundary no one can inspect. The boundary being auditable is the actual research artifact; the model is the vehicle.
-
Utilization vs. acquisition: When a fine-tuned model scores higher, two very different things could have happened. It might have acquired new knowledge, or it might have gotten better at surfacing knowledge that was already latent — better formatting, better instruction following, better retrieval of what’s already in the weights. On an ordinary model these are nearly impossible to separate. With a documented ceiling, the separation becomes mechanical: gains on in-scope items are utilization by construction, and gains on out-of-scope items would be genuine acquisition. This paper reports the former without the latter.
Framework Shift
Before (mainstream):                 After (this paper):

  everything ever written              curriculum ceiling
  [........................]           [___ <= Grade 5 ___]
             |                                  |
             v                                  v
       large model                         5B model
             |                                  |
   ? what did it know                   known upper bound,
   ? what did it just learn             documented in prose
             |                                  |
             v                                  v
    post-hoc forensics                  controlled injection
    (dedup, probe, argue)               (add X, measure X)
             |                                  |
             v                                  v
    "probably not contaminated"         "X is out of scope,
                                         here is the standard"
From forensics to experimental design, the core shift is moving the control from after training to before it — you stop trying to prove a negative about your corpus and instead build a corpus where the negative is stated up front.
Expert Assessment
A caveat on calibration: I’m working primarily from the abstract and the described artifacts, not from an audit of the corpus. The claims I’d most want to check are exactly the ones I flag below.
Problem choice: Real gap, and it’s getting more urgent, not less. As pretraining corpora approach “all available text,” every knowledge-editing, continual-learning, and emergent-capability claim becomes harder to defend. This paper sits in a clear trajectory — BabyLM proved controlled-scope pretraining is scientifically productive, TinyStories proved small models can be fluent within a narrow world, and this scales that logic to a size where the model is a usable experimental subject. The framing choice of a *pedagogical boundary rather than a topical or temporal one is genuinely clever, because school standards are a pre-existing, externally maintained, community-audited taxonomy. The authors didn’t have to invent the ontology, which is usually where these projects die.
My reservation: Grade 5 is an artifact of U.S. state education policy, not a cognitive or linguistic joint in nature. It’s interpretable, which is what’s being claimed, but it’s also arbitrary in a way that will make cross-lingual and cross-cultural extensions messy. And the concept-vocabulary boundary is genuinely fuzzy — plenty of Grade 5 material gestures at ideas formalized much later.
Method maturity: Honestly, it’s data engineering with a good idea on top. The filtering is presumably classifier-based, and the entire scientific value rests on the filter’s recall for out-of-scope content — a quantity that is very hard to bound over 88B tokens. Precision failures just make the corpus smaller; recall failures silently poison every downstream experiment. I’d want to see aggressive adversarial auditing: hire people to *find out-of-scope content and report how easy it was.
There’s a second worry I’d want addressed explicitly. Where do 88B tokens of grade-appropriate text come from? Genuine K-5 material doesn’t exist at that scale. Either heavy filtering of general web text (which raises the recall question sharply — implicit above-grade framing survives filters that catch explicit topics) or synthetic generation/rewriting by a frontier model. If it’s the latter, the generator’s out-of-scope knowledge leaks in as distributional structure even when no forbidden term appears. That’s a subtle, hard-to-detect contamination channel and it would undercut the central guarantee.
Experimental integrity: The abstract’s own language — “illustrate the sandbox’s utility in a first suite of experiments” — tells you the demonstration is deliberately preliminary. That’s fine for a resource paper but it does put weight on the resource being airtight.
The negative result needs care. “ICL does not raise out-of-scope capabilities” is only interesting if you’ve ruled out the boring explanations: insufficient context, poor prompt format, a model too small to benefit from ICL at all. A model at 5B trained on simple text may have weak in-context learning across the board, which would produce this result for uninteresting reasons. The strongest control I’d want is a matched 5B model trained on unfiltered text at the same token budget. Without it, you cannot attribute the flat curve to scope restriction rather than to scale, corpus simplicity, or general model weakness. Whether that control exists is the single thing I’d look for first in the full paper.
Writing quality: The abstract’s hedging is where the corners got cut. “Sufficient language competence for open-ended evaluation” and “clear knowledge and capability boundaries” are both load-bearing claims stated as assertions. The section that would most elevate the paper is a rigorous filter-validation chapter: adversarial audit results, estimated leakage rates by domain, honest documentation of where the Grade 5 line is unenforceable, and a clear account of the corpus’s provenance mix. For a resource paper, that section *is the contribution — the injection experiments are a demo, and demos are replaceable.
Verdict: weak accept — the framing is genuinely useful and the artifact will get used, but the central guarantee is only as strong as an unverified filter, and the accompanying experiments are thin enough that the paper stands or falls on corpus auditing that the abstract doesn’t foreground.
Takeaways
Things worth stealing:
Borrow existing human taxonomies instead of inventing ontologies. The move that makes this project tractable is using school standards as an off-the-shelf, externally maintained, human-readable scope specification. The same trick generalizes: medical training curricula for clinical-model scope control, apprenticeship progressions for tool use, certification syllabi for professional domains, language-proficiency frameworks like CEFR for graded linguistic ability. Any field with a formalized “what you should know at stage N” document has a free ontology sitting there. Most researchers reach for embeddings and clustering when a licensing board already did the work.
Define your negative space before training, not after. The generalizable methodology is: pick a boundary, document it in language a stranger can check, filter to it, then run injection experiments against the documented gaps. This applies well beyond curricula — temporal cutoffs, language exclusions, domain exclusions. The point isn’t the specific boundary, it’s building corpora where “the model never saw X” is a design specification rather than a post-hoc hope.
Fluency and knowledge scale differently, and you can exploit the gap. LittleLearner is evidence you can decouple them: adult grammar with a child’s knowledge base. If you’re building an evaluation subject, this is a useful design parameter — you may not need a knowledgeable model to study reasoning, formatting, calibration, or instruction following. A cheaper, tightly scoped model can be the better instrument precisely because you know what it doesn’t know.
The negative result is the practically useful bit. If it holds under proper controls, “ICL and light post-training improve utilization but don’t extend capability scope” is directly actionable for anyone deploying RAG or fine-tuning. Retrieval gives your model facts; it does not give it the reasoning substrate needed to use them. If your model can’t do the underlying operation, stuffing the answer into context won’t rescue it. Most teams learn this expensively.
Caveat on the sandbox itself: before building research on top of LittleCurriculum, check the corpus provenance and filter-validation numbers. If a substantial portion is synthetically generated by a frontier model, the “known ceiling” guarantee is weaker than advertised, and experiments that depend on it inherit that weakness.
论文: 2608.13545 作者: Fanfei Li, Jana Zeller, Manuel Prada-Corral, Thaddäus Wiedemer, Prasanna Mayilvahanan, Ryan Cotterell, Wieland Brendel 分类: cs.CL, cs.AI, cs.LG
缺口
有一个问题在悄悄地拖垮一整类论文。
每当有人宣称”我们教会了模型一个新事实”或者”微调诱发了某种能力”,结果背后都悬着一个无法回答的疑问:模型到底是在学,还是在把它早就从十几万亿 token 网页文本里吸收过的东西调出来?
你查不了。因为没有人——包括建语料库的人——能说清里面到底有什么。
这个领域从三个方向进攻过,三个方向都在某个具体的地方失效了。
基准去污染(n-gram 重叠过滤、对测试集做 embedding 去重)删掉的是字面上的测试样本,对概念毫无作用。
你可以把某道 GSM8K 题的所有出现都清干净,模型照样读过一百万篇代数教程。
发育合理语料库——BabyLM 那条线,还有 TinyStories——确实控制住了范围,而且控制得很漂亮。
但这份控制是用规模换来的:缩到 1000 万到 1 亿词。
得到的模型只适合研究语法习得,别的干不了。
一个连话题都撑不过三句话的模型,你没法在它身上做开放式评测、指令跟随、或者知识注入实验。
事后归因——影响函数、记忆探测、canary 插入、激活层面的知识定位——试图反推模型见过什么。
这些都是在一个不可控的底座上做估计,底座的所有不确定性它们全盘继承。
所以缺口相当精确:没有人手上有一个模型,同时既流畅到能做开放式评测,又受限到知识天花板可以用人类可读、可审计的方式写下来。
LittleLearner 押的注是:学校课程标准正好就是这样一份文件。
[问题]  网页级语料库不透明
   |    无法区分 "此刻学到的" 和 "预训练时见过的"
   v
[已有尝试]
   +-- 去污染 ............. 删测试样本,删不掉概念
   +-- BabyLM / TinyStories  范围干净,但模型弱到没法探测
   +-- 影响函数 / 探针 ..... 在脏底座上做事后估计
   |
   v
[假设]  人类课程标准就是一份可审计的知识天花板:
        "不包含美国五年级以上教的内容"
   |
   v
[方法]  把语料过滤到 880 亿 in-scope token
        50 亿参数从零预训练  =>  LITTLELEARNER
   |
   v
[证据]  后训练注入 + 上下文注入,
        都能让模型更好地 *调用* 范围内知识,
        但范围外能力曲线是平的
   |
   v
[结论]  能力边界在预训练阶段就定了;
        提示和轻量后训练只是重新分配,不是扩张
增量
一句话:“模型是不是早就知道这个?“从一个需要争论的问题,变成了一个查课程标准就能回答的问题。
核心机制
流程分三段,有意思的工程全在第一段。
从美国小学课程标准出发——那份规定孩子在五年级结束时应该掌握哪些概念、事实、词汇的清单。
把它编译成一份范围规格说明:分数四则运算在内,代数符号操作在外;水循环在内,分子键合在外;各州首府在内,宏观经济政策在外。
然后在一个大文本池上跑过滤装置,保留与规格一致的文档,丢掉任何预设了超纲知识的内容。
产出是 LITTLECURRICULUM,约 880 亿 token——比 BabyLM 大三个数量级,而这正是重点:足够训练出一个真能说话的模型。
第二段刻意平淡:在该语料上从零预训练一个 50 亿参数的 decoder。
不做前沿模型蒸馏,因为那等于从后门把超纲知识偷运进来。
产物 LITTLELEARNER 是一个成年人式的流畅度配一个小学生的知识库——一种自然界不存在的组合。
第三段是这个沙盒真正开始产出价值的地方。
有了已知的天花板,你就能做以前根本无法解读的注入实验。
拿一个你确知超纲的事实或技能,通过后训练或上下文示例推进去,测量什么发生了变化。
论文这第一批实验的核心发现:两条路径都能改善模型对已有知识的调用,但都抬不起真正超纲的能力。
天花板守住了。
   美国小学课程标准 (K-5)
   [概念]  [事实]  [词汇]
        |
        |  编译为范围规格说明
        v
   +----------------------------+
   |   in-scope / out-of-scope  | <=== 大规模原始文本池
   |          过滤              |
   +----------------------------+
        |                    |
      保留               丢弃 (预设六年级以上)
        |
        v
   LITTLECURRICULUM  ~880 亿 token
        |
        v
   50 亿参数 decoder 从零预训练  (无教师模型)
        |
        v
   LITTLELEARNER  = 流畅 + 有界
        |
        +--- 探针 A: 后训练注入 ------+
        +--- 探针 B: 上下文注入 ------+
                                      |
                                      v
                  范围内知识利用率 ..... ^ 提升
                  范围外能力 ........... ~ 持平
把它想成一个无菌小鼠种群。
免疫学家不会拿野生小鼠研究肠道菌群,因为野鼠的菌群是一段不可知的历史偶然——这正是我们在网页级预训练面前的处境。
所以他们在无菌隔离器里养无菌小鼠,整个微生物清单是有据可查的。
然后引入一个明确定义的菌株,精确观察发生了什么。
每一块都对得上。
无菌隔离器就是范围过滤器。
有据可查的清单就是课程标准——不是”我们希望它是干净的”,而是”清单在这儿”。
在里面长大的小鼠就是 LittleLearner:一个真正在运作的生物体,不是细胞培养物——这就是 880 亿 token 规模为什么重要(BabyLM 尺度的模型是细胞培养物:干净,但不够”活”,回答不了系统层面的问题)。
引入明确菌株就是后训练或上下文注入。
结论也对得上:菌株定植了,动物代谢它,但你不会因此获得一种它在发育上从未具备条件的系统性免疫能力。
事实落地了;能力没有凭空长出来。
这个比喻还顺带承载了主要局限,这是它选对了的信号:无菌种群的价值上限就是隔离器密封的质量,一旦有一处没被发现的泄漏,全部科学价值归零。
关键概念
-
污染 vs. 概念前置:这两件事经常被混为一谈。污染是模型见过一模一样的测试样本——“秘鲁首都是哪里?利马”原文出现在训练集里。概念前置更隐蔽:模型可能从没见过你那道具体的二次方程,但它读过成千上万页预设了”你会做符号变形”的材料。标准去污染抓得住前者,对后者完全失明。LittleCurriculum 针对的是后者,所以它按”一份文档预设了什么”来过滤,而不是按字符串重叠。举个具体的例子:一篇从头到尾没提你那道题的物理博客,照样在教模型力和加速度成正比——而那才是真正要命的泄漏。
-
可解释的知识边界:这里不寻常的一步不是限制数据——所有人都在限制数据。而是沿着一条人类能读懂的轴去限制。“不含五年级以上内容”是一个你可以对照公开文件核查、可以不同意、可以提 bug 的断言。对比一下”我们用一个在 Wikipedia 引用上训练的分类器过滤了质量”——那是一条没人能检查的边界。边界的可审计性才是真正的研究产出物;模型是载体。
-
利用 vs. 获取:当一个微调后的模型分数变高,可能发生了两件完全不同的事。它可能获取了新知识,也可能只是变得更擅长把本来就潜伏在权重里的东西表达出来——格式更好、更会跟指令、更容易取出已有内容。在普通模型上这两者几乎无法分离。有了成文的天花板,分离就变成机械操作:范围内项目上的提升按定义就是”利用”,范围外项目上的提升才是真正的”获取”。这篇论文报告的是前者,没有后者。
框架转变
之前(主流方法):                   之后(本文方法):

  人类写过的一切                       课程天花板
  [........................]           [___ <= 五年级 ___]
             |                                  |
             v                                  v
        大模型                              50 亿模型
             |                                  |
   ? 它本来知道什么                     已知上界,
   ? 它刚学到什么                       用自然语言写下来
             |                                  |
             v                                  v
      事后取证                          可控注入
   (去重、探针、争论)                  (加入 X,测量 X)
             |                                  |
             v                                  v
   "大概没被污染吧"                    "X 超纲,标准在这儿"
一句话:从事后取证到实验设计,核心转变是把控制点从训练之后挪到训练之前——你不再试图证明一个关于语料库的否命题,而是直接造一个把否命题写在开头的语料库。
专家评审
先说校准前提:我主要依据摘要和所描述的产出物做判断,没有审计过语料库本身。我下面标出的疑点,恰好就是我最想核查的东西。
选题眼光:真缺口,而且正在变得更紧迫而不是更缓和。
随着预训练语料逼近”所有可得文本”,每一个知识编辑、持续学习、能力涌现的结论都变得更难辩护。
这篇论文处在一条清晰的轨迹上——BabyLM 证明了受控范围预训练在科学上有产出,TinyStories 证明了小模型能在窄世界里保持流畅,这篇把同一逻辑推到模型足以作为实验对象的规模。
选择教学阶段边界而不是主题边界或时间边界,是真的巧:学校标准是一套既存的、外部维护的、经过社群审议的分类体系。
作者不必自己发明本体论——而这通常正是这类项目的死因。
我的保留:五年级是美国州级教育政策的产物,不是认知或语言学上的自然接缝。
它可解释,这是被宣称的性质;但它同时是任意的,这会让跨语言、跨文化的扩展变得很乱。
而且概念-词汇边界本身相当模糊——大量五年级材料会指向那些要到很晚才被形式化的观念。
方法成熟度:坦白说,这是数据工程加一个好想法。
过滤大概是分类器驱动的,而整个科学价值都压在过滤器对超纲内容的召回率上——一个在 880 亿 token 上极难给出上界的量。
精确率失效只是让语料变小;召回率失效会无声地污染每一个下游实验。
我希望看到激进的对抗性审计:请人专门去找超纲内容,然后报告有多容易找到。
还有第二个我希望被明确回应的担忧:880 亿 token 的学龄适配文本从哪来?
真实的 K-5 材料不存在这个量级。
要么是对通用网页文本做重度过滤(那么召回率问题变得非常尖锐——隐含的超纲框架能躲过抓显式主题的过滤器),要么是前沿模型合成或改写。
如果是后者,生成模型的超纲知识会以分布结构的形式渗进来,即使一个禁用词都没出现。
这是一条隐蔽、难检测的污染通道,会直接削弱核心保证。
实验诚意:摘要自己的措辞——“用第一批实验展示沙盒的效用”——已经告诉你演示是刻意初步的。
对资源型论文这没问题,但它把重量全压在了资源本身必须无懈可击上。
那个负面结果需要小心处理。
“ICL 抬不起超纲能力”只有在你排除了所有无聊解释之后才有意思:上下文不足、提示格式不对、模型小到根本就不太会 ICL。
一个在简单文本上训练的 50 亿模型可能全面 ICL 能力都很弱,那么这个结果会因为极其无趣的原因出现。
我最想看到的对照是:同 token 预算下,在未过滤文本上训练的 50 亿模型。
没有它,你无法把平坦的曲线归因于范围限制,而不是归因于规模、语料简单性、或模型整体偏弱。
这个对照存在与否,是我打开全文第一件要找的事。
写作功力:偷懒的地方就在摘要的模糊措辞里。
“足以支持开放式评测的语言能力”和”清晰的知识与能力边界”都是承重断言,却以陈述句的形式给出。
最能把整篇论文提一档的,是一章严格的过滤器验证:对抗性审计结果、按领域估计的泄漏率、诚实说明五年级这条线在哪些地方根本无法执行、以及清晰交代语料来源构成。
对资源型论文来说,那一章就是贡献;注入实验只是 demo,而 demo 是可替换的。
判决:弱接收 —— 框架确实有用、产出物会被用起来,但核心保证的强度只等于一个未经验证的过滤器,而配套实验薄到让论文的成败全押在摘要没有着重强调的语料审计上。
要点总结
值得偷走的东西:
借用已有的人类分类体系,别自己发明本体论。
让这个项目变得可行的关键一步,是把学校标准当成现成的、外部维护的、人类可读的范围规格。
同样的招数可以推广:用医学培训大纲控制临床模型范围,用学徒进阶体系控制工具使用,用职业认证考纲控制专业领域,用 CEFR 之类的语言能力框架做分级语言能力。
任何有”第 N 阶段应该掌握什么”成文文件的领域,都有一套免费本体论摆在那里。
大多数研究者一伸手就去做 embedding 和聚类,而某个认证委员会早就把活干完了。
在训练之前定义你的负空间,而不是训练之后。
可推广的方法论是:选一条边界,用陌生人能核查的语言写下来,过滤到它,然后针对这些成文的空缺做注入实验。
这远不止适用于课程——时间截断、语言排除、领域排除都一样。
重点不是那条具体的边界,而是造出”模型从未见过 X”是设计规格而非事后祈祷的语料库。
流畅度和知识的扩展规律不同,你可以利用这个缝隙。
LittleLearner 证明了两者可以解耦:成年人的语法配小学生的知识库。
如果你在造一个评测对象,这是一个有用的设计参数——研究推理、格式、校准、指令跟随,你可能并不需要一个知识丰富的模型。
一个更便宜、范围更紧的模型可以是更好的仪器,恰恰因为你知道它不知道什么。
那个负面结论才是实用价值最高的部分。
如果它在合适的对照下站得住,“ICL 和轻量后训练提升利用率但不扩张能力边界”对任何部署 RAG 或做微调的人都是直接可行动的。
检索给你的模型事实;它不给模型使用这些事实所需的推理底座。
如果模型做不了那个底层操作,把答案塞进上下文救不了它。
大多数团队都是花了大钱才学到这一课。
关于沙盒本身的提醒:在 LittleCurriculum 上盖研究之前,先查语料来源和过滤器验证数据。
如果相当比例是前沿模型合成的,“已知天花板”这个保证会比宣传的弱,而依赖它的实验会继承这份弱点。