Paper: 2603.11047 Authors: Jen-Hao Rick Chang, Xiaoming Zhao, Dorian Chan, Oncel Tuzel Categories: cs.CV, cs.AI, cs.GR
The Gap
3D generation has been on a tear lately — NeRF, 3DGS, and their descendants can reconstruct geometry with impressive fidelity. But there’s a quiet embarrassment in the field: almost everything assumes diffuse surfaces. Lambertian shading, view-independent color, flat-lit objects. The moment you put a ceramic mug, a wet leaf, or a metallic car door in front of these systems, the output looks like a matte clay model. The specular highlight that tells your brain “this is shiny” just isn’t there.
Why? Because most 3D generative models learn a latent space from RGB images or depth maps independently, then bolt on appearance as a secondary concern. Methods like Zero123, One-2-3-45, and similar single-image-to-3D pipelines either ignore view-dependent effects entirely or approximate them with environment maps that don’t generalize. The core issue is representational: if your latent space was never designed to hold “how this surface looks from angle X under lighting Y,” you can’t generate it.
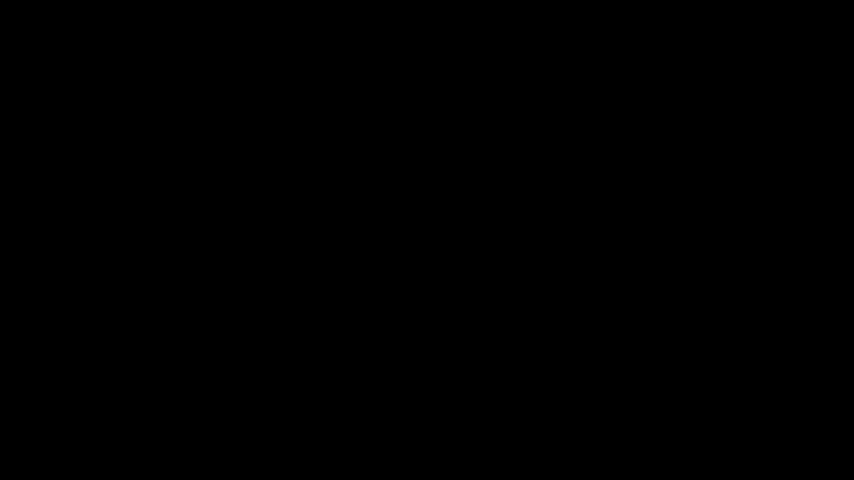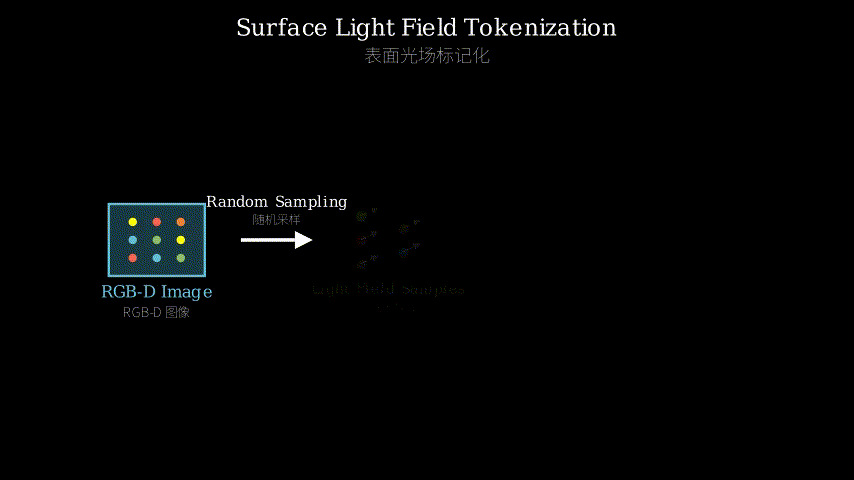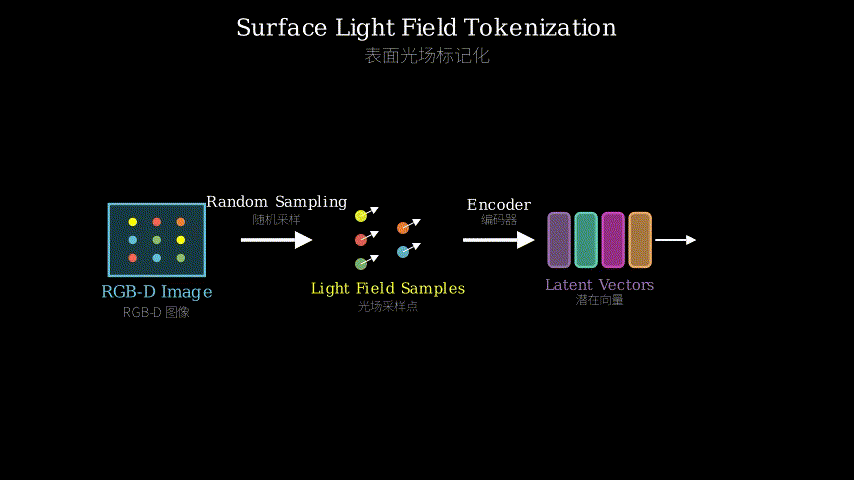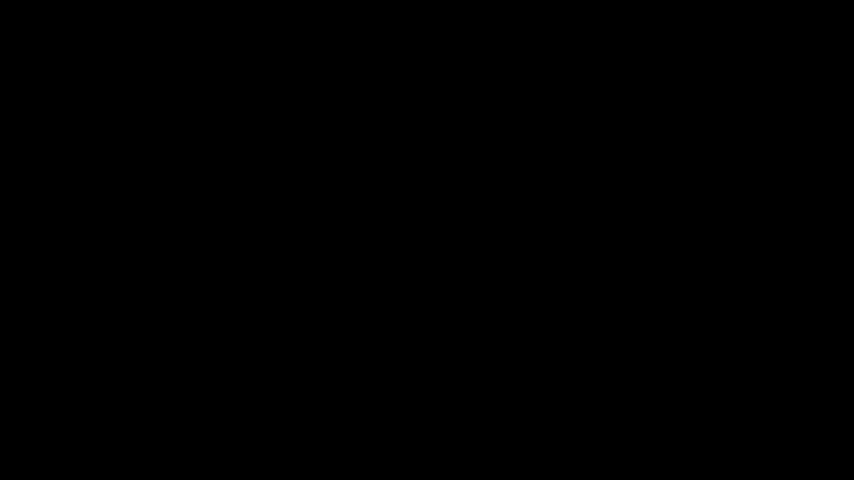
LiTo’s insight is that RGB-D images (color + depth) are actually samples of something richer — a surface light field. Every pixel in an RGB-D image is a measurement of radiance at a surface point from a specific viewing direction. If you treat your training data that way, you can build a latent space that natively encodes view-dependent appearance alongside geometry.
Problem: 3D generation ignores view-dependent appearance
    |
    v
Assumption: RGB-D frames = samples of a surface light field
    |
    v
Method: Encode random SLF subsamples -> compact latent vectors
    |                                    |
    |                                    v
    |                          Latent flow matching
    |                          conditioned on single image
    v
Evidence: Better specular/Fresnel reproduction vs Zero123,
          One-2-3-45, and other baselines on visual quality
          + input fidelity metrics
    |
    v
Conclusion: Unified geometry+appearance latent space is
            achievable and improves single-image 3D generation
The Increment
One sentence: Before LiTo, single-image 3D generation produced matte clay objects; after LiTo, it produces objects that actually look like the material in the photo.
Core Mechanism
The pipeline has three interlocking pieces. First, a surface light field (SLF) encoder takes random subsamples of RGB-D observations — think of it as grabbing a handful of (position, direction, color) tuples from your training views — and compresses them into a fixed-size set of latent vectors using a cross-attention transformer. The key move here is that the encoder sees random subsets at training time, which forces it to learn a representation that’s robust to missing views rather than memorizing a fixed camera arrangement.
Second, those latent vectors live in a shared 3D latent space that jointly encodes geometry and appearance. This isn’t two separate heads bolted together — the geometry and the view-dependent color are entangled in the same token set. A decoder can then render novel views by querying this latent space with a target camera ray, producing both depth and view-dependent RGB.
Third, a flow matching model learns the distribution over these latent vectors conditioned on a single input image. Flow matching (a cleaner cousin of diffusion) learns to transport a simple noise distribution to the learned SLF latent distribution. At inference, you give it one photo, it samples from the conditioned distribution, and you get a full 3D object with consistent lighting and material response.
Input: single RGB image
    |
    v
Flow Matching Model (conditioned on image features)
    |
    v
Sampled latent token set  <-- also trained via:
    ^                         random RGB-D subsamples
    |                         from multi-view data
    |                              |
    +-- SLF Encoder ---------------+
        (cross-attention over
         position+direction+color tuples)
    |
    v
SLF Decoder
    |
    +-- query with target ray --> depth + view-dependent RGB
    |
    v
Novel view with specular highlights, Fresnel effects
Think of it like a wine sommelier’s memory. A sommelier doesn’t memorize every bottle they’ve ever tasted — they build an internal model of “what this grape variety does under these conditions.” When they taste a new wine, they don’t need the full bottle history; a few sips from different angles (temperature, aeration, pairing) are enough to reconstruct the full profile.
LiTo’s encoder is the sommelier’s palate: it takes a few random “sips” of the surface light field (random RGB-D samples from different viewpoints) and compresses them into a compact internal model. The latent tokens are the sommelier’s mental notes — they encode both the structure (“this is a Burgundy-shaped tannin profile”) and the appearance (“it’ll show differently in a warm glass vs a cold one”). The flow matching model is the sommelier’s ability to reconstruct a full tasting profile from just seeing the label — one image in, full 3D material model out.
The load-bearing part of this metaphor: just as a sommelier trained on random sips generalizes better than one who only ever tasted full bottles in sequence, LiTo’s random subsample training forces the encoder to learn view-invariant geometry and view-dependent appearance simultaneously, rather than overfitting to a fixed camera rig.
Key Concepts
-
Surface Light Field (SLF): A regular light field records radiance as a function of position and direction anywhere in space. A surface light field restricts this to surface points — for every point on an object’s surface, it records how much light leaves in every direction. This is exactly what makes a ceramic mug look different from a matte clay mug: the ceramic has a surface light field where certain directions get a bright specular spike, while the clay’s SLF is nearly uniform. RGB-D images are sparse samples of this function — each pixel gives you one (surface point, viewing direction, radiance) measurement. LiTo’s core bet is that if you treat your data this way, you can learn to interpolate the full SLF from a handful of samples.
-
Flow Matching: Diffusion models learn to denoise; flow matching learns to transport. You define a straight-line path (a “flow”) from a noise sample to a data sample, and train a neural network to predict the velocity field along that path. At inference, you integrate the velocity field from noise to data. It’s cleaner than diffusion (no noise schedule tuning, fewer NFE at inference) and has been gaining traction as the backbone for generative models. Here it’s used to learn the distribution over SLF latent codes conditioned on an image — so the model learns “given this photo, what’s the probability distribution over plausible 3D objects with matching appearance?”
-
Cross-Attention Encoding of Unordered Sets: The SLF encoder needs to compress a variable-size, unordered set of (position, direction, color) tuples into a fixed-size latent. Cross-attention handles this naturally — the latent tokens act as queries, the SLF samples act as keys/values, and the attention mechanism aggregates information regardless of input order or count. This is what makes the random subsample training trick work: the encoder sees 50 samples one time, 200 another time, in random order, and learns to produce consistent latents regardless.
Framework Shift
Before (mainstream approach):        After (this paper):

  Image(s)                             Image(s)
     |                                    |
     v                                    v
  Geometry                         Flow Matching Model
  Reconstruction                          |
     |                                    v
     v                             SLF Latent Tokens
  Diffuse Color                    (geometry + appearance
  (view-independent)                jointly encoded)
     |                                    |
     v                                    v
  3D mesh / NeRF                   Novel View Render
  (matte, flat)                    (specular, Fresnel,
                                    material-consistent)

  Appearance = afterthought         Appearance = first-class
  Geometry and color = separate     Geometry and color = unified
  View-dependence = ignored         View-dependence = native
From treating appearance as a post-hoc texture to treating it as a native dimension of the 3D representation, the core shift is: RGB-D data is a light field sample, not just a geometry signal.
Expert Assessment
Problem choice: This is a real gap, not a manufactured one. The field has been quietly embarrassed by matte outputs for years, and the reason is structural — most 3D latent spaces were designed around geometry benchmarks where view-dependence doesn’t matter. LiTo is attacking the right problem at the right time, as the community starts caring about photorealistic generation rather than just shape reconstruction.
Method maturity: The insight (RGB-D = SLF samples) is genuinely clever and underexplored. The execution — cross-attention encoder + flow matching — is solid engineering on top of that insight, not brute force. That said, the random subsample training trick isn’t entirely new (it echoes NeRF’s ray sampling and set-based encoders like PerceiverIO), so the novelty is more in the application than the components. A skeptic could ask: why not just train a NeRF with a specular BRDF head? The answer is probably “generalization and generation,” but the paper should make that case more explicitly.
Experimental integrity: The abstract claims “higher visual quality and better input fidelity than existing methods” — fair enough if the baselines include Zero123 and One-2-3-45, which are genuinely weak on specular surfaces. The concern is cherry-picking: specular objects are a favorable test bed for this method, and it’s worth checking whether the gains hold on diffuse objects too (where the baseline methods are more competitive). Without seeing the full paper, the metrics (PSNR, LPIPS, presumably) on a diverse object set would be the thing to scrutinize.
Writing quality: The abstract is clean but undersells the SLF framing — “RGB-depth images provide samples of a surface light field” is the key insight and it’s buried in the middle. The introduction probably spends too long on NeRF history and not enough on why the SLF perspective is the right lens. If I were rewriting one section, it’d be the motivation: lead with a concrete failure case (here’s a shiny mug, here’s what every prior method produces, here’s why), then introduce SLF as the natural fix.
Verdict: weak accept — the core insight is sound and the problem is real, but the paper needs to work harder to distinguish itself from “NeRF with a fancier appearance model” and to show that gains aren’t limited to the favorable specular test cases.
Takeaways
The most transferable idea here is the random subsample encoding trick: if you have data that’s naturally a set of samples from some function