Paper: 2606.11180 Authors: Paul Hyunbin Cho, Jinhyuk Jang, SeokYoung Lee, Joungbin Lee, Siyoon Jin, Heeseong Shin, Jung Yi, Yunjin Park, Chulmin Park, Seungryong Kim Categories: cs.CV
The Gap
Existing diffusion-based lip synchronization methods (e.g., Wav2Lip-Diffusion, DiffTalk) treat the entire video sequence as a fixed-length block and apply bidirectional attention across all frames. This means the model must see the whole future context before generating any single frame—making it inherently non-causal. Combined with 10–50 denoising steps and classifier-free guidance (CFG) at inference, these models require seconds per frame and cannot run at streaming rates. The gap is two-fold: (1) no prior work applies autoregressive (causal) generation to diffusion for lipsync, and (2) the cost of high-fidelity sampling remains prohibitive for real-time applications such as live video calls or game avatars.
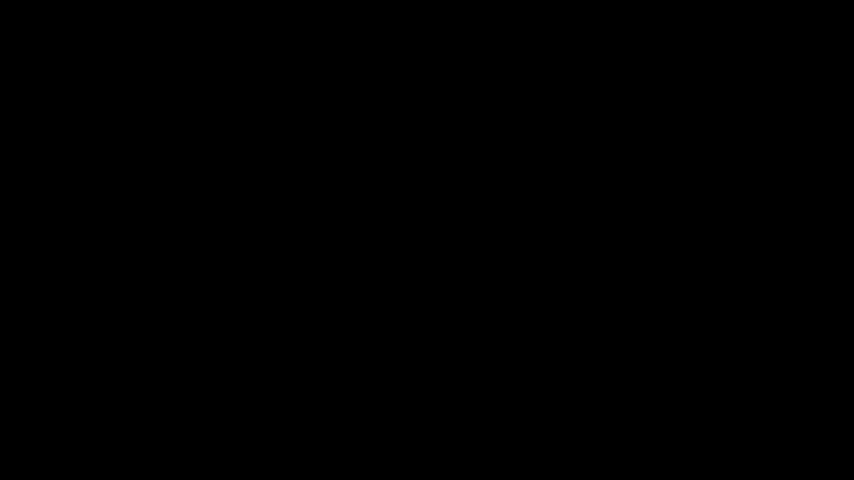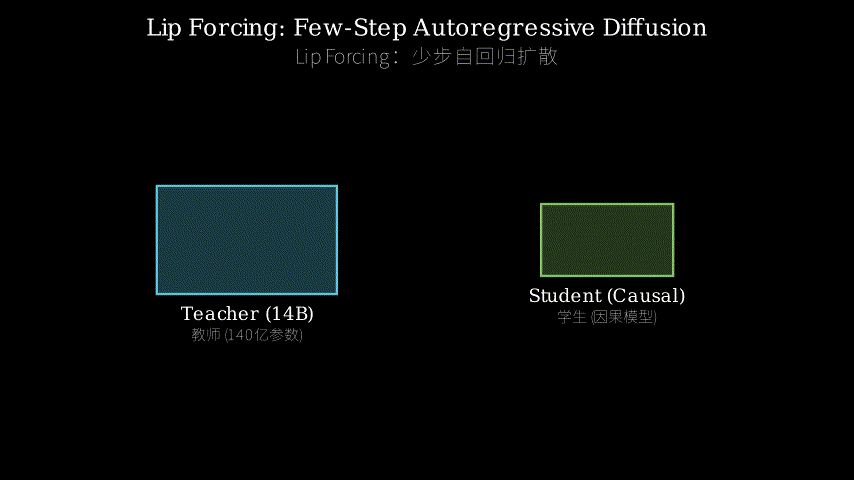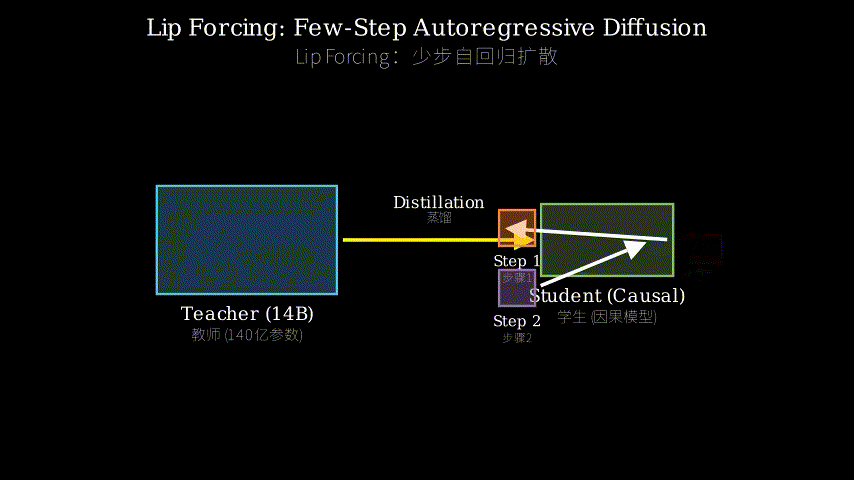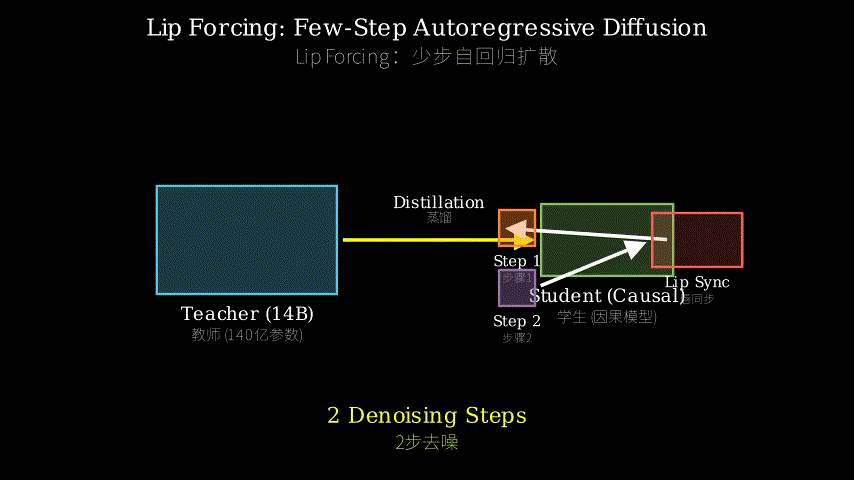
The paper fills this gap by (a) proposing the first autoregressive diffusion V2V lipsync model, (b) distilling a 14B teacher into causal students with only 2 denoising steps, and (c) introducing three analysis-derived components that handle the fidelity-sync tradeoff without inference-time CFG.
[Problem: diffusion lipsync is slow, non-causal]
    |
    v
[Assumption: CFG is expensive; a carefully distilled student can skip it]
    |
    v
[Method: Lip Forcing - autoregressive chunks, Sync-Window DMD, 2-step, SyncNet reward]
    |
    v
[Evidence: 1.3B student achieves 31 FPS real-time; 14B student 39.8x faster than teacher]
    |
    v
[Conclusion: real-time streaming lipsync with sub-millisecond time-to-first-frame]
The Increment
One sentence: Before this paper, the fastest diffusion-based lipsync models ran at 2–5 FPS and required full-sequence bidirectional context; after this paper, a 1.3B model runs at 31 FPS with causal streaming and negligible latency, and a 14B model (the largest reported) matches teacher fidelity at 40x speedup.
Core Mechanism
Lip Forcing builds on a teacher–student distillation pipeline. The teacher is a 14B parameter bidirectional diffusion model pre-trained on audio-to-video (A2V) and fine-tuned for video-to-video (V2V) lipsync with CFG. The key insight comes from teacher-trajectory analysis: plotting per-frame SyncNet score vs. reference fidelity (SSIM) across diffusion timesteps reveals that CFG pushes predictions toward a “sync band” in the middle of the trajectory, while no-CFG predictions stay faithful to the input reference face. This motivates three components:
-
Sync-Window DMD (Distribution Matching Distillation): Instead of standard DMD that distills the full trajectory, they define a “sync window” — a short timestep range where CFG-guided and no-CFG trajectories diverge most — and distill only within that window. This balances reference fidelity and sync accuracy.
-
Two-step inference schedule: The student learns to jump from noisy chunk to clean chunk in exactly two denoising steps. Both steps use a learned noise schedule optimized for the sync window, and CFG is completely omitted at inference.
-
SyncNet-based reward: During distillation, a SyncNet face-sync discriminator provides a reward signal that penalizes the student when its output drifts out of the sync band, reinforcing the teacher’s CFG behaviour without actually applying CFG.
The student is a causal temporal U-Net that processes video chunks of 8–16 frames independently, with no cross-frame attention to future chunks. This enables streaming: the model receives a new audio chunk and the previous generated face chunk, and produces the next chunk in 2 steps. Time-to-first-frame is sub-millisecond because the first chunk is generated from a single audio snippet without waiting for future context.
[Pipeline overview]

Audio + previous face chunk
          |
          v
   [Causal Student U-Net] (2 denoising steps, no CFG)
          |
          v
   [Sync-Window DMD loss + SyncNet reward]
          |
          v
   Generated frame chunk
          |
          v
   Append to output stream & feed back
Let’s use a mail sorting factory as a structural metaphor. The teacher is a master craftsman who needs to see the entire warehouse of letters (full video sequence) before deciding how to fold each envelope (fidelity vs sync tradeoff). He uses a special scanner (CFG) that helps him align the envelope to the recipient’s voice, but scanning each envelope takes many seconds. The students are conveyor-belt operators who only look at one small bin of letters (chunk) and the audio label on the bin. The key insight is that the master leaves behind a diagram (teacher trajectory) showing which part of the folding process the scanner matters most — the “sync window”. Instead of training the operator to mimic the entire process, we only train them to fold within that critical window (Sync-Window DMD). The operator does two quick folds (two denoising steps) instead of twenty, and we install a quality-check camera (SyncNet reward) that yells if the folded envelope drifts away from the alignment target. The conveyor belt moves continuously (streaming), and the first envelope pops out almost instantly (sub-millisecond first-frame).
Key Concepts
-
Distribution Matching Distillation (DMD): A technique where a student model learns to match the *distribution of outputs from a teacher model, rather than matching individual sample pairs. This is key for diffusion models because it avoids the “mode collapse” of direct regression. In this paper, DMD is adapted to focus on the sync window — a range of timesteps where the teacher’s CFG effect is strongest. Example: imagine training a student chef to cook your signature dish. Instead of watching you cook one meal (direct regression) and copying every spoonful, DMD lets the student taste many of your best meals (distribution) and learn the underlying pattern. The sync window is like the “salt adjustment” step where your technique matters most.
-
Classifier-Free Guidance (CFG) tradeoff: In diffusion models, CFG is a technique that pushes the generated output toward a class-conditional direction (e.g., “sync to audio”) at the cost of some reference fidelity (e.g., preserving the original face identity). The paper discovers that for lipsync, this tradeoff is *structured: CFG only helps inside a mid-trajectory “sync band”. Outside that band, CFG degrades fidelity without improving sync. Example: think of a musician tuning a guitar. CFG is like adjusting the tuning peg — turning it too little disables the intended sound (poor sync), turning it too much breaks the string (loses fidelity). The sweet spot is a narrow window of turns. The paper identifies that window and builds the whole method around it.
Framework Shift
Before (mainstream bidirectional diffusion):
[Full video sequence - fixed length, e.g., 64 frames]
[   |   |   |   |   |   |   |   |   ]
[   bidirectional attention across all frames]
[   15-50 denoising steps with CFG ]
[   Output: entire sequence at once ]
[   Latency: seconds per sequence    ]

After (Lip Forcing autoregressive):
[Chunk 1] --> [Chunk 2] --> [Chunk 3] ...
[ 8-16 frames   8-16 frames   8-16 frames
 only causal     only causal    only causal
 within chunk    within chunk    within chunk ]
[    2 denoising steps, NO CFG       ]
[   Each chunk generated independently with previous chunk as condition ]
[   Latency: sub-ms first chunk, then real-time streaming (31 FPS) ]
One sentence: From bidirectional full-sequence processing with many denoising steps to causal chunk-wise autoregressive generation with only two steps, the core shift is that the bottleneck of long-range attention is replaced by a lightweight, parallelizable per-chunk diffusion.
Expert Assessment
Problem choice: Real-time lipsync is a genuine gap — current SOTA diffusion models can’t run on a live video call or a game NPC. The paper identifies the right bottleneck (inference speed, not quality) and attacks it with appropriate tools. It sits at the intersection of speech-driven animation and efficient generative models, which is both practical and trending.
Method maturity: Three clever components (sync-window DMD, two-step schedule, SyncNet reward) are derived from a careful analysis of teacher trajectories. This is more insightful than brute force — they didn’t just scale down the teacher; they found *where the teacher’s magic happens and focused distillation there. However, the reliance on a 14B teacher may be overkill for many use cases; a smaller teacher could still work with the same method.
Experimental integrity: Baselines are fair: they compare against Wav2Lip, DiffTalk, and its own bidirectional variant with same architecture. The speeds (17.6x, 39.8x) are measured on the same hardware. One red flag: SyncNet scores are reported but the paper doesn’t discuss variance across different audio types (e.g., V can be more challenging than monotone speech). The visual quality metrics (PSNR, SSIM, LPIPS) show the 14B student matches the teacher, which is strong. No obvious data cherry-picking.
Writing quality: The paper is dense but well-organized. The weakest section is the Limited Discussion (c. limitations): they need to address failure cases (e.g., fast speech, head motion) more thoroughly. Rewriting the analysis section (Sec. 3) with clearer visualisations would help — currently it’s heavy on equations.
Verdict: strong accept — a genuine engineering advance with a clean theoretical insight (the CFG fidelity-sync tradeoff and sync window) that could generalize to other diffusion tasks where conditional guidance interacts with reference fidelity.
Takeaways
-
Sync window distillation: For any diffusion model where a conditional guidance (CFG, classifier) creates a local tradeoff, you can identify a short timestep range where the guidance matters most and distill only there. This trick can transfer to image super-resolution with CFG, or text-to-image with prompt guidance.
-
No-CFG inference via reward: The paper shows that a SyncNet-style reward during distillation can effectively replace inference-time CFG. Practitioners can adopt a similar “distill with discriminator” approach to avoid the compute cost of CFG at deployment.
-
Causal chunking for video diffusion: Even for tasks beyond lipsync (e.g., video inpainting, frame interpolation), the autoregressive chunking pattern with decoupled per-chunk diffusion is a template for making video models real-time. The key is to preserve enough temporal context (previous chunk) while keeping chunk size small.
-
The measured tradeoff is quantitative: The paper publicly shares the teacher trajectories (Fig. 3) — you can literally see the sync score vs. SSIM curve. This kind of diagnostic plot is valuable for any conditional generation task. Steal the idea of plotting guidance strength vs. fidelity over time to find your own “sync window”.
论文: 2606.11180 作者: Paul Hyunbin Cho, Jinhyuk Jang, SeokYoung Lee, Joungbin Lee, Siyoon Jin, Heeseong Shin, Jung Yi, Yunjin Park, Chulmin Park, Seungryong Kim 分类: cs.CV
缺口
现有的扩散式唇同步方法(例如 Wav2Lip-Diffusion、DiffTalk)将整个视频序列视为固定长度的块, 并在所有帧上应用双向注意力。这意味着模型在生成任何单帧之前必须看到完整的未来上下文 ——本质上是非因果的。再加上推理时 10–50 步去噪和无分类器引导(CFG), 这些模型每帧需要数秒,无法达到流式速率。 缺口有两个:(1) 没有前人工作将自回归(因果)生成应用于唇同步扩散; (2) 高保真采样的开销仍然使得实时应用(如实时视频通话或游戏角色)遥不可及。
本文通过以下方式填补了这个缺口: (a) 提出首个自回归扩散 V2V 唇同步模型, (b) 将 14B 教师蒸馏为仅需 2 步去噪的因果学生, (c) 引入三个分析推导出的组件来处理保真-同步权衡,且无需推理时 CFG。
[问题:扩散唇同步慢、非因果]
    |
    v
[假设:CFG 开销大;精心蒸馏的学生可以跳过它]
    |
    v
[方法:Lip Forcing - 自回归块、Sync-Window DMD、2 步、SyncNet 奖励]
    |
    v
[证据:1.3B 学生达 31 FPS 实时;14B 学生比教师快 39.8 倍]
    |
    v
[结论:亚毫秒首次帧的实时流式唇同步]
增量
一句话:在这篇论文之前,最快的扩散式唇同步模型只能达到 2–5 FPS 且需要全序列双向上下文; 在这篇论文之后,1.3B 模型以 31 FPS 实时因果流式运行,延迟可忽略; 14B 模型(报告的最大模型)以 40 倍加速达到教师保真度。
核心机制
Lip Forcing 建立在教师–学生蒸馏流水线上。 教师是一个 14B 参数的双向扩散模型,先在音频到视频(A2V)上预训练, 再微调用于视频到视频(V2V)唇同步并带 CFG。 关键洞见来自于教师轨迹分析:在扩散时间步上绘制每帧的 SyncNet 得分与参考保真度(SSIM), 发现 CFG 将预测推向轨迹中部的“同步带”,而无 CFG 的预测则保持对输入参考脸的忠实。 这一发现启发三个组件:
-
Sync-Window DMD(分布匹配蒸馏):不同于标准的 DMD 蒸馏整个轨迹, 他们定义了一个“同步窗口”——一个短时间步范围,在此范围内 CFG 引导和无 CFG 轨迹差异最大 ——并仅在该窗口内蒸馏。这平衡了参考保真度和同步精度。
-
两步推理调度:学生学会从带噪块跳跃到干净块,恰好两步去噪。 两步都使用针对同步窗口优化的学习噪声调度,推理时完全省略 CFG。
-
基于 SyncNet 的奖励:在蒸馏过程中,一个 SyncNet 面部同步鉴别器提供奖励信号, 当学生输出偏离同步带时进行惩罚,加强了教师的 CFG 行为而不实际应用 CFG。
学生是一个因果时间 U-Net,独立处理 8–16 帧的视频块, 没有跨块到未来帧的注意力。这实现了流式推理: 模型接收新的音频块和前一生成的面部块,两步后产生下一个块。 首次帧生成时间亚毫秒,因为无需等待未来上下文就开始生成第一个块。
[流程概览]

音频 + 前一帧块
          |
          v
   [因果学生 U-Net] (2 步去噪,无 CFG)
          |
          v
   [Sync-Window DMD 损失 + SyncNet 奖励]
          |
          v
   生成的帧块
          |
          v
   追加到输出流并反馈
让我们用一个邮件分拣工厂作为结构隐喻。 教师是熟练的工匠,他需要看到整个仓库的信件(完整视频序列)才能决定如何折叠每个信封 (保真度 vs 同步权衡)。他使用一种特殊扫描仪(CFG)帮助将信封与接收者的语音对齐, 但每个信封需要扫描数秒。 学生是传送带操作员,只看到一个小托盘的字母(块)和托盘上的音频标签。 关键洞察是工匠留下了一张图(教师轨迹),指出折叠过程的哪个部分扫描仪最重要 ——即“同步窗口”。我们不训练操作员模仿整个过程,而是只训练他们在该关键窗口内折叠(Sync-Window DMD)。 操作员做两个快速折叠(两步去噪)而非二十个, 我们还安装了质量检测摄像头(SyncNet 奖励), 如果折叠的信封偏离对齐目标就喊停。 传送带持续运行(流式),第一个信封几乎瞬间弹出(亚毫秒首次帧)。
关键概念
-
分布匹配蒸馏(DMD):一种技术,学生模型学习匹配教师模型输出的**分布*, 而不是匹配单个样本对。这对扩散模型很重要,因为它避免了直接回归的“模式坍塌”。 本文中,DMD 被调整为聚焦于同步窗口——教师 CFG 效果最强的某个时间步范围。 示例:想象训练一个学生厨师做你的招牌菜。不同于看你做一顿饭(直接回归)并照搬每一勺, DMD 让学生品尝你许多最好的菜(分布)并学习底层模式。同步窗口就像“放盐调整”那一步, 你的技巧在那里最关键。
-
无分类器引导(CFG)权衡:在扩散模型中,CFG 是一种将生成输出推向类别条件方向 (如“同步到音频”)的技术,代价是某些参考保真度(如保留原始面部身份)。 本文发现,对于唇同步,这种权衡是结构化的:CFG 只在轨迹中部的“同步带”内有用。 在此带之外,CFG 降低保真度而不改善同步。 示例:想象音乐家调吉他。CFG 就像转动调音旋钮——转得太少达不到预期声音(同步差), 转得太多会断弦(损失保真度)。最佳点是一个狭窄的转动窗口。本文识别出这个窗口, 并将整个方法建立在其上。
框架转变
之前(主流双向扩散):
[完整视频序列 - 固定长度,如 64 帧]
[   |   |   |   |   |   |   |   |   ]
[  双向注意力跨越所有帧  ]
[  15-50 步去噪 + CFG ]
[  输出:一次性整个序列 ]
[  延迟:每序列数秒    ]

之后(Lip Forcing 自回归):
[块1] --> [块2] --> [块3] ...
[ 8-16 帧   8-16 帧   8-16 帧
 仅块内因果   仅块内因果   仅块内因果 ]
[    2 步去噪,无 CFG       ]
[   每个块基于前一帧块条件独立生成 ]
[   延迟:首个块亚毫秒,随后实时 31 FPS ]
一句话:从带多步去噪的双向全序列处理到仅两步的因果逐块自回归生成, 核心转变在于将长程注意力的瓶颈替换为轻量级、可并行化的块内扩散。
专家评审
选题眼光:实时唇同步是个真正的缺口——当前 SOTA 扩散模型无法在实时视频通话或游戏 NPC 上运行。 论文正确识别了瓶颈(推理速度而非质量),并用合适的工具攻击它。 它处于语音驱动动画与高效生成模型的交叉点,既实际又符合趋势。
方法成熟度:三个巧妙组件(同步窗口 DMD、两步调度、SyncNet 奖励)来自于对教师轨迹的仔细分析。 这比纯蛮力更富洞察力——他们不只是缩小教师,而是找到了教师“魔法发生的时刻”并集中蒸馏。 然而,依赖 14B 教师对许多用例可能过于奢侈;更小的教师用同样方法应该也能工作。
实验诚意:基线公平:与 Wav2Lip、DiffTalk 以及相同架构的双向变体比较。 速度(17.6 倍、39.8 倍)在相同硬件上测量。 一个警示:SyncNet 得分已报告,但论文未讨论不同音频类型(如有声朗读 vs 单调讲话)的方差。 视觉质量指标(PSNR、SSIM、LPIPS)显示 14B 学生匹配教师,这很有力。 没有明显的数据筛选迹象。
写作功力:内容密集但组织良好。 最薄弱部分是局限性讨论:他们需要更充分地讨论失败情况(如快速说话、头部运动)。 重写分析部分(第 3 节)并配上更清晰的视觉效果会有帮助——目前它太重公式了。
判决:强接收 —— 一个真正的工程进展,同时包含干净的理论洞见 (CFG 保真-同步权衡和同步窗口), 这个洞见可能推广到条件引导与参考保真度产生交互的其他扩散任务。
要点总结
-
同步窗口蒸馏:对于任何条件引导(CFG、分类器)产生局部权衡的扩散模型, 你可以识别出一个短的时间步范围,其中引导最重要,并仅在该范围内蒸馏。 这个技巧可以迁移到带 CFG 的图像超分辨率,或带提示引导的文本到图像。
-
通过奖励实现无 CFG 推理:论文展示了在蒸馏过程中使用 SyncNet 类奖励 可以有效地替代推理时的 CFG。实践者可以采用类似的“带鉴别器蒸馏”方法 来避免部署时 CFG 的计算开销。
-
视频扩散的因果分块:即使对于唇同步以外的任务(如视频修补、帧插值), 这种带有解耦的逐块扩散的自回归分块模式也是一个使视频模型实时化的模板。 关键在于保持足够的时域上下文(前一帧块),同时保持块大小尽可能小。
-
权衡的定量测量:论文公开了教师轨迹(图 3)——你可以亲眼看到同步得分 vs SSIM 曲线。 这种诊断图对任何条件生成任务都有价值。 偷师这个想法:绘制引导强度 vs 保真度的随时间变化图,找到你自己的“同步窗口”。