Paper: 2605.31598 Authors: Cristobal Eyzaguirre, Jiajun Wu, Juan Carlos Niebles Categories: cs.CV
The Gap
Video vision-language models process long videos using spatiotemporal self-attention, which scales quadratically with frame count. Existing efficiency methods—aggressive frame dropping, sliding windows, or coarse attention approximations—trade accuracy for speed. The field has reached a point where models can handle long videos, but deployment in streaming or real-time settings remains impractical due to compute and latency constraints. Prior work either accepts the quadratic cost or sacrifices too much accuracy when approximating full attention.
Problem: Quadratic scaling in video VLMs
   |
   v
Existing solutions: Frame dropping / Sliding windows / Attention approximation
   |
   +---> Trade accuracy for efficiency
   |
   v
Gap: Can we achieve linear scaling WITHOUT losing accuracy?
   |
   v
Assumption: Cross-frame context can be compressed into fixed-size state
   |
   v
Method: StateKV (importance-based recurrent state + per-frame cache)
   |
   v
Evidence: Matches full attention, beats baselines across 3 benchmarks, 7 models
   |
   v
Conclusion: Linear-time video prefill is practical without fine-tuning
The Increment
One sentence: Before this paper, long-video VLMs chose between quadratic compute or accuracy loss; after, they can process videos in linear time while preserving full-attention accuracy through inference-time state compression.
Core Mechanism
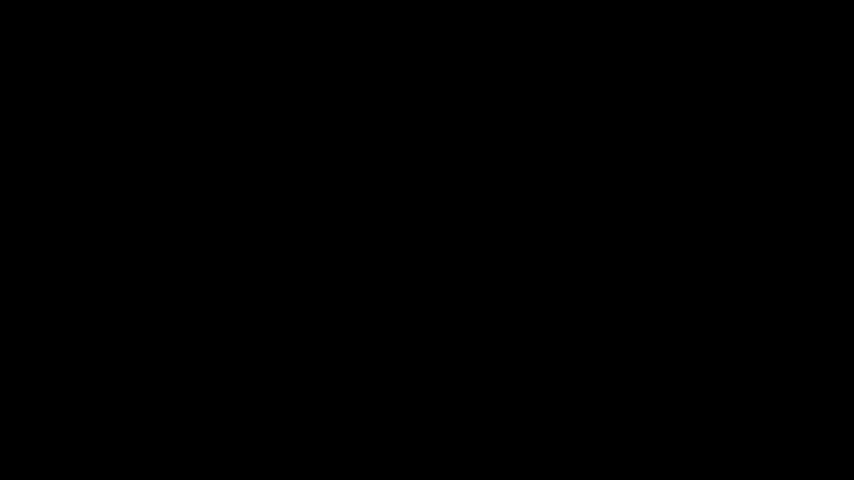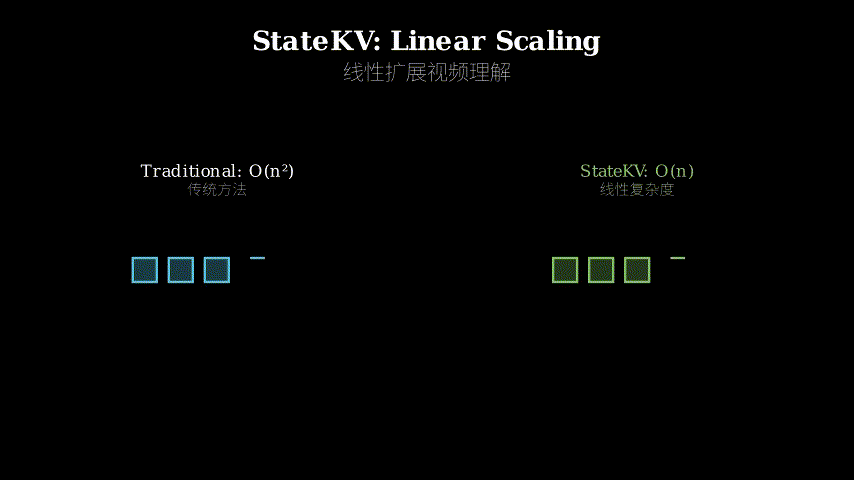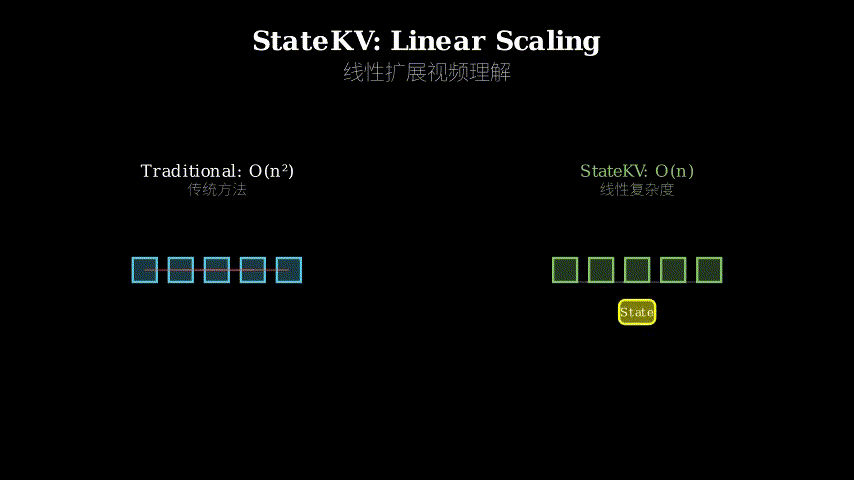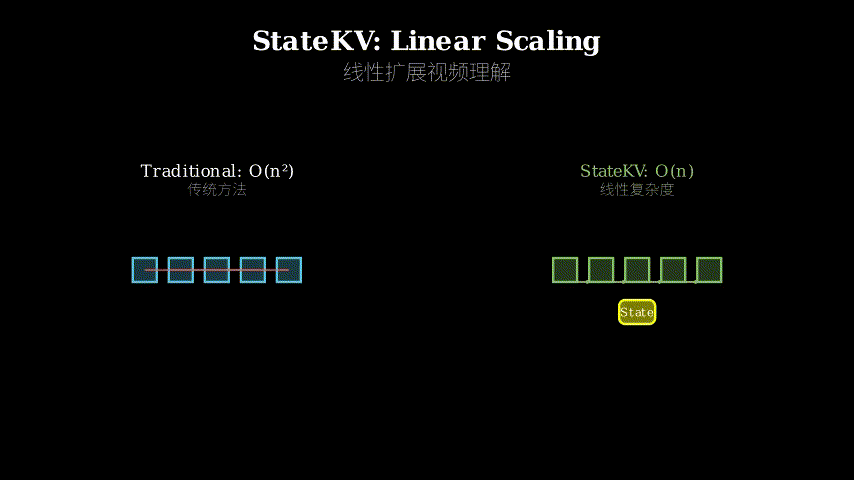
StateKV operates during the video prefill phase—when the model first processes all video frames before generating text. It maintains two separate caches: a fixed-capacity recurrent state that carries compressed cross-frame context forward, and a full per-frame cache used during text generation.
The recurrent state works by selecting the most important key-value pairs from each frame based on attention scores, evicting less important entries when capacity is reached. As each new frame arrives, the model attends to both the recurrent state (containing compressed history) and the current frame’s full tokens. Important tokens from the current frame are then merged into the recurrent state for future frames. This creates a rolling window of compressed context that grows linearly with video length rather than quadratically.
During text decoding, the model switches to using the full per-frame cache, ensuring no information loss when generating responses. The recurrent state is only used for video-to-video attention during prefill, not for text generation.
Video Frames:  [F1] --> [F2] --> [F3] --> ... --> [Fn]
                 |        |        |               |
                 v        v        v               v
              +-----+  +-----+  +-----+         +-----+
Prefill:      | Attn|  | Attn|  | Attn|   ...   | Attn|
              +-----+  +-----+  +-----+         +-----+
                 |        |        |               |
                 v        v        v               v
            [Recurrent State: Fixed Capacity]
            [Select top-K KV pairs by importance]
            [Evict low-importance entries]
                 |
                 +---> Compressed cross-frame context
                 |
                 v
            [Per-frame Cache: Full KV for decoding]
                 |
                 v
              Decode text tokens using full cache
Think of StateKV like a news editor covering a multi-day event. The recurrent state is the editor’s running summary—each day, they read new developments (current frame), update their mental model by keeping the most important facts (importance-based selection), and discard minor details to avoid cognitive overload (fixed capacity). The per-frame cache is the full archive of daily reports. When writing the final article (text generation), the editor consults the complete archive, not just the summary. The summary’s job is to help the editor understand each new day’s events in context, not to replace the archive.
Key Concepts
-
Recurrent State with Importance-Based Eviction: Traditional attention keeps all past tokens, causing quadratic growth. StateKV maintains a fixed-size buffer of key-value pairs, selecting which to keep based on attention scores from the current frame. When a new frame arrives and the buffer is full, the least-attended tokens are evicted. This is like a cache replacement policy, but for semantic importance rather than recency. Concretely: if the buffer holds 1000 KV pairs and frame 50 generates 200 new important tokens, the 200 least-important existing tokens are dropped. The buffer size stays constant, so compute scales linearly.
-
Dual-Cache Architecture: StateKV uses two separate caches with different purposes. The recurrent state (small, compressed) is used only during video prefill to propagate cross-frame context. The per-frame cache (large, complete) stores all tokens from all frames and is used during text decoding. This separation allows linear-time video processing without sacrificing generation quality. The recurrent state answers “what context do I need to understand the next frame?” while the per-frame cache answers “what information do I need to generate accurate text?”
-
Inference-Time Adaptation: StateKV requires no fine-tuning or architectural changes. It’s a drop-in replacement for the attention mechanism during inference. The pretrained model’s weights remain frozen; only the KV cache management strategy changes. This is powerful because it means any existing video VLM can be adapted immediately. The model never “knows” it’s using compressed context—from its perspective, it’s still doing standard attention, just with a different set of cached tokens.
Framework Shift
Before (Full Self-Attention):        After (StateKV):

Video frames:                        Video frames:
[F1][F2][F3]...[Fn]                 [F1][F2][F3]...[Fn]
  |   |   |      |                    |   |   |      |
  +---+---+------+                    v   v   v      v
  |                                 [Recurrent State]
  v                                 [Fixed capacity]
[All-to-all attention]              [Importance-based]
[Quadratic: O(n^2)]                      |
  |                                      v
  v                                [Selective attention]
[Full KV cache]                    [Linear: O(n)]
[Memory: O(n^2)]                        |
  |                                     v
  v                                [Per-frame cache]
[Decode]                           [Full KV for decode]
                                        |
                                        v
                                   [Decode]
From exhaustive cross-frame attention to selective context propagation, the core shift is replacing quadratic all-to-all dependencies with linear importance-filtered recurrence.
Expert Assessment
Problem choice: This is a real deployment bottleneck, not a manufactured gap. Video VLMs are moving toward streaming and long-horizon applications (robotics, surveillance, video QA), where quadratic scaling is a showstopper. The problem sits at the intersection of model efficiency and practical deployment—a high-value target. The framing is honest: they acknowledge existing efficiency methods and clearly state the accuracy-efficiency tradeoff they’re trying to break.
Method maturity: The core insight—importance-based state compression—is elegant but not groundbreaking. It’s essentially applying cache eviction policies from systems research to attention mechanisms. The dual-cache design is clever: it sidesteps the “lossy compression hurts generation” problem by only compressing during prefill. However, the method is somewhat brute-force in its reliance on attention scores as the sole importance metric. More sophisticated importance measures (gradient-based, uncertainty-based) might yield better compression. The lack of architectural changes is both a strength (easy adoption) and a limitation (can’t co-design the model for this compression scheme).
Experimental integrity: The evaluation is thorough—three benchmarks, seven models, three model families. Baselines are fair: they compare against sliding windows and recency-based methods, which are the dominant streaming approximations. The FLOPs analysis is a nice touch, showing that StateKV enables running larger models at the same compute budget. One red flag: no ablation on state capacity. How sensitive is accuracy to buffer size? The paper doesn’t explore the accuracy-memory tradeoff curve in depth. Also, all experiments are on long-video benchmarks; short-video performance (where full attention is feasible) isn’t reported, so we don’t know if there’s a regression.
Writing quality: The abstract and introduction are crisp. The method section is clear but could use more intuition-building before diving into implementation details. The related work section is thorough but reads like a checklist—it would benefit from a narrative arc showing how prior work led to this approach. The results section is dense with numbers but light on analysis: why does StateKV outperform sliding windows by different margins across models? What patterns emerge? The conclusion is generic and could be cut entirely.
Verdict: weak accept — Solid engineering contribution with clear practical value, but limited conceptual novelty and incomplete exploration of the method’s design space.
Takeaways
Importance-based eviction for attention caches: The idea of using attention scores to decide which KV pairs to keep is transferable beyond video. Any domain with long sequences (audio, genomics, time-series) could apply this. The key insight: not all tokens are equally useful for future context, and you can measure usefulness via attention weights.
Dual-cache pattern for lossy prefill + lossless decode: Compress aggressively during the “understanding” phase, but preserve full information during the “generation” phase. This pattern applies to any encoder-decoder or prefill-decode architecture where generation quality is more critical than encoding speed.
Inference-time adaptation as a deployment strategy: StateKV shows that you can adapt pretrained models to new efficiency constraints without retraining. This is a practical template: identify the bottleneck (quadratic attention), design a drop-in replacement (recurrent state), validate that accuracy holds. The “no fine-tuning required” property is underrated—it means faster iteration and lower deployment friction.
FLOPs-accuracy tradeoff reframing: Instead of “how do we make this model faster?”, ask “what larger model can we run at the same cost?” StateKV’s FLOPs savings enable running bigger models, which often yields better accuracy than running a smaller model faster. This reframing applies broadly: efficiency gains should be evaluated not just as speedups, but as budget reallocation opportunities.
论文: 2605.31598 作者: Cristobal Eyzaguirre, Jiajun Wu, Juan Carlos Niebles 分类: cs.CV
缺口
视频视觉-语言模型使用时空自注意力处理长视频,其计算量随帧数二次方增长。
现有的效率方法——激进的帧丢弃、滑动窗口或粗糙的注意力近似——都在用精度换速度。
该领域已经能让模型处理长视频,但由于计算和延迟限制,在流式或实时场景中部署仍不现实。
先前工作要么接受二次方代价,要么在近似完整注意力时牺牲太多精度。
问题:视频VLM中的二次方扩展
   |
   v
现有方案:丢帧 / 滑动窗口 / 注意力近似
   |
   +---> 用精度换效率
   |
   v
缺口:能否实现线性扩展且不损失精度?
   |
   v
假设:跨帧上下文可压缩到固定大小的状态
   |
   v
方法:StateKV(基于重要性的循环状态 + 逐帧缓存)
   |
   v
证据:匹配完整注意力,在3个基准、7个模型上超越基线
   |
   v
结论:线性时间视频预填充无需微调即可实现
增量
一句话:这篇论文之前,长视频VLM要在二次方计算和精度损失之间二选一;
之后,它们可以通过推理时状态压缩以线性时间处理视频,同时保持完整注意力的精度。
核心机制
StateKV在视频预填充阶段运行——即模型在生成文本前首次处理所有视频帧时。
它维护两个独立的缓存:一个固定容量的循环状态,向前传递压缩的跨帧上下文;
一个完整的逐帧缓存,用于文本生成。
循环状态的工作方式是根据注意力分数从每帧中选择最重要的键值对,当容量达到上限时驱逐不太重要的条目。
每当新帧到达时,模型同时关注循环状态(包含压缩的历史)和当前帧的完整token。
然后将当前帧的重要token合并到循环状态中供未来帧使用。
这创建了一个压缩上下文的滚动窗口,随视频长度线性增长而非二次方增长。
在文本解码期间,模型切换到使用完整的逐帧缓存,确保生成响应时没有信息损失。
循环状态仅用于预填充期间的视频到视频注意力,不用于文本生成。
视频帧:  [F1] --> [F2] --> [F3] --> ... --> [Fn]
           |        |        |               |
           v        v        v               v
        +-----+  +-----+  +-----+         +-----+
预填充: | 注意力|  | 注意力|  | 注意力|   ...   | 注意力|
        +-----+  +-----+  +-----+         +-----+
           |        |        |               |
           v        v        v               v
      [循环状态:固定容量]
      [按重要性选择top-K KV对]
      [驱逐低重要性条目]
           |
           +---> 压缩的跨帧上下文
           |
           v
      [逐帧缓存:用于解码的完整KV]
           |
           v
        使用完整缓存解码文本token
把StateKV想象成一个报道多日事件的新闻编辑。
循环状态是编辑的运行摘要——每天,他们阅读新进展(当前帧),通过保留最重要的事实(基于重要性的选择)更新心智模型,并丢弃次要细节以避免认知过载(固定容量)。
逐帧缓存是每日报道的完整档案。
当撰写最终文章(文本生成)时,编辑查阅完整档案,而非仅仅摘要。
摘要的作用是帮助编辑在上下文中理解每天的新事件,而非替代档案。
关键概念
- 基于重要性驱逐的循环状态:传统注意力保留所有过去的token,导致二次方增长。
StateKV维护一个固定大小的键值对缓冲区,根据当前帧的注意力分数选择保留哪些。
当新帧到达且缓冲区已满时,被关注最少的token被驱逐。
这类似于缓存替换策略,但针对的是语义重要性而非时间新近性。
具体来说:如果缓冲区容纳1000个KV对,第50帧生成200个新的重要token,则驱逐200个最不重要的现有token。
缓冲区大小保持恒定,因此计算量线性扩展。
- 双缓存架构:StateKV使用两个具有不同目的的独立缓存。
循环状态(小型、压缩)仅在视频预填充期间使用,以传播跨帧上下文。
逐帧缓存(大型、完整)存储所有帧的所有token,在文本解码期间使用。
这种分离允许线性时间视频处理而不牺牲生成质量。
循环状态回答”我需要什么上下文来理解下一帧?”
而逐帧缓存回答”我需要什么信息来生成准确的文本?”
- 推理时适配:StateKV不需要微调或架构更改。
它是推理期间注意力机制的即插即用替代品。
预训练模型的权重保持冻结;
只有KV缓存管理策略发生变化。
这很强大,因为这意味着任何现有的视频VLM都可以立即适配。
模型从不”知道”它在使用压缩上下文——从它的角度看,它仍在做标准注意力,只是使用了不同的缓存token集。
框架转变
之前(完整自注意力):            之后(StateKV):

视频帧:                          视频帧:
[F1][F2][F3]...[Fn]              [F1][F2][F3]...[Fn]
  |   |   |      |                 |   |   |      |
  +---+---+------+                 v   v   v      v
  |                              [循环状态]
  v                              [固定容量]
[全对全注意力]                    [基于重要性]
[二次方:O(n^2)]                      |
  |                                   v
  v                              [选择性注意力]
[完整KV缓存]                      [线性:O(n)]
[内存:O(n^2)]                        |
  |                                   v
  v                              [逐帧缓存]
[解码]                            [用于解码的完整KV]
                                      |
                                      v
                                 [解码]
从穷举的跨帧注意力到选择性上下文传播,核心转变是用线性的基于重要性的循环过滤替代二次方的全对全依赖。
专家评审
选题眼光:这是真实的部署瓶颈,不是人造缺口。
视频VLM正在向流式和长时域应用(机器人、监控、视频问答)发展,二次方扩展是致命障碍。
问题位于模型效率和实际部署的交叉点——高价值目标。
框架诚实:他们承认现有效率方法,并清楚地说明他们试图打破的精度-效率权衡。
方法成熟度:核心洞察——基于重要性的状态压缩——优雅但不算突破性。
本质上是将系统研究中的缓存驱逐策略应用于注意力机制。
双缓存设计巧妙:通过仅在预填充期间压缩,它回避了”有损压缩损害生成”的问题。
然而,该方法在依赖注意力分数作为唯一重要性度量方面有些蛮力。
更复杂的重要性度量(基于梯度、基于不确定性)可能产生更好的压缩。
缺乏架构更改既是优势(易于采用)也是局限(无法为这种压缩方案协同设计模型)。
实验诚意:评估很全面——三个基准、七个模型、三个模型家族。
基线公平:他们与滑动窗口和基于新近性的方法比较,这些是主流的流式近似。
FLOPs分析是个亮点,显示StateKV能在相同计算预算下运行更大的模型。
一个警示信号:没有关于状态容量的消融实验。
精度对缓冲区大小有多敏感?
论文没有深入探索精度-内存权衡曲线。
此外,所有实验都在长视频基准上;
没有报告短视频性能(完整注意力可行的场景),所以我们不知道是否有退化。
写作功力:摘要和引言简洁。
方法部分清晰,但在深入实现细节之前可以多建立直觉。
相关工作部分全面但读起来像清单——如果能有叙事弧线展示先前工作如何导向这种方法会更好。
结果部分数字密集但分析不足:为什么StateKV在不同模型上超越滑动窗口的幅度不同?
出现了什么模式?
结论泛泛,完全可以删掉。
判决:弱接收 — 扎实的工程贡献,具有明确的实用价值,但概念新颖性有限,对方法设计空间的探索不完整。
要点总结
注意力缓存的基于重要性驱逐:使用注意力分数决定保留哪些KV对的想法可迁移到视频之外。
任何具有长序列的领域(音频、基因组学、时间序列)都可以应用这一点。
关键洞察:并非所有token对未来上下文都同等有用,你可以通过注意力权重衡量有用性。
有损预填充+无损解码的双缓存模式:在”理解”阶段激进压缩,但在”生成”阶段保留完整信息。
这种模式适用于任何编码器-解码器或预填充-解码架构,其中生成质量比编码速度更关键。
推理时适配作为部署策略:StateKV表明你可以在不重新训练的情况下将预训练模型适配到新的效率约束。
这是一个实用模板:识别瓶颈(二次方注意力),设计即插即用替代品(循环状态),验证精度保持。
“无需微调”属性被低估了——它意味着更快的迭代和更低的部署摩擦。
FLOPs-精度权衡的重新框架:不要问”如何让这个模型更快?”
而要问”在相同成本下我们能运行什么更大的模型?”
StateKV的FLOPs节省使得运行更大的模型成为可能,这通常比更快地运行较小模型产生更好的精度。
这种重新框架广泛适用:效率提升不应仅作为加速来评估,而应作为预算重新分配的机会。