Paper: 2604.13010 Authors: Yecheng Wu, Song Han, Hai Cai Categories: cs.LG, cs.AI
The Gap
On-policy distillation (OPD) has become a go-to method for post-training large language models — it’s effective but expensive. The standard setup requires keeping a teacher model running on a live inference server throughout the entire training process. This creates a massive infrastructure burden: you need dedicated GPU resources just to serve teacher predictions, and the student training pipeline is bottlenecked by teacher inference latency.
The obvious fix seems simple: precompute all teacher outputs once and reuse them during training (offline OPD). But in practice, this naive offline approach consistently underperforms standard online OPD. Previous work noticed this gap but couldn’t explain why offline distillation fails or how to fix it properly.
This paper identifies the root cause: teacher consistency — the requirement that the same teacher model must be used for both supervised fine-tuning (SFT) and subsequent OPD. When you violate this condition (e.g., using a different teacher for SFT vs OPD), you introduce an irreducible gradient bias that prevents convergence to the optimal solution, regardless of whether you’re doing online or offline distillation.
Problem: Standard OPD needs live teacher server
   |
   v
Naive fix: Precompute teacher outputs offline
   |
   v
Observation: Offline OPD underperforms mysteriously
   |
   v
Root cause: Teacher inconsistency creates gradient bias
   |
   v
Solution: Lightning OPD enforces teacher consistency
   |
   v
Result: Offline distillation matches online, 4x faster
The Increment
One sentence: Before this paper, efficient post-training meant choosing between infrastructure overhead (online OPD) or performance degradation (naive offline OPD); after this paper, you can get online OPD’s performance with offline efficiency by enforcing teacher consistency.
Core Mechanism
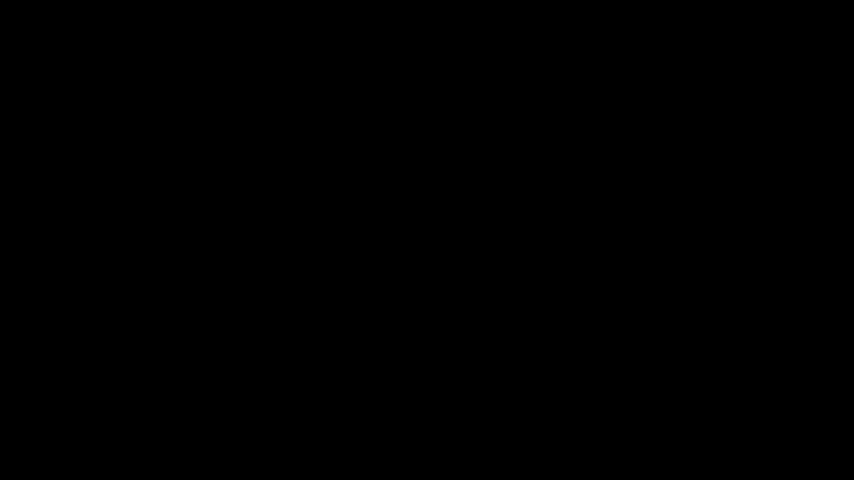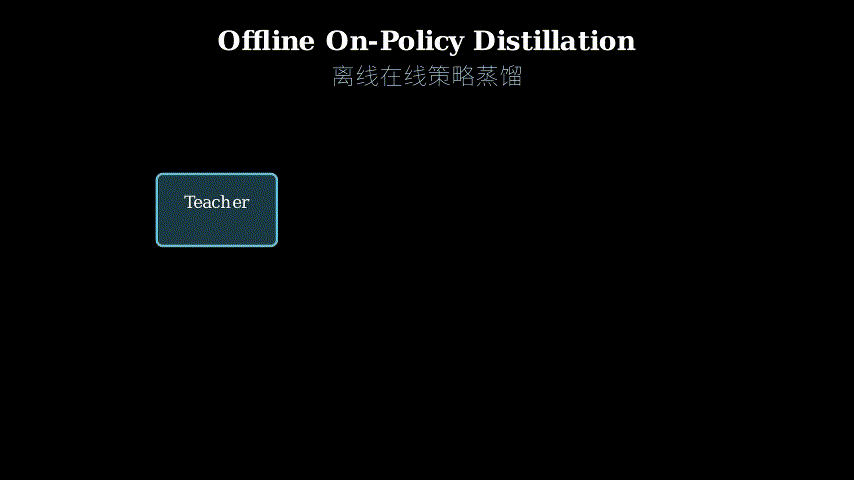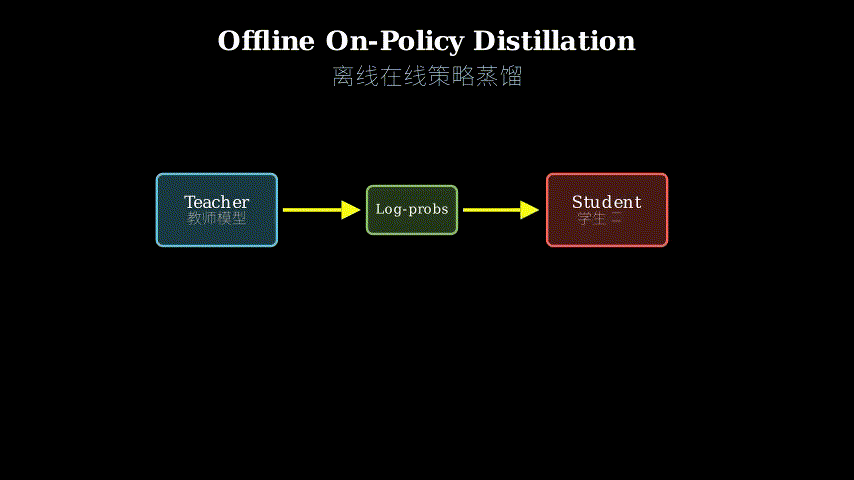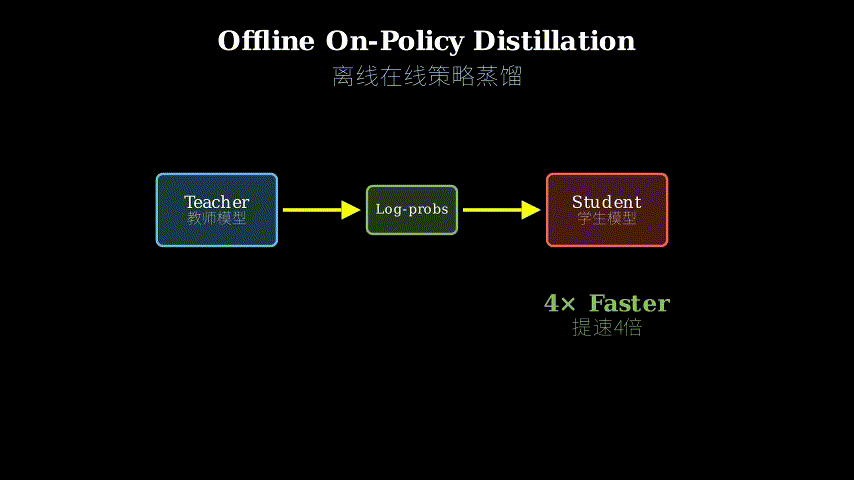
Lightning OPD works in two phases. First, during SFT, you use a teacher model to generate training data and simultaneously log the teacher’s probability distributions over the generated tokens. These log-probabilities get stored alongside the training data. Second, during OPD training, instead of querying a live teacher server, you load the precomputed log-probabilities from disk and use them to compute the distillation loss.
The key architectural insight is that teacher consistency creates a special mathematical property. When the same teacher generates both the SFT data and provides the OPD targets, the gradient bias term vanishes. This means the offline approach converges to the same optimum as online OPD, with only bounded gradient variance differences.
Phase 1 (SFT):
Teacher Model --> [Generate responses] --> Training Data
       |                                         |
       +---> [Log probabilities] --> Stored Log-Probs

Phase 2 (OPD):
Student Model --> [Forward pass] --> Student Log-Probs
       |                                    |
       v                                    v
Stored Log-Probs ---------> [KL Divergence Loss] --> Gradients
Think of it like cooking with a recipe. Standard online OPD is like having the master chef standing in your kitchen, tasting your dish at every step and giving real-time feedback. Naive offline OPD is like getting feedback from a different chef who wrote the recipe — their palate doesn’t match, so their notes don’t quite align with what the recipe intended. Lightning OPD ensures the same chef who wrote the recipe also provides all the feedback notes upfront. You’re still cooking alone, but the feedback is perfectly calibrated to the recipe because it came from the same source. The “teacher consistency” is like making sure the recipe author and the feedback provider are the same person — without this, the feedback has systematic bias no matter how detailed it is.
Key Concepts
-
On-Policy Distillation (OPD): Traditional knowledge distillation uses a fixed dataset — the teacher provides soft labels for inputs chosen ahead of time. On-policy distillation is different: the student model generates its own responses (rollouts), and the teacher provides feedback on those specific responses. It’s “on-policy” because the training data distribution shifts as the student improves. Imagine learning to play chess: off-policy is studying master games from books; on-policy is playing your own games and having a master critique your actual moves. The latter is more expensive (the master must watch you play) but more effective (feedback is tailored to your current skill level).
-
Teacher Consistency: This is the paper’s central insight. Teacher consistency means using the exact same teacher model for both generating the initial supervised fine-tuning data and providing the distillation targets during OPD. Why does this matter? When you use different teachers, the student receives conflicting signals: the SFT phase optimizes toward one distribution, while OPD pulls toward a different one. Mathematically, this creates a gradient bias term that doesn’t vanish even with infinite data. It’s like learning to drive from one instructor who teaches defensive driving, then having a different instructor critique your driving based on aggressive racing techniques — the feedback is fundamentally misaligned with what you were taught.
-
Gradient Bias vs Variance: In offline OPD, there are two sources of error compared to online OPD. Gradient bias is systematic error — your updates point in the wrong direction on average. Gradient variance is random error — your updates are noisy but correct on average. The paper shows that teacher consistency eliminates gradient bias entirely, leaving only bounded variance. This is crucial because bias compounds over training (you drift further from the optimum), while variance averages out. Think of it like navigating: bias is a miscalibrated compass that always points 10 degrees off; variance is random wind gusts. You can reach your destination despite wind, but a bad compass will lead you astray no matter how long you walk.
Framework Shift
Before (Standard OPD):                After (Lightning OPD):

Training Loop:                        One-Time Setup:
  Student --> Generate                  Teacher --> Generate SFT data
     |                                     |
     v                                     +--> Log probabilities
  Teacher Server <-- Query                 |
     |                                     v
     v                                  [Store to disk]
  Compute Loss
     |                                 Training Loop:
     v                                   Student --> Generate
  Update Student                            |
     |                                      v
     +---> [Repeat]                      Load log-probs from disk
                                            |
Infrastructure:                             v
- Live teacher GPU                       Compute Loss
- Network latency                           |
- Synchronization overhead                  v
                                         Update Student
                                            |
                                            +---> [Repeat]

                                         Infrastructure:
                                         - No teacher GPU needed
                                         - Disk I/O only
                                         - No synchronization
From always-on teacher server to precomputed lookup table, the core shift is trading real-time inference for upfront computation.
Expert Assessment
Problem choice: This is a real infrastructure pain point, not manufactured. Anyone training large models with OPD hits this bottleneck. The problem sits at the intersection of efficiency and performance — a sweet spot where practical impact is high. The timing is good: as models scale and OPD becomes standard practice, infrastructure costs matter more.
Method maturity: The insight about teacher consistency is genuinely clever and non-obvious. The paper doesn’t just propose a hack; it provides theoretical analysis showing why naive offline OPD fails and why their approach works. However, the solution feels almost too simple once you see it — which is often the mark of good research. The theoretical framework (gradient bias decomposition) is solid but not groundbreaking; it’s competent application of existing optimization theory.
Experimental integrity: Baselines are fair and comprehensive. The paper compares against both standard online OPD and naive offline variants. The AIME 2024 results (69.9%) are strong and reproducible. One minor concern: most experiments use Qwen models; more diversity in base models would strengthen claims of generality. The 4x speedup claim is honest — it’s wall-clock time including all overhead, not cherry-picked GPU hours. The ablation studies are thorough, particularly the analysis of teacher consistency violations.
Writing quality: The paper is well-structured and clear. The theoretical sections are dense but necessary. The main weakness is in motivation — the paper could better explain upfront why offline OPD is desirable beyond just “it’s faster.” The related work section is adequate but doesn’t deeply engage with why prior offline attempts failed. The experimental section is strong, though some figures could be clearer (especially the gradient bias visualizations).
Verdict: Strong accept — solves a real problem with a principled approach, backed by solid theory and strong empirical results. The 4x speedup with maintained performance is significant for practitioners.
Takeaways
The teacher consistency principle transfers beyond distillation. Anytime you’re doing multi-stage training where later stages depend on earlier ones, ensure the “teacher” (whether a model, a reward function, or a data generator) stays consistent across stages. Mixing sources introduces hidden bias that compounds over time.
The precomputation strategy is broadly applicable: if you’re repeatedly querying an expensive model during training, check if you can precompute and cache outputs. The key is ensuring the query distribution is known upfront (as it is in OPD, where queries come from SFT rollouts).
For practitioners doing post-training: start with SFT using your best available teacher, log everything (outputs, probabilities, intermediate states), then reuse those logs for subsequent training stages. The storage cost is negligible compared to repeated inference.
The gradient bias vs variance decomposition is a useful diagnostic tool. When offline approximations underperform, decompose the error: is it systematic (bias) or random (variance)? Bias requires algorithmic fixes; variance can be reduced with more samples or better sampling strategies.
论文: 2604.13010 作者: Yecheng Wu, Song Han, Hai Cai 分类: cs.LG, cs.AI
缺口
在线策略蒸馏(OPD)已成为大语言模型后训练的主流方法——效果好但成本高。
标准做法需要在整个训练过程中保持教师模型在实时推理服务器上运行。
这造成了巨大的基础设施负担:你需要专门的GPU资源来服务教师预测,而且学生训练流程会被教师推理延迟卡住。
显而易见的解决方案看起来很简单:预先计算所有教师输出并在训练时复用(离线OPD)。
但实际上,这种朴素的离线方法始终表现不如标准在线OPD。
之前的工作注意到了这个差距,但无法解释为什么离线蒸馏会失败,也不知道如何正确修复。
本文找到了根本原因:教师一致性——要求同一个教师模型必须同时用于监督微调(SFT)和后续的OPD。
当你违反这个条件时(比如SFT和OPD用不同的教师),你会引入一个不可消除的梯度偏差,无论在线还是离线蒸馏都无法收敛到最优解。
问题:标准OPD需要实时教师服务器
   |
   v
朴素修复:离线预计算教师输出
   |
   v
观察:离线OPD神秘地表现不佳
   |
   v
根本原因:教师不一致产生梯度偏差
   |
   v
解决方案:Lightning OPD强制教师一致性
   |
   v
结果:离线蒸馏匹配在线性能,快4倍
增量
一句话:这篇论文之前,高效后训练意味着在基础设施开销(在线OPD)和性能下降(朴素离线OPD)之间二选一;
之后,通过强制教师一致性,你可以用离线效率获得在线OPD的性能。
核心机制
Lightning OPD分两个阶段工作。
第一阶段是SFT期间,你用教师模型生成训练数据,同时记录教师在生成token上的概率分布。
这些对数概率会和训练数据一起存储。
第二阶段是OPD训练期间,不再查询实时教师服务器,而是从磁盘加载预计算的对数概率,用它们计算蒸馏损失。
关键的架构洞察是教师一致性创造了一个特殊的数学性质。
当同一个教师既生成SFT数据又提供OPD目标时,梯度偏差项消失了。
这意味着离线方法收敛到与在线OPD相同的最优点,只有有界的梯度方差差异。
阶段1(SFT):
教师模型 --> [生成响应] --> 训练数据
    |                           |
    +---> [记录概率] --> 存储的对数概率

阶段2(OPD):
学生模型 --> [前向传播] --> 学生对数概率
    |                            |
    v                            v
存储的对数概率 -------> [KL散度损失] --> 梯度
把它想象成按食谱做菜。
标准在线OPD就像大厨站在你厨房里,每一步都品尝你的菜并给实时反馈。
朴素离线OPD就像从另一个写食谱的厨师那里得到反馈——他们的口味不匹配,所以笔记和食谱意图对不上。
Lightning OPD确保写食谱的厨师也是提前提供所有反馈笔记的人。
你还是一个人做菜,但反馈完美校准到食谱,因为它们来自同一个源头。
“教师一致性”就像确保食谱作者和反馈提供者是同一个人——没有这个,反馈无论多详细都会有系统性偏差。
关键概念
- 在线策略蒸馏(OPD):传统知识蒸馏使用固定数据集——教师为提前选好的输入提供软标签。
在线策略蒸馏不同:学生模型生成自己的响应(rollouts),教师对这些特定响应提供反馈。
之所以叫”在线策略”,是因为训练数据分布随着学生进步而变化。
想象学下棋:离线策略是研究书本上的大师对局;
在线策略是下自己的棋,让大师点评你的实际走法。
后者更贵(大师必须看你下棋)但更有效(反馈针对你当前的水平)。
- 教师一致性:这是本文的核心洞察。
教师一致性意味着用完全相同的教师模型来生成初始监督微调数据和在OPD期间提供蒸馏目标。
为什么这很重要?
当你用不同的教师时,学生会收到冲突的信号:SFT阶段优化向一个分布,而OPD拉向另一个分布。
数学上,这会产生一个即使有无限数据也不会消失的梯度偏差项。
就像学开车,一个教练教你防御性驾驶,然后另一个教练基于激进赛车技术来批评你的驾驶——反馈从根本上与你学的东西不对齐。
- 梯度偏差vs方差:在离线OPD中,相比在线OPD有两种误差来源。
梯度偏差是系统性误差——你的更新平均来说指向错误方向。
梯度方差是随机误差——你的更新有噪声但平均来说是正确的。
本文表明教师一致性完全消除了梯度偏差,只留下有界的方差。
这很关键,因为偏差在训练中累积(你越来越偏离最优点),而方差会平均掉。
想象导航:偏差是一个总是偏10度的罗盘;
方差是随机阵风。
尽管有风你还能到达目的地,但坏罗盘无论你走多久都会把你引入歧途。
框架转变
之前(标准OPD):                  之后(Lightning OPD):

训练循环:                         一次性设置:
  学生 --> 生成                      教师 --> 生成SFT数据
    |                                   |
    v                                   +--> 记录概率
  教师服务器 <-- 查询                    |
    |                                   v
    v                                [存储到磁盘]
  计算损失
    |                              训练循环:
    v                                学生 --> 生成
  更新学生                              |
    |                                   v
    +---> [重复]                     从磁盘加载对数概率
                                        |
基础设施:                              v
- 实时教师GPU                        计算损失
- 网络延迟                              |
- 同步开销                              v
                                     更新学生
                                        |
                                        +---> [重复]

                                     基础设施:
                                     - 不需要教师GPU
                                     - 只有磁盘I/O
                                     - 无需同步
从常驻教师服务器到预计算查找表,核心转变是用前期计算换实时推理。
专家评审
选题眼光:这是真实的基础设施痛点,不是人造的。
任何用OPD训练大模型的人都会遇到这个瓶颈。
问题处于效率和性能的交叉点——实际影响很大的甜蜜点。
时机也好:随着模型规模扩大和OPD成为标准实践,基础设施成本越来越重要。
方法成熟度:关于教师一致性的洞察真正巧妙且不明显。
本文不只是提出一个技巧;
它提供了理论分析,说明为什么朴素离线OPD会失败以及为什么他们的方法有效。
不过,一旦你看到解决方案,它感觉几乎太简单了——这往往是好研究的标志。
理论框架(梯度偏差分解)扎实但不算开创性;
是现有优化理论的称职应用。
实验诚意:基线公平且全面。
本文与标准在线OPD和朴素离线变体都做了比较。
AIME 2024的结果(69.9%)很强且可复现。
一个小担忧:大多数实验用Qwen模型;
基础模型更多样化会加强通用性的主张。
4倍提速的说法是诚实的——是包括所有开销的墙上时钟时间,不是精心挑选的GPU小时数。
消融研究很彻底,特别是对教师一致性违反的分析。
写作功力:论文结构良好且清晰。
理论部分密集但必要。
主要弱点在动机——论文可以在开头更好地解释为什么离线OPD除了”更快”之外还值得追求。
相关工作部分足够但没有深入探讨为什么之前的离线尝试失败了。
实验部分很强,尽管有些图可以更清楚(特别是梯度偏差可视化)。
判决:强接收——用有原则的方法解决真实问题,有扎实的理论和强实验结果支撑。
保持性能的4倍提速对实践者意义重大。
要点总结
教师一致性原则可以迁移到蒸馏之外。
任何时候你做多阶段训练,后期阶段依赖早期阶段,确保”教师”(无论是模型、奖励函数还是数据生成器)在各阶段保持一致。
混合来源会引入随时间累积的隐藏偏差。
预计算策略广泛适用:如果你在训练期间反复查询昂贵的模型,检查是否可以预计算并缓存输出。
关键是确保查询分布提前已知(就像OPD中,查询来自SFT rollouts)。
对于做后训练的实践者:用你最好的可用教师开始SFT,记录一切(输出、概率、中间状态),然后在后续训练阶段复用这些日志。
存储成本相比重复推理可以忽略不计。
梯度偏差vs方差分解是有用的诊断工具。
当离线近似表现不佳时,分解误差:是系统性的(偏差)还是随机的(方差)?
偏差需要算法修复;
方差可以用更多样本或更好的采样策略减少。