Paper: 2605.00809 Authors: Yan Fang, Mengcheng Lan, Zilong Huang, Weixian Lei, Yunqing Zhao, Yujie Zhong, Yingchen Yu, Qi She, Yao Zhao, Yunchao Wei Categories: cs.CV
The Gap
Vision encoders for multimodal LLMs have been trained using contrastive methods (CLIP) or hybrid approaches with separate text decoders. These methods create an architectural mismatch: vision encoders learn through bidirectional attention and contrastive objectives, while LLMs operate autoregressively, predicting the next token. When you plug a CLIP-trained ViT into an LLM, you’re connecting two systems that learned to think differently. The vision encoder speaks “similarity space” while the LLM speaks “next-token prediction.”
Prior work tried bridging this with adapter layers or continued finetuning, but the fundamental misalignment remains. The gap: no one had trained a vision encoder using the same autoregressive language modeling objective that LLMs use from the start.
Problem: Vision-Language Mismatch
   |
   v
Observation: CLIP uses contrastive learning (bidirectional)
             LLMs use autoregressive prediction (causal)
   |
   v
Hypothesis: Train ViT with language modeling objective
            -> Better alignment with LLM architecture
   |
   v
Method: GenLIP - ViT predicts language tokens directly
        Single transformer, no contrastive batches
   |
   v
Evidence: Matches CLIP baselines with 8B samples
          Outperforms on OCR/chart tasks after multi-res training
   |
   v
Conclusion: Generative pretraining creates better
            vision encoders for autoregressive LLMs
The Increment
One sentence: Before GenLIP, vision encoders learned through contrastive similarity matching; after GenLIP, they learn by predicting language tokens autoregressively, speaking the same native language as LLMs.
Core Mechanism
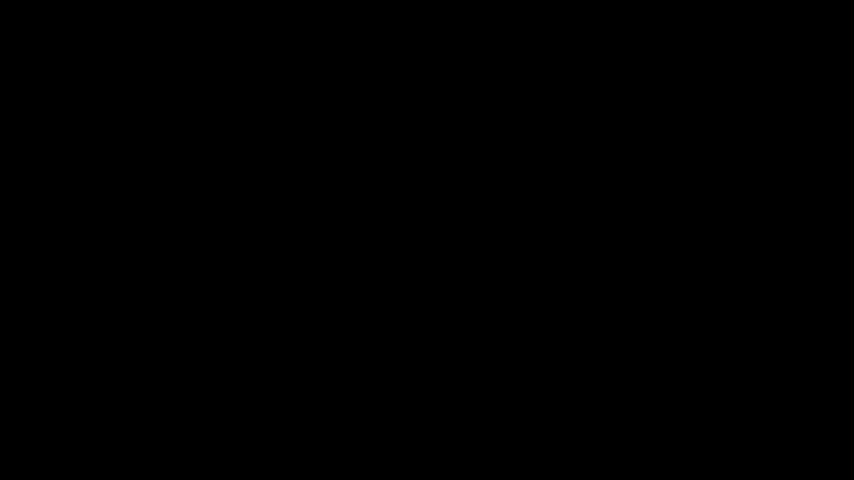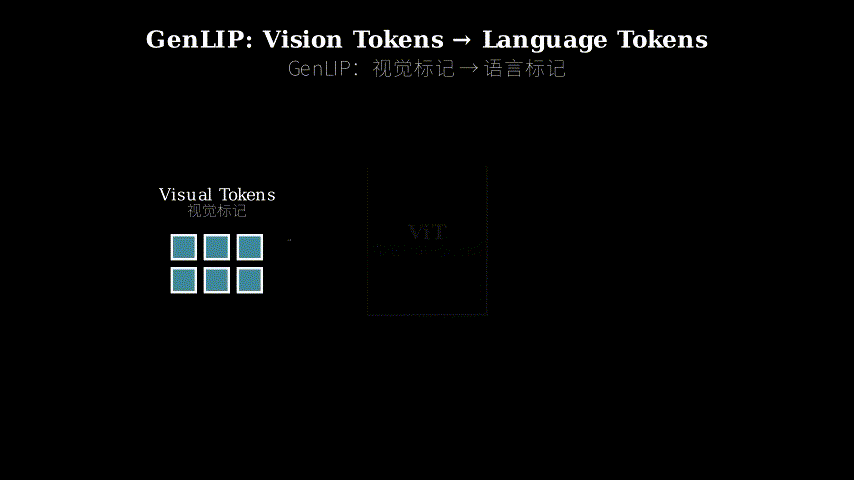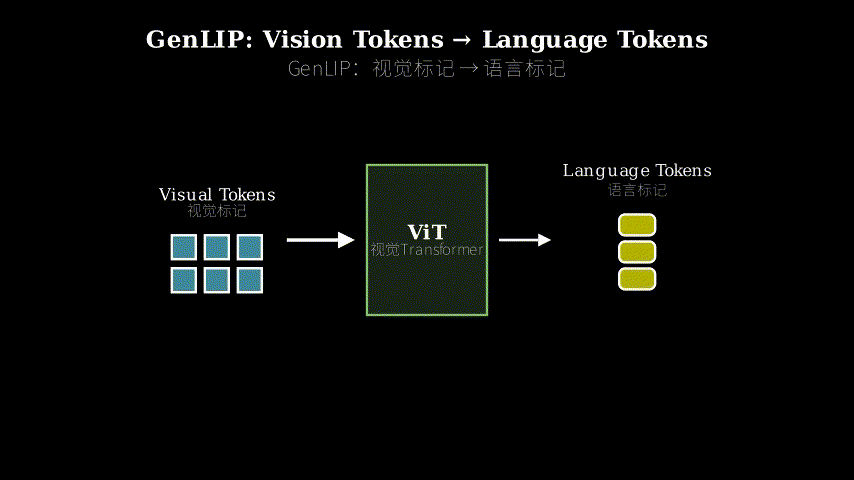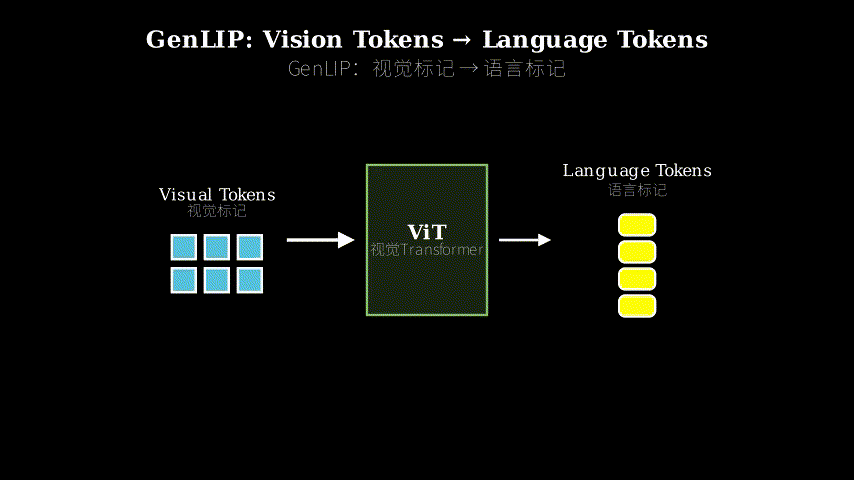
GenLIP takes a Vision Transformer and trains it to be a language model. Feed it an image, the ViT produces visual tokens. These visual tokens then predict a sequence of language tokens (text describing the image) using standard next-token prediction, exactly like GPT predicts text from text.
The architecture is a single transformer that processes both visual and textual tokens. Visual tokens from the image go through ViT layers. Then language tokens are appended, and the model predicts each language token autoregressively based on all previous visual tokens and language tokens. No separate text encoder, no contrastive loss comparing image-text pairs in a batch—just straightforward language modeling loss on the text tokens.
Training uses image-caption pairs. The model sees the image, generates visual representations, then tries to predict the caption word by word. The loss is computed only on the language tokens (not the visual tokens), using cross-entropy like any language model. This means the ViT learns to encode images in a way that makes language prediction easy.
Image Input
    |
    v
[ViT Layers] --> Visual Tokens [v1, v2, ..., vN]
    |
    v
Concatenate with Language Tokens [w1, w2, ..., wM]
    |
    v
[Transformer Layers with Causal Masking]
    |
    v
Predict: P(w1|v*), P(w2|v*,w1), P(w3|v*,w1,w2), ...
    |
    v
Loss: Cross-Entropy on Language Tokens Only
Think of it like teaching someone a foreign language through immersion rather than translation dictionaries. CLIP is like giving students a dictionary: “this image is similar to this text.” GenLIP is immersion: “look at this image, now describe it word by word.” The student (ViT) learns to think in the target language (autoregressive prediction) from day one, not through a translation layer.
The ViT becomes a native speaker of the LLM’s language because it learned through the same task—predicting the next token. When you later plug this ViT into an LLM, there’s no accent, no translation overhead. Both systems already think in terms of “what comes next.”
Key Concepts
-
Autoregressive Language Modeling: Imagine reading a sentence with words covered up, revealing them one at a time from left to right. At each step, you predict the next word based only on what you’ve seen so far. That’s autoregressive: each prediction depends on previous tokens, not future ones. GenLIP trains the ViT this way—given image tokens and previous words, predict the next word. This is fundamentally different from CLIP, which looks at the whole image and whole text simultaneously and asks “how similar are these?” Autoregressive is sequential and causal; contrastive is holistic and symmetric.
-
Visual Tokens as Context: In a language model, context is the preceding text that helps predict the next word. GenLIP treats visual tokens as context—they’re the “preceding text” for generating the caption. The ViT encodes the image into a sequence of tokens (like words), and these tokens condition the language generation. This is why the alignment works: the LLM is used to receiving a sequence of tokens and predicting the next one. Visual tokens are just another sequence, formatted the same way.
-
Single-Objective Training: Most vision-language models juggle multiple losses: contrastive loss, reconstruction loss, maybe a language modeling loss on top. GenLIP uses one loss: cross-entropy on language tokens. This simplicity matters because the model isn’t trying to satisfy competing objectives. It has one job—predict text from images—and all its parameters optimize for that. The result is a vision encoder that’s laser-focused on being a good language model input, not a jack-of-all-trades representation.
Framework Shift
Before (CLIP-style):                After (GenLIP):

Image  Text                         Image
  |     |                             |
  v     v                             v
[ViT] [Text Enc]                   [ViT] --> Visual Tokens
  |     |                             |
  +-----+                             v
    |                            [Append Language Tokens]
    v                                 |
Similarity Score                      v
    |                          [Causal Transformer]
    v                                 |
Contrastive Loss                      v
(batch-level)                   Predict Next Token
                                      |
                                      v
                               Language Modeling Loss
                               (sequence-level)
From parallel encoding with batch-level comparison to sequential generation with token-level prediction, the core shift is treating vision encoding as the first stage of language generation rather than a separate modality to be aligned.
Expert Assessment
Problem choice: Real gap. The architectural mismatch between contrastive vision encoders and autoregressive LLMs has been a known pain point. Adapter layers and projection modules are band-aids. Training the vision encoder in the LLM’s native objective is a logical next step that surprisingly few explored systematically. This sits at the intersection of two mature areas (vision-language pretraining and LLM scaling), making it a natural evolution rather than a leap into the unknown.
Method maturity: Elegant simplicity. The method is almost trivial—just apply language modeling to images—but that’s the point. The authors resisted the urge to add bells and whistles. No auxiliary losses, no complex architectures. The risk is that it’s *too simple and leaves performance on the table, but the results suggest otherwise. One concern: the method inherits LLM scaling properties, which means it’s data-hungry. The 8B sample training is not small, even if it’s less than some CLIP variants.
Experimental integrity: Baselines are fair and diverse (CLIP, SigLIP, EVA-CLIP). The multi-resolution continued pretraining is a nice touch that shows the method’s flexibility. However, the paper could be more transparent about compute costs—training a generative model is typically more expensive than contrastive learning per sample. The OCR and chart improvements are compelling because they’re detail-sensitive tasks where you’d expect generative pretraining to shine. No major red flags, but I’d want to see ablations on data efficiency (how does it perform at 1B, 2B, 4B samples?).
Writing quality: The abstract and intro are crisp. The method section is almost too brief—readers might want more implementation details (learning rate schedules, warmup, regularization). The related work section does a decent job positioning the work but could better articulate why prior generative vision-language models (e.g., early VQ-VAE + transformer approaches) didn’t catch on. The results section is thorough but could use a failure analysis: where does GenLIP still lag behind CLIP?
Verdict: weak accept — Solid execution of a simple, well-motivated idea with competitive results, though not a paradigm shift.
Takeaways
For practitioners building multimodal systems: If you’re training a vision encoder specifically for an LLM, consider generative pretraining instead of contrastive. The architectural alignment reduces the need for complex adapter layers. The single-objective training also simplifies hyperparameter tuning—you’re not balancing multiple loss weights.
For researchers on vision-language pretraining: The multi-resolution continued pretraining trick (native aspect ratios) is worth stealing. It’s a cheap way to boost performance on detail-heavy tasks without retraining from scratch. Also, the result that generative pretraining scales well with data suggests that as datasets grow, this approach might pull ahead of contrastive methods.
For anyone skeptical of “simpler is better”: This paper is a case study. The authors removed components (text encoder, contrastive loss, batch construction) and got competitive results. Sometimes the right move is subtraction, not addition. If your model has three losses and two auxiliary tasks, ask whether you really need them or if you’re just hedging bets.
论文: 2605.00809 作者: Yan Fang, Mengcheng Lan, Zilong Huang, Weixian Lei, Yunqing Zhao, Yujie Zhong, Yingchen Yu, Qi She, Yao Zhao, Yunchao Wei 分类: cs.CV
缺口
多模态大语言模型的视觉编码器一直用对比学习(CLIP)或带独立文本解码器的混合方法训练。
这些方法造成了架构错配:视觉编码器通过双向注意力和对比目标学习,而大语言模型是自回归运作,预测下一个token。
当你把CLIP训练的ViT插入LLM时,你在连接两个思维方式不同的系统。
视觉编码器说”相似度空间”的语言,LLM说”下一token预测”的语言。
之前的工作试图用适配层或继续微调来搭桥,但根本性的错位依然存在。
缺口在于:没人从一开始就用LLM的自回归语言建模目标来训练视觉编码器。
问题:视觉-语言错配
   |
   v
观察:CLIP用对比学习(双向)
     LLM用自回归预测(因果)
   |
   v
假设:用语言建模目标训练ViT
     -> 与LLM架构更好对齐
   |
   v
方法:GenLIP - ViT直接预测语言token
     单个transformer,无对比批次
   |
   v
证据:用8B样本匹配CLIP基线
     多分辨率训练后在OCR/图表任务上超越
   |
   v
结论:生成式预训练为自回归LLM
     创造更好的视觉编码器
增量
一句话: GenLIP之前,视觉编码器通过对比相似度匹配学习;GenLIP之后,它们通过自回归预测语言token学习,说着和LLM一样的母语。
核心机制
GenLIP把Vision Transformer训练成一个语言模型。
喂给它一张图,ViT产生视觉token。
这些视觉token然后预测一串语言token(描述图像的文本),用标准的下一token预测,就像GPT从文本预测文本一样。
架构是单个transformer,同时处理视觉和文本token。
图像的视觉token经过ViT层。
然后语言token被追加上去,模型基于所有之前的视觉token和语言token自回归预测每个语言token。
没有独立的文本编码器,没有对比损失在批次中比较图文对——只有对文本token的直接语言建模损失。
训练用图像-标题对。
模型看到图像,生成视觉表示,然后试图逐词预测标题。
损失只在语言token上计算(不在视觉token上),用交叉熵,就像任何语言模型一样。
这意味着ViT学会以让语言预测变容易的方式编码图像。
图像输入
    |
    v
[ViT层] --> 视觉Token [v1, v2, ..., vN]
    |
    v
与语言Token拼接 [w1, w2, ..., wM]
    |
    v
[带因果掩码的Transformer层]
    |
    v
预测: P(w1|v*), P(w2|v*,w1), P(w3|v*,w1,w2), ...
    |
    v
损失: 仅在语言Token上的交叉熵
把它想象成通过沉浸式教学而非翻译词典来教外语。
CLIP像给学生一本词典:“这张图和这段文本相似。
“GenLIP是沉浸式:“看这张图,现在逐词描述它。
“学生(ViT)从第一天起就学会用目标语言(自回归预测)思考,而非通过翻译层。
ViT成为LLM语言的母语者,因为它通过同样的任务学习——预测下一个token。
当你后来把这个ViT插入LLM时,没有口音,没有翻译开销。
两个系统已经都在用”接下来是什么”的方式思考。
关键概念
- 自回归语言建模: 想象读一个句子,词被遮住,从左到右一次揭示一个。
每一步,你只根据目前看到的预测下一个词。
这就是自回归:每次预测只依赖之前的token,不依赖未来的。
GenLIP这样训练ViT——给定图像token和之前的词,预测下一个词。
这和CLIP根本不同,CLIP同时看整张图和整段文本,问”这俩多相似?
“自回归是顺序的、因果的;对比是整体的、对称的。
- 视觉Token作为上下文: 在语言模型中,上下文是帮助预测下一个词的前文。
GenLIP把视觉token当上下文——它们是生成标题的”前文”。
ViT把图像编码成一串token(像词),这些token条件化语言生成。
这就是对齐有效的原因:LLM习惯接收一串token然后预测下一个。
视觉token只是另一串,格式一样。
- 单目标训练: 大多数视觉-语言模型要兼顾多个损失:对比损失、重建损失、可能还有语言建模损失。
GenLIP用一个损失:语言token上的交叉熵。
这种简洁性很重要,因为模型不用满足相互竞争的目标。
它只有一个任务——从图像预测文本——所有参数都为此优化。
结果是一个专注于成为好的语言模型输入的视觉编码器,而非万金油表示。
框架转变
之前(CLIP风格):              之后(GenLIP):

图像  文本                      图像
  |     |                         |
  v     v                         v
[ViT] [文本编码器]              [ViT] --> 视觉Token
  |     |                         |
  +-----+                         v
    |                        [追加语言Token]
    v                             |
相似度分数                        v
    |                      [因果Transformer]
    v                             |
对比损失                          v
(批次级)                    预测下一Token
                                  |
                                  v
                           语言建模损失
                           (序列级)
从带批次级比较的并行编码到带token级预测的顺序生成,核心转变是把视觉编码当作语言生成的第一阶段,而非需要对齐的独立模态。
专家评审
选题眼光: 真缺口。
对比视觉编码器和自回归LLM之间的架构错配一直是已知痛点。
适配层和投影模块是创可贴。
用LLM的原生目标训练视觉编码器是合乎逻辑的下一步,令人惊讶的是很少有人系统探索。
这处于两个成熟领域(视觉-语言预训练和LLM扩展)的交叉点,是自然演进而非跃入未知。
方法成熟度: 优雅的简洁。
方法几乎平凡——只是把语言建模应用到图像——但这正是重点。
作者抵制了加花哨功能的冲动。
没有辅助损失,没有复杂架构。
风险是它太简单,留下性能空间,但结果表明并非如此。
一个担忧:方法继承了LLM的扩展特性,意味着它数据饥渴。
8B样本训练不算小,即使比某些CLIP变体少。
实验诚意: 基线公平且多样(CLIP、SigLIP、EVA-CLIP)。
多分辨率继续预训练是个好点子,展示了方法的灵活性。
但论文在计算成本上可以更透明——训练生成模型通常比对比学习每样本更贵。
OCR和图表改进令人信服,因为它们是细节敏感任务,你会期待生成式预训练表现出色。
没有大红旗,但我想看数据效率的消融(在1B、2B、4B样本时表现如何?
)。
写作功力: 摘要和引言简洁。
方法部分几乎太简短——读者可能想要更多实现细节(学习率调度、预热、正则化)。
相关工作部分在定位工作上做得不错,但可以更好地阐明为什么之前的生成式视觉-语言模型(如早期VQ-VAE + transformer方法)没流行起来。
结果部分详尽,但可以加失败分析:GenLIP在哪里仍落后CLIP?
判决: 弱接收 — 对一个简单、动机充分的想法的扎实执行,结果有竞争力,但不是范式转变。
要点总结
对于构建多模态系统的实践者: 如果你专门为LLM训练视觉编码器,考虑生成式预训练而非对比式。
架构对齐减少了对复杂适配层的需求。
单目标训练也简化了超参数调优——你不用平衡多个损失权重。
对于视觉-语言预训练的研究者: 多分辨率继续预训练技巧(原生宽高比)值得偷师。
这是在不从头重训的情况下提升细节密集任务性能的廉价方法。
另外,生成式预训练随数据扩展良好的结果表明,随着数据集增长,这种方法可能超越对比方法。
对于怀疑”越简单越好”的人: 这篇论文是个案例研究。
作者移除了组件(文本编码器、对比损失、批次构建),得到了有竞争力的结果。
有时正确的举动是做减法,不是加法。
如果你的模型有三个损失和两个辅助任务,问问你是否真的需要它们,还是只是在对冲赌注。