Paper: 2606.19336 Authors: Yingshan Susan Wang, Cedegao E. Zhang, Linlu Qiu, Zexue He, Pengyuan Li, Alex Pentland, Roger P. Levy, Yoon Kim Categories: cs.CL
The Gap
Existing user simulators are trained as LLMs to match a single ground-truth response per context. The dominant approaches are:
- MLE (Maximum Likelihood Estimation): maximize the log-probability of the reference response.
- SimRL (Similarity-based RL): use a reward like BLEU or BERTScore on the distance to the reference.
Both assume that matching one correct output is sufficient. This fails because human responses are diverse—there are many plausible responses to the same context. Training to match a single target either averages over possibilities (producing bland outputs) or overfits that one surface form. The resulting simulator cannot faithfully capture the full distribution of real user behavior.
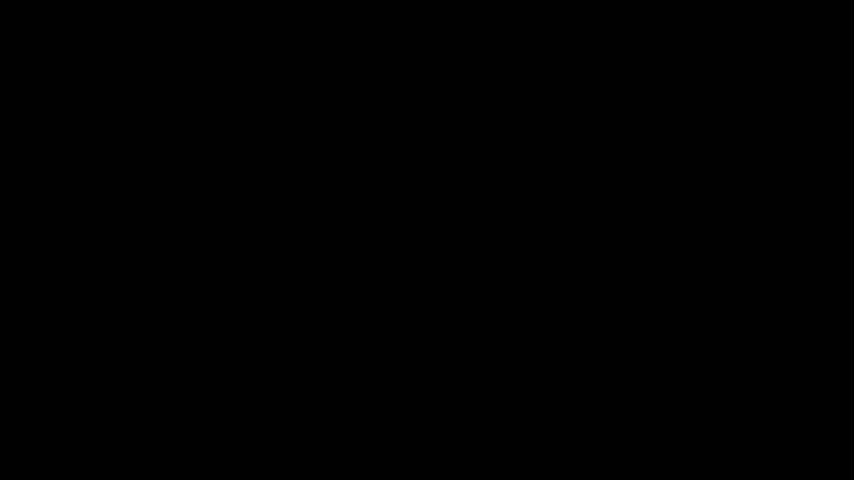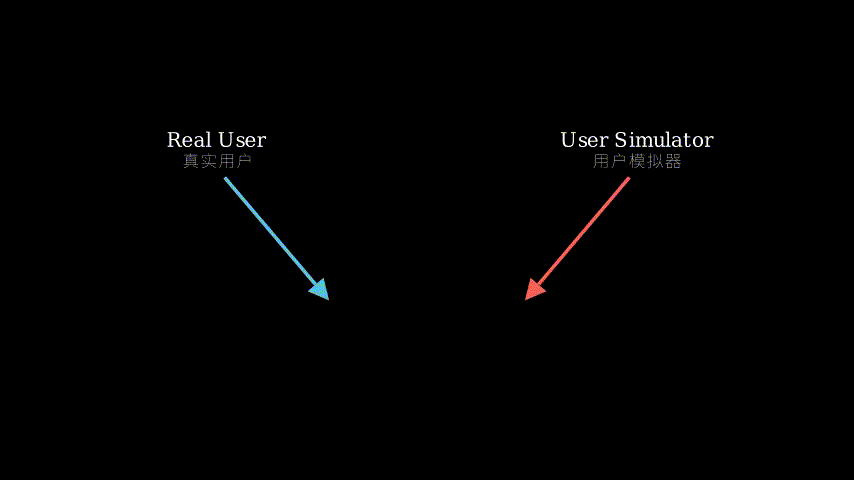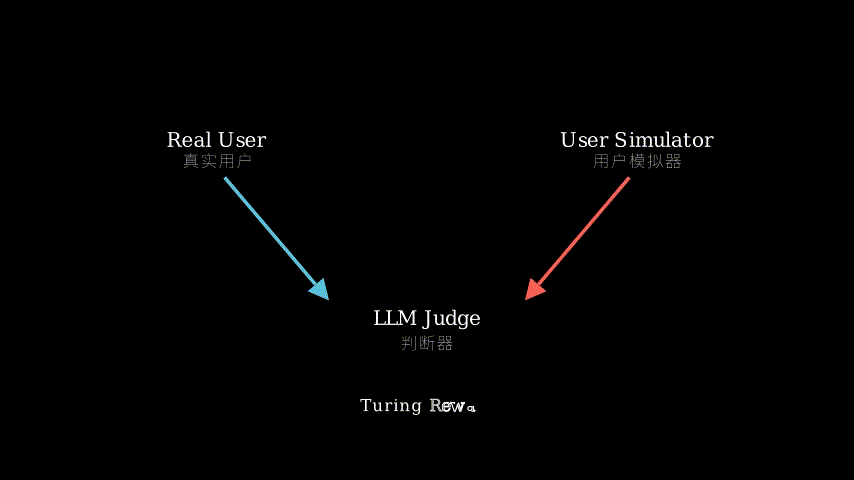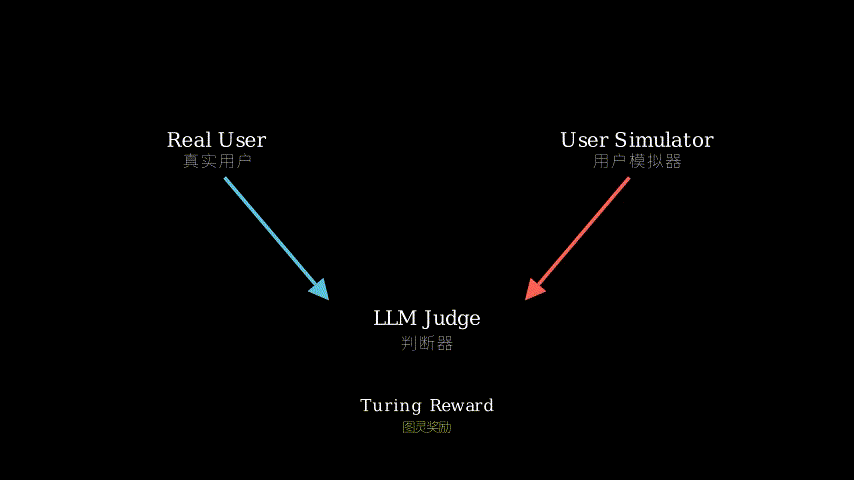
The paper identifies this distributional mismatch as the core limitation. Their key insight: instead of rewarding fidelity to a *specific response, reward indistinguishability from the set of all possible real responses. They operationalize this through a Turing test: a judge (discriminator) tries to tell real from simulated responses, and the simulator is rewarded when it fools the judge. This shifts the training signal from “how close is this to the right answer?” to “could this have been said by a real user?”
[ Problem: Simulators match one reference               ]
[  - MLE: maximize log P(ref | context)                  ]
[  - SimRL: maximize similarity(ref, sample)             ]
[    |                                                    ]
[    v                                                    ]
[ Limitation: Ignores diversity of real responses;        ]
[   produces outputs that are either bland or overfit     ]
[    |                                                    ]
[    v                                                    ]
[ Key Insight: Use Turing test as reward function         ]
[   - Reward = P(judge classifies sample as real)         ]
[    |                                                    ]
[    v                                                    ]
[ Method: Turing-RL (PPO with discriminator reward)       ]
[    |                                                    ]
[    v                                                    ]
[ Evidence: Outperforms MLE / SimRL on LLM and human eval ]
[    |                                                    ]
[    v                                                    ]
[ Conclusion: Optimizing for indistinguishability >       ]
[   optimizing for response matching                      ]
The Increment
One sentence: Before this paper, user simulators were trained by squeezing the model toward one predetermined answer; after this paper, they are trained to blend into the crowd of real users, making the entire distribution of possible responses fair game.
Core Mechanism
The method has two main components:
- User Simulator LLM (the policy) – an autoregressive language model that generates a response given a conversation history. This is the model we want to train.
- Discriminator LLM (the judge) – another LLM that, given the same history and a proposed response, outputs a scalar score: the probability that the response is from a real human (as opposed to the simulator).
Data flow during training:
- For each training example (history + real human response), the simulator generates a synthetic response.
- The discriminator scores both the real response (should be high) and the synthetic response (should be low). The discriminator is trained via binary classification to maximize this gap.
- The synthetic response’s discriminator score is used as the reward for the simulator. The simulator is updated with PPO (Proximal Policy Optimization) to maximize this reward.
- Periodically, the discriminator is fine-tuned on fresh real + simulated data to prevent it from being exploited.
This creates a symbiotic min-max game: the simulator tries to fool the discriminator; the discriminator tries to not be fooled. The reward is dynamic and adapts as the simulator improves.
+-----------------------+          +-----------------------+
| User Simulator (RL)  |          | Discriminator (Judge) |
| Policy: LLM          |--------->| LLM that scores       |
| Input: history       |          | response = real?      |
| Output: response     |          | Output: score [0,1]   |
+-----------+----------+          +----------+------------+
            |                                ^
            | reward = score                 |
            v                                |
+--------------------------------+          |
| Reinforcement Learning (PPO)   |          |
| Update simulator to maximize   |          |
| reward on generated responses  |          |
+--------------------------------+          |
         |                                   |
         | (periodically)                    |
         v                                   |
+--------------------------------+          |
| Update Discriminator:          |----------+
| binary classification: real vs |
| simulated responses            |
+--------------------------------+
Structural metaphor: The Art Forger and the Expert Appraiser
Imagine a forger (user simulator) who wants to sell paintings that pass as originals by a master (real human user). The forger has studied the master’s entire portfolio (training data). The old way: the forger picks one specific painting and tries to copy it exactly (reference matching). The forger ends up being good at that painting but can’t paint anything else in the master’s style.
The new way: the forger paints something new, then brings it to a world-class appraiser (discriminator). The appraiser examines the painting and gives a score: “This looks 90% real” or “this looks 30% real.” The forger practices (RL updates) to increase that score. Meanwhile, the appraiser also gets better by studying real paintings and previous forgeries. Over time, the forger learns the master’s entire style—not just one canvas. The forger can now produce any new painting that the appraiser cannot distinguish from a real masterwork.
Mapping:
- Forger → User Simulator LLM
- Appraiser → Discriminator LLM
- Style of master → Distribution of real user responses
- Forgery practice → RL episode
- Appraiser’s score → Reward
- The appraiser also training → Discriminator fine-tuning
Key Concepts
-
Turing Test as a Reward Signal: A Turing test decides if an agent is indistinguishable from a human. Here it’s applied *locally: given a context, can a judge tell whether a response came from a real user or a machine? The score from the judge becomes the reinforcement signal. This is fundamentally different from supervised loss because the judge learns what “real” looks like across the whole dataset, and the simulator learns to match that distribution rather than a single point.
-
Reinforcement Learning from Learned Rewards: When the true reward (human judgment) is too expensive to query at every step, a learned proxy can be used. Here the discriminator is that proxy. The simulator is free to explore any response; as long as the discriminator finds it realistic, it gets high reward. This encourages diversity and naturalness.
-
Adversarial Min-Max Dynamics: The objective can be thought of as a two-player game: the simulator maximizes the discriminator’s error, the discriminator minimizes its error. This drives both models toward a Nash equilibrium where the simulator’s output distribution matches the real user’s distribution. Intuitively, the discriminator only gets better by seeing harder fakes, and the simulator only gets better by facing a tougher judge.
Framework Shift
The core shift is from point-wise matching to distribution-wise indistinguishability.
Before (mainstream approach):
+-----------------------------------+
| Training:                          |
|   Input: (history, real_response)  |
|   Objective: P(simulator_output)   |
|   close to real_response           |
|   Method: MLE or similarity reward |
+-----------------------------------+
| Simulator learns to reproduce      |
| the single most "correct" token    |
| sequence for a given history       |
+-----------------------------------+

After (this paper):
+------------------------------------------+
| Training:                                  |
|   Input: (history, real_response)          |
|   Objective: simulator_output should      |
|   be indistinguishable from real by judge |
|   Method: RL with discriminator reward     |
+------------------------------------------+
| Simulator learns to sample from the       |
| full distribution of plausible human      |
| responses for that history                |
+------------------------------------------+
One sentence: From “make this output look like the label” to “make your outputs look like they came from the label’s author.”
Expert Assessment
Problem choice: Real and timely. As LLM-based assistants become widespread, better user simulators are needed for evaluation and training. The existing approach of SFT/MLE is clearly insufficient for capturing human variability. This paper identifies a concrete boundary and attacks it with a clean idea.
Method maturity: Clever insight rather than brute force. The core idea (Turing test reward) is elegant and well-motivated. The implementation uses standard RL (PPO) and a standard discriminator, so the novelty is in the *framing and reward design, not in complex machinery. A simpler approach might be to use GAN-style training directly, but that often suffers instability; the authors’ two-stage pretrain+RL scheme is a pragmatic middle ground.
Experimental integrity: Baselines (MLE, SimRL) are fair and representative. Results are consistent across two domains (conversational chat and Reddit) and are confirmed by both automated LLM-based evaluation and human judgment. Sample sizes in human evaluation are modest (~100-200 per condition) but sufficient for a clear trend. One minor red flag: the SimRL baseline uses BLEU+distinctness, which is not the strongest similarity reward (e.g., BERTScore might be better). However, the paper still shows a clear win, and the comparison is defensible.
Writing quality: Clear and well-organized. The abstract sets up the gap properly. The figures are helpful. The discussion of limitations is a bit thin—they could elaborate on when the discriminator might fail (e.g., with very long contexts or rare user types). That section, if expanded, would strengthen the paper’s credibility.
Verdict: strong accept — A well-motivated, cleanly executed paper that offers a genuine improvement over a widely used approach. The idea is portable and likely to influence future user simulation work.
Takeaways
- Use a learned discriminator as a reward function for free-form generation tasks where “correctness” is ill-defined but human-likeness is desired.
- Pretrain the simulator with supervised learning before RL to give the discriminator a good starting point; otherwise the discriminator trivially rejects everything.
- Periodically update the discriminator to prevent mode collapse and maintain a meaningful reward landscape.
- The Turing test framing can be applied beyond user simulation: any task that asks “does this output sound like it came from a specific distribution?” (e.g., style transfer, persona grounding).
- If you are building a user simulator for evaluation of dialog systems, switching from MLE to a Turing-reward RL training is a concrete, low-risk upgrade that yields more realistic synthetic users.
论文: 2606.19336 作者: Yingshan Susan Wang, Cedegao E. Zhang, Linlu Qiu, Zexue He, Pengyuan Li, Alex Pentland, Roger P. Levy, Yoon Kim 分类: cs.CL
缺口
现有的用户模拟器都是在大语言模型上训练,使其匹配单一的真实回复。 主流方法有两种:
- 极大似然估计(MLE):最大化参考回复的对数概率。
- 基于相似度的强化学习(SimRL):用 BLEU 或 BERTScore 等指标衡量生成回复与参考回复的相似度,以此作为奖励。
这两种方法都假设匹配一个正确答案就够了。 但人类的回复是多样的——同一个上下文可以有多种合理的回应。 训练模型只匹配单个目标,要么迫使模型在所有可能之间取平均(输出平淡无奇),要么让模型过拟合那一句话。 这样得到的模拟器无法忠实反映真实用户行为背后的完整分布。
本文指出,这种分布不匹配是根本局限。 核心洞见:与其奖励与某个“正确”回复的接近程度,不如奖励生成回复与真实用户回复集合的不可区分性。 他们用图灵测试来实现:一个裁判(判别器)尝试分辨真实回复与模拟器生成的回复;模拟器获得的奖励就是它骗过裁判的程度。 训练信号从“这个答案离正确答案有多近”变成了“这句话可能是一个真实用户说的吗?”
[ 问题:模拟器只匹配单一参考                             ]
[   - MLE: 最大化 P(参考|上下文)                          ]
[   - SimRL: 最大化 相似度(参考, 生成)                   ]
[    |                                                    ]
[    ↓                                                    ]
[ 局限:忽略真实回复的多样性;输出要么平淡要么过拟合     ]
[    |                                                    ]
[    ↓                                                    ]
[ 关键洞见:用图灵测试作为奖励函数                       ]
[   - 奖励 = P(判别器判为真实)                             ]
[    |                                                    ]
[    ↓                                                    ]
[ 方法:Turing-RL(PPO + 判别器奖励)                    ]
[    |                                                    ]
[    ↓                                                    ]
[ 证据:在 LLM 评估和人工评估上都超越 MLE/SimRL          ]
[    |                                                    ]
[    ↓                                                    ]
[ 结论:优化不可区分性 > 优化匹配单一样本                ]
增量
一句话:本文之前,用户模拟器被训练成“照抄标准答案”;本文之后,模拟器被训练成“混入真实用户群”,让各种可能的回复都能被合法生成。
核心机制
方法包含两个主要组件:
- 用户模拟器 LLM(策略)——一个自回归语言模型,根据对话历史生成回复。这是我们要训练的模型。
- 判别器 LLM(裁判)——另一个语言模型,接收相同的历史和一条回复,输出一个标量分数:该回复来自真实人类的概率(而非来自模拟器)。
训练时的数据流:
- 对于每个训练样本(历史 + 真实回复),模拟器生成一条合成回复。
- 判别器给真实回复打分(应高)和给合成回复打分(应低)。判别器通过二分类训练来最大化这个差距。
- 合成回复的判别器分数被用作模拟器的奖励。模拟器用 PPO 算法更新以最大化该奖励。
- 定期用新的真实+合成数据微调判别器,防止被模拟器钻空子。
这形成了一个共生式的 min-max 博弈:模拟器试图骗过判别器;判别器努力不被骗。奖励是动态的,随模拟器进步而调整。
+-----------------------+          +-----------------------+
| 用户模拟器 (RL)       |          | 判别器 (裁判)         |
| 策略: LLM             |--------->| LLM 打分              |
| 输入: 历史            |          | 回复是真实的吗?      |
| 输出: 回复            |          | 输出: 分数 [0,1]     |
+-----------+----------+          +----------+------------+
            |                                ^
            | 奖励 = 分数                     |
            ↓                                |
+--------------------------------+          |
| 强化学习 (PPO)                 |          |
| 更新模拟器以最大化             |          |
| 生成回复的奖励                 |          |
+--------------------------------+          |
         |                                   |
         | (定期)                             |
         ↓                                   |
+--------------------------------+          |
| 更新判别器:                    |----------+
| 二分类:真实 vs 模拟回复        |
+--------------------------------+
结构性比喻:艺术伪造者和鉴定专家
设想一个伪造者(用户模拟器)想出售能冒充大师(真实用户)真迹的画作。 伪造者研究了大师的全部作品集(训练数据)。旧做法:伪造者选中一幅画,死磕临摹(匹配参考)。 结果他只擅长那一幅,根本不会大师的风格。
新做法:伪造者画一幅新画,拿去给世界级鉴定专家(判别器)看。 专家仔细审视后给出评分:“这幅90%像真的”或“30%像真的”。 伪造者不断练习(RL 更新)来提高这个分数。 与此同时,专家也在不断学习真迹和之前的赝品。 最终,伪造者学到了大师的整个风格——不仅仅是某一张画布。 现在他能画任何新画,让专家无法分辨是真是假。
映射关系:
- 伪造者 → 用户模拟器 LLM
- 鉴定专家 → 判别器 LLM
- 大师风格 → 真实用户回复的分布
- 伪造练习 → RL 回合
- 专家评分 → 奖励
- 专家也在不断提高 → 判别器微调
关键概念
-
图灵测试作为奖励信号:图灵测试判断一个智能体是否与人类不可区分。本文将其局部化:给定上下文,裁判能否区分这是一个真实用户还是一种机器?裁判的分数变成了强化信号。这与监督损失有本质区别——裁判学会了整个数据集里“真实”的样子,而模拟器则学习匹配那个分布,而不是一个点。
-
从学习到的奖励中做强化学习:当真实奖励(人工判断)太昂贵时,可以用一个学习到的代理。这里的判别器就是那个代理。模拟器可以自由探索任何回复;只要裁判觉得真实,就能得高分。这鼓励多样性和自然度。
-
对抗性极小极大博弈:目标可以看作两个玩家的博弈:模拟器最大化判别器的错误率,判别器最小化自己的错误率。这会驱动两个模型走向纳什均衡——模拟器的输出分布与真实用户分布一致。直观地说,判别器只有看到更难分辨的假货才会变强;模拟器只有面对更严厉的裁判才会变强。
框架转变
核心转变是从逐点匹配变为分布不可区分性。
之前(主流方法):
+-----------------------------------+
| 训练:                             |
|   输入:(历史, 真实回复)           |
|   目标:模拟器的输出              |
|   接近真实回复                     |
|   方法:MLE 或相似度奖励          |
+-----------------------------------+
| 模拟器学会了在给定历史下          |
| 重复那条“最正确”的 token 序列    |
+-----------------------------------+

之后(本文方法):
+------------------------------------------+
| 训练:                                      |
|   输入:(历史, 真实回复)                    |
|   目标:模拟器的输出必须                    |
|   让裁判无法与真实区分                      |
|   方法:强化学习 + 判别器奖励              |
+------------------------------------------+
| 模拟器学会了从所有可能的人类              |
| 回复分布中采样                            |
+------------------------------------------+
一句话:从**“让输出像标签”转变为“让你的输出看起来像是标签作者写的”**。
专家评审
选题眼光:真实且及时。随着基于 LLM 的助手越来越普遍,更好的用户模拟器对评估和训练至关重要。现有 SFT/MLE 方法显然不足以捕捉人类的多样性。本文准确指出了边界,并用一个干净的想法突破了它。
方法成熟度:巧劲而非蛮力。核心想法(图灵测试奖励)优雅且动机充分。实现使用了标准的 RL(PPO)和标准的判别器,新颖之处在于框架设计和奖励设计,而非复杂的机制。可能存在更简单的方法(直接 GAN),但 GAN 训练常不稳定,作者的两阶段预训练+RL 方案是务实的折中。
实验诚意:基线(MLE, SimRL)公平且有代表性。结果在两个领域(对话聊天和 Reddit 论坛)上一致,并同时得到自动化 LLM 评估和人工评估的确认。人工评估的样本量较小(每个条件约100-200条),但趋势足够清晰。一个需要留意的细节:SimRL 基线使用的 BLEU+Distinctness 并非最强的相似度奖励(BERTScore 可能更好)。不过论文依然显示出明显优势,比较是站得住脚的。
写作功力:清晰且组织良好。摘要正确建立了缺口。图示有帮助。局限讨论略显单薄——可以多谈谈判别器失灵的时机(比如上下文太长或用户类型太罕见)。如果能扩展那部分,会提升论文的可信度。
判决:强接收 —— 动机好、执行干净的论文,对广泛使用的方法提供了真正的改进。这个想法可移植性强,很可能影响未来的用户模拟研究。
要点总结
- 用学习到的判别器作为奖励函数:适用于“正确性”难以定义但“像人”非常重要的自由生成任务。
- 先用监督学习预训练模拟器:给判别器一个好的起点,否则判别器一开始就会把所有生成结果都判为假。
- 定期更新判别器:防止模式崩坏,维持有意义的奖励景观。
- 图灵测试框架超越用户模拟:所有需要回答“这个输出是否来自特定的分布?”的任务(如风格迁移、角色一致性)都可以借鉴。
- 如果你正在构建用于评估对话系统的用户模拟器,从 MLE 切换到图灵奖励的 RL 训练是一个具体、低风险、且能提供更真实模拟用户的升级。