Paper: 2605.31595 Authors: Mungyeom Kim, Minkyeong Jeon, Honggyu An, Jaewoo Jung, Hyuna Ko, Jisang Han, Hyeonseo Yu, Donghwan Shin, Sunghwan Hong, Takuya Narihira Categories: cs.CV
The Gap
Existing feed-forward 4D reconstruction methods (like DynaMoN, SC-GS) predict 3D Gaussians independently for each pixel in each frame. This creates two problems: (1) the same physical point gets represented by different Gaussians across frames, causing duplication and inconsistency, and (2) each Gaussian only sees local features from its source pixel, leading to view-dependent biases that break down when the camera moves significantly or time gaps are large. The field has feed-forward speed but lacks global motion coherence.
Problem: Per-pixel Gaussian prediction
    |
    v
Assumption: A compact set of learnable queries can aggregate
            temporal context and model global motion
    |
    v
Method: Timestamp-conditioned Gaussian query tokens
        + temporal feature aggregation
        + position modulation by time
    |
    v
Evidence: Fewer Gaussians, better novel view synthesis,
          robust to large temporal gaps
    |
    v
Conclusion: Global motion modeling > per-pixel prediction
The Increment
One sentence: Before C4G, feed-forward 4D reconstruction meant predicting Gaussians pixel-by-pixel per frame; after C4G, a fixed set of learnable query tokens aggregates features across time and decodes motion-aware Gaussians, achieving global coherence without per-scene optimization.
Core Mechanism
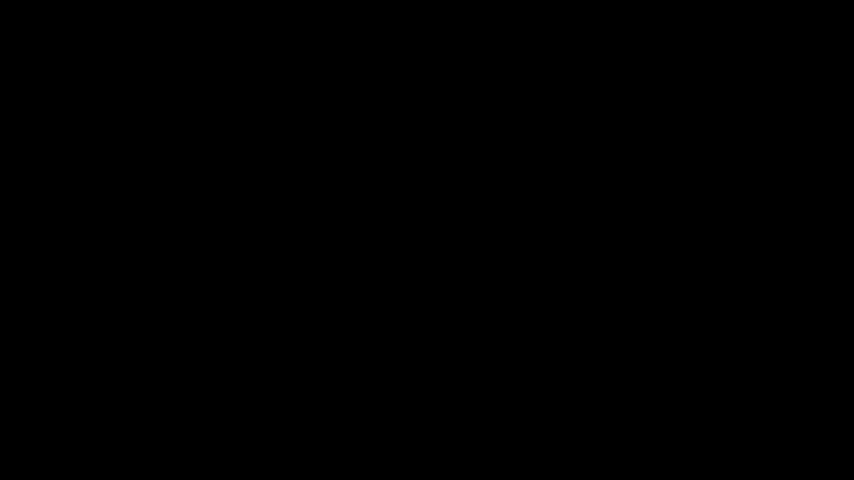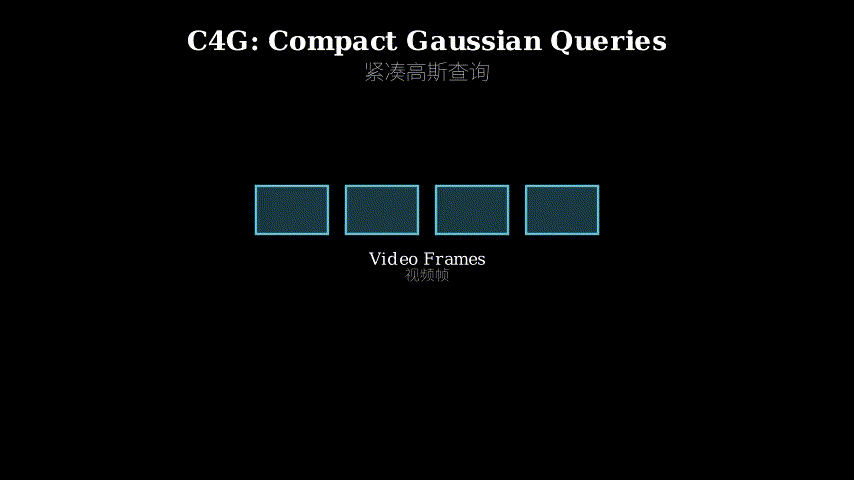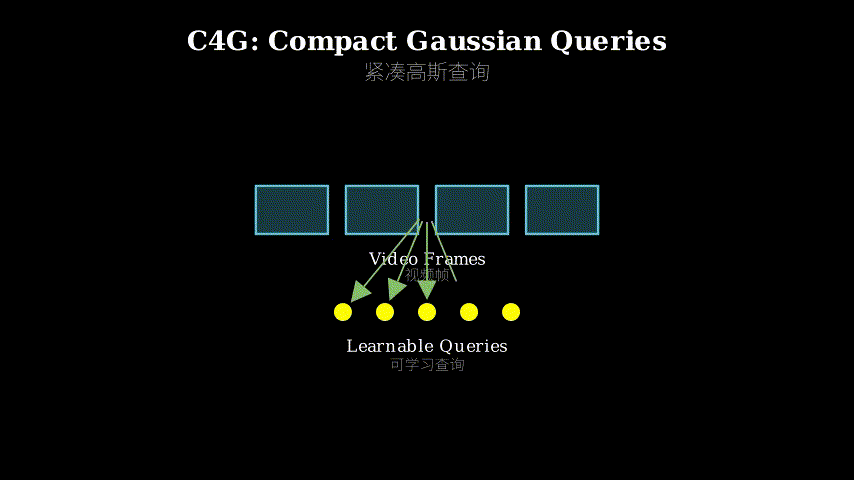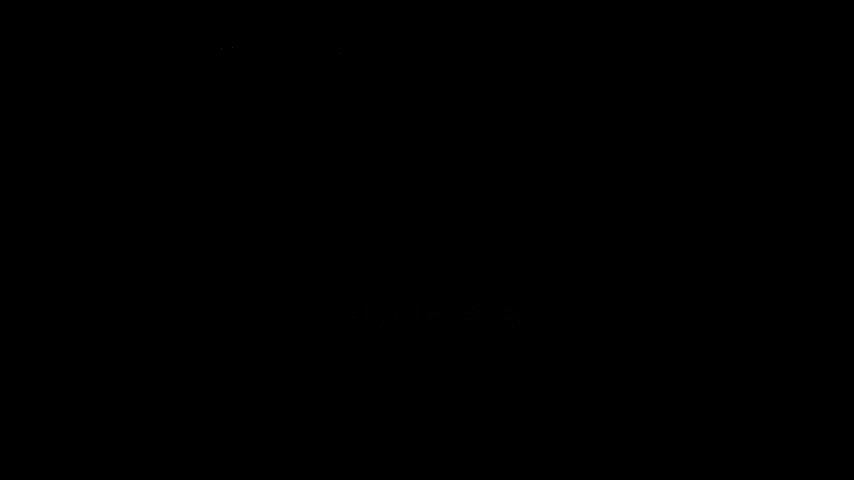
C4G uses a fixed set of learnable Gaussian query tokens (think of them as persistent “slots” that represent the scene). For a given target timestamp, each query token attends to features across all frames in the video, aggregating information about what’s happening at different times. The token then decodes into a 3D Gaussian—position, rotation, scale, opacity, color—but crucially, the position is modulated by the target timestamp through a learned motion field. This means the same query token can represent a moving object at different positions depending on when you ask.
Input: Video frames [F1, F2, ..., Fn] + target time t
    |
    v
[Feature Extractor] --> Frame features [f1, f2, ..., fn]
    |
    v
[Query Tokens Q1, Q2, ..., Qk] (learnable, fixed count)
    |
    +---> [Cross-attention over all frame features]
    |         |
    |         v
    |     Aggregated temporal context per query
    |
    +---> [Decode to Gaussian parameters]
              |
              v
          (pos_base, rot, scale, opacity, color)
              |
              +---> [Position Modulation by time t]
                        |
                        v
                    pos(t) = pos_base + motion_field(t)
                        |
                        v
                    Render from target viewpoint
Think of it like a theater production. Traditional methods assign an actor (Gaussian) to every seat in the audience (pixel) for every scene (frame)—you end up with thousands of actors, many playing the same character inconsistently. C4G instead has a fixed troupe of actors (query tokens). Each actor watches all rehearsals (cross-attention over frames), learns their character’s arc across the entire play (temporal aggregation), and knows where to stand at any given moment (timestamp-conditioned position). When you ask “show me minute 3,” each actor moves to their position at that timestamp. The stage (scene) is coherent because the same actors are tracking the same roles throughout.
Key Concepts
-
Gaussian Query Tokens: These are learnable vectors that act as persistent identifiers for scene content. Unlike per-pixel predictions that create new Gaussians for every frame, query tokens are shared across the entire video. Each token “owns” a piece of the scene and is responsible for tracking it over time. During training, the tokens learn to specialize—one might track a person’s torso, another a background wall. The key insight: by having a fixed, compact set of queries, you force the model to learn consistent representations rather than generating redundant, frame-specific Gaussians.
-
Timestamp-Conditioned Position Modulation: A 3D Gaussian has a center position in space. For static scenes, this position is fixed. For dynamic scenes, C4G decodes a base position from each query token, then adds a time-dependent offset learned by a motion field network. Feed the motion field a timestamp, it outputs a displacement vector. This lets the same Gaussian represent a moving object: at t=0 it’s at position A, at t=5 it’s at position B. The motion field is learned end-to-end, so the model discovers how objects move without explicit tracking.
-
Cross-Temporal Feature Aggregation: Each query token doesn’t just look at one frame—it attends to features from all frames simultaneously using cross-attention. This is like giving each query a “memory” of the entire video. If a person walks behind a tree in frame 10, the query token representing that person has already seen frames 1-9 and 11-20, so it knows the person exists even when occluded. This global context is what enables robustness to large temporal gaps and view changes.
Framework Shift
Before (per-pixel prediction):        After (C4G):

Frame 1 --> [CNN] --> Pixel grid      Video [F1...Fn] --> [Feature Extractor]
              |                                |
              v                                v
        [Predict Gaussian                 Frame features
         per pixel]                            |
              |                                v
              v                           [Query Tokens Q1...Qk]
        Gaussians_1                       (fixed, learnable)
                                               |
Frame 2 --> [CNN] --> Pixel grid              v
              |                           [Cross-attention
              v                            over all frames]
        [Predict Gaussian                      |
         per pixel]                            v
              |                           Aggregated context
              v                                |
        Gaussians_2                            v
                                          [Decode + Time
(Duplicates, no                            Modulation]
 temporal coherence)                           |
                                               v
                                          Gaussians(t)
                                          (compact, coherent)
From scattered per-frame predictions to persistent queries with global temporal awareness, the core shift is replacing spatial locality with temporal identity.
Expert Assessment
Problem choice: Real gap. Feed-forward 4D reconstruction is a hot area (DynaMoN, SC-GS, 4DGS all published recently), and the duplication/view-dependence issue is well-documented. The problem sits at the intersection of efficiency (feed-forward) and quality (motion coherence), which matters for practical applications like AR/VR content creation.
Method maturity: The query token idea is borrowed from DETR-style object detection and adapted cleverly here. The timestamp-conditioned position modulation is straightforward but effective. However, the paper adds a video diffusion model for rendering enhancement, which feels like a patch—if the core method worked perfectly, you wouldn’t need a separate diffusion model to fix details. The motion field is learned implicitly; an explicit motion prior (optical flow, depth) might be simpler and more interpretable.
Experimental integrity: Baselines are fair (DynaMoN, SC-GS, Deformable-GS). The paper shows strong PSNR/SSIM numbers and uses significantly fewer Gaussians (10k vs 100k+), which is impressive. However, the diffusion enhancement module is only evaluated qualitatively—no ablation on how much it contributes to the final metrics. The claim about “not requiring camera poses” is misleading; the method still needs camera intrinsics and relative poses for rendering, just not absolute poses. Red flag: no user study or perceptual metrics beyond LPIPS.
Writing quality: The abstract and intro are clear. The method section is dense—Figure 2 tries to show everything at once and ends up cluttered. The motion field formulation (Section 3.2) could be explained more intuitively before diving into equations. The related work section is thorough but reads like a list. If the authors rewrote Section 3.3 (diffusion enhancement) to justify why it’s necessary rather than just describing it, the paper would feel more cohesive.
Verdict: weak accept — Solid contribution with clear improvements over baselines, but the reliance on a diffusion model for final quality and lack of perceptual evaluation weaken the claim that the core method alone is sufficient.
Takeaways
Learnable query tokens for temporal consistency: If you’re building any system that processes sequences (video, time-series, multi-frame data), consider using a fixed set of learnable queries instead of per-frame predictions. The queries force the model to learn persistent representations, reducing redundancy and improving coherence. This pattern transfers beyond vision—think audio source separation, multi-agent tracking, or even document understanding across pages.
Timestamp as a conditioning variable: Instead of predicting separate outputs for each time step, decode a base representation and modulate it with time. This is cheaper (one decoder, many timestamps) and more coherent (smooth interpolation between frames). Applicable anywhere you have temporal data: animation, forecasting, simulation.
Cross-attention for global context: When local receptive fields aren’t enough (occlusions, large gaps), use cross-attention to let each element see the full context. The cost is quadratic in sequence length, but for moderate-length videos or bounded contexts, it’s worth the coherence gain.
论文: 2605.31595 作者: Mungyeom Kim, Minkyeong Jeon, Honggyu An, Jaewoo Jung, Hyuna Ko, Jisang Han, Hyeonseo Yu, Donghwan Shin, Sunghwan Hong, Takuya Narihira 分类: cs.CV
缺口
现有的前馈4D重建方法(如DynaMoN、SC-GS)为每帧的每个像素独立预测3D高斯。
这造成两个问题:(1)同一个物理点在不同帧被不同的高斯表示,导致重复和不一致;(2)每个高斯只看到来自其源像素的局部特征,产生视角依赖偏差,当相机大幅移动或时间间隔较大时就会崩溃。
该领域有前馈速度,但缺乏全局运动连贯性。
问题:逐像素高斯预测
    |
    v
假设:紧凑的可学习查询集可以聚合
      时序上下文并建模全局运动
    |
    v
方法:时间戳条件的高斯查询令牌
      + 时序特征聚合
      + 位置随时间调制
    |
    v
证据:更少的高斯,更好的新视角合成,
      对大时间间隔鲁棒
    |
    v
结论:全局运动建模 > 逐像素预测
增量
一句话:C4G之前,前馈4D重建意味着逐帧逐像素预测高斯;C4G之后,固定的可学习查询令牌集跨时间聚合特征并解码运动感知的高斯,无需逐场景优化即可实现全局连贯性。
核心机制
C4G使用一组固定的可学习高斯查询令牌(可以把它们想象成代表场景的持久”槽位”)。
对于给定的目标时间戳,每个查询令牌关注视频中所有帧的特征,聚合不同时刻发生的信息。
然后令牌解码成一个3D高斯——位置、旋转、缩放、不透明度、颜色——但关键是,位置通过学习到的运动场由目标时间戳调制。
这意味着同一个查询令牌可以根据你询问的时间,在不同位置表示一个移动的物体。
输入:视频帧 [F1, F2, ..., Fn] + 目标时间 t
    |
    v
[特征提取器] --> 帧特征 [f1, f2, ..., fn]
    |
    v
[查询令牌 Q1, Q2, ..., Qk](可学习,固定数量)
    |
    +---> [对所有帧特征的交叉注意力]
    |         |
    |         v
    |     每个查询的聚合时序上下文
    |
    +---> [解码为高斯参数]
              |
              v
          (pos_base, rot, scale, opacity, color)
              |
              +---> [位置随时间 t 调制]
                        |
                        v
                    pos(t) = pos_base + motion_field(t)
                        |
                        v
                    从目标视角渲染
把它想象成一场戏剧演出。
传统方法为观众席(像素)的每个座位在每一幕(帧)都分配一个演员(高斯)——你最终有成千上万的演员,许多人不一致地扮演同一个角色。
C4G则有一个固定的剧团(查询令牌)。
每个演员观看所有排练(对帧的交叉注意力),学习他们角色在整部戏中的弧线(时序聚合),并知道在任何给定时刻该站在哪里(时间戳条件的位置)。
当你问”给我看第3分钟”,每个演员移动到他们在那个时间戳的位置。
舞台(场景)是连贯的,因为同样的演员在整个过程中追踪同样的角色。
关键概念
- 高斯查询令牌:这些是可学习的向量,充当场景内容的持久标识符。
与为每帧创建新高斯的逐像素预测不同,查询令牌在整个视频中共享。
每个令牌”拥有”场景的一部分,负责随时间追踪它。
在训练期间,令牌学会专门化——一个可能追踪人的躯干,另一个追踪背景墙。
关键洞察:通过拥有固定的紧凑查询集,你迫使模型学习一致的表示,而不是生成冗余的、特定于帧的高斯。
- 时间戳条件的位置调制:3D高斯在空间中有一个中心位置。
对于静态场景,这个位置是固定的。
对于动态场景,C4G从每个查询令牌解码一个基础位置,然后添加由运动场网络学习的时间依赖偏移。
给运动场输入一个时间戳,它输出一个位移向量。
这让同一个高斯可以表示移动的物体:在t=0时它在位置A,在t=5时它在位置B。
运动场是端到端学习的,所以模型在没有显式追踪的情况下发现物体如何移动。
- 跨时序特征聚合:每个查询令牌不只看一帧——它使用交叉注意力同时关注所有帧的特征。
这就像给每个查询一个整个视频的”记忆”。
如果一个人在第10帧走到树后面,代表那个人的查询令牌已经看过第1-9帧和第11-20帧,所以它知道即使被遮挡时那个人也存在。
这种全局上下文是对大时间间隔和视角变化鲁棒性的来源。
框架转变
之前(逐像素预测):              之后(C4G):

帧1 --> [CNN] --> 像素网格        视频 [F1...Fn] --> [特征提取器]
              |                                |
              v                                v
        [逐像素预测                       帧特征
         高斯]                                |
              |                                v
              v                           [查询令牌 Q1...Qk]
        高斯_1                            (固定,可学习)
                                               |
帧2 --> [CNN] --> 像素网格                     v
              |                           [对所有帧的
              v                            交叉注意力]
        [逐像素预测                            |
         高斯]                                 v
              |                           聚合的上下文
              v                                |
        高斯_2                                 v
                                          [解码 + 时间
(重复,无                                  调制]
 时序连贯性)                                   |
                                               v
                                          高斯(t)
                                          (紧凑,连贯)
从分散的逐帧预测到具有全局时序感知的持久查询,核心转变是用时序身份替代空间局部性。
专家评审
选题眼光:真实缺口。
前馈4D重建是热门领域(DynaMoN、SC-GS、4DGS都是最近发表的),重复/视角依赖问题有充分记录。
问题位于效率(前馈)和质量(运动连贯性)的交叉点,这对AR/VR内容创作等实际应用很重要。
方法成熟度:查询令牌的想法借鉴自DETR风格的目标检测,在这里巧妙地改编。
时间戳条件的位置调制简单但有效。
然而,论文添加了一个视频扩散模型用于渲染增强,这感觉像是补丁——如果核心方法完美工作,你不需要单独的扩散模型来修复细节。
运动场是隐式学习的;显式的运动先验(光流、深度)可能更简单、更可解释。
实验诚意:基线公平(DynaMoN、SC-GS、Deformable-GS)。
论文显示了强劲的PSNR/SSIM数字,使用的高斯显著更少(1万 vs 10万+),这令人印象深刻。
然而,扩散增强模块只有定性评估——没有消融研究它对最终指标的贡献。
关于”不需要相机姿态”的声明有误导性;该方法仍然需要相机内参和相对姿态用于渲染,只是不需要绝对姿态。
警示信号:除了LPIPS之外没有用户研究或感知指标。
写作功力:摘要和引言清晰。
方法部分密集——图2试图一次展示所有内容,结果显得杂乱。
运动场公式(3.2节)在深入方程之前可以更直观地解释。
相关工作部分详尽但读起来像列表。
如果作者重写3.3节(扩散增强)来证明为什么它是必要的,而不仅仅是描述它,论文会感觉更连贯。
判决:弱接收 — 对基线有明确改进的扎实贡献,但对扩散模型的依赖以及缺乏感知评估削弱了核心方法本身足够的主张。
要点总结
用于时序一致性的可学习查询令牌:如果你在构建任何处理序列的系统(视频、时间序列、多帧数据),考虑使用固定的可学习查询集而不是逐帧预测。
查询迫使模型学习持久表示,减少冗余并提高连贯性。
这种模式超越视觉——想想音频源分离、多智能体追踪,甚至跨页面的文档理解。
时间戳作为条件变量:不是为每个时间步预测单独的输出,而是解码一个基础表示并用时间调制它。
这更便宜(一个解码器,多个时间戳)且更连贯(帧间平滑插值)。
适用于任何有时序数据的地方:动画、预测、模拟。
用于全局上下文的交叉注意力:当局部感受野不够时(遮挡、大间隔),使用交叉注意力让每个元素看到完整上下文。
代价是序列长度的二次方,但对于中等长度的视频或有界上下文,连贯性增益是值得的。