Paper: 2605.31586 Authors: Wesley Scivetti, Ethan Wilcox, Nathan Schneider, Kanishka Misra, Leonie Weissweiler Categories: cs.CL, cs.AI
The Gap
Prior work showed that only the largest LLMs (GPT-4 scale) could handle rare constructions—fixed form-meaning pairings like “let alone” or “much less” that carry specific semantic constraints. The field assumed this was a capability threshold: you either have 100B+ parameters or you fail. But no one systematically tested open-source models across different scales, architectures, and training data sizes. More critically, no one tracked when during training these models acquire constructional understanding, or what other knowledge correlates with that acquisition.
This paper fills both gaps: (1) Do modestly sized open models actually understand Paired-Focus constructions? (2) What learning dynamics underlie this understanding—does it emerge early with syntax, or later with semantics?
Problem: Rare constructions assumed to need massive scale
   |
   v
Assumption: Understanding = syntax + semantics, but which comes first?
   |
   v
Method: Novel dataset testing both form and meaning across model scales
   |      + training dynamics analysis on open-checkpoint models
   v
Evidence: Modest models succeed; semantics emerges AFTER syntax,
   |       correlated with world knowledge gains
   v
Conclusion: Constructional semantics is learnable at modest scale,
            but requires substantial pretraining data
The Increment
One sentence: Before this paper, we thought rare construction understanding required 100B+ parameters; after, we know 7B-13B models can do it if trained on enough data, and that semantic understanding lags behind syntactic knowledge by a measurable training interval.
Core Mechanism
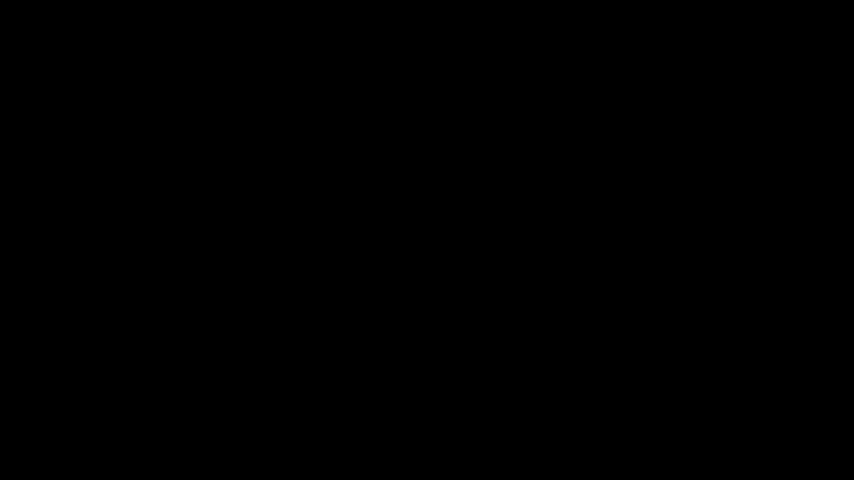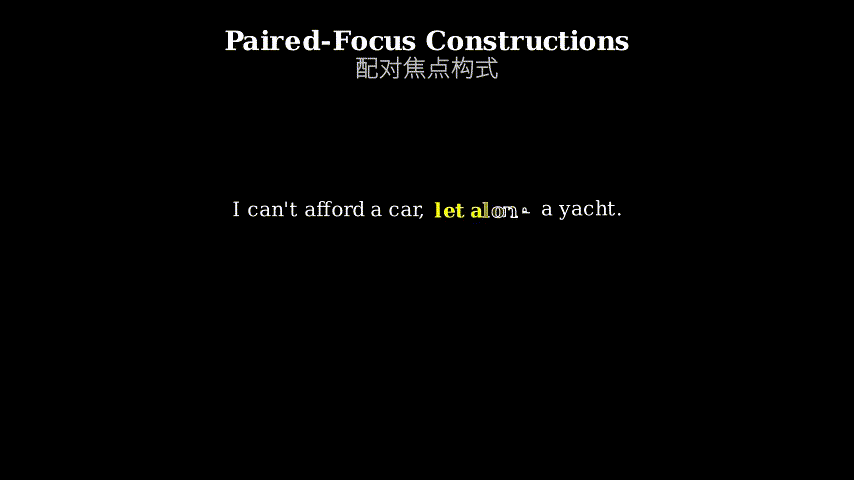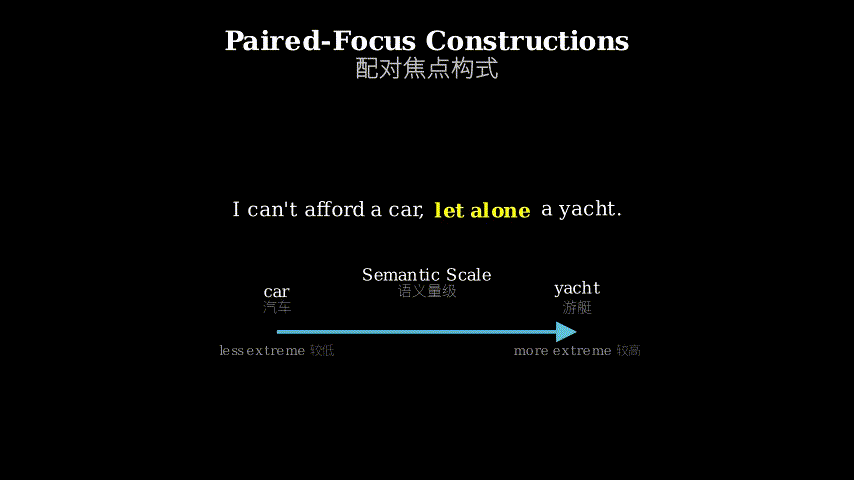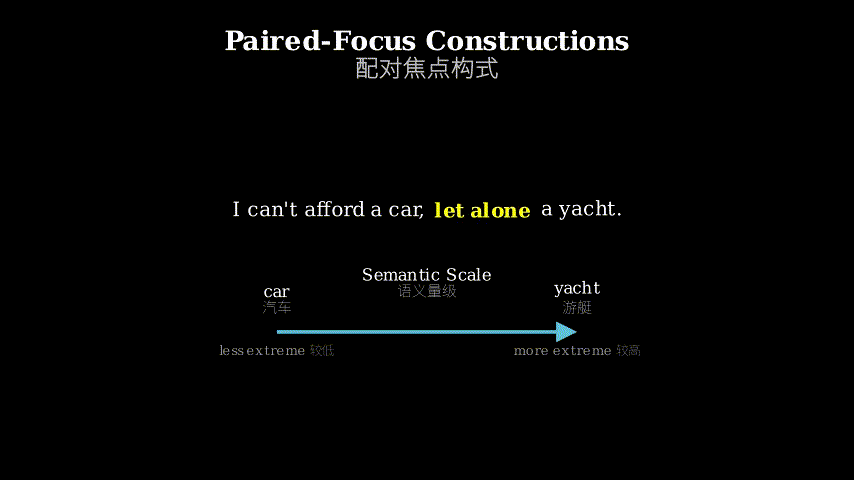
The method has three components. First, a novel dataset targeting Paired-Focus constructions (PFCs) like “let alone” and “much less.” These constructions have a specific semantic constraint: the second item must be more extreme on some scale than the first (“He can’t run a mile, let alone a marathon”). The dataset tests both syntactic knowledge (can the model detect PFC forms?) and semantic knowledge (does it understand the scalar ordering?).
Second, a cross-sectional evaluation across 20+ models varying in size (1B to 70B parameters), architecture (decoder-only, encoder-decoder), and pretraining data scale (human-scale ~10B tokens vs web-scale 1T+ tokens). This isolates which factors matter for PFC understanding.
Third, a longitudinal analysis of training dynamics using models with public checkpoints (Pythia, OLMo). By testing each checkpoint on both syntactic and semantic PFC tasks, they track when each type of knowledge emerges and what other capabilities correlate with semantic acquisition.
Dataset Construction:
  Scalar adjectives + world knowledge -> PFC test items
       |                                      |
       v                                      v
  "tall/short"                    "run mile/marathon"
       |                                      |
       +--------------------------------------+
                        |
                        v
              PFC templates with controls
              ("let alone" vs "not to mention")

Evaluation Pipeline:
  Model checkpoint -> Syntactic probe -> Form sensitivity score
       |
       +-----------> Semantic probe -> Meaning accuracy
       |
       +-----------> World knowledge tasks -> Correlation analysis
Think of this like testing whether someone truly understands sarcasm versus just recognizing the tone. You need two tests: (1) Can they identify sarcastic sentences? (That’s syntax—recognizing the form.) (2) Do they grasp that the speaker means the opposite? (That’s semantics—understanding the meaning inversion.) This paper does both for PFCs, then adds a third dimension: watching a child grow up and noting when they start catching sarcasm versus when they start using it correctly themselves. The key insight: recognizing the sarcastic tone happens earlier than understanding the meaning flip, and the meaning flip correlates with general social reasoning development.
Key Concepts
-
Paired-Focus Constructions (PFCs): Fixed phrases like “let alone,” “much less,” or “never mind” that connect two items with a built-in semantic rule: the second item must be more extreme than the first on some implicit scale. Example: “I can’t afford a bike, let alone a car” works because cars are more expensive than bikes. Flip it—“I can’t afford a car, let alone a bike”—and it sounds wrong because you violated the scalar ordering. PFCs are rare in text (appearing once per ~100K words), making them a stress test for whether models truly learn form-meaning mappings versus just memorizing common patterns.
-
Constructional semantics: The idea that meaning isn’t just in individual words but in the *construction itself—the fixed pattern carries semantic constraints independent of the words filling its slots. “Let alone X” doesn’t mean “let” + “alone” + X; it means “X is even more extreme than what I just said, so if the first thing is impossible, X is definitely impossible.” Models that learn constructional semantics grasp this constraint; models that only learn syntax might recognize “let alone” as a valid phrase but fail to enforce the scalar ordering.
-
Training dynamics vs cross-sectional evaluation: Cross-sectional is a snapshot—test many models at their final state and compare. Training dynamics is a movie—test one model at many points during training and watch knowledge emerge. Cross-sectional tells you *what matters (model size? data scale?). Training dynamics tells you when and how knowledge develops (does syntax come before semantics? what else is learned at the same time?). This paper does both: cross-sectional to identify which models succeed, training dynamics to understand the learning process.
Framework Shift
Before (mainstream approach):        After (this paper):

Rare construction understanding:     Rare construction understanding:

  [Massive scale]                     [Modest scale] + [Enough data]
        |                                    |              |
        v                                    v              v
   100B+ params                         7B-13B params   1T+ tokens
        |                                    |
        v                                    +---> Syntax first
   Success/Failure                                    |
   (binary threshold)                                 v
                                                 Semantics later
                                                      |
                                                      v
                                              (correlated with
                                               world knowledge)
One sentence: From “you need massive scale” to “you need sufficient data and patience,” the core shift is recognizing that constructional semantics is a late-emerging capability that piggybacks on world knowledge acquisition, not a parameter count threshold.
Expert Assessment
Problem choice: Real gap. The field genuinely didn’t know if open-source models could handle rare constructions, and the training dynamics question is novel. This sits at the intersection of linguistic theory (Construction Grammar) and LLM capabilities research—a productive boundary.
Method maturity: Solid execution. The dataset design is clever: using both scalar adjectives (objective ordering) and world knowledge (subjective but testable) gives two independent semantic probes. The training dynamics analysis is the paper’s strongest contribution—most capability studies are cross-sectional snapshots. One weakness: they don’t test whether models that fail semantic PFC tasks also fail *other scalar reasoning tasks, which would strengthen the claim that PFCs specifically test constructional understanding versus general scalar reasoning.
Experimental integrity: Baselines are fair. Testing 20+ models across architectures and scales is thorough. The correlation analysis between PFC semantics and world knowledge is suggestive but not causal—they show co-occurrence, not that one causes the other. The human-scale data result (models trained on <100B tokens fail all semantic tests) is striking but based on only a few models; more data points would be reassuring.
Writing quality: The paper front-loads linguistic theory, which will lose some ML readers. Section 3 (dataset construction) is dense—a worked example walking through one test item’s creation would help. The training dynamics section (5.2) is excellent and should be expanded. The conclusion undersells the practical implications: if semantic understanding requires 1T+ tokens, that’s a concrete data budget recommendation for anyone training models.
Verdict: weak accept — Solid empirical work with a novel training dynamics angle, but the theoretical framing (Construction Grammar) may limit impact in the ML community, and the causal story behind the correlations needs strengthening.
Takeaways
For model trainers: If you’re training a <10B parameter model and want it to handle rare constructions, budget for 1T+ tokens of pretraining data. Syntactic knowledge emerges earlier, but semantic understanding requires substantial world knowledge first.
For evaluation designers: Testing rare constructions requires probing both form recognition and meaning understanding separately. A model can ace syntactic tests while failing semantic ones—don’t conflate the two.
For capability researchers: Training dynamics analysis (testing checkpoints throughout training) reveals more than cross-sectional comparisons. The lag between syntactic and semantic acquisition suggests a two-stage learning process: first memorize the form, then infer the meaning from distributional patterns. This pattern likely generalizes to other linguistic phenomena.
Steal this technique: The correlation analysis between target capability (PFC semantics) and auxiliary tasks (world knowledge domains) is a simple but powerful way to generate hypotheses about what knowledge underlies a capability. Apply it to other “mysterious” emergent abilities.
论文: 2605.31586 作者: Wesley Scivetti, Ethan Wilcox, Nathan Schneider, Kanishka Misra, Leonie Weissweiler 分类: cs.CL, cs.AI
缺口
先前研究表明,只有最大规模的大模型(GPT-4级别)才能处理罕见构式——像”更不用说""何况”这样携带特定语义约束的固定形式-意义配对。
学界假设这是一个能力门槛:要么有1000亿以上参数,要么失败。
但没人系统测试过不同规模、架构和训练数据量的开源模型。
更关键的是,没人追踪模型在训练过程中何时获得构式理解,或这种理解与其他知识的相关性。
本文填补两个空白:(1)中等规模的开源模型真的理解配对焦点构式吗?(2)这种理解的学习动态是什么——它与句法同时出现,还是随语义后来出现?
问题:罕见构式被认为需要大规模模型
   |
   v
假设:理解 = 句法 + 语义,但哪个先出现?
   |
   v
方法:新数据集测试不同规模模型的形式和意义
   |      + 开放检查点模型的训练动态分析
   v
证据:中等模型成功;语义在句法之后出现,
   |       与世界知识增长相关
   v
结论:构式语义在中等规模下可学习,
      但需要大量预训练数据
增量
一句话:这篇论文之前,我们以为罕见构式理解需要1000亿以上参数;之后,我们知道70-130亿参数模型在足够数据训练下也能做到,且语义理解在句法知识之后以可测量的训练间隔出现。
核心机制
方法有三个组件。
第一,针对配对焦点构式(PFC)的新数据集,如”更不用说""何况”。
这些构式有特定语义约束:第二项必须在某个尺度上比第一项更极端(“他连一英里都跑不了,更不用说马拉松”)。
数据集测试句法知识(模型能检测PFC形式吗?)和语义知识(它理解标量排序吗?)。
第二,对20多个模型进行横断面评估,这些模型在规模(10亿到700亿参数)、架构(仅解码器、编码器-解码器)和预训练数据规模(人类规模约100亿token vs 网络规模1万亿以上token)上有差异。
这隔离了哪些因素对PFC理解重要。
第三,使用有公开检查点的模型(Pythia、OLMo)进行训练动态纵向分析。
通过在句法和语义PFC任务上测试每个检查点,他们追踪何时每种知识出现,以及哪些其他能力与语义获得相关。
数据集构建:
  标量形容词 + 世界知识 -> PFC测试项
       |                        |
       v                        v
  "高/矮"              "跑一英里/马拉松"
       |                        |
       +------------------------+
                  |
                  v
        带对照的PFC模板
        ("更不用说" vs "不提")

评估流程:
  模型检查点 -> 句法探测 -> 形式敏感度分数
       |
       +-------> 语义探测 -> 意义准确度
       |
       +-------> 世界知识任务 -> 相关性分析
把这想象成测试某人是否真正理解讽刺,而不只是识别语气。
你需要两个测试:(1)他们能识别讽刺句子吗?(这是句法——识别形式。
)(2)他们理解说话者的意思相反吗?(这是语义——理解意义反转。
)本文对PFC做这两项测试,然后加第三个维度:观察孩子成长,记录何时他们开始捕捉讽刺,何时开始正确使用。
关键洞察:识别讽刺语气比理解意义反转更早发生,意义反转与一般社会推理发展相关。
关键概念
- 配对焦点构式(PFC):像”更不用说""何况""别提”这样的固定短语,连接两个项目并带有内置语义规则:第二项必须在某个隐含尺度上比第一项更极端。
例子:“我买不起自行车,更不用说汽车”有效,因为汽车比自行车贵。
反过来——“我买不起汽车,更不用说自行车”——听起来不对,因为你违反了标量排序。
PFC在文本中罕见(每约10万词出现一次),使它们成为模型是否真正学习形式-意义映射而非仅记忆常见模式的压力测试。
- 构式语义:意义不仅在单个词中,而在**构式*本身——固定模式携带独立于填充其槽位的词的语义约束。
“更不用说X”不意味着”更”+“不”+“用”+“说”+X;它意味着”X比我刚说的更极端,所以如果第一件事不可能,X肯定不可能”。
学习构式语义的模型掌握这个约束;只学习句法的模型可能识别”更不用说”是有效短语,但无法执行标量排序。
- 训练动态 vs 横断面评估:横断面是快照——在最终状态测试许多模型并比较。
训练动态是电影——在训练期间的许多点测试一个模型,观察知识出现。
横断面告诉你什么重要(模型规模?数据规模?)。
训练动态告诉你何时和如何发展知识(句法在语义之前吗?同时学到什么?)。
本文两者都做:横断面识别哪些模型成功,训练动态理解学习过程。
框架转变
之前(主流方法):              之后(本文方法):

罕见构式理解:                  罕见构式理解:

  [大规模]                        [中等规模] + [足够数据]
      |                                |            |
      v                                v            v
  1000亿+参数                      70-130亿参数  1万亿+token
      |                                |
      v                                +---> 句法先出现
  成功/失败                                    |
  (二元门槛)                                   v
                                          语义后出现
                                               |
                                               v
                                          (与世界知识
                                           相关)
一句话:从”你需要大规模”到”你需要足够数据和耐心”,核心转变是认识到构式语义是晚期出现的能力,依附于世界知识获取,而非参数数量门槛。
专家评审
选题眼光:真实缺口。
学界确实不知道开源模型能否处理罕见构式,训练动态问题是新颖的。
这处于语言学理论(构式语法)和大模型能力研究的交叉点——一个富有成效的边界。
方法成熟度:执行扎实。
数据集设计巧妙:使用标量形容词(客观排序)和世界知识(主观但可测试)提供两个独立的语义探测。
训练动态分析是本文最强贡献——大多数能力研究是横断面快照。
一个弱点:他们没测试语义PFC任务失败的模型是否也在其他标量推理任务上失败,这会加强PFC专门测试构式理解而非一般标量推理的主张。
实验诚意:基线公平。
跨架构和规模测试20多个模型很彻底。
PFC语义与世界知识的相关性分析有启发性但非因果——他们展示共现,而非一个导致另一个。
人类规模数据结果(在少于1000亿token上训练的模型在所有语义测试上失败)引人注目,但仅基于几个模型;更多数据点会更令人放心。
写作功力:论文前置语言学理论,会失去一些机器学习读者。
第3节(数据集构建)密集——一个详细例子演示一个测试项的创建会有帮助。
训练动态部分(5.2)优秀,应该扩展。
结论低估了实际影响:如果语义理解需要1万亿以上token,这对任何训练模型的人来说是具体的数据预算建议。
判决:弱接收 — 扎实的实证工作,有新颖的训练动态角度,但理论框架(构式语法)可能限制在机器学习社区的影响,相关性背后的因果故事需要加强。
要点总结
对模型训练者:如果你训练一个小于100亿参数的模型并希望它处理罕见构式,预算1万亿以上token的预训练数据。
句法知识更早出现,但语义理解首先需要大量世界知识。
对评估设计者:测试罕见构式需要分别探测形式识别和意义理解。
模型可以在句法测试中表现优异,同时在语义测试中失败——不要混淆两者。
对能力研究者:训练动态分析(在整个训练过程中测试检查点)比横断面比较揭示更多。
句法和语义获得之间的滞后表明两阶段学习过程:首先记忆形式,然后从分布模式推断意义。
这种模式可能推广到其他语言现象。
偷走这个技术:目标能力(PFC语义)与辅助任务(世界知识领域)之间的相关性分析是一种简单但强大的方法,用于生成关于什么知识支撑某种能力的假设。
将其应用于其他”神秘”涌现能力。