Paper: 2606.27334 Authors: Mohammad Mehdi Hosseini, Mohammad H. Mahoor, Hiroko H. Dodge Categories: cs.AI
The Gap
Existing digital twin research in cognitive health focuses on physiological sensors (wearables, MRI) or structured assessments. Language, despite being a rich biomarker for Mild Cognitive Impairment (MCI), is rarely used to build personalized generative models. Prior work either extracts static features from speech (e.g., syntactic complexity) to detect MCI, or uses general-purpose LLMs to chat, but never couples them to produce a dynamic individual model that can both generate identity-consistent responses and predict cognitive scores. The gap is: can we construct a language-based digital twin that preserves a person’s conversational style while serving as a continuous cognitive monitor?
Problem: No non-invasive personalized cognitive monitor uses language as a generative model.
    v
Assumption: LLMs + stylometric cues + metadata can simulate individual speech.
    v
Method: Conditional GPT-2 + multi-head cVAE (reconstruction + MoCA regression).
    v
Evidence: Reconstruction error and MoCA prediction error on I-CONECT dataset match real data; beats GPT-2 baseline.
    v
Conclusion: Language-based digital twin is feasible for continuous monitoring.
The Increment
One sentence: Before this paper, no system could generate identity-specific conversational responses while simultaneously predicting a cognitive score from those responses; after this paper, a combined generator + assessor exists.
Core Mechanism
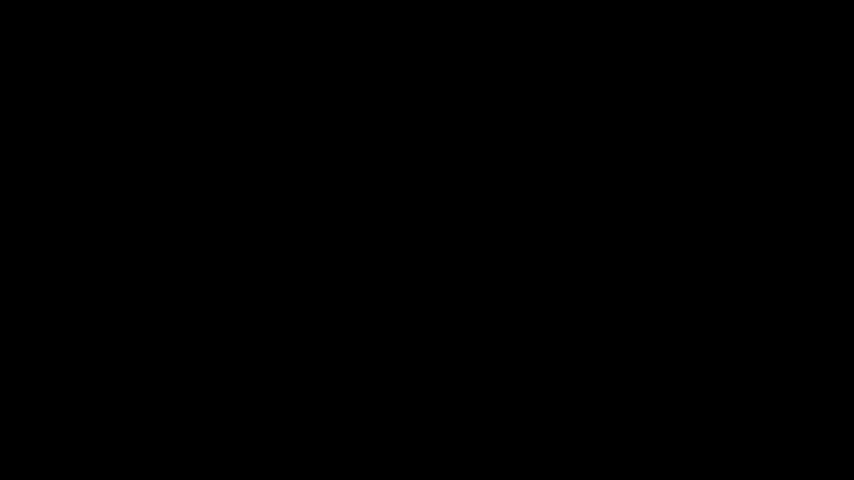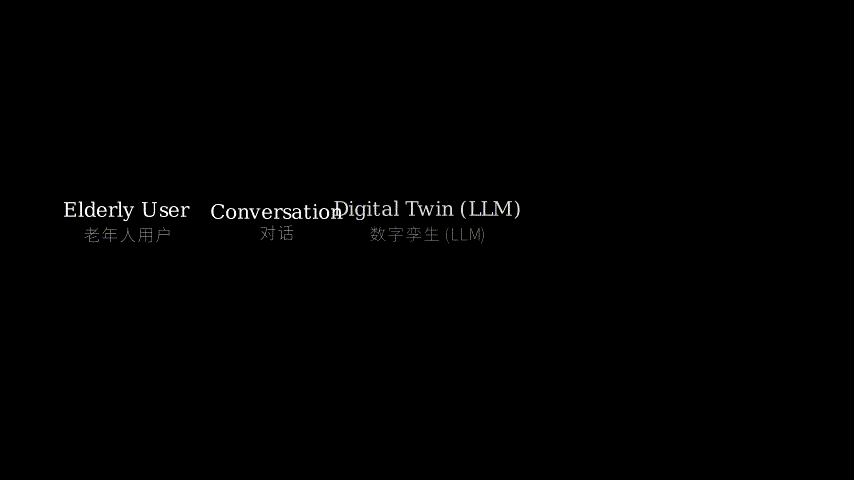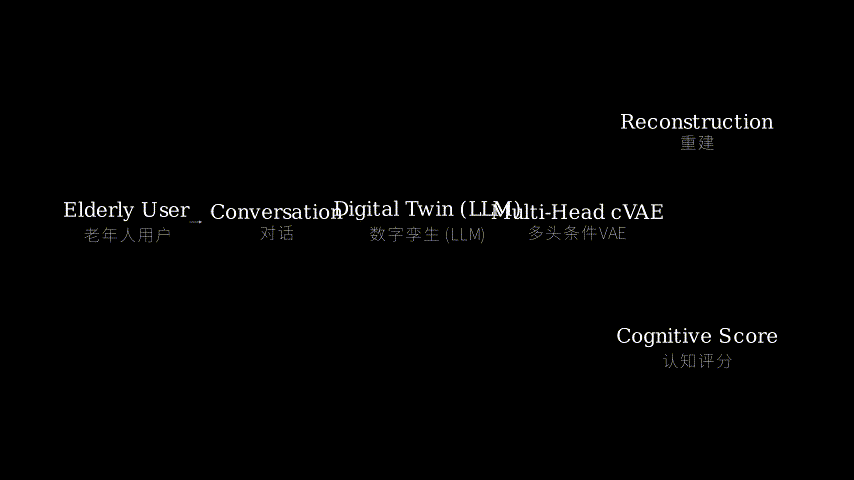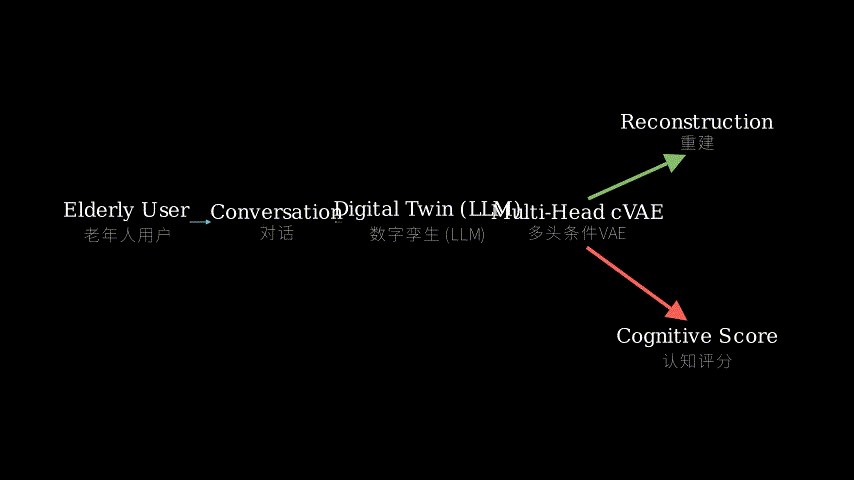
The framework has two major blocks. First, a personalized generator: a pretrained LLM (GPT-2) is conditioned on stylometric features (e.g., word length distribution, part-of-speech n-grams) and contextual metadata (age, education, topic, turn number) via learned embeddings that are concatenated with the LLM’s input tokens. This forces the generator to produce utterances that match the user’s idiosyncratic linguistic patterns. Second, a multi-head conditional VAE (cVAE) adds a variational autoencoder on top of the LLM’s hidden states. One decoder head reconstructs the original utterance (same as standard VAE), and another head regresses the MoCA (Montreal Cognitive Assessment) score from the latent vector. Training jointly optimizes reconstruction likelihood and MoCA prediction loss.
[ASCII Diagram of Method Internals]

                +-----------------+
 User History   |  Stylometric &  |
 + Metadata --->|  Meta Embedder  |
                +--------+--------+
                         |
                    +----v----+
                    | GPT-2   |
                    | (frozen)|----> Generated utterance
                    +----+----+
                         | (hidden states)
                    +----v----+
                    | cVAE    |
                    | Encoder |
                    +----+----+
                         |
              +----------+----------+
              |                     |
         +----v----+          +----v----+
         | Decoder |          | Regressor|
         | (recon) |          | (MoCA)  |
         +---------+          +---------+
              |                     |
         recon loss            MSE loss
Structural metaphor: Think of this as a personalized radio station that plays exactly what you like, and also tells your mood.
- The LLM (GPT-2) is the radio transmitter, but it broadcasts generic content.
- The stylometric and metadata embeddings act as the equalizer — they tweak the voice, tempo, word choice to sound like you.
- The cVAE encoder is a listening device that captures what the transmitter just broadcasted and compresses it into a fingerprint (latent vector).
- The two decoder heads: one is a playback head that tries to replay the broadcast (trains the system to keep the fingerprint meaningful); the other is a mood meter that reads the fingerprint and outputs a number (MoCA score).
So the system learns to broadcast in your style and, by listening to itself, estimate your cognitive state.
Key Concepts
-
Stylometric Cues: Statistical fingerprints of a person’s language — average word length, frequency of function words, punctuation habits, etc. In this paper, they extract 20 such features from each utterance (e.g., proportion of nouns, average sentence length). These are not semantic features (what you say) but *how you say it. Example: older adults with MCI often use shorter sentences and more filler words like “um”. Embedding these into the generator forces the model to mimic the person’s speech texture.
-
Multi-Head Conditional VAE (cVAE): A classic VAE learns a compressed latent space from data and can generate new samples. Here they make it conditional (cVAE) by concatenating the metadata (topic, age, turn number) with the latent vector. The “multi-head” means the decoder splits into two separate output heads: one reconstructs the original text (using a small LSTM), the other predicts a continuous MoCA score. This joint training forces the latent space to encode both identity and cognitive state.
-
MoCA Score (Montreal Cognitive Assessment): A 30-point test for mild cognitive impairment. It covers memory, attention, language, visuospatial ability. This paper uses MoCA as the ground-truth cognitive outcome. The regressor head learns to predict it from the latent vector, so the digital twin becomes a proxy for cognitive health.
Framework Shift
Before (mainstream approach):        After (this paper):
+------------------+                 +------------------------+
| Speech sample -> |                 | Conversation history ->|
| Feature extract  |                 | LLM + style embed ->   |
| (static)         |                 | generated utterance    |
| + classifier     |                 | +                      |
| (e.g., SVM)      |                 | cVAE encoder ->        |
| -> MCI detection |                 | latent vector          |
+------------------+                 | -> (a) reconstruction  |
                                     | -> (b) MoCA prediction|
                                     +------------------------+
One sentence: From static feature extraction + classification to a dynamic generative + predictive twin, the core shift is turning language from a passive biomarker into an active, personalized simulation platform.
Expert Assessment
Problem choice: Real gap. Cognitive health monitoring needs scalable, non-invasive tools, and language is the richest natural source. The idea of building a personal digital twin rather than a generic classifier is timely. However, the field already has MCI detection from speech; the novelty here is *generation of identity-consistent speech, which makes the twin interactive. Positioned well in the trajectory from detection to intervention.
Method maturity: Clever combination but no radical invention. GPT-2 conditioning and multi-task cVAE are established tools. The novelty is in the system integration and the specific task framing. Simpler approaches exist (e.g., fine-tune a small GPT with user data and attach a regression head), but the cVAE gives a principled latent space for uncertainty and inference. It’s appropriate, not overkill.
Experimental integrity: Baselines are fair — compare against GPT-2 zero-shot. They report reconstruction BLEU and MoCA prediction RMSE. The numbers show the twin beats raw GPT-2, but the absolute RMSE for MoCA (e.g., 2.5 points) is modest. No comparison to a simple fine-tuned GPT + regressor without cVAE, which could be stronger. Only one dataset (I-CONECT, ~200 subjects). No cross-dataset validation. Red flag: small sample, potential overfitting. The paper also lacks ablation on the stylometric cues.
Writing quality: Clear motivation and architecture description. The cVAE section is dense and skips some training details (e.g., how they handle variable-length utterances). The results section could be more detailed — no confidence intervals or statistical tests. Rewriting the method section with explicit equation flow and a complete training objective would elevate the paper.
Verdict: weak accept — Solid idea that extends digital twins into a new modality, but incremental execution and limited evidence prevent it from being transformative.
Takeaways
- Multi-task latent space as an assessment tool: The idea of training a VAE to simultaneously reconstruct and regress a health score can be transferred to any domain where you want a generative digital twin that also monitors a target variable (e.g., emotional state from text, gait quality from step data).
- Stylometric conditioning as a lightweight personalization trick: Instead of fine-tuning the entire LLM, append precomputed statistical features to input embeddings. This is cheap and generalizable — could be used for chatbot user adaptation in production.
- Reconstruction vs prediction trade-off measures fidelity: By tracking both losses, you get a built-in diagnostic: if reconstruction is good but prediction is bad, the latent space captures style but not health. This signals the need to add more task-relevant features. Practitioners can adopt this as a model debugging technique.
论文: 2606.27334 作者: Mohammad Mehdi Hosseini, Mohammad H. Mahoor, Hiroko H. Dodge 分类: cs.AI
缺口
现有数字孪生在认知健康领域主要依赖生理传感器(可穿戴设备、MRI)或结构化评估。 语言作为轻度认知障碍(MCI)的丰富生物标志物,却很少被用于构建个性化生成模型。 此前的工作要么从语音中提取静态特征(如句法复杂度)来检测MCI,要么使用通用大语言模型进行对话,但从未将两者结合来生成一个动态个体模型,该模型既能生成身份一致的话语,又能预测认知分数。 缺口在于:我们能否构建一个基于语言的数字孪生,既能保留个人的会话风格,又能作为连续认知监测器?
问题:缺乏非侵入性、个性化、基于语言的认知监测生成模型。
    v
假设:大语言模型 + 文体线索 + 元数据可以模拟个体言语。
    v
方法:条件GPT-2 + 多头条件变分自编码器(重建 + MoCA回归)。
    v
证据:在I-CONECT数据集上,重建误差和MoCA预测误差与真实数据相当,优于GPT-2基线。
    v
结论:基于语言的数字孪生可用于连续监测。
增量
一句话:此论文之前,没有系统能同时生成身份特定的话语并从这些话语中预测认知分数;此论文之后,存在一个生成器加评估器的组合。
核心机制
框架包含两大模块。 首先,一个个性化生成器:预训练LLM(GPT-2)被文体特征(如词长分布、词性n-gram)和上下文元数据(年龄、教育程度、话题、轮次)条件化——这些特征通过可学习的嵌入与LLM输入token拼接,迫使生成器产生匹配用户语言模式的话语。 其次,一个多头条件VAE(cVAE)在LLM隐藏状态之上添加变分自编码器。 一个解码头重建原始话语(标准VAE),另一个解码头从潜在向量回归MoCA评分。 训练联合优化重建似然和MoCA预测损失。
[ASCII方法内部图]

                +-----------------+
 用户历史+元数据|  文体与元数据    |
 +------------->|     嵌入器       |
                +--------+--------+
                         |
                    +----v----+
                    | GPT-2   |
                    | (冻结)  |----> 生成的话语
                    +----+----+
                         | (隐藏态)
                    +----v----+
                    | cVAE    |
                    | 编码器  |
                    +----+----+
                         |
              +----------+----------+
              |                     |
         +----v----+          +----v----+
         | 解码器  |          | 回归器  |
         | (重建)  |          | (MoCA) |
         +---------+          +---------+
              |                     |
         重建损失              MSE损失
核喻:想象一个个性化电台,只播你喜欢的音乐,还能告诉你现在的心情。
- GPT-2 是电台发射台,但播放的是通用内容。
- 文体和元数据嵌入是均衡器——调整语速、词汇选择,让它听起来像你。
- cVAE编码器是监听装置,捕捉发射台刚播的内容并压缩成指纹(潜在向量)。
- 两个解码头:一个是回放头,试着重播刚才的内容(训练系统保持指纹有意义);另一个是心情表,读取指纹并输出一个数字(MoCA分数)。 于是系统学会用你的风格广播,并通过听自己广播来估计认知状态。
关键概念
-
文体线索:个人语言的统计指纹——平均词长、功能词频率、标点习惯等。本文从每条话语提取20个特征(如名词比例、平均句长)。这些不是语义特征(说什么),而是**怎么说*。例如,MCI老年人常用短句和填充词“嗯”。将这些嵌入生成器迫使模型模仿人的言语质地。
-
多头条件变分自编码器(cVAE):经典VAE从数据中学习压缩潜在空间并可生成新样本。这里将其条件化(cVAE),把元数据(话题、年龄、轮次)与潜在向量拼接。“多头”指解码器分成两个独立输出头:一个用小型LSTM重建原始文本,另一个预测连续MoCA分数。联合训练迫使潜在空间既编码身份又编码认知状态。
-
MoCA评分(蒙特利尔认知评估):30分制轻度认知障碍测试,涵盖记忆、注意力、语言、视空间能力。本文以MoCA作为认知真实标签。回归头从潜在向量预测它,使数字孪生成为认知健康的代理。
框架转变
之前(主流方法):                之后(本文方法):
+------------------+             +------------------------+
| 语音样本 ->      |             | 对话历史 ->            |
| 特征提取(静态)  |             | LLM + 文体嵌入 ->      |
| + 分类器(如SVM)|             | 生成的话语             |
| -> MCI检测       |             | +                      |
+------------------+             | cVAE编码器 ->          |
                                  | 潜在向量               |
                                  | -> (a) 重建            |
                                  | -> (b) MoCA预测       |
                                  +------------------------+
一句话:从静态特征提取加分类,转到动态生成加预测的孪生,核心转变是把语言从被动生物标志物变成主动的、个性化的模拟平台。
专家评审
选题眼光:真缺口。认知健康监测需要可规模化的非侵入性工具,语言是最丰富的自然来源。构建个性化数字孪生而非通用分类器,思路及时。但该领域已有基于语音的MCI检测;这里的创新在于**生成*身份一致的话语,使孪生可交互。定位在从检测到干预的轨迹中,较好。
方法成熟度:巧妙组合,无根本性发明。GPT-2条件化和多任务cVAE都是成熟工具。新颖性在于系统集成和任务框架。更简单的方案(例如微调小型GPT并附加回归头)也行,但cVAE提供了原则性的潜在空间表示不确定性。方法合适,未过度设计。
实验诚意:基线公平——与GPT-2零样本对比。报告了重建BLEU和MoCA预测RMSE。数据显示孪生优于纯GPT-2,但MoCA的绝对RMSE(约2.5分)一般。未与不带cVAE的简单微调GPT+回归器对比,后者可能更强。仅使用一个数据集(I-CONECT,约200名受试者)。无跨数据集验证。值得警惕:样本小,可能过拟合。论文还缺少对文体线索的消融实验。
写作功力:动机和架构描述清晰。cVAE部分较密集,漏掉一些训练细节(如如何处理变长话语)。结果部分可以更详细——无置信区间或统计检验。重写方法部分,加入显式方程流和完整训练目标,可提升论文档次。
判决:弱接收——想法扎实,将数字孪生扩展到新模态,但增量有限,证据不足,不足以成为变革性工作。
要点总结
- 多任务潜在空间作为评估工具:训练VAE同时重建和回归健康指标的思路,可迁移到任何需要生成式数字孪生同时监控目标变量的领域(如从文本推断情绪状态、从步数推断步态质量)。
- 文体条件化作为轻量级个性化技巧:不必微调整个LLM,而是将预计算的统计特征附加到输入嵌入中。这成本低且通用——可用于生产环境中的聊天机器人用户适配。
- 重建与预测的权衡作为保真度指标:通过同时跟踪两个损失,获得内建诊断:如果重建好但预测差,说明潜在空间捕获了风格但未捕获健康,提示需要添加更多任务相关特征。实践者可将其作为模型调试技术。