Paper: 2603.00883 Authors: Michael Hardy, Yunsung Kim Categories: cs.LG, cs.AI, cs.CY, stat.AP
The Gap
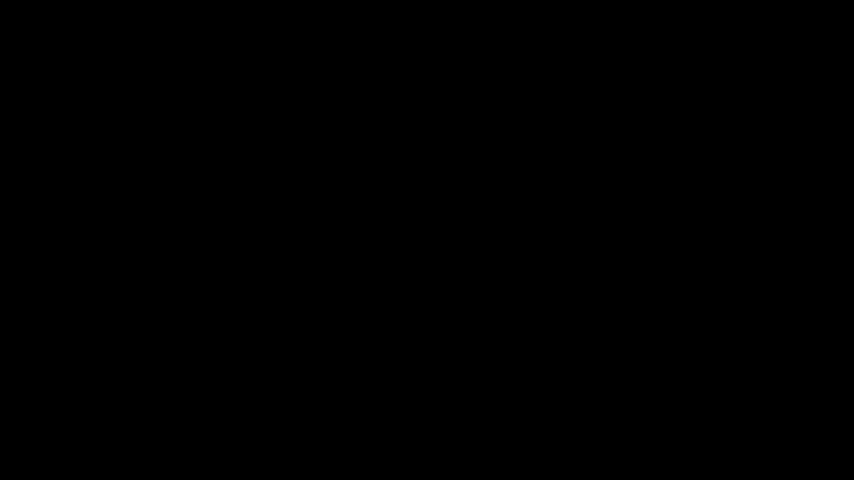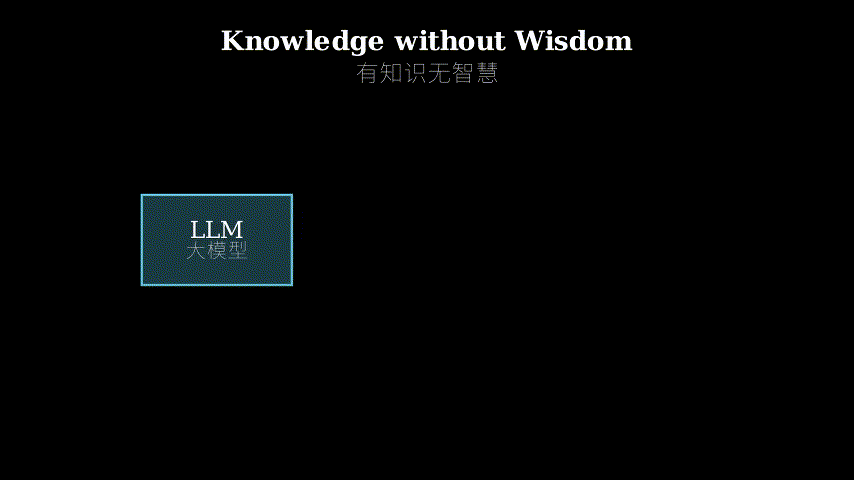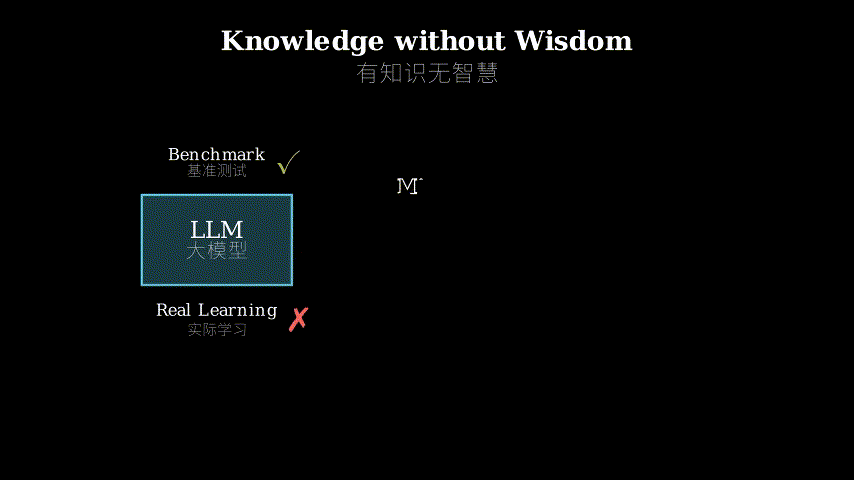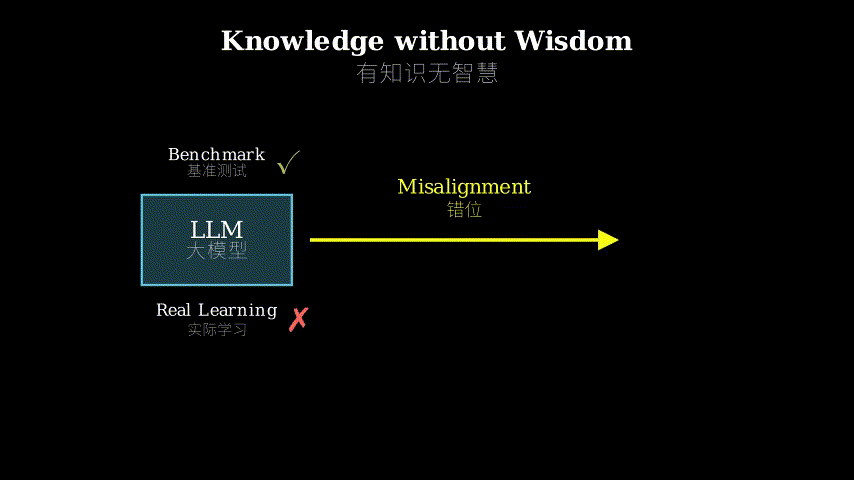
The AI community has been chasing benchmark scores like they’re the finish line. MMLU, HumanEval, GSM8K — models keep getting better at these standardized tests. The implicit assumption: if a model aces benchmarks, it’ll perform well on real-world tasks in that domain. But here’s the problem nobody was rigorously measuring: benchmark performance is a proxy metric, and we’ve been treating it like ground truth.
Prior work evaluated LLMs on educational tasks using either synthetic datasets or correlation with other AI benchmarks. What was missing? Direct measurement of alignment between model behavior and actual downstream impact — specifically, whether LLM judgments about teaching quality correlate with what expert educators value and, critically, whether they predict student learning outcomes. The field had validation theater but no validation substance.
The Increment
Before: We assumed models good at benchmarks would be good at real tasks. After: We have quantitative proof that benchmark excellence can be orthogonal or even negatively correlated with real-world impact.
The authors designed a measurement framework that treats alignment as a three-way relationship. Think of it like tuning a musical instrument: you need a reference pitch (expert human judgments on teaching quality), the instrument you’re tuning (LLM outputs), and the actual sound quality you care about (student learning outcomes). Most prior work only checked if the LLM matched the reference pitch. This paper checks if matching that pitch actually produces better music.
They evaluated leading foundation models on out-of-distribution educational tasks — rating teaching episodes, predicting learning gains. The core finding is structural: LLMs correlate more strongly with each other than with human experts, revealing a shared bias space inherited from pretraining. When you ensemble models (either by majority vote or weighted by benchmark performance), you’re not averaging out noise — you’re amplifying the shared misalignment. It’s like asking a committee of people who all learned from the same textbook: consensus doesn’t equal correctness when the textbook itself is biased.
The measurement apparatus itself is the contribution. They decompose misalignment error into model-specific and shared components, finding that ~50% of the error variance is common across all foundation models. This suggests the problem isn’t in fine-tuning or prompting strategies — it’s baked into the pretraining corpus and objectives.
Key Concepts
Out-of-Distribution (OOD) Tasks in Context
When we say “out-of-distribution,” we usually mean data the model hasn’t seen. But there’s a subtler meaning here: tasks where the objective function differs from pretraining. LLMs are trained to predict next tokens on internet text. That objective correlates with many useful capabilities, but it’s not the same as “judge teaching quality in ways that predict student learning.”
Concrete example: Imagine a teaching video where the instructor makes a common pedagogical error — say, introducing a complex concept without scaffolding. An LLM might rate this highly if the explanation is articulate and uses sophisticated vocabulary (features correlated with “good text” in pretraining data). But expert educators know this approach confuses students. The learning outcome data proves the experts right. The LLM’s notion of “quality” is misaligned not because it’s stupid, but because it’s optimizing a different objective.
Shared Bias Space
The paper measures that different foundation models make correlated errors. This isn’t random — it’s structural. All these models were pretrained on overlapping internet corpora with similar objectives (next-token prediction, sometimes with RLHF on similar feedback datasets).
Think of it like this: if you train ten different students using the same textbook that has a subtle error on page 47, all ten students will likely make the same mistake on problems related to that concept. The error isn’t in the students’ individual reasoning — it’s in the shared knowledge source. The authors quantify this: 50% of misalignment variance is shared. That’s huge. It means you can’t fix this by switching models or ensembling — you need to change the training diet.
Negative Alignment with Learning Outcomes
This is the most alarming finding. It’s not just that LLMs fail to predict learning outcomes — in some cases, their judgments are negatively correlated. When the model says “this is good teaching,” students actually learn less.
Why? The hypothesis: LLMs latch onto surface features that correlate with “impressive text” but anti-correlate with effective pedagogy. Verbose explanations, technical jargon, complex sentence structures — these might score high in the model’s latent representation of quality, but they’re pedagogical red flags. Expert teachers know that clarity, simplicity, and student-centered pacing matter more. The model has knowledge (it can generate articulate text about teaching) but lacks wisdom (understanding what actually helps students learn).
Expert Assessment
Problem significance: This is critical. LLMs are already being deployed in educational contexts — tutoring systems, teacher training feedback, curriculum design. If these systems are optimizing for metrics that anti-correlate with learning, we’re not just wasting resources, we’re actively harming students. The affected community is massive: every student and educator in systems adopting AI tools.
Method maturity: This is a measurement study, not a solution. The authors provide a diagnostic framework but don’t offer a fix. That’s appropriate for the scope, but it means this is early-stage science. The methods for measuring alignment are sound, but translating these insights into better training procedures is left as future work. One limitation they don’t emphasize enough: their educational tasks are specific (K-12 teaching episodes). Generalization to other domains is plausible but unproven.
Experimental rigor: The baselines are fair — they compare multiple leading foundation models and use real expert annotations plus learning outcome data. The datasets are small by ML standards (inherent to getting ground-truth learning data), which limits statistical power. A red flag: the paper doesn’t deeply explore whether the misalignment is task-specific or a general phenomenon. Are LLMs bad at all “impact prediction” tasks, or specifically educational ones? More domain diversity would strengthen the claims.
Verdict: Weak accept — important negative result with solid measurement methodology, but limited scope and no proposed solutions.
Takeaways
Proxy metrics can be worse than useless: If your proxy anti-correlates with your true objective, optimizing it actively harms performance. This applies beyond education — any domain where you’re using AI benchmarks as a stand-in for real-world impact should be measuring alignment, not assuming it.
Ensemble methods amplify shared biases: When models share a bias (from common pretraining), ensembling doesn’t help — it makes things worse. This is counterintuitive because ensembles usually improve robustness. The lesson: diversity in ensembles requires diversity in training, not just architecture.
Measure downstream impact, not intermediate proxies: The paper’s core methodological contribution is the three-way alignment check (model vs. experts vs. outcomes). This framework is portable. If you’re deploying AI in healthcare, don’t just check if it agrees with doctors — check if it predicts patient outcomes. If you’re using AI for hiring, don’t just validate against recruiter judgments — track actual job performance.
Pretraining creates a shared reality distortion field: 50% shared error variance means the problem is upstream. Fine-tuning and prompting are band-aids. If you want models aligned with domain-specific objectives that differ from “predict internet text,” you need domain-specific pretraining or fundamentally different training objectives.
论文: 2603.00883 作者: Michael Hardy, Yunsung Kim 分类: cs.LG, cs.AI, cs.CY, stat.AP
缺口
AI领域一直在追逐基准分数,仿佛那就是终点线。MMLU、HumanEval、GSM8K——模型在这些标准化测试上不断进步。隐含假设是:如果模型在基准测试中表现优异,它在该领域的实际任务中也会表现出色。但没人严格测量的问题是:基准性能只是代理指标,我们却把它当成了基本事实。
此前的工作用合成数据集或与其他AI基准的相关性来评估LLM在教育任务上的表现。缺失的是什么?直接测量模型行为与实际下游影响之间的对齐度——具体来说,就是LLM对教学质量的判断是否与专家教育者的价值观相关,更关键的是,它们能否预测学生的学习成果。这个领域有验证的表演,却没有验证的实质。
增量
之前: 我们假设在基准测试中表现好的模型在实际任务中也会表现好。之后: 我们有了定量证据,证明基准卓越性可能与现实世界影响正交,甚至负相关。
作者设计了一个测量框架,将对齐视为三方关系。想象调音乐器:你需要参考音高(专家对教学质量的人类判断)、你要调的乐器(LLM输出),以及你真正关心的音质(学生学习成果)。大多数先前工作只检查LLM是否匹配参考音高。本文检查匹配那个音高是否真的产生更好的音乐。
他们在分布外教育任务上评估了领先的基础模型——评价教学片段、预测学习增益。核心发现具有结构性:LLM之间的相关性强于它们与人类专家的相关性,揭示了从预训练继承的共享偏差空间。当你集成模型时(无论是多数投票还是按基准性能加权),你不是在平均噪声——你是在放大共享的错位。这就像询问一个都从同一本教科书学习的委员会:当教科书本身有偏差时,共识不等于正确。
测量装置本身就是贡献。他们将错位误差分解为模型特定和共享成分,发现约50%的误差方差在所有基础模型中是共同的。这表明问题不在微调或提示策略——它烙印在预训练语料库和目标中。
关键概念
语境中的分布外(OOD)任务
当我们说”分布外”时,通常指模型没见过的数据。但这里有更微妙的含义:目标函数与预训练不同的任务。LLM被训练来预测互联网文本的下一个token。这个目标与许多有用能力相关,但它不等同于”以预测学生学习的方式判断教学质量”。
具体例子:想象一个教学视频,教师犯了常见的教学错误——比如,在没有脚手架的情况下引入复杂概念。如果解释清晰且使用复杂词汇(与预训练数据中”好文本”相关的特征),LLM可能会给予高评价。但专家教育者知道这种方法会让学生困惑。学习成果数据证明专家是对的。LLM的”质量”概念错位不是因为它愚蠢,而是因为它在优化不同的目标。
共享偏差空间
论文测量了不同基础模型会犯相关错误。这不是随机的——是结构性的。所有这些模型都在重叠的互联网语料库上用相似目标(下一个token预测,有时在相似反馈数据集上进行RLHF)进行预训练。
这样想:如果你用同一本教科书训练十个不同的学生,而这本书第47页有个微妙错误,所有十个学生在与该概念相关的问题上可能都会犯同样的错误。错误不在学生的个体推理——在共享知识源。作者量化了这一点:50%的错位方差是共享的。这很重要。这意味着你不能通过切换模型或集成来解决这个问题——你需要改变训练饮食。
与学习成果的负对齐
这是最令人震惊的发现。不仅LLM无法预测学习成果——在某些情况下,它们的判断是负相关的。当模型说”这是好的教学”时,学生实际上学得更少。
为什么?假设:LLM抓住了与”令人印象深刻的文本”相关但与有效教学法反相关的表面特征。冗长的解释、技术术语、复杂的句子结构——这些在模型的质量潜在表示中可能得分很高,但它们是教学红旗。专家教师知道清晰、简单和以学生为中心的节奏更重要。模型有知识(它可以生成关于教学的清晰文本),但缺乏智慧(理解什么真正帮助学生学习)。
专家评审
问题重要性: 这至关重要。LLM已经在教育环境中部署——辅导系统、教师培训反馈、课程设计。如果这些系统正在优化与学习反相关的指标,我们不仅在浪费资源,还在积极伤害学生。受影响的群体是巨大的:采用AI工具的系统中的每个学生和教育者。
方法成熟度: 这是测量研究,不是解决方案。作者提供了诊断框架,但没有提供修复方法。这对范围来说是合适的,但这意味着这是早期科学。测量对齐的方法是可靠的,但将这些见解转化为更好的训练程序留作未来工作。他们没有充分强调的一个局限:他们的教育任务是特定的(K-12教学片段)。推广到其他领域是合理的但未经证实。
实验严谨性: 基线是公平的——他们比较了多个领先的基础模型,并使用真实的专家注释加上学习成果数据。按ML标准,数据集很小(获取真实学习数据固有的),这限制了统计能力。一个红旗:论文没有深入探讨错位是任务特定的还是普遍现象。LLM在所有”影响预测”任务上都很差,还是特别在教育任务上?更多的领域多样性会加强主张。
判决: 弱接收——重要的负面结果,测量方法可靠,但范围有限且没有提出解决方案。
要点总结
代理指标可能比无用更糟: 如果你的代理与真实目标反相关,优化它会主动损害性能。这适用于教育之外——任何使用AI基准作为现实世界影响替代的领域都应该测量对齐,而不是假设它。
集成方法放大共享偏差: 当模型共享偏差(来自共同预训练)时,集成没有帮助——它使事情变得更糟。这是反直觉的,因为集成通常提高鲁棒性。教训:集成中的多样性需要训练中的多样性,而不仅仅是架构。
测量下游影响,而非中间代理: 论文的核心方法论贡献是三方对齐检查(模型vs.专家vs.结果)。这个框架是可移植的。如果你在医疗保健中部署AI,不要只检查它是否与医生一致——检查它是否预测患者结果。如果你使用AI进行招聘,不要只针对招聘人员判断进行验证——跟踪实际工作表现。
预训练创造共享的现实扭曲场: 50%的共享误差方差意味着问题在上游。微调和提示是创可贴。如果你想要与”预测互联网文本”不同的特定领域目标对齐的模型,你需要特定领域的预训练或根本不同的训练目标。