Paper: 2604.09512 Authors: Luis Mickeler, Kai Lion, Alfonso Nardi, Jost Kellner, Pierre Didier, Bhavin J. Shastri, Niao He, Rachel Grange Categories: cs.LG, physics.optics
The Gap
Transformers dominate AI, but there’s an asymmetry: matrix multiplications get all the hardware love (GPUs, TPUs, custom accelerators), while nonlinear functions like Softmax are stuck in digital land. Softmax is less than 1% of operations but creates disproportionate latency bottlenecks because it requires sequential normalization across entire sequences. Prior approaches either accept this bottleneck or try approximate digital implementations (polynomial approximations, hardware-friendly variants) that trade accuracy for speed but still run on the same digital substrate.
The gap: no one’s seriously explored analog optical hardware for these specific nonlinearities in transformers, despite optics’ natural advantage in parallel, low-latency computation.
Problem: Softmax latency bottleneck in transformers
   |
   v
Assumption: Analog optics can implement nonlinear functions
            faster than digital circuits
   |
   v
Method: Use TFLN Mach-Zehnder modulators as
        analog Softmax/Sigmoid units
   |
   v
Evidence: Vision Transformers + LLMs maintain accuracy
          with 4-bit quantization at 10 GBaud
   |
   v
Conclusion: Optical nonlinear units viable for
            hybrid transformer accelerators
The Increment
One sentence: Before this paper, transformer acceleration meant faster matrix math on digital chips; after, it means offloading nonlinearities to optical analog hardware that computes through light modulation instead of transistor switching.
Core Mechanism
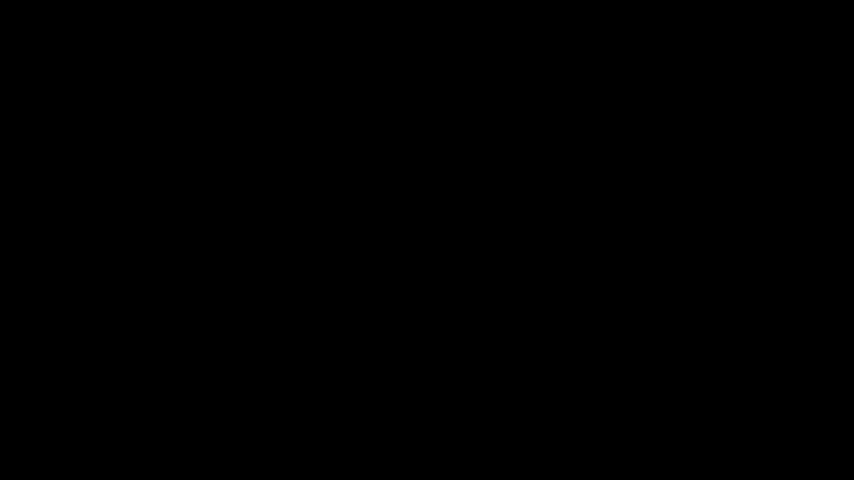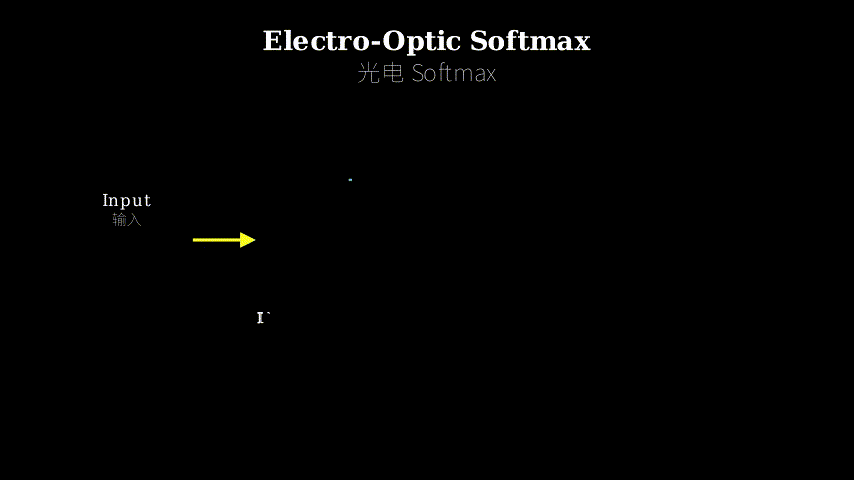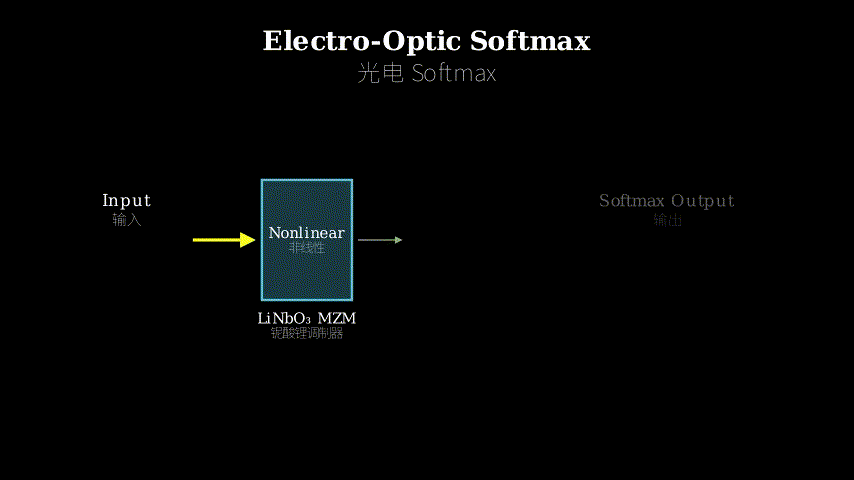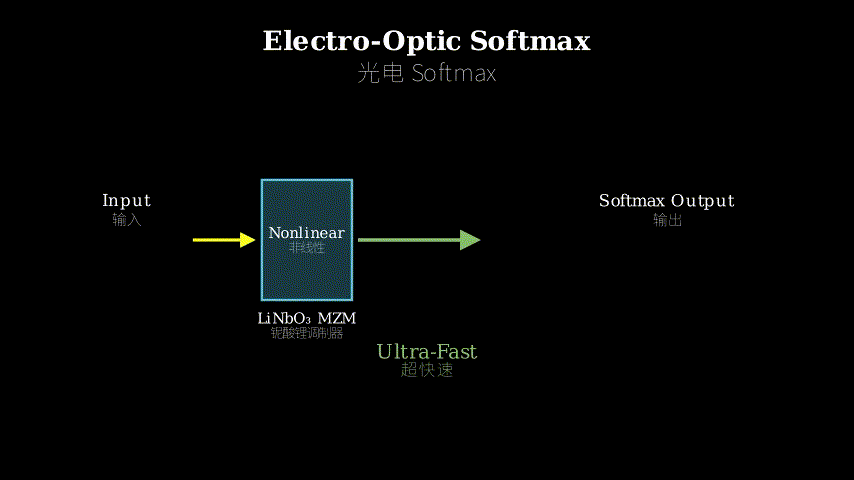
The system uses thin-film lithium niobate (TFLN) Mach-Zehnder modulators (MZMs) as the computational primitive. An MZM is an optical device where you split a light beam into two paths, apply voltage to one path (changing its refractive index via the electro-optic effect), then recombine the beams. The interference pattern depends on the voltage—this gives you a nonlinear voltage-to-light-intensity mapping.
For Softmax, the input vector gets encoded as voltages on multiple MZMs in parallel. Each MZM outputs light intensity proportional to exp(x_i). These optical signals feed into photodetectors, get normalized (the sum is computed optically or digitally), and you have your Softmax output. The key: all exponentials happen simultaneously in the optical domain at the speed of light, not sequentially in digital logic.
The system operates with 4-bit quantization on both inputs and outputs. They characterize noise at encoding speeds up to 10 GBaud (10 billion symbols per second) and test robustness across Vision Transformers (ViT) and large language models.
Digital Input (4-bit)
   |
   v
[Voltage Encoder] ---> Electrical signals
   |
   +---> [MZM 1] ---> Light intensity ~ exp(x_1)
   |
   +---> [MZM 2] ---> Light intensity ~ exp(x_2)
   |
   +---> [MZM N] ---> Light intensity ~ exp(x_N)
   |
   v
[Photodetectors] ---> Measure intensities
   |
   v
[Normalization] ---> Sum and divide
   |
   v
Digital Output (4-bit)
Think of it like a water park’s wave pool. In a digital system, you’d generate waves by having workers sequentially push floats up and down—slow, energy-intensive. The MZM approach is like dropping stones into the pool: each stone (voltage) creates ripples (light phase shifts) instantly and in parallel. When the ripples meet at the edge (photodetector), their combined height (interference pattern) gives you the answer. The wave pool naturally computes the superposition; you just read the result. The 4-bit quantization is like only caring whether the wave height is in one of 16 discrete buckets—coarse, but fast to measure and often good enough.
Key Concepts
-
Mach-Zehnder Modulator (MZM): Imagine a Y-shaped pipe where water flows in, splits into two paths, then rejoins. If you heat one path, water flows faster there, so when the streams merge, they’re out of sync—sometimes they add up (constructive), sometimes they cancel (destructive). An MZM does this with light: voltage changes the refractive index of one path, shifting the light’s phase. When the beams recombine, the interference pattern creates a nonlinear voltage-to-intensity mapping. This nonlinearity is what lets you compute functions like exp(x) without digital circuits.
-
Electro-optic effect in lithium niobate: Certain crystals change their refractive index when you apply an electric field—like how Jello jiggles when you poke it, but for light. Lithium niobate does this extremely well and fast (picosecond response). Apply voltage, light slows down or speeds up in that material, phase shifts, and you get modulation. Thin-film lithium niobate (TFLN) is a newer form that’s compact and integrates with silicon photonics, making it practical for chips.
-
4-bit quantization for analog-digital interface: Analog optical systems output continuous values, but digital systems need discrete numbers. 4-bit quantization means you round the optical output to one of 16 levels (2^4). It’s lossy—like describing a painting with only 16 colors—but transformers are surprisingly robust to this coarseness. The trade-off: you lose precision but gain speed (fewer bits to process) and simplicity (cheaper analog-to-digital converters). The paper shows models maintain competitive accuracy even with this aggressive quantization.
Framework Shift
Before (digital accelerators):        After (optical hybrid):

[Input] --> [GPU/TPU]                 [Input] --> [Digital MatMul]
              |                                      |
         Matrix Mult (fast)                    Matrix Mult (fast)
              |                                      |
         Softmax (slow)                             |
              |                                      v
         [Output]                            [Optical MZM Array]
                                                     |
                                              Softmax (fast)
                                                     |
                                                [Output]

Bottleneck: Sequential                Bottleneck: Analog-digital
            normalization                         conversion
From compute-everything-digitally to compute-linear-ops-digitally-and-nonlinear-ops-optically, the core shift is moving the latency bottleneck from the function itself to the interface between domains.
Expert Assessment
Problem choice: Real gap. Softmax latency is a known issue in transformer inference, especially for long sequences. The problem isn’t manufactured—it’s just that most researchers assume digital is the only game in town. This sits at the intersection of two mature fields (photonics and ML acceleration) that haven’t talked much.
Method maturity: Clever application of existing hardware (TFLN MZMs are well-characterized), not a fundamental photonics breakthrough. The insight is recognizing that MZM’s natural nonlinearity maps well to Softmax/Sigmoid. However, the paper doesn’t deeply explore why 4-bit quantization works so well—feels like they got lucky and didn’t dig into the theory. Also, they sidestep the elephant: how do you scale this to thousands of attention heads in modern LLMs? The prototype is small-scale.
Experimental integrity: Baselines are fair (standard ViT and LLM architectures). The noise characterization at 10 GBaud is solid. But the accuracy numbers are “competitive,” not “better”—they’re showing you don’t lose much, not that you gain something. The paper would be stronger if they showed wall-clock latency comparisons against actual GPU implementations, not just operation counts. Also, energy consumption is mentioned but not rigorously measured.
Writing quality: The photonics background section is too dense for ML readers, while the ML evaluation is too shallow for photonics experts—trying to serve two audiences and satisfying neither. The related work section undersells prior optical computing efforts. If they rewrote the results section to focus on the latency-accuracy trade-off curve (instead of just reporting final numbers), the contribution would be clearer.
Verdict: Weak accept — Interesting cross-disciplinary work that opens a door, but the experimental scope is limited and the practical path to deployment is murky. It’s a “proof of concept” paper that needs follow-up work to matter.
Takeaways
If you’re building ML accelerators, steal this framing: don’t assume all operations need the same substrate. Linear ops love digital parallelism; nonlinear ops might prefer analog physics. The 4-bit quantization result is the real gem—it suggests transformers are more robust to coarse nonlinearities than we thought, which could justify other approximate hardware (not just optical).
For photonics researchers: transformers are a killer app for analog optical computing because the attention mechanism naturally separates linear (matmul) and nonlinear (softmax) stages. You don’t need to replace the whole network, just the bottleneck.
The broader lesson: when a small operation causes disproportionate latency, look for a different computational medium that makes that operation cheap, even if it means hybrid systems. The interface cost (analog-digital conversion) is often worth it.
论文: 2604.09512 作者: Luis Mickeler, Kai Lion, Alfonso Nardi, Jost Kellner, Pierre Didier, Bhavin J. Shastri, Niao He, Rachel Grange 分类: cs.LG, physics.optics
缺口
Transformer 统治了 AI 领域,但存在一个不对称现象:矩阵乘法得到了所有硬件的宠爱(GPU、TPU、定制加速器),而 Softmax 这样的非线性函数却困在数字电路里。
Softmax 的运算量不到总量的 1%,但造成了不成比例的延迟瓶颈,因为它需要对整个序列进行顺序归一化。
此前的方法要么接受这个瓶颈,要么尝试近似的数字实现(多项式近似、硬件友好变体),用精度换速度,但仍然跑在同样的数字基底上。
缺口在于:尽管光学在并行、低延迟计算上有天然优势,却没人认真探索过用模拟光学硬件来实现 Transformer 中的这些特定非线性函数。
问题:Transformer 中的 Softmax 延迟瓶颈
   |
   v
假设:模拟光学可以比数字电路更快地实现非线性函数
   |
   v
方法:用 TFLN 马赫-曾德尔调制器作为
      模拟 Softmax/Sigmoid 单元
   |
   v
证据:视觉 Transformer + 大语言模型在
      10 GBaud 和 4 比特量化下保持准确率
   |
   v
结论:光学非线性单元可用于
      混合 Transformer 加速器
增量
一句话:这篇论文之前,Transformer 加速意味着在数字芯片上更快地做矩阵运算;之后,它意味着把非线性运算卸载到光学模拟硬件上,通过光调制而非晶体管开关来计算。
核心机制
系统使用薄膜铌酸锂(TFLN)马赫-曾德尔调制器(MZM)作为计算原语。
MZM 是一种光学器件,把光束分成两路,对其中一路施加电压(通过电光效应改变折射率),然后重新合并光束。
干涉图样取决于电压——这给你一个非线性的电压到光强映射。
对于 Softmax,输入向量被编码为多个 MZM 上的并行电压。
每个 MZM 输出与 exp(x_i) 成正比的光强。
这些光信号进入光电探测器,经过归一化(总和可以光学或数字计算),你就得到了 Softmax 输出。
关键在于:所有指数运算在光域中以光速同时发生,而非在数字逻辑中顺序执行。
系统在输入和输出上都使用 4 比特量化。
他们在高达 10 GBaud(每秒 100 亿符号)的编码速度下表征噪声,并在视觉 Transformer(ViT)和大语言模型上测试鲁棒性。
数字输入(4 比特)
   |
   v
[电压编码器] ---> 电信号
   |
   +---> [MZM 1] ---> 光强 ~ exp(x_1)
   |
   +---> [MZM 2] ---> 光强 ~ exp(x_2)
   |
   +---> [MZM N] ---> 光强 ~ exp(x_N)
   |
   v
[光电探测器] ---> 测量光强
   |
   v
[归一化] ---> 求和并除
   |
   v
数字输出(4 比特)
把它想象成水上乐园的造浪池。
在数字系统中,你得让工人顺序推动浮板上下运动来造浪——慢,耗能。
MZM 方法就像往池子里扔石头:每块石头(电压)瞬间并行地产生涟漪(光相移)。
当涟漪在边缘(光电探测器)相遇时,它们的叠加高度(干涉图样)给你答案。
造浪池自然地计算叠加;你只需读取结果。
4 比特量化就像只关心波高是否在 16 个离散桶之一——粗糙,但测量快,通常够用。
关键概念
- 马赫-曾德尔调制器(MZM):想象一个 Y 形管道,水流进来,分成两路,然后重新汇合。
如果你加热其中一路,那里的水流更快,所以当水流合并时,它们不同步——有时叠加(相长),有时抵消(相消)。
MZM 对光做同样的事:电压改变一条路径的折射率,使光的相位偏移。
当光束重新合并时,干涉图样创造出非线性的电压到光强映射。
这种非线性让你无需数字电路就能计算 exp(x) 这样的函数。
- 铌酸锂中的电光效应:某些晶体在施加电场时会改变折射率——就像你戳果冻时它会晃动,但这是对光而言。
铌酸锂在这方面表现极好且快速(皮秒级响应)。
施加电压,光在该材料中减速或加速,相位偏移,你就得到调制。
薄膜铌酸锂(TFLN)是一种更新的形式,紧凑且能与硅光子学集成,使其适用于芯片。
- 模拟-数字接口的 4 比特量化:模拟光学系统输出连续值,但数字系统需要离散数字。
4 比特量化意味着你把光学输出四舍五入到 16 个级别之一(2^4)。
这是有损的——就像用 16 种颜色描述一幅画——但 Transformer 对这种粗糙度出奇地鲁棒。
权衡:你失去精度但获得速度(处理的比特更少)和简单性(更便宜的模数转换器)。
论文显示即使在这种激进量化下,模型仍保持竞争力准确率。
框架转变
之前(数字加速器):              之后(光学混合):

[输入] --> [GPU/TPU]              [输入] --> [数字矩阵乘]
              |                                |
         矩阵乘(快)                      矩阵乘(快)
              |                                |
         Softmax(慢)                         |
              |                                v
         [输出]                         [光学 MZM 阵列]
                                               |
                                          Softmax(快)
                                               |
                                           [输出]

瓶颈:顺序归一化                   瓶颈:模数转换
从全数字计算到线性运算数字化、非线性运算光学化,核心转变是把延迟瓶颈从函数本身移到了域之间的接口。
专家评审
选题眼光:真实缺口。
Softmax 延迟是 Transformer 推理中的已知问题,尤其对长序列。
这个问题不是人造的——只是大多数研究者假设数字是唯一选择。
这处于两个成熟领域(光子学和机器学习加速)的交叉点,它们此前交流不多。
方法成熟度:巧妙应用现有硬件(TFLN MZM 已被充分表征),不是光子学的根本突破。
洞见在于认识到 MZM 的天然非线性很好地映射到 Softmax/Sigmoid。
然而,论文没有深入探索为什么 4 比特量化效果这么好——感觉他们运气好但没挖掘理论。
另外,他们回避了大象:如何扩展到现代大语言模型中的数千个注意力头?原型是小规模的。
实验诚意:基线公平(标准 ViT 和 LLM 架构)。
10 GBaud 的噪声表征扎实。
但准确率数字是”有竞争力”,不是”更好”——他们展示的是你不会损失太多,而非你获得了什么。
如果他们展示与实际 GPU 实现的墙钟延迟比较,而非仅运算次数,论文会更强。
另外,能耗被提及但未严格测量。
写作功力:光子学背景部分对机器学习读者太密集,而机器学习评估对光子学专家太浅——试图服务两个受众却都不满意。
相关工作部分低估了此前的光学计算努力。
如果他们重写结果部分,聚焦于延迟-准确率权衡曲线(而非仅报告最终数字),贡献会更清晰。
判决:弱接收 — 有趣的跨学科工作,打开了一扇门,但实验范围有限,实际部署路径模糊。
这是一篇需要后续工作才能产生影响的”概念验证”论文。
要点总结
如果你在构建机器学习加速器,偷走这个框架:不要假设所有运算都需要同样的基底。
线性运算喜欢数字并行;非线性运算可能更喜欢模拟物理。
4 比特量化结果是真正的宝石——它表明 Transformer 对粗糙非线性的鲁棒性超出我们想象,这可以为其他近似硬件(不仅是光学)提供理由。
对光子学研究者:Transformer 是模拟光学计算的杀手级应用,因为注意力机制自然地分离了线性(矩阵乘)和非线性(Softmax)阶段。
你不需要替换整个网络,只需替换瓶颈。
更广泛的教训:当一个小运算造成不成比例的延迟时,寻找一种让该运算变便宜的不同计算介质,即使这意味着混合系统。
接口成本(模数转换)通常是值得的。