Paper: 2605.22820 Authors: Carlos Heredia, Daniel Roncel Categories: cs.LG
The Gap
Retail demand modeling faces a fundamental tension: we want to predict sales (demand-first) but also need price elasticities for decision-making. Traditional econometric models estimate elasticities directly but struggle with high-dimensional product spaces and context dependence. Recent neural approaches predict demand well but derive elasticities as afterthoughts—taking numerical derivatives of black-box networks yields noisy, economically implausible estimates, especially for cross-price effects where data is sparse.
The core problem: elasticity is a derivative, but neural networks aren’t designed to have well-behaved derivative structure. You can differentiate a neural net, but nothing guarantees the resulting elasticities will be smooth, symmetric where theory demands, or stable across similar contexts.
Problem: Need both accurate demand forecasts AND stable elasticities
   |
   v
Prior approaches split into two camps:
   |
   +---> Econometric models: Theory-driven elasticities
   |        |
   |        +---> Limitation: Poor fit in high dimensions
   |
   +---> Neural demand models: Flexible predictions
            |
            +---> Limitation: Noisy elasticity derivatives
   |
   v
This paper's insight: Learn demand as gradient of a potential
   |
   v
Method: Neural network outputs potential function Φ(p, context)
        Demand = ∇_p Φ  (gradient w.r.t. log-prices)
   |
   v
Evidence: Dominick's beer dataset (multi-product retail)
   |
   +---> Better out-of-sample demand prediction
   +---> More stable cross-price elasticities
   +---> Economically plausible substitution patterns
   |
   v
Conclusion: Integrable structure improves both prediction and interpretation
The Increment
One sentence: Before this paper, neural demand models treated elasticities as numerical derivatives of predictions; after, elasticities are exact derivatives of a learned potential function, making them smooth and economically interpretable by construction.
Core Mechanism
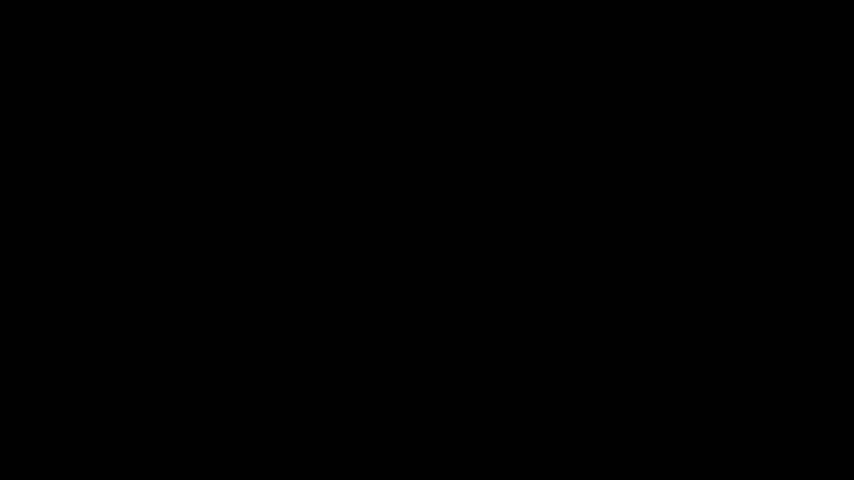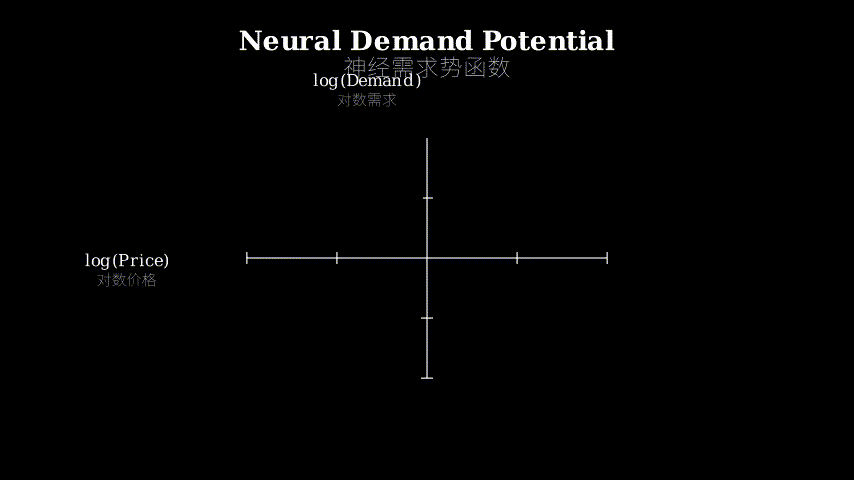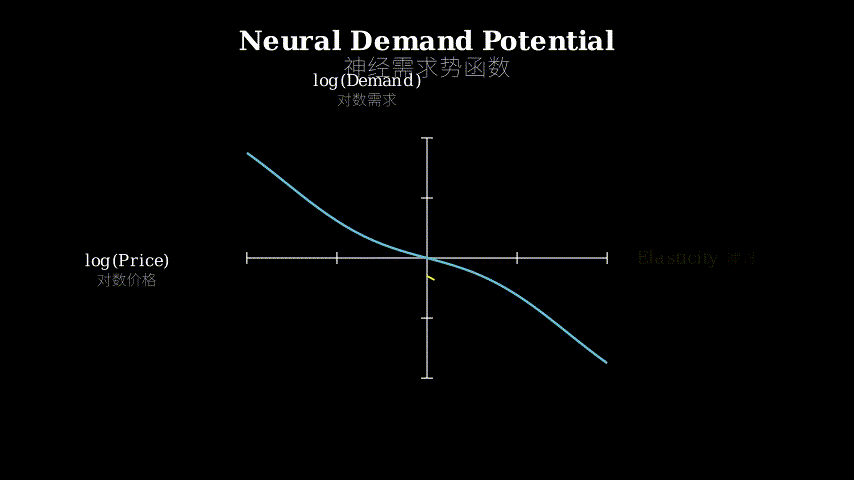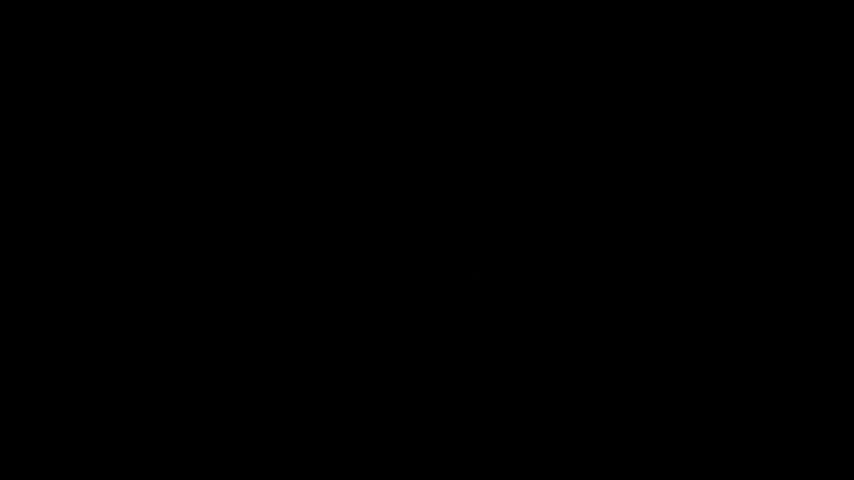
The ICDN architecture inverts the typical neural demand pipeline. Instead of learning a function that maps (prices, context) → demand, it learns a scalar potential function Φ(log-prices, context). Demand is then defined as the gradient of this potential with respect to log-prices. This seemingly small change has profound implications: gradients of smooth functions are automatically smooth, and the potential structure enforces integrability constraints that align with economic theory.
The network takes log-prices and contextual features (store, time, promotions) as input, processes them through standard neural layers, and outputs a single scalar—the potential. During training, the model computes ∇Φ to get predicted log-demand and compares it to observed log-demand. Crucially, elasticities are never explicitly supervised; they emerge as second derivatives ∇²Φ, inheriting smoothness from the potential’s learned structure.
The architecture uses automatic differentiation to compute these derivatives efficiently. At inference time, you get both demand predictions (first derivatives) and elasticity estimates (second derivatives) from a single forward pass plus gradient computation. The potential acts as a regularizer: it can’t produce arbitrary elasticity patterns because all elasticities must be consistent with some underlying scalar field.
Input: log-prices p, context c
   |
   v
[Neural Network Φ_θ]  <--- Learns scalar potential
   |
   v
Potential: Φ(p, c) ∈ R
   |
   +---> ∂Φ/∂p_i = q_i  (demand for product i)
   |
   +---> ∂²Φ/∂p_i∂p_j = ε_ij  (elasticity i w.r.t. price j)
   |
   v
Loss: ||q_predicted - q_observed||²
      (only supervise demand, elasticities come free)
Think of it like a topographic map. Traditional neural demand models try to learn the altitude at every point directly—they memorize elevations. This approach learns the underlying terrain as a smooth surface (the potential). Once you have the terrain, slopes (demand) and curvature (elasticities) follow automatically and must be consistent with each other. You can’t have a slope pointing north at one spot and south at a nearby spot without the terrain being curved in a specific way. The potential enforces this geometric consistency.
When you ask “how does demand for beer A change when beer B’s price increases?”, you’re asking about terrain curvature. The potential guarantees that if you walk from point (p_A, p_B) to (p_A, p_B + δ), the change in slope you experience is smooth and consistent with the overall landscape. Traditional models learn slopes independently at each point, so nearby slopes can contradict each other—you get elasticity estimates that flip sign or explode in magnitude for no economic reason.
Key Concepts
-
Integrability: In economics, demand functions should ideally come from utility maximization, which means they’re gradients of some underlying preference structure. Mathematically, this means the demand system is “integrable”—there exists a potential function whose gradient gives you demand. Most flexible models (including neural nets) don’t guarantee this. ICDN enforces it by construction: since demand is literally defined as ∇Φ, it’s integrable by definition. This isn’t just mathematical elegance; it rules out economically nonsensical patterns like circular substitution chains (A substitutes for B, B for C, C for A) that violate revealed preference.
-
Log-log specification: The model works in log-space: log-demand as a function of log-prices. This is standard in demand modeling because elasticities become simple derivatives (∂log q / ∂log p = elasticity), and it naturally handles the multiplicative structure of demand (prices and quantities span orders of magnitude). The log-log form also makes the potential interpretation cleaner: Φ becomes something like a “log-utility” function, and its gradients give percentage changes rather than absolute changes.
-
Context conditioning: The potential Φ isn’t just a function of prices—it’s conditioned on context (store characteristics, time, promotions). This means the entire demand surface can shift and deform based on context. A promotion doesn’t just shift demand for one product; it reshapes the entire elasticity landscape. The neural network learns how context modulates the potential’s shape, allowing elasticities to vary in economically meaningful ways (e.g., substitution patterns differ between discount and premium stores).
Framework Shift
Before (directed demand model):        After (potential-based model):

  [Prices, Context]                      [Prices, Context]
         |                                       |
         v                                       v
  +-------------+                         +-------------+
  | Neural Net  |                         | Neural Net  |
  +-------------+                         +-------------+
         |                                       |
         v                                       v
    [Demand q]                            [Potential Φ]
         |                                       |
         v                                       +---> ∇Φ = Demand q
  Elasticity ε ≈ Δq/Δp                          |
  (numerical derivative,                        +---> ∇²Φ = Elasticity ε
   noisy, inconsistent)                         (exact derivative,
                                                  smooth, consistent)
One sentence: From learning demand directly and approximating elasticities numerically, to learning a potential function where demand and elasticities are exact, consistent derivatives.
Expert Assessment
Problem choice: This is a real gap at the intersection of machine learning and econometrics. Retail pricing decisions require elasticity estimates, and existing neural approaches genuinely struggle with cross-price effects. The problem sits in a sweet spot: economically important, technically tractable, and underexplored. Not groundbreaking in scope, but honest and well-motivated.
Method maturity: The core idea—parameterizing demand via a potential—is elegant and draws on established theory (integrability from microeconomics, energy-based models from ML). The execution is straightforward: standard neural architecture with automatic differentiation. No architectural tricks or hyperparameter magic. The simplicity is a strength; this could have been done five years ago but wasn’t. That said, the paper doesn’t explore architectural choices deeply (network depth, activation functions, regularization schemes). It’s a proof of concept, not an exhaustive study.
Experimental integrity: The Dominick’s beer dataset is a reasonable testbed—real retail data with multiple products and price variation. The baseline (directed log-log model) is fair but minimal; comparisons to econometric benchmarks (AIDS, Rotterdam) or other neural approaches would strengthen claims. The elasticity stability results are compelling but qualitative (visual inspection of elasticity matrices). Quantitative metrics for elasticity plausibility (symmetry violations, sign consistency) would be more convincing. The out-of-sample improvement is modest, suggesting the main value is interpretability, not raw prediction.
Writing quality: The paper is clear and well-structured, but the related work section undersells connections to energy-based models and implicit differentiation in ML. The experimental section could use more ablations: how sensitive is performance to potential architecture? Do different activation functions affect elasticity smoothness? The discussion of economic plausibility is hand-wavy—specific examples of implausible elasticities from the baseline vs. plausible ones from ICDN would be more persuasive than general claims.
Verdict: weak accept — Solid idea with clear motivation and reasonable evidence, but experimental scope is narrow and the contribution is incremental rather than transformative.
Takeaways
For ML practitioners: The potential function trick generalizes beyond demand modeling. Anytime you need to predict a quantity and its derivatives (e.g., force fields in physics, gradients in optimization landscapes), learning the potential instead of the quantity directly can improve derivative quality. The key insight: derivatives of smooth functions are smoother than finite differences of noisy predictions.
For economists/pricing analysts: This shows neural networks can respect economic structure without sacrificing flexibility. If you’re building demand models for pricing or assortment optimization, the potential formulation gives you elasticities you can actually trust for downstream decisions. The context-conditioning is particularly useful for heterogeneous markets.
For researchers: The paper demonstrates that imposing structure (integrability) can improve both prediction and interpretation. This is a template for “theory-informed neural models”—use domain knowledge to constrain architecture, not just loss functions. The approach is underexplored in other economic domains (production functions, cost curves, auction bidding).
论文: 2605.22820 作者: Carlos Heredia, Daniel Roncel 分类: cs.LG
缺口
零售需求建模面临一个根本性张力:我们想预测销量(需求优先),但也需要价格弹性来做决策。
传统计量经济学模型直接估计弹性,但在高维产品空间和情境依赖下表现不佳。
近期的神经网络方法能很好地预测需求,但把弹性当作事后补充——对黑盒网络做数值求导会产生噪声大、经济上不合理的估计,尤其是数据稀疏的交叉价格效应。
核心问题:弹性是导数,但神经网络的设计初衷不是为了有良好的导数结构。
你可以对神经网络求导,但没有任何保证结果弹性会平滑、在理论要求的地方对称、或在相似情境下稳定。
问题:既需要准确的需求预测,又需要稳定的弹性
   |
   v
现有方法分为两派:
   |
   +---> 计量经济学模型:理论驱动的弹性
   |        |
   |        +---> 局限:高维下拟合差
   |
   +---> 神经需求模型:灵活的预测
            |
            +---> 局限:弹性导数噪声大
   |
   v
本文洞察:把需求学成势函数的梯度
   |
   v
方法:神经网络输出势函数 Φ(p, context)
      需求 = ∇_p Φ(对对数价格求梯度)
   |
   v
证据:Dominick's 啤酒数据集(多产品零售)
   |
   +---> 样本外需求预测更好
   +---> 交叉价格弹性更稳定
   +---> 替代模式经济上合理
   |
   v
结论:可积结构同时改善预测和解释性
增量
一句话:这篇论文之前,神经需求模型把弹性当作预测的数值导数;之后,弹性是学到的势函数的精确导数,构造上就保证了平滑性和经济可解释性。
核心机制
ICDN 架构反转了典型的神经需求流程。
它不学习一个从(价格,情境)→ 需求的函数,而是学习一个标量势函数 Φ(对数价格,情境)。
需求被定义为这个势函数对对数价格的梯度。
这个看似微小的改变有深远影响:平滑函数的梯度自动平滑,势函数结构强制执行与经济理论一致的可积性约束。
网络接收对数价格和情境特征(商店、时间、促销)作为输入,通过标准神经层处理,输出一个标量——势函数。
训练时,模型计算 ∇Φ 得到预测的对数需求,与观测到的对数需求比较。
关键是,弹性从未被显式监督;它们作为二阶导数 ∇²Φ 自然涌现,从势函数的学习结构继承平滑性。
架构使用自动微分高效计算这些导数。
推理时,一次前向传播加梯度计算就能同时得到需求预测(一阶导数)和弹性估计(二阶导数)。
势函数充当正则化器:它不能产生任意的弹性模式,因为所有弹性必须与某个底层标量场一致。
输入:对数价格 p,情境 c
   |
   v
[神经网络 Φ_θ]  <--- 学习标量势函数
   |
   v
势函数:Φ(p, c) ∈ R
   |
   +---> ∂Φ/∂p_i = q_i(产品 i 的需求)
   |
   +---> ∂²Φ/∂p_i∂p_j = ε_ij(弹性 i 对价格 j)
   |
   v
损失:||q_预测 - q_观测||²
     (只监督需求,弹性免费获得)
把它想象成地形图。
传统神经需求模型试图直接学习每个点的海拔——它们记忆海拔高度。
这个方法把底层地形学成一个平滑曲面(势函数)。
一旦有了地形,坡度(需求)和曲率(弹性)自动跟随,且必须相互一致。
你不能在某处有一个朝北的坡度,在附近又有一个朝南的坡度,除非地形以特定方式弯曲。
势函数强制执行这种几何一致性。
当你问”啤酒 A 的需求如何随啤酒 B 的价格上涨而变化?“,你在问地形曲率。
势函数保证当你从点 (p_A, p_B) 走到 (p_A, p_B + δ) 时,你经历的坡度变化是平滑的,与整体地貌一致。
传统模型在每个点独立学习坡度,所以附近的坡度可能相互矛盾——你得到的弹性估计会无缘无故地翻转符号或数量级爆炸。
关键概念
- 可积性:在经济学中,需求函数理想情况下应该来自效用最大化,这意味着它们是某个底层偏好结构的梯度。
数学上,这意味着需求系统是”可积的”——存在一个势函数,其梯度给出需求。
大多数灵活模型(包括神经网络)不保证这一点。
ICDN 通过构造强制执行:因为需求字面上定义为 ∇Φ,它在定义上就是可积的。
这不仅仅是数学优雅;它排除了经济上荒谬的模式,比如循环替代链(A 替代 B,B 替代 C,C 替代 A),这违反了显示偏好。
- 对数-对数规范:模型在对数空间工作:对数需求作为对数价格的函数。
这在需求建模中是标准做法,因为弹性变成简单的导数(∂log q / ∂log p = 弹性),它自然处理需求的乘法结构(价格和数量跨越数量级)。
对数-对数形式也让势函数解释更清晰:Φ 变成类似”对数效用”函数的东西,其梯度给出百分比变化而非绝对变化。
- 情境调节:势函数 Φ 不只是价格的函数——它以情境(商店特征、时间、促销)为条件。
这意味着整个需求曲面可以根据情境移动和变形。
促销不只是移动一个产品的需求;它重塑整个弹性景观。
神经网络学习情境如何调制势函数的形状,允许弹性以经济上有意义的方式变化(例如,折扣店和高端店之间的替代模式不同)。
框架转变
之前(有向需求模型):              之后(基于势函数的模型):

  [价格,情境]                        [价格,情境]
       |                                     |
       v                                     v
  +----------+                          +----------+
  | 神经网络 |                          | 神经网络 |
  +----------+                          +----------+
       |                                     |
       v                                     v
   [需求 q]                             [势函数 Φ]
       |                                     |
       v                                     +---> ∇Φ = 需求 q
弹性 ε ≈ Δq/Δp                               |
(数值导数,                                 +---> ∇²Φ = 弹性 ε
 噪声大,不一致)                            (精确导数,
                                              平滑,一致)
一句话:从直接学习需求并数值近似弹性,到学习一个势函数,其中需求和弹性是精确、一致的导数。
专家评审
选题眼光:这是机器学习和计量经济学交叉处的真实缺口。
零售定价决策需要弹性估计,现有神经方法在交叉价格效应上确实挣扎。
问题处于甜蜜点:经济上重要、技术上可行、探索不足。
范围上不算突破性,但诚实且动机充分。
方法成熟度:核心想法——通过势函数参数化需求——优雅且借鉴了成熟理论(微观经济学的可积性、机器学习的基于能量的模型)。
执行直截了当:标准神经架构加自动微分。
没有架构技巧或超参数魔法。
简洁是优势;这本可以五年前就做,但没人做。
话说回来,论文没有深入探索架构选择(网络深度、激活函数、正则化方案)。
这是概念验证,不是详尽研究。
实验诚意:Dominick’s 啤酒数据集是合理的测试平台——真实零售数据,多产品和价格变化。
基线(有向对数-对数模型)公平但最小;与计量经济学基准(AIDS、Rotterdam)或其他神经方法的比较会加强主张。
弹性稳定性结果令人信服但定性(弹性矩阵的视觉检查)。
弹性合理性的定量指标(对称性违反、符号一致性)会更有说服力。
样本外改进适度,表明主要价值是可解释性,而非原始预测。
写作功力:论文清晰且结构良好,但相关工作部分低估了与基于能量的模型和机器学习中隐式微分的联系。
实验部分可以有更多消融:性能对势函数架构有多敏感?不同激活函数影响弹性平滑性吗?经济合理性的讨论含糊——基线的不合理弹性与 ICDN 的合理弹性的具体例子会比一般性主张更有说服力。
判决:弱接收 — 扎实的想法,动机清晰,证据合理,但实验范围狭窄,贡献是渐进式而非变革性的。
要点总结
对机器学习从业者:势函数技巧超越需求建模。
任何时候你需要预测一个量及其导数(例如,物理中的力场、优化景观中的梯度),学习势函数而非直接学习量可以改善导数质量。
关键洞察:平滑函数的导数比噪声预测的有限差分更平滑。
对经济学家/定价分析师:这表明神经网络可以在不牺牲灵活性的情况下尊重经济结构。
如果你在为定价或品类优化构建需求模型,势函数形式给你可以真正信任的弹性用于下游决策。
情境调节对异质市场特别有用。
对研究者:论文展示了施加结构(可积性)可以同时改善预测和解释。
这是”理论知情神经模型”的模板——用领域知识约束架构,而非仅约束损失函数。
这种方法在其他经济领域(生产函数、成本曲线、拍卖出价)探索不足。