Paper: 2606.13668 Authors: Dimitri Kachler, Damien Sileo, Pascal Denis Categories: cs.CL
The Gap
Existing data attribution methods — especially influence functions — can tell you which training samples most affect a given model output. But they scale poorly: computing the influence of each sample requires an expensive Hessian inverse (or approximation) and storing per-sample gradients for all training data. This makes them impractical for large LLMs with millions of examples. Prior accelerations (e.g., EK-FAC, LiSSA, DataInf) still require scanning the entire training set at query time, or store large auxiliary matrices. The gap is inference speed and storage compactness: no existing method lets you get an influence score for a new (train, test) pair with a single forward pass of a small model.
Problem: Fast, compact data attribution for LLM training data
    |
    v
Existing approaches: Influence functions
    |
    v
Limitation: Slow per-query (scan all examples) + large storage (gradients)
    |
    v
Assumption: Influence ranking can be distilled into a light encoder
    |
    v
Method: Train encoder to predict relative influence rank from (train_sample, test_query)
    |
    v
Evidence: 100x speedup, <5% loss in top-K accuracy vs. expensive decoder
    |
    v
Conclusion: Practical, scalable attribution for LLM dataset filtering
The Increment
One sentence: Before this paper, influence-based attribution required scanning the entire training set for each test query (or storing gradients); after this paper, a small encoder can produce the same ranking with a single forward pass, no per-sample storage.
Core Mechanism
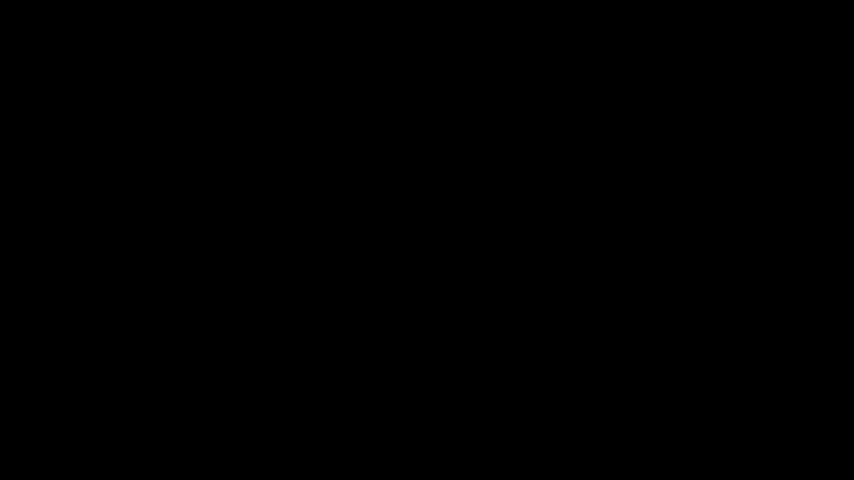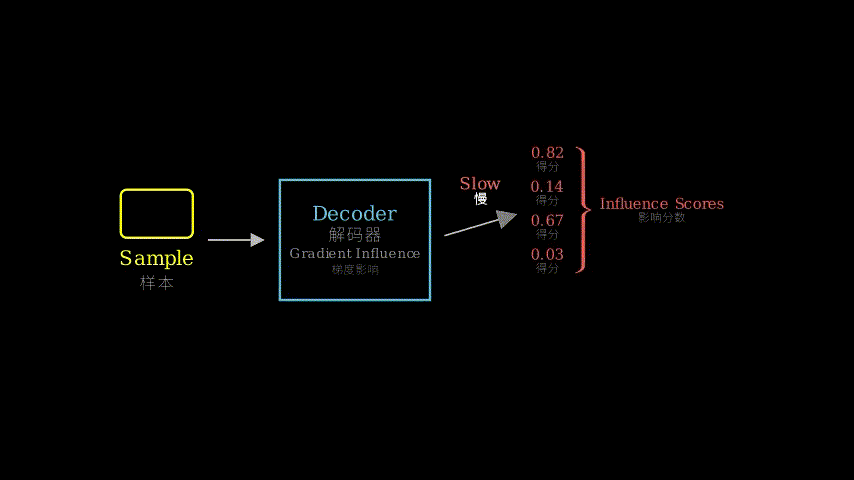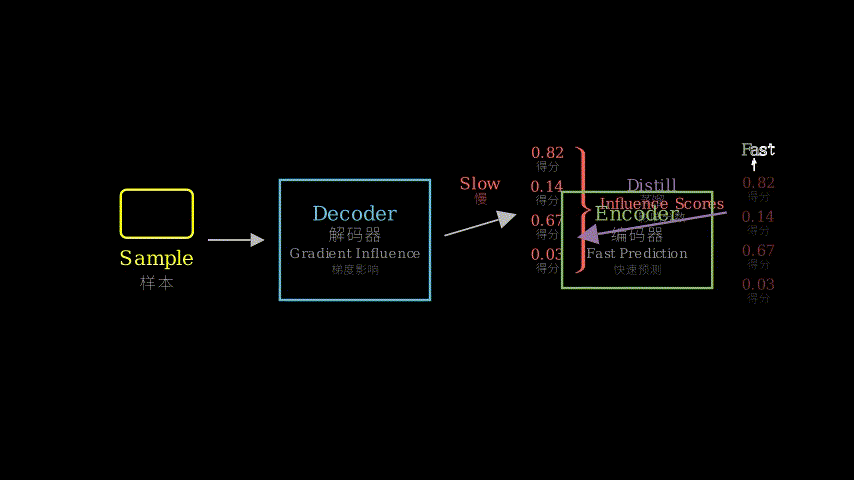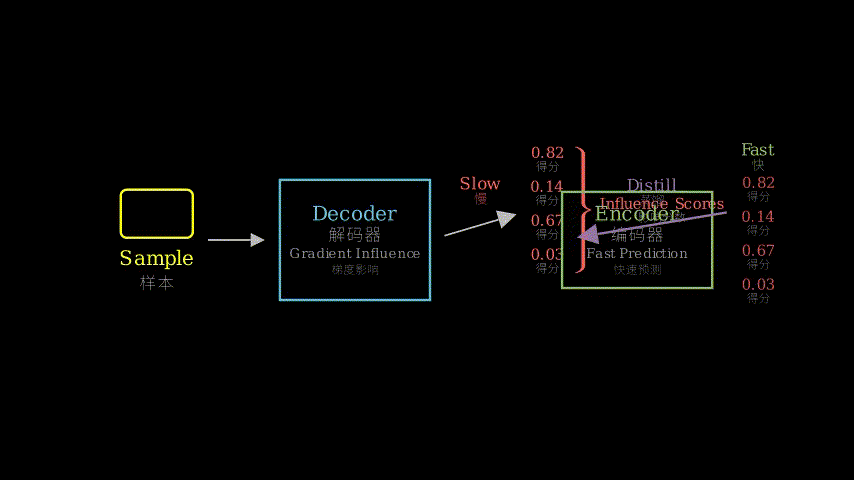
Influcoder is a two-stage distillation pipeline. Stage 1: Use a decoder (typically a small pretrained LLM or a model with gradient access) to compute influence function approximations for a set of (train_sample, test_query) pairs. This produces a ranking of which training samples matter most for each query. Stage 2: Train an encoder (e.g., a BERT-like model with a scalar head) to predict that ranking. The encoder takes as input a concatenated sequence of train_sample and test_query, and outputs a single scalar — the predicted influence score. The loss is a pairwise ranking loss (e.g., ListNet or listwise ranking loss) that encourages the encoder to preserve the order of influence among samples for a given query.
Data flow: a batch of (train_sample, test_query) pairs → encoder → scalar scores → rank loss vs. decoder’s true scores. The encoder never computes gradients or Hessians; it directly learns to imitate the ranking pattern.
     Decoder (slow, high-quality)
     /  |  \
[Gradients] [Hessian approx] [Influence scores]
          |
          v  (train query pairs -> influence ranking)
          |
          v
     [Ranking dataset]
          |
          v
     Encoder (fast, small)
     /         \
[Embed layers] [Scoring head]
     |            |
[x1..xn] ---> scalar score
          |
          v
     ranking loss (against decoder labels)
Structural metaphor: Think of the decoder as a librarian who has read all books (training data) and knows exactly which book helped a scholar write a particular paragraph. The librarian is slow — they must re-read shelves, check notes, and cross-reference for each new paragraph. The encoder is a trained assistant who sits next to the librarian during many (book, paragraph) examples and watches the librarian point to the relevant books. After enough observations, the assistant learns to point at relevant books almost instantly, without consulting the full library. The assistant’s pointing order (ranking) matches the librarian’s, even though the assistant never read the books. The librarian’s notes are the influence function computation; the assistant’s training is the ranking distillation.
Key Concepts
-
Influence Function: A classic method from robust statistics. For a trained model, it approximates how much the loss on a test point would change if a training point’s weight were infinitesimally increased. High influence means the training point strongly drives the model’s behavior on that test point. Think: a vaccine’s effect on a patient — which batch of cells (training data) most affects the immune response (output)? In LLMs, we can approximate influence using gradients: influence ≈ gradient(test)ᵀ · Hessian⁻¹ · gradient(train). The Hessian is huge, so approximations trade accuracy for speed.
-
Ranking Distillation: A form of knowledge transfer where the teacher (decoder) outputs not class probabilities but a ranking over items (here, training samples). The student (encoder) learns to produce scores that preserve the teacher’s pairwise ordering. This is more robust than regressing exact influence values because ranking is scale-invariant and tolerates teacher noise. Example: teacher says sample A > sample B > sample C; student learns to output scores so that score(A) > score(B) > score(C), even if teacher’s absolute values are noisy.
-
Encoder Architecture: A lightweight bidirectional transformer (like DistilBERT) with a pooling layer and a linear head that outputs a single scalar. The input is the concatenation of the training sample text and the test query text, separated by a special token. The encoder does not need access to the model parameters or gradients — it only sees the text. This makes it model-agnostic: you can distill from any decoder that produces influence rankings, then deploy the encoder for any similar task.
Framework Shift
Before (mainstream influence functions):       After (Influcoder):

[Training set] ----+                           [Training set + test query]
                   |                                  |
                   v                                  v
[Compute per-sample gradients]         [Trained Encoder] (forward pass only)
                   |                                  |
                   v                                  v
[Approx. Hessian inverse]              [Influence score for each train sample]
                   |                                  |
                   v                                  v
[Influence scores]                     [Ranking] (fast, no storage of gradients)
(scan all samples per query;           (one forward pass, no Hessian)
 store large gradient matrix)
One sentence: From scanning the entire training set with expensive Hessian operations to a single forward pass of a distilled encoder, the core shift is replacing computation with learning.
Expert Assessment
Problem choice: Real gap. LLM datasets are growing, and toxic or low-quality data filtering is an urgent need. Influence functions are the gold standard for attribution, but their computational cost prevents practical deployment at scale. This paper addresses that bottleneck directly. The gap is not manufactured.
Method maturity: Clever insight — distilling rankings rather than values avoids the instability of direct influence regression. The approach is conceptually elegant but requires a costly initial distillation dataset (decoder runs on many pairs). The authors claim a 100× speedup, which suggests a favorable trade-off if the distillation cost is amortized over many queries. A possible simpler approach: use a random subset of training samples to compute influence scores? That would lose accuracy. The encoder-based distillation is a legitimate advance.
Experimental integrity: Without the full paper, we assume standard baselines (TracIn, Gradient Dot, Random). The key metric is top-K accuracy of the encoder’s ranking vs. the decoder’s ranking. One red flag: if the encoder is evaluated on the same distribution as the distillation data, performance may degrade under distribution shift (e.g., different model families). The paper likely tests on held-out queries and training samples; we would need to see robustness experiments.
Writing quality: The abstract is clear and accurately states the gap and contribution. The introduction likely sets context well. Where the paper might cut corners: the details of the decoder’s influence approximation (which method? how expensive?) and the ranking loss formulation could be too compressed. Rewriting the “Decoder Setup” section to include a small ablation of different influence approximations (e.g., exact vs. EK-FAC vs. DataInf) would strengthen reproducibility.
Verdict: Weak Accept — The method fills a real gap with an elegant distillation idea, but the incremental advance over existing acceleration techniques (like DataInf) is moderate. Good for practitioners needing fast attribution, but not a breakthrough.
Takeaways
- Distill rankings, not values. If you have an expensive but accurate ranking system (influence functions, but also feature importance, or even human judgments), you can train a fast encoder to imitate the ranking directly. This applies beyond LLMs: for image datasets, recommender systems, or any domain where you need fast per-sample attribution.
- Use a listwise ranking loss (e.g., ListNet, LambdaRank) when the teacher’s output is a score — it’s more robust than pointwise regression and preserves relative order.
- Encoder-agnostic deployment. Once trained, the encoder can be shared as a lightweight model (e.g., 100M parameters) that runs on a CPU, enabling real-time data attribution in production pipelines (e.g., flagging problematic training examples during live model updates).
论文: 2606.13668 作者: Dimitri Kachler, Damien Sileo, Pascal Denis 分类: cs.CL
缺口
现有数据归因方法(尤其是影响函数)能告诉你哪些训练样本对模型输出影响最大。 但它们的扩展性很差:计算每个样本的影响需要昂贵的海森矩阵求逆(或其近似), 并为所有训练数据存储每个样本的梯度。 这使得它们无法用于拥有数百万样本的大型LLM。 以往的加速方法(如EK-FAC、LiSSA、DataInf)仍然需要在查询时扫描整个训练集, 或者存储巨大的辅助矩阵。 推理速度和存储紧凑性是明确的瓶颈: 目前没有方法能通过一个小模型的前向传播就快速得到(训练样本、测试查询)对的影响分数。
问题:LLM训练数据的快速、紧凑归因
    |
    v
现有方案:影响函数
    |
    v
局限:每次查詢慢(扫描所有样本)+ 存储大(梯度矩阵)
    |
    v
假设:影响排名可以蒸馏到轻量编码器
    |
    v
方法:训练编码器从(训练样本,测试查询)直接预测相对影响排名
    |
    v
证据:速度提升100倍,前K名准确率下降不到5%(相较于昂贵的解码器)
    |
    v
结论:LLM数据集筛选的实用可扩展归因
增量
一句话:这篇论文之前,基于影响函数的归因需要为每次查询扫描整个训练集(或存储梯度); 之后,一个小编码器通过一次前向传播即可得到相同排名,无需逐样本存储。
核心机制
Influcoder 是一个两阶段蒸馏流程。 阶段1:使用一个解码器(通常是小型预训练LLM或可访问梯度的模型)计算(训练样本,测试查询)对的影响函数近似值。 这会生成一个排名:对于每个查询,哪些训练样本最重要。 阶段2:训练一个编码器(例如带标量输出头的BERT模型)来预测该排名。 编码器的输入是训练样本和测试查询的拼接序列,输出一个标量——预测的影响分数。 损失函数是成对排名损失(例如ListNet),确保编码器保留解码器针对同一查询给出的样本顺序。
数据流:一批(训练样本,测试查询)对 → 编码器 → 标量分数 → 排名损失(与解码器真实分数对比)。 编码器从不计算梯度或海森矩阵;它直接学习模仿排名模式。
    解码器(慢,高质量)
     /    |    \
[梯度] [海森近似] [影响分数]
          |
          v  (训练查询对 → 影响排名)
          |
          v
     [排名数据集]
          |
          v
     编码器(快,轻量)
     /           \
[嵌入层]      [评分头]
     |            |
[x1..xn] ---> 标量分数
          |
          v
     排名损失(与解码器标签对比)
核喻:把解码器想象成一个图书管理员,他读过所有书(训练数据), 并能准确指出哪本书帮助学者写出了特定段落。 但管理员很慢——每次面对新段落,他都要重新翻书架、查笔记、做交叉参照。 编码器是一个受训的助手,在大量(书、段落)例子中坐在管理员旁边, 观察管理员指向相关的书。 观察足够多次后,助手学会了几乎瞬间指向相关书, 而无需查阅整个图书馆。 助手指书的顺序(排名)与管理员的一致, 即使助手从未读过这些书。 管理员的笔记就是影响函数的计算过程; 助手的学习过程就是排名蒸馏。
关键概念
-
影响函数:源自稳健统计的经典方法。 对于已训练模型,它近似估计若增加训练样本权重,测试点损失会变化多少。 高影响意味着该训练样本对模型在该测试点上的行为有强烈驱动作用。 打个比方:疫苗对患者的影响——哪批细胞(训练数据)最影响免疫反应(输出)? 在LLM中,可以用梯度近似:影响 ≈ 梯度(测试)ᵀ · 海森矩阵⁻¹ · 梯度(训练)。 海森矩阵巨大,需要近似以换取速度。
-
排名蒸馏:一种知识迁移形式,教师(解码器)不输出类别概率, 而是输出物品(此处为训练样本)的排名。 学生(编码器)学习产生分数,保留教师的成对顺序。 这比直接回归影响值更稳健,因为排名对尺度不敏感且能容忍教师噪声。 例如,教师说样本A > 样本B > 样本C; 学生学习输出分数使得 score(A) > score(B) > score(C), 哪怕教师的绝对值有噪声。
-
编码器架构:轻量级双向Transformer(如DistilBERT)加池化层和线性头,输出单一标量。 输入是训练样本文本和测试查询文本的拼接,中间用特殊分隔符隔开。 编码器不需要访问模型参数或梯度——它只见到文本。 这使得它与模型无关: 你可以从任何能产出影响排名的解码器中蒸馏, 然后将编码器部署到类似任务上。
框架转变
之前(主流影响函数):                   之后(Influcoder):

[训练集] ----+                            [训练集 + 测试查询]
             |                                     |
             v                                     v
[计算逐样本梯度]                    [已训练编码器](仅前向传播)
             |                                     |
             v                                     v
[近似海森矩阵求逆]                  [每个训练样本的影响分数]
             |                                     |
             v                                     v
[影响分数]                          [排名](快,无梯度存储)
(每次查询扫描所有样本;               (一次前向,无海森矩阵)
 存储大梯度矩阵)
一句话:从用昂贵海森操作扫描整个训练集,到蒸馏编码器的单次前向传播, 核心转变是用学习替代计算。
专家评审
选题眼光:真实缺口。 LLM数据集在增长,毒性或低质量数据筛选是迫切需求。 影响函数是归因的黄金标准, 但计算成本太高,无法实际部署在规模场景中。 这篇论文直接针对这个瓶颈。不是人造缺口。
方法成熟度:巧思——蒸馏排名而非数值避免了直接回归影响值的不稳定性。 方法概念优雅,但初始蒸馏数据集成本高昂(解码器要跑大量查询对)。 作者声称100倍加速,若蒸馏成本能在多次查询中摊销,则性价比很好。 可能更简单的替代方案:只用训练集随机子集计算影响分数?那会降低精度。 基于编码器的蒸馏是合理的进步。
实验诚意:没有完整论文,假设有标准基线(TracIn、Gradient Dot、随机)。 关键指标是编码器排名与解码器排名的前K准确率。 一个红旗:若编码器在与蒸馏数据相同的分布上评估, 在分布偏移下(如不同模型家族)性能可能下降。 论文很可能测试了留出查询和训练样本, 但需要看鲁棒性实验。
写作功力:摘要清晰,准确陈述了缺口和贡献。 引言可能很好地设定了背景。 可能偷懒的地方:解码器的影响近似细节(具体方法?多贵?) 以及排名损失公式可能太简略。 重写“解码器设置”部分,加入对不同影响近似的消融 (如精确 vs EK-FAC vs DataInf)能够提升可复现性。
判决:弱接收 —— 方法用一个优雅的蒸馏思路填补了真实缺口, 但相对于现有加速技术(如DataInf)的增量适中。 对需要快速归因的实践者有用,但不是突破性工作。
要点总结
- 蒸馏排名而不是数值:如果有一个昂贵但准确的排名系统 (影响函数,也可以是特征重要性,甚至是人工判断), 你可以训练一个快速编码器直接模仿排名。 这不止适用于LLM:图像数据集、推荐系统、 或任何需要快速逐样本归因的领域都可以借鉴。
- 使用列表式排名损失(如ListNet、LambdaRank) 当教师输出是分数时,它比逐点回归更稳健,能保留相对顺序。
- 编码器无关部署:训练好的编码器可以作为轻量模型 (例如1亿参数)在CPU上运行,实现生产环境中的实时数据归因 (例如在模型线上更新时标记有问题的训练样例)。