Paper: 2603.04045 Authors: Manuel Fernández Burda, Santiago Aranguri, Iván Arcuschin Moreno, Enzo Ferrante Categories: cs.LG, cs.AI
The Gap
Protein language models are now good enough to design novel proteins from scratch. The problem: when you fine-tune them on specific taxonomic groups (say, bacteria or fungi), they start generating toxic sequences even though you never asked for toxicity. Previous safety work focused on preventing intentional misuse through training-time interventions or post-hoc filtering. But what about accidental toxicity that emerges from innocent domain adaptation?
Existing approaches either require expensive retraining (alignment methods), throw away too many good sequences (filtering), or degrade biological plausibility (activation steering). The field needed a lightweight, inference-time control that doesn’t sacrifice the quality of generated proteins.
Problem: Domain adaptation -> accidental toxic proteins
   |
   v
Assumption: Toxicity signal lives in logit differences
   |
   v
Method: Amplify (baseline - toxic_model) logits at inference
   |
   v
Evidence: 4 taxa tested, toxicity down, quality preserved
   |
   v
Conclusion: Practical safety knob without retraining cost
The Increment
One sentence: Before this paper, you had to choose between safe-but-degraded proteins or high-quality-but-risky ones; now you can dial down toxicity at generation time while keeping biological plausibility intact.
Core Mechanism
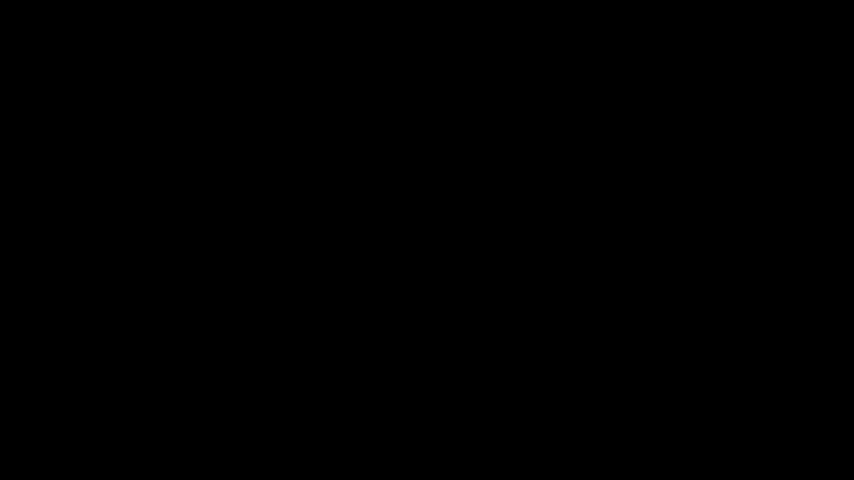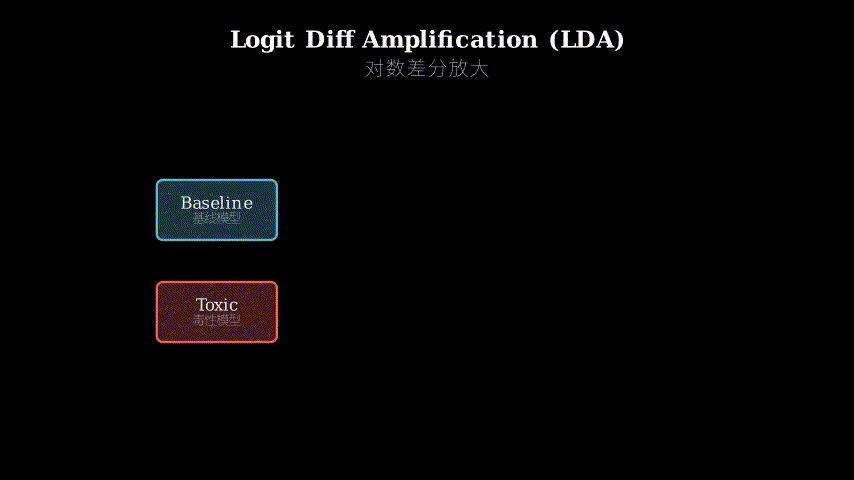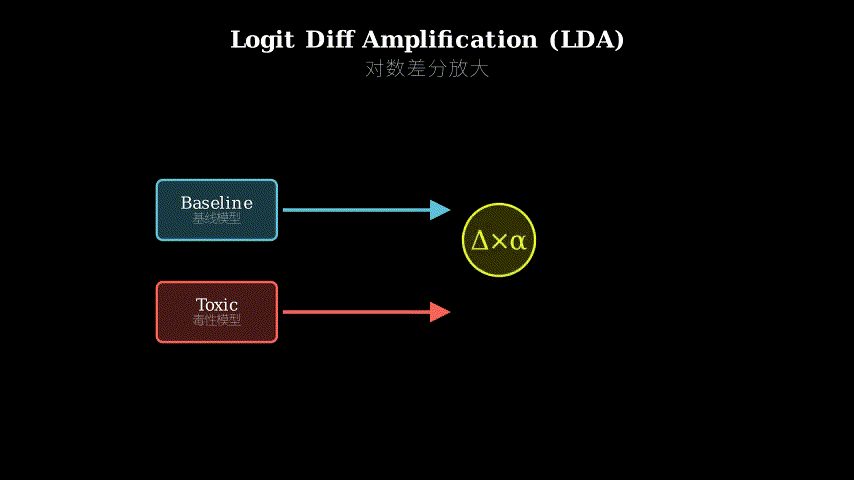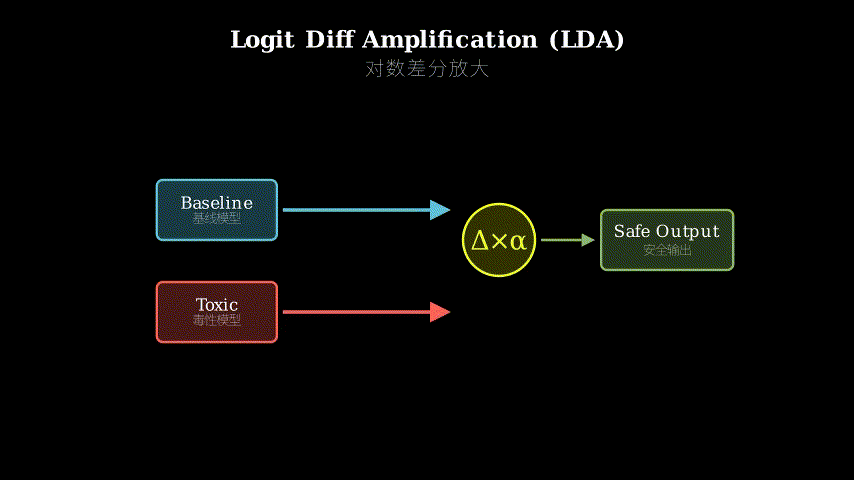
LDA works by running two models in parallel during generation: your baseline protein language model and a toxicity-finetuned version of the same model. At each token prediction step, you compute the logit difference (baseline minus toxic model) and amplify it by a scaling factor α before applying softmax. This pushes the probability mass toward tokens the baseline prefers and away from tokens the toxic model favors.
The key insight is that the toxic model has learned a direction in logit space that points toward toxicity. By subtracting its logits from the baseline and amplifying the difference, you’re essentially saying “go the opposite way from what the toxic model wants.” The amplification factor α controls how aggressively you steer—higher α means stronger toxicity suppression but potentially more deviation from natural protein distributions.
The method requires no gradient updates, no architectural changes, and no retraining. You just need access to both models’ logits at inference time. The computational overhead is minimal: one extra forward pass per token.
Generation loop at each position:

  Baseline PLM          Toxic PLM
       |                    |
       v                    v
  logits_base          logits_toxic
       |                    |
       +--------------------+
                |
                v
         diff = logits_base - logits_toxic
                |
                v
         amplified = logits_base + alpha * diff
                |
                v
            softmax
                |
                v
         sample next token
Think of it like driving with two GPS systems. Your main GPS (baseline model) knows the general route to your destination (biologically plausible proteins). But you also have a second GPS (toxic model) that’s been trained on routes through dangerous neighborhoods (toxic sequences). At every intersection, you check what the dangerous GPS suggests, then deliberately steer away from those turns. The amplification factor α is how hard you turn the wheel away—crank it up and you’ll avoid danger but might take a longer route; keep it moderate and you balance safety with efficiency.
Key Concepts
-
Logit Difference Amplification (LDA): Imagine you’re mixing paint colors. You have a base color (your baseline model’s predictions) and a “bad” color you want to avoid (toxic model’s predictions). Instead of just using the base color, you look at the difference between them and exaggerate it. If the base color is “more blue” than the bad color, you make it even bluer. This exaggeration happens in logit space (before probabilities are computed), so you’re amplifying the raw preference signal. The result: tokens that the toxic model likes become exponentially less likely to be sampled.
-
Dual-use risk in protein design: Protein language models can generate functional proteins, including enzymes, antibodies, or structural proteins. But “functional” is a double-edged sword—some proteins are functional toxins. The dual-use problem isn’t about malicious actors (though that’s a concern); it’s that the same capability that lets you design a therapeutic enzyme could accidentally design a neurotoxin if you fine-tune on the wrong organism. It’s like how a chemistry textbook teaches you to synthesize aspirin but also contains the knowledge to make explosives.
-
Biological plausibility metrics: How do you know if a generated protein sequence is “real” versus gibberish? Two key checks: (1) Fréchet ESM Distance measures whether your generated sequences have the same statistical fingerprint as natural proteins by comparing embeddings in a pretrained protein model’s latent space—think of it as asking “does this look like proteins I’ve seen before?” (2) pLDDT (predicted Local Distance Difference Test) from AlphaFold2 estimates whether the sequence would fold into a stable 3D structure—basically “would this actually work as a protein or just be a floppy mess?”
Framework Shift
Before (mainstream approach):        After (this paper):

Training time intervention:          Inference time steering:

  [Train] -> [Align] -> [Deploy]       [Train baseline] -> [Deploy]
              ^                                |
              |                                v
         (expensive,                    [At generation time:]
          permanent)                     baseline + toxic model
                                              |
                                              v
                                         logit diff
                                              |
                                              v
                                         amplify & sample
                                              ^
                                              |
                                         (cheap, tunable)
From baking safety into the model to adding a safety dial at serving time, the core shift is control flexibility without retraining cost.
Expert Assessment
Problem choice: This is a real gap, not manufactured. As protein design tools democratize, accidental toxicity from domain adaptation is a genuine safety concern that existing alignment methods don’t address well. The problem sits at the intersection of AI safety and computational biology—timely given recent advances in both fields.
Method maturity: LDA is borrowed from language model steering work (specifically contrastive decoding variants), so it’s not a novel algorithmic contribution. The insight here is recognizing that the technique transfers to protein generation and actually works better than activation-based steering methods. It’s clever adaptation rather than invention, but that’s fine—good engineering often beats novel theory.
Experimental integrity: The baselines are fair. They test across four taxonomic groups (bacteria, fungi, plants, animals) and compare against both the taxon-finetuned model and activation steering methods. The toxicity metric (ToxDL2) is a pretrained classifier, which introduces some circularity risk—are they just fooling one classifier?—but they back it up with biological plausibility metrics (FED, pLDDT) that show quality preservation. One red flag: no wet lab validation. These are all computational predictions. Would be stronger with at least a few synthesized sequences tested for actual toxicity.
Writing quality: The paper is clear but front-loads too much motivation about dual-use risks without quickly establishing what’s technically new. The method section is crisp, but the results section buries the lead—the key finding (LDA preserves quality unlike activation steering) should be a standalone figure, not mixed into ablation studies. Rewriting the intro to lead with “domain adaptation accidentally elicits toxicity” → “here’s a lightweight fix” would improve flow.
Verdict: weak accept — Solid engineering contribution addressing a real safety concern, though limited by lack of experimental validation and incremental algorithmic novelty.
Takeaways
The transferable idea here is inference-time steering via logit difference amplification as a safety mechanism. If you’re working with any generative model where you can identify an “undesirable direction” (toxicity, bias, off-topic generation), you can:
- Fine-tune a small model on examples of what you want to avoid
- At inference, compute logit differences between your base model and the “bad” model
- Amplify those differences to steer away from undesirable outputs
This is cheaper than retraining and more flexible than filtering. The key constraint: you need to be able to create a “negative exemplar” model, which requires having examples of what you want to avoid. In protein design, that’s toxic sequences. In language models, it could be biased text, off-brand responses, or factually incorrect statements.
The other concrete takeaway: biological plausibility metrics matter. Don’t just measure task performance (toxicity reduction)—check that you haven’t broken the underlying distribution (FED) or structural viability (pLDDT). This dual evaluation framework (safety + quality) is worth stealing for any safety intervention in generative models.
论文: 2603.04045 作者: Manuel Fernández Burda, Santiago Aranguri, Iván Arcuschin Moreno, Enzo Ferrante 分类: cs.LG, cs.AI
缺口
蛋白质语言模型现在已经能从零开始设计新型蛋白质。 问题来了:当你针对特定分类群(比如细菌或真菌)微调这些模型时,它们会开始生成有毒序列,尽管你从未要求过毒性。 之前的安全工作主要关注通过训练时干预或事后过滤来防止故意滥用。 但对于从无害的领域适应中意外涌现的毒性呢?
现有方法要么需要昂贵的重训练(对齐方法),要么丢弃太多好序列(过滤),要么降低生物学合理性(激活引导)。 该领域需要一种轻量级的推理时控制,不牺牲生成蛋白质的质量。
问题: 领域适应 -> 意外产生有毒蛋白质
   |
   v
假设: 毒性信号存在于对数差异中
   |
   v
方法: 在推理时放大(基线 - 毒性模型)对数值
   |
   v
证据: 测试4个分类群,毒性下降,质量保持
   |
   v
结论: 无需重训练成本的实用安全旋钮
增量
一句话: 这篇论文之前,你必须在安全但降质的蛋白质和高质量但有风险的蛋白质之间选择; 现在你可以在生成时调低毒性,同时保持生物学合理性。
核心机制
LDA的工作方式是在生成过程中并行运行两个模型:你的基线蛋白质语言模型和同一模型的毒性微调版本。 在每个token预测步骤,你计算对数差(基线减去毒性模型),然后在应用softmax之前用缩放因子α放大它。 这将概率质量推向基线偏好的token,远离毒性模型青睐的token。
关键洞察是毒性模型在对数空间中学到了一个指向毒性的方向。 通过从基线中减去其对数值并放大差异,你本质上在说”朝着毒性模型想要的相反方向走”。 放大因子α控制你引导的激进程度——更高的α意味着更强的毒性抑制,但可能更偏离自然蛋白质分布。
该方法不需要梯度更新,不需要架构改变,不需要重训练。 你只需要在推理时访问两个模型的对数值。 计算开销很小:每个token只需一次额外的前向传播。
每个位置的生成循环:

  基线PLM              毒性PLM
       |                    |
       v                    v
  logits_base          logits_toxic
       |                    |
       +--------------------+
                |
                v
         diff = logits_base - logits_toxic
                |
                v
         amplified = logits_base + alpha * diff
                |
                v
            softmax
                |
                v
         采样下一个token
把它想象成用两个GPS系统开车。 你的主GPS(基线模型)知道到达目的地的一般路线(生物学上合理的蛋白质)。 但你还有第二个GPS(毒性模型),它在危险街区的路线上训练过(有毒序列)。 在每个路口,你检查危险GPS的建议,然后故意避开那些转弯。 放大因子α是你转动方向盘的力度——把它调高,你会避开危险但可能走更长的路; 保持适度,你在安全和效率之间取得平衡。
关键概念
-
对数差分放大(LDA): 想象你在混合颜料。 你有一个基础颜色(基线模型的预测)和一个你想避免的”坏”颜色(毒性模型的预测)。 你不是只用基础颜色,而是看它们之间的差异并夸大它。 如果基础颜色比坏颜色”更蓝”,你就让它更蓝。 这种夸大发生在对数空间(在计算概率之前),所以你在放大原始偏好信号。 结果:毒性模型喜欢的token被采样的可能性呈指数级下降。
-
蛋白质设计中的双重用途风险: 蛋白质语言模型可以生成功能性蛋白质,包括酶、抗体或结构蛋白。 但”功能性”是一把双刃剑——有些蛋白质是功能性毒素。 双重用途问题不仅仅关于恶意行为者(尽管这也是一个担忧); 而是让你设计治疗性酶的同一能力,如果你在错误的生物体上微调,可能会意外设计出神经毒素。 这就像化学教科书教你合成阿司匹林,但也包含制造炸药的知识。
-
生物学合理性指标: 你如何知道生成的蛋白质序列是”真实的”而不是胡言乱语? 两个关键检查:(1)Fréchet ESM距离通过比较预训练蛋白质模型潜在空间中的嵌入,测量你生成的序列是否具有与天然蛋白质相同的统计指纹——可以理解为问”这看起来像我见过的蛋白质吗?” (2)来自AlphaFold2的pLDDT(预测局部距离差异测试)估计序列是否会折叠成稳定的3D结构——基本上是”这实际上能作为蛋白质工作还是只是一团乱麻?”
框架转变
之前(主流方法):                  之后(本文方法):

训练时干预:                      推理时引导:

  [训练] -> [对齐] -> [部署]       [训练基线] -> [部署]
              ^                                |
              |                                v
         (昂贵,                         [生成时:]
          永久性)                       基线 + 毒性模型
                                              |
                                              v
                                         对数差
                                              |
                                              v
                                         放大并采样
                                              ^
                                              |
                                         (便宜,可调)
从将安全性烘焙到模型中到在服务时添加安全旋钮,核心转变是无需重训练成本的控制灵活性。
专家评审
选题眼光: 这是真实的缺口,不是人造的。 随着蛋白质设计工具的民主化,领域适应带来的意外毒性是现有对齐方法无法很好解决的真正安全问题。 这个问题处于AI安全和计算生物学的交叉点——考虑到两个领域的最新进展,时机恰当。
方法成熟度: LDA借鉴自语言模型引导工作(特别是对比解码变体),所以不是新颖的算法贡献。 这里的洞察是认识到该技术可以迁移到蛋白质生成,并且实际上比基于激活的引导方法效果更好。 这是巧妙的适应而非发明,但这没问题——好的工程往往胜过新颖理论。
实验诚意: 基线是公平的。 他们在四个分类群(细菌、真菌、植物、动物)上测试,并与分类群微调模型和激活引导方法进行比较。 毒性指标(ToxDL2)是一个预训练分类器,这引入了一些循环风险——他们只是在愚弄一个分类器吗? 但他们用生物学合理性指标(FED、pLDDT)支持它,显示质量保持。 一个警示信号:没有湿实验室验证。 这些都是计算预测。 如果至少有几个合成序列测试实际毒性会更有说服力。
写作功力: 论文清晰,但在前面加载了太多关于双重用途风险的动机,没有快速确立技术上的新颖之处。 方法部分简洁,但结果部分埋没了重点——关键发现(LDA保持质量,不像激活引导)应该是独立的图,而不是混在消融研究中。 重写引言,以”领域适应意外引发毒性”→“这是一个轻量级修复”为主线会改善流畅度。
判决: 弱接收 — 解决真实安全问题的扎实工程贡献,尽管受限于缺乏实验验证和增量算法新颖性。
要点总结
这里可迁移的想法是通过对数差分放大进行推理时引导作为安全机制。 如果你正在使用任何生成模型,可以识别”不希望的方向”(毒性、偏见、离题生成),你可以:
- 在你想避免的示例上微调一个小模型
- 在推理时,计算基础模型和”坏”模型之间的对数差
- 放大这些差异以引导远离不希望的输出
这比重训练更便宜,比过滤更灵活。 关键约束:你需要能够创建一个”负面范例”模型,这需要有你想避免的示例。 在蛋白质设计中,那是有毒序列。 在语言模型中,可能是有偏见的文本、偏离品牌的回应或事实错误的陈述。
另一个具体要点:生物学合理性指标很重要。 不要只测量任务性能(毒性降低)——检查你是否破坏了底层分布(FED)或结构可行性(pLDDT)。 这种双重评估框架(安全+质量)值得在生成模型的任何安全干预中借鉴。