Paper: 2602.22193 Authors: Melody Ma, John Hewitt Categories: cs.CL
Abstract
This research investigates how reasoning language models access world knowledge stored in their parameters. While these models excel at mathematical reasoning through reinforcement learning, they underperform when retrieving factual knowledge. The authors discover that a simple “think step-by-step” prompt significantly improves knowledge recall but not mathematical performance, revealing a gap in how models apply reasoning to different domains. They propose training models via reinforcement learning on world-knowledge question answering tasks, using TriviaQA as the primary training dataset. This approach yields a 9.9% improvement on TriviaQA and transfers well to other benchmarks: Natural Questions (+4.2%), HotpotQA (+2.1%), SimpleQA (+0.6%), and StrategyQA (+3.0%).
Key Contributions
- Empirical demonstration that reasoning models generate suboptimal reasoning traces for parametric knowledge access by default
- Evidence that simple prompting interventions (“think step-by-step”) improve knowledge recall but not mathematical reasoning, suggesting domain-specific optimization gaps
- A reinforcement learning framework for training models to reason over their parametric knowledge using verifiable world-knowledge QA rewards
- Significant performance improvements across multiple knowledge-intensive benchmarks with strong transfer learning effects
- Analysis showing that reasoning models are systematically under-optimized for accessing their own stored knowledge
Methodology and Training Approach
The researchers employ a targeted reinforcement learning strategy to enhance parametric knowledge access. Unlike traditional reasoning model training that focuses on mathematical tasks, this work uses world-knowledge question answering as both the training objective and the reward signal. The training process leverages TriviaQA, a dataset containing factual questions with verifiable answers, allowing the model to receive clear feedback on whether its reasoning process successfully retrieves correct information.
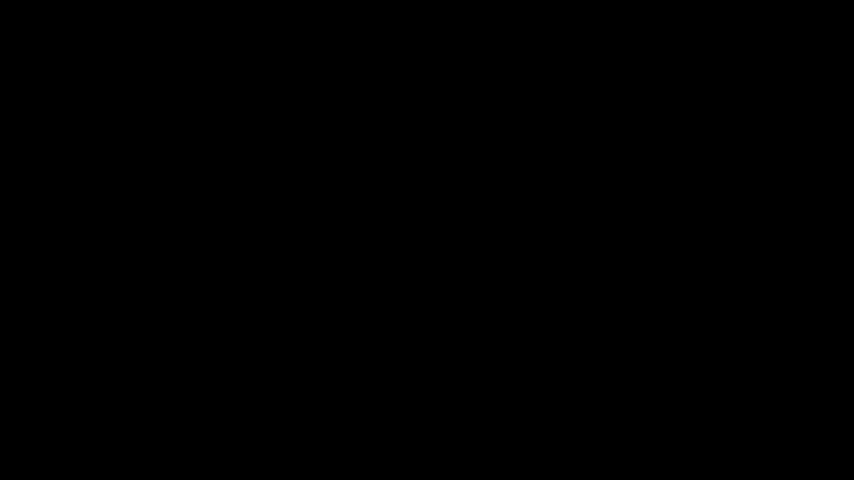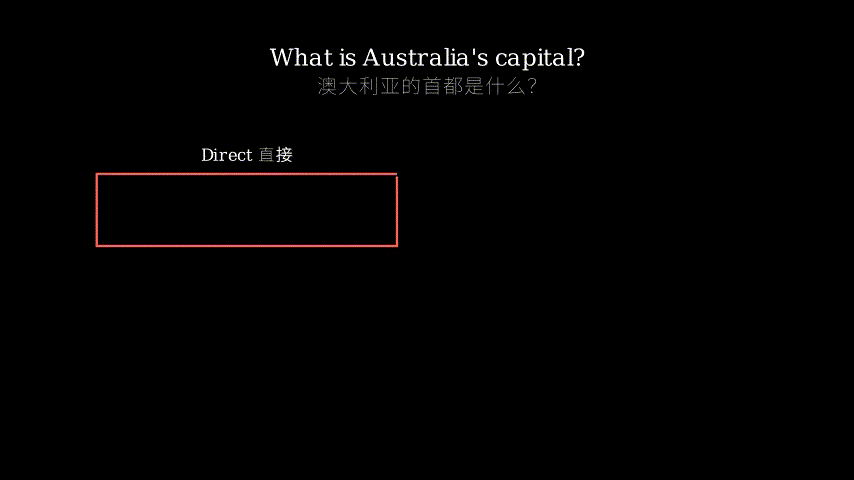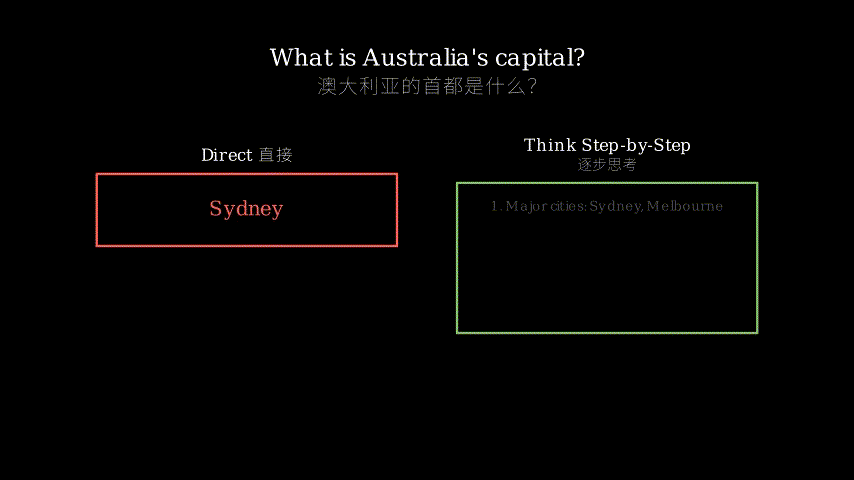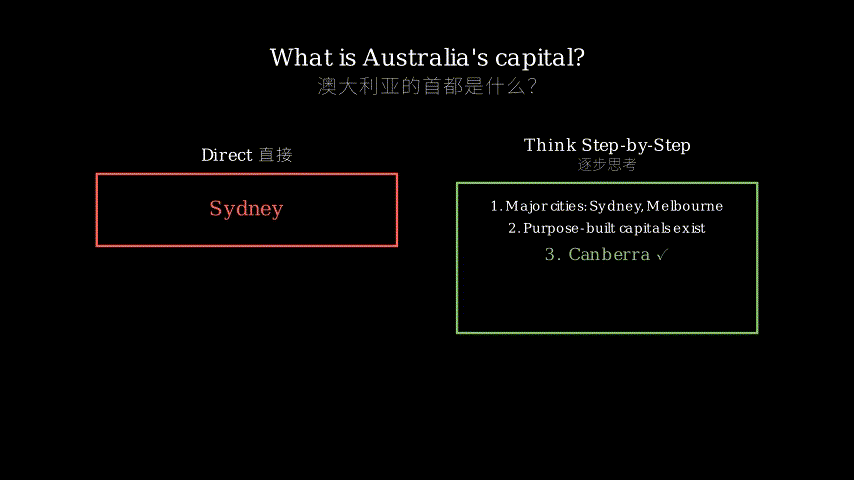
The key insight is that reasoning traces beneficial for knowledge retrieval differ from those optimized for mathematical problem-solving. For instance, recalling that Canberra is Australia’s capital might benefit from reasoning through concepts like “purpose-built capitals” or “major Australian cities,” creating a structured path to the correct answer. The reinforcement learning objective encourages the model to develop such knowledge-accessing reasoning patterns.
The training methodology maintains the model’s existing capabilities while specifically enhancing its ability to reason through factual recall. This targeted approach avoids the common pitfall of catastrophic forgetting, where training on new tasks degrades performance on previously learned ones.
Experimental Results and Analysis
The experimental results reveal substantial improvements across diverse knowledge-intensive benchmarks. On TriviaQA, the primary training dataset, the model achieves a 9.9% performance gain, demonstrating effective learning of knowledge-accessing reasoning patterns. More importantly, these improvements transfer to unseen datasets: Natural Questions shows a 4.2% increase, HotpotQA improves by 2.1%, and StrategyQA gains 3.0%.
The varying magnitudes of improvement across datasets provide insights into the nature of knowledge access reasoning. Larger gains on Natural Questions and StrategyQA suggest these tasks particularly benefit from structured reasoning over parametric knowledge. The more modest improvement on SimpleQA (0.6%) indicates that some knowledge access patterns may be dataset-specific or that SimpleQA requires different reasoning strategies.
Critically, the “think step-by-step” prompting experiment establishes a baseline showing that models possess latent capabilities for better knowledge reasoning but don’t employ them by default. This finding validates the core hypothesis: reasoning models need explicit optimization for parametric knowledge access, as their default training (focused on mathematical reasoning) doesn’t naturally generalize to this domain.
Implications for Language Model Development
This research has significant implications for how we train and deploy reasoning language models. First, it challenges the assumption that reasoning capabilities developed for one domain (mathematics) automatically transfer to others (knowledge retrieval). The results suggest that reasoning is not a monolithic skill but rather a collection of domain-specific strategies that require targeted optimization.
Second, the work demonstrates that parametric knowledge—information stored in model weights—can be more effectively accessed through learned reasoning patterns. This is particularly relevant as language models grow larger and store more world knowledge. Rather than relying solely on retrieval-augmented generation or external knowledge bases, models can be trained to better utilize their internal knowledge through structured reasoning.
Third, the strong transfer learning effects across multiple benchmarks suggest that knowledge-accessing reasoning patterns are somewhat generalizable. Training on one knowledge-intensive dataset (TriviaQA) improves performance on others, indicating that the model learns broadly applicable strategies for navigating its parametric knowledge rather than dataset-specific tricks.
Finally, this research opens questions about the optimal balance between different types of reasoning training. Future work might explore curriculum learning approaches that systematically develop both mathematical and knowledge-accessing reasoning, or investigate whether other domains (commonsense reasoning, causal inference) similarly require specialized reasoning optimization.
Takeaways
- Reasoning language models are systematically under-optimized for accessing their parametric knowledge, despite strong performance on mathematical reasoning tasks
- Simple prompting interventions reveal latent capabilities, but explicit reinforcement learning training is needed for consistent improvement
- Training on world-knowledge QA tasks yields substantial gains (9.9% on TriviaQA) with strong transfer to other knowledge-intensive benchmarks
- Reasoning strategies are domain-specific: what works for mathematics doesn’t automatically work for knowledge retrieval
- The gap between prompted and default performance suggests significant room for improvement in how reasoning models are trained and deployed
论文: 2602.22193 作者: Melody Ma, John Hewitt 分类: cs.CL
摘要
本研究探讨了推理语言模型如何访问存储在其参数中的世界知识。虽然这些模型通过强化学习在数学推理方面表现出色,但在检索事实知识时表现不佳。作者发现,简单的”逐步思考”提示能显著改善知识回忆但不影响数学性能,揭示了模型在不同领域应用推理能力的差距。他们提出通过强化学习在世界知识问答任务上训练模型,使用TriviaQA作为主要训练数据集。这种方法在TriviaQA上获得9.9%的提升,并很好地迁移到其他基准测试:Natural Questions(+4.2%)、HotpotQA(+2.1%)、SimpleQA(+0.6%)和StrategyQA(+3.0%)。
主要贡献
- 实证表明推理模型在默认情况下为参数化知识访问生成次优的推理轨迹
- 证明简单的提示干预(“逐步思考”)能改善知识回忆但不影响数学推理,表明存在领域特定的优化差距
- 提出使用可验证的世界知识问答奖励来训练模型对其参数化知识进行推理的强化学习框架
- 在多个知识密集型基准测试中取得显著性能提升,展现出强大的迁移学习效果
- 分析表明推理模型在访问其自身存储知识方面系统性地优化不足
方法论与训练策略
研究人员采用了针对性的强化学习策略来增强参数化知识访问能力。与传统的专注于数学任务的推理模型训练不同,本工作将世界知识问答同时作为训练目标和奖励信号。训练过程利用TriviaQA数据集,该数据集包含具有可验证答案的事实性问题,使模型能够获得关于其推理过程是否成功检索正确信息的明确反馈。
关键洞察在于,有益于知识检索的推理轨迹与为数学问题求解优化的推理轨迹不同。例如,回忆堪培拉是澳大利亚首都可能受益于通过”专门建造的首都”或”澳大利亚主要城市”等概念进行推理,创建一条通往正确答案的结构化路径。强化学习目标鼓励模型发展这种知识访问推理模式。
训练方法在保持模型现有能力的同时,专门增强其通过事实回忆进行推理的能力。这种针对性方法避免了灾难性遗忘的常见陷阱,即在新任务上的训练会降低先前学习任务的性能。
实验结果与分析
实验结果显示在多样化的知识密集型基准测试中取得了实质性改进。在主要训练数据集TriviaQA上,模型实现了9.9%的性能提升,证明了知识访问推理模式的有效学习。更重要的是,这些改进迁移到了未见过的数据集:Natural Questions显示4.2%的增长,HotpotQA提高2.1%,StrategyQA获得3.0%的提升。
不同数据集上改进幅度的差异为理解知识访问推理的本质提供了洞察。Natural Questions和StrategyQA上的较大提升表明这些任务特别受益于对参数化知识的结构化推理。SimpleQA上较为温和的改进(0.6%)表明某些知识访问模式可能是数据集特定的,或者SimpleQA需要不同的推理策略。
关键的是,“逐步思考”提示实验建立了一个基线,表明模型具有更好的知识推理潜在能力,但默认情况下不会使用它们。这一发现验证了核心假设:推理模型需要对参数化知识访问进行显式优化,因为它们的默认训练(专注于数学推理)不会自然地泛化到这个领域。
对语言模型开发的启示
这项研究对我们如何训练和部署推理语言模型具有重要意义。首先,它挑战了为一个领域(数学)开发的推理能力会自动迁移到其他领域(知识检索)的假设。结果表明,推理不是一种单一技能,而是需要针对性优化的领域特定策略集合。
其次,这项工作证明了通过学习的推理模式可以更有效地访问参数化知识——存储在模型权重中的信息。随着语言模型规模增大并存储更多世界知识,这一点尤为相关。模型可以通过结构化推理更好地利用其内部知识,而不仅仅依赖检索增强生成或外部知识库。
第三,跨多个基准测试的强大迁移学习效果表明,知识访问推理模式在某种程度上是可泛化的。在一个知识密集型数据集(TriviaQA)上的训练改善了其他数据集的性能,表明模型学习的是导航其参数化知识的广泛适用策略,而不是数据集特定的技巧。
最后,这项研究提出了关于不同类型推理训练之间最佳平衡的问题。未来的工作可能探索系统性发展数学和知识访问推理的课程学习方法,或研究其他领域(常识推理、因果推断)是否同样需要专门的推理优化。
要点总结
- 推理语言模型在访问其参数化知识方面系统性地优化不足,尽管在数学推理任务上表现强劲
- 简单的提示干预揭示了潜在能力,但需要显式的强化学习训练才能实现持续改进
- 在世界知识问答任务上的训练产生了显著提升(TriviaQA上9.9%),并强力迁移到其他知识密集型基准测试
- 推理策略是领域特定的:适用于数学的方法不会自动适用于知识检索
- 提示性能与默认性能之间的差距表明推理模型的训练和部署方式还有很大改进空间