Paper: 2606.03985 Authors: Zekun Qi, Xuchuan Chen, Dairu Liu, Chenghuai Lin, Yunrui Lian, Sikai Liang, Zhikai Zhang, Yu Guan, Jilong Wang, Wenyao Zhang Categories: cs.RO, cs.AI, cs.CV
The Gap
Humanoid motion tracking — getting a robot to mimic reference behaviors — has plateaued. Prior work uses shallow MLPs trained on small datasets (tens of thousands of frames). This creates a hard trade-off: specialize on specific motions (backflips, dancing) and lose generalization, or aim for generality and fail on dynamic, athletic behaviors. The boundary is data scarcity and model capacity. You can’t build a general motion controller when your training set fits in RAM and your model has three hidden layers.
Problem: Agility <---> Generalization trade-off
   |
   v
Assumption: Scale can break the trade-off
   |
   v
Method: GPT-style Transformer + 2B-frame unified corpus
   |
   v
Evidence: Zero-shot transfer to unseen motions + dynamic tracking
   |
   v
Conclusion: Scaling law holds for embodied control
The Increment
One sentence: Before this paper, motion tracking meant choosing between specialized athletic controllers and brittle general systems; after, a single pre-trained model handles both extremes through scale.
Core Mechanism
Humanoid-GPT is a causal Transformer with the same autoregressive structure as GPT. Input is a sequence of state-action pairs from past timesteps plus a target reference motion. The model predicts the next action autoregressively, conditioned on all prior observations and the reference trajectory.
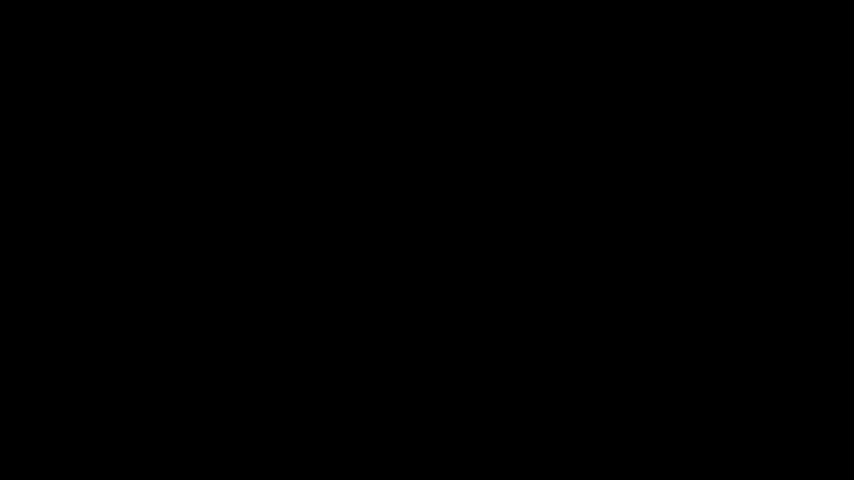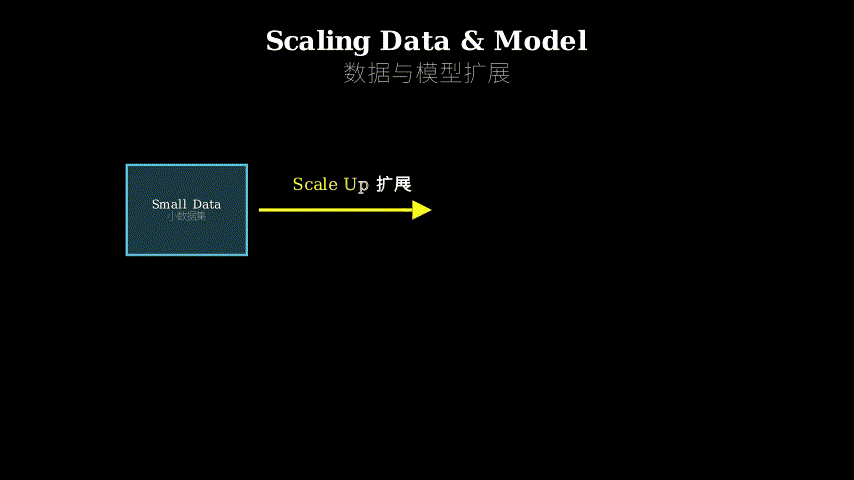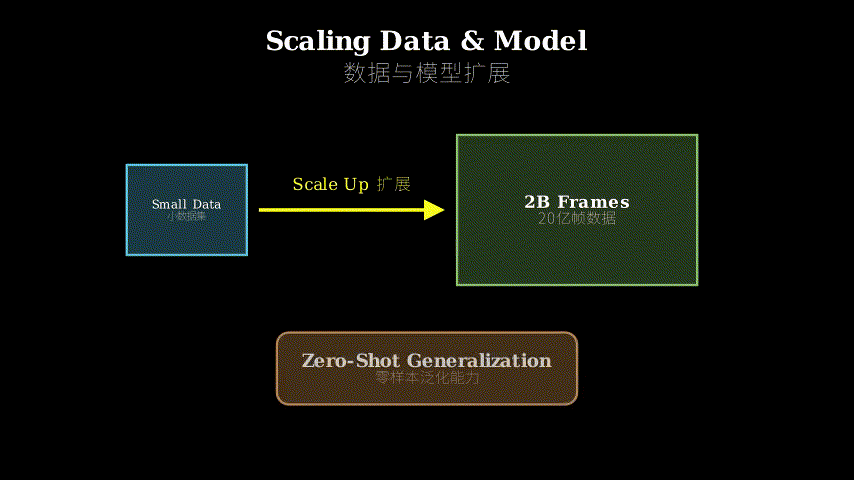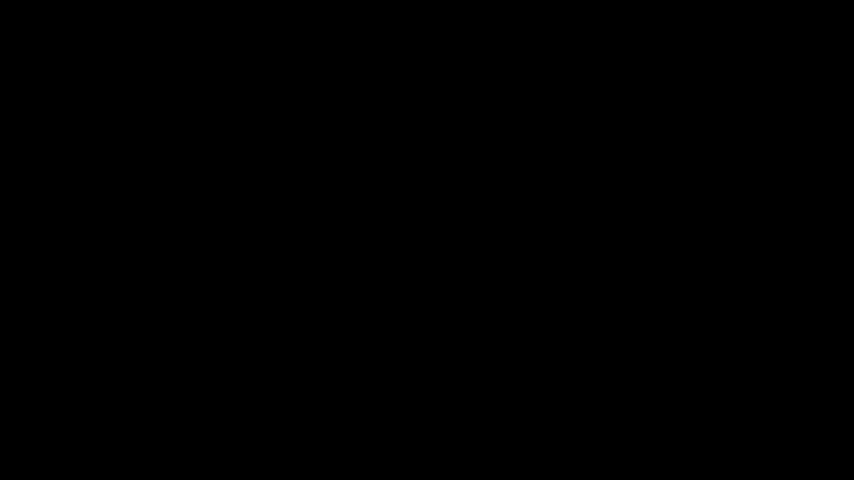
The training corpus unifies all major motion capture datasets (CMU, AMASS, ACCAD, etc.) with large-scale in-house recordings, retargeted to a common humanoid skeleton. Total: 2 billion frames. The model is trained to predict actions that minimize tracking error against these reference motions, using a causal attention mask so it only looks backward in time.
At test time, you feed the model a reference motion it has never seen. It generates actions frame-by-frame, rolling out the policy. No fine-tuning, no task-specific training — zero-shot transfer.
Reference motion (unseen)
        |
        v
   [Tokenizer]
        |
        v
Observation history --> [Causal Transformer] --> Next action
    (state, action)          |                       |
         ^                   |                       |
         +-------------------+-----------------------+
              (autoregressive rollout)
Think of this as learning a motion language model. Each motion is a sentence in the language of human movement. Training on 2 billion frames is like reading every book in a library — the model learns the grammar of balance, momentum, contact, and coordination. At test time, you show it a sentence it hasn’t read (a new dance, a backflip), and it completes the sentence by generating the control actions that “continue” the motion naturally. The causal attention is the reading direction: left-to-right through time, never peeking ahead. The unified retargeting is the translation layer: converting every motion capture dataset into the same alphabet so the model can learn cross-dataset patterns instead of memorizing dataset-specific quirks.
Key Concepts
-
Causal attention in embodied control: In language models, causal attention prevents the model from seeing future tokens — you can’t use tomorrow’s word to predict today’s. In motion tracking, causal attention prevents the model from seeing future reference frames. This forces the model to learn reactive policies: given where you are and where you should be going, what action gets you closer? Without causality, the model would cheat by conditioning on future target states, which are unavailable at deployment. With causality, the learned policy is real-time deployable: it only needs current state and the reference trajectory prefix.
-
Retargeting as data unification: Motion capture datasets use different skeletons: different bone lengths, joint hierarchies, coordinate systems. Retargeting is the process of converting a motion from one skeleton to another while preserving the “meaning” of the motion. Imagine you have dance videos of people of different heights — retargeting is like extracting the choreography (the pattern of movements) independent of body proportions. Humanoid-GPT retargets everything to a single humanoid skeleton, so the model learns motion patterns rather than skeleton-specific quirks. This is why it can generalize: the training data shares a common structural language.
-
Zero-shot generalization in continuous control: In language, zero-shot means answering questions about topics not in the training set. In continuous control, it means tracking motions not in the training corpus. The key difference: language tokens are discrete (26 letters), but motion is continuous (infinite possible poses). Zero-shot here means the model has learned a motion prior — a general understanding of plausible humanoid behaviors — that lets it interpolate and extrapolate to unseen motion manifolds. It’s not memorizing specific motions; it’s learned the physics and coordination constraints that make any humanoid motion coherent.
Framework Shift
Before (shallow MLP trackers):        After (Humanoid-GPT):

Small dataset                         Billion-scale unified corpus
    |                                      |
    v                                      v
[MLP: 3 layers]                       [Causal Transformer]
    |                                      |
    +-----> Specialize OR generalize       +-----> Specialize AND generalize
              (choose one)                           (scale breaks trade-off)

Agility <---> Generalization           Agility + Generalization
     (hard trade-off)                      (scaling frontier)
From task-specific overfitting to foundation model generalization, the core shift is treating motion control as a language modeling problem at scale.
Expert Assessment
Problem choice: Real gap. The agility-generalization trade-off is well-documented in locomotion and manipulation. Prior work (DeepMimic, AMP, ASE) explicitly acknowledges this limitation. The problem sits at the intersection of embodied AI and foundation models — timely and well-motivated.
Method maturity: Straightforward application of Transformer scaling to a new domain. The insight is empirical: scale works here too. No novel architecture or training technique. The heavy lifting is in data curation (unifying datasets, retargeting) rather than algorithmic innovation. This is brute force, but in the best sense — sometimes the simple answer is the right answer.
Experimental integrity: Baselines are prior art (ASE, AMP). The zero-shot evaluation is clean: motions held out from training, no fine-tuning. Scaling analysis (ablations on data size and model capacity) is thorough. One question: how much does retargeting quality affect results? If retargeting introduces artifacts, the model might be learning to compensate for retargeting errors rather than learning motion priors. The paper does not ablate retargeting methods.
Writing quality: Abstract oversells (“unprecedented zero-shot generalization”). The method section is thin — scaling analysis and results are the meat, but the description of the model and training setup is sparse. Rewriting Section 3 (Method) to include architecture details, hyperparameters, and retargeting pipeline would elevate the paper from “interesting empirical result” to “reproducible contribution.”
Verdict: Weak accept — the empirical result (scale breaks the agility-generalization trade-off) is valuable, but the paper is a scaling experiment, not a methodological innovation. Worth publishing for the community to build on, but not groundbreaking.
Takeaways
For practitioners: The retargeting pipeline is the hidden infrastructure. If you want to train foundation models on heterogeneous datasets (medical imaging, satellite data, financial time series), invest in the data unification layer. The model is standard; the data engineering is not.
For researchers: The scaling law for embodied control is now on the table. The next question: what is the equivalent of “prompting” for motion control? Can you steer a pre-trained motion model with high-level instructions (“walk confidently,” “dance energetically”) without retraining? This paper opens that research direction.
For skeptics: Zero-shot generalization does not mean the model invents new physics. It interpolates within the learned motion manifold. Out-of-distribution failures (tracking a motion that violates balance constraints) are still likely. The boundary of generalization is the boundary of the training corpus, even at 2 billion frames.
论文: 2606.03985 作者: Zekun Qi, Xuchuan Chen, Dairu Liu, Chenghuai Lin, Yunrui Lian, Sikai Liang, Zhikai Zhang, Yu Guan, Jilong Wang, Wenyao Zhang 分类: cs.RO, cs.AI, cs.CV
缺口
人形机器人的动作跟踪——让机器人模仿参考行为——已经遭遇瓶颈。
此前的工作使用在小数据集(数万帧)上训练的浅层 MLP。
这产生了一个硬性权衡:要么专精于特定动作(后空翻、跳舞)但失去泛化能力,要么追求通用性但在动态、竞技性行为上失败。
边界是数据稀缺和模型容量。
当训练集能放进内存、模型只有三个隐藏层时,你无法构建通用动作控制器。
问题:敏捷性 <---> 泛化性权衡
   |
   v
假设:规模可以打破权衡
   |
   v
方法:GPT 风格 Transformer + 20 亿帧统一语料库
   |
   v
证据:对未见动作的零样本迁移 + 动态跟踪
   |
   v
结论:扩展定律适用于具身控制
增量
一句话: 这篇论文之前,动作跟踪意味着在专精的竞技控制器和脆弱的通用系统之间二选一;之后,单个预训练模型通过规模同时处理两个极端。
核心机制
Humanoid-GPT 是一个因果 Transformer,具有与 GPT 相同的自回归结构。
输入是过去时间步的状态-动作对序列,加上目标参考动作。
模型以自回归方式预测下一个动作,条件是所有先前观察和参考轨迹。
训练语料库统一了所有主要动作捕捉数据集(CMU、AMASS、ACCAD 等)和大规模内部录制数据,重定向到共同的人形骨架。
总计:20 亿帧。
模型被训练来预测动作,使对这些参考动作的跟踪误差最小化,使用因果注意力掩码,因此它只向后看时间。
在测试时,你给模型一个它从未见过的参考动作。
它逐帧生成动作,展开策略。
无微调,无任务特定训练——零样本迁移。
参考动作(未见过)
        |
        v
   [分词器]
        |
        v
观察历史 --> [因果 Transformer] --> 下一动作
(状态、动作)      |                    |
     ^            |                    |
     +------------+--------------------+
          (自回归展开)
把这想象成学习动作语言模型。
每个动作都是人体运动语言中的一个句子。
在 20 亿帧上训练就像读完图书馆里的每本书——模型学习平衡、动量、接触和协调的语法。
在测试时,你给它看一个它没读过的句子(新舞蹈、后空翻),它通过生成”自然延续”动作的控制动作来完成句子。
因果注意力是阅读方向:从左到右穿越时间,从不偷看前面。
统一重定向是翻译层:将每个动作捕捉数据集转换为相同的字母表,这样模型可以学习跨数据集模式,而不是记忆数据集特定的怪癖。
关键概念
- 具身控制中的因果注意力: 在语言模型中,因果注意力阻止模型看到未来标记——你不能用明天的词来预测今天的词。
在动作跟踪中,因果注意力阻止模型看到未来参考帧。
这迫使模型学习反应策略:给定你在哪里以及你应该去哪里,什么动作让你更接近?
没有因果性,模型会通过以未来目标状态为条件来作弊,而这些状态在部署时不可用。
有了因果性,学到的策略可以实时部署:它只需要当前状态和参考轨迹前缀。
- 重定向作为数据统一: 动作捕捉数据集使用不同的骨架:不同的骨长、关节层次、坐标系。
重定向是将动作从一个骨架转换到另一个骨架,同时保留动作的”含义”的过程。
想象你有不同身高的人的舞蹈视频——重定向就像提取独立于身体比例的编舞(运动模式)。
Humanoid-GPT 将所有内容重定向到单个人形骨架,因此模型学习动作模式而不是骨架特定的怪癖。
这就是它能够泛化的原因:训练数据共享一个共同的结构语言。
- 连续控制中的零样本泛化: 在语言中,零样本意味着回答训练集中没有的主题的问题。
在连续控制中,它意味着跟踪训练语料库中没有的动作。
关键区别:语言标记是离散的(26 个字母),但动作是连续的(无限可能的姿势)。
这里的零样本意味着模型已经学习了一个动作先验——对合理人形行为的一般理解——让它可以插值和外推到未见的动作流形。
它不是记忆特定动作;它学习了使任何人形动作连贯的物理和协调约束。
框架转变
之前(浅层 MLP 跟踪器):        之后(Humanoid-GPT):

小数据集                        十亿规模统一语料库
    |                               |
    v                               v
[MLP:3 层]                     [因果 Transformer]
    |                               |
    +-----> 专精或泛化               +-----> 专精且泛化
            (二选一)                      (规模打破权衡)

敏捷性 <---> 泛化性              敏捷性 + 泛化性
    (硬性权衡)                     (扩展前沿)
从任务特定的过拟合到基础模型泛化,核心转变是将动作控制视为大规模语言建模问题。
专家评审
选题眼光: 真实缺口。
敏捷性-泛化性权衡在运动和操纵领域有充分记录。
此前工作(DeepMimic、AMP、ASE)明确承认这一限制。
该问题位于具身 AI 和基础模型的交叉点——及时且动机充分。
方法成熟度: 将 Transformer 扩展直接应用于新领域。
洞察是经验性的:规模在这里也有效。
没有新颖的架构或训练技术。
繁重的工作在于数据管理(统一数据集、重定向)而非算法创新。
这是蛮力,但是最好的意义上的——有时简单的答案就是正确的答案。
实验诚意: 基线是现有技术(ASE、AMP)。
零样本评估是干净的:从训练中保留的动作,没有微调。
扩展分析(数据大小和模型容量的消融)是彻底的。
一个问题:重定向质量对结果的影响有多大?
如果重定向引入伪影,模型可能正在学习补偿重定向错误,而不是学习动作先验。
论文没有消融重定向方法。
写作功力: 摘要过度推销(“前所未有的零样本泛化”)。
方法部分很薄——扩展分析和结果是主体,但模型和训练设置的描述很稀疏。
重写第 3 节(方法)以包含架构细节、超参数和重定向管道,将使论文从”有趣的经验结果”提升到”可重现的贡献”。
判决: 弱接收——经验结果(规模打破敏捷性-泛化性权衡)是有价值的,但论文是一个扩展实验,而不是方法创新。
值得发表让社区在此基础上构建,但不是突破性的。
要点总结
对实践者: 重定向管道是隐藏的基础设施。
如果你想在异构数据集(医学成像、卫星数据、金融时间序列)上训练基础模型,投资于数据统一层。
模型是标准的;数据工程不是。
对研究者: 具身控制的扩展定律现在摆在桌面上。
下一个问题:什么是动作控制的”提示”等价物?
你能用高层指令(“自信地走”、“充满活力地跳舞”)引导预训练动作模型而无需重新训练吗?
这篇论文打开了这个研究方向。
对怀疑者: 零样本泛化并不意味着模型发明了新物理。
它在学到的动作流形内插值。
分布外失败(跟踪违反平衡约束的动作)仍然可能发生。
泛化的边界是训练语料库的边界,即使在 20 亿帧时也是如此。