Paper: 2606.20560 Authors: Joshua Engels, Callum McDougall, Bilal Chughtai, Janos Kramar, Senthoran Rajamanoharan, Cindy Wu, Arthur Conmy, Asic Q Chen, Jean Tarbouriech, Min Ma Categories: cs.LG, cs.AI
The Gap
Existing interpretability research on autoregressive LLMs (e.g., Gemma) treats each generated token as a transparent step — you can inspect the logits after each output. But DiffusionGemma performs most of its computation in a continuous latent space across many denoising steps. This raises an obvious question: does the lack of discrete token snapshots make diffusion models inherently less transparent? Prior work on diffusion model interpretability (e.g., in image domains) focused on feature visualization, not on reconstructing algorithmic reasoning over tokens. This paper is the first to decompose transparency into variable and algorithmic components for diffusion language models, and to propose a concrete method for recovering variable transparency via a token bottleneck.
[Problem: opaque serial depth of 28.6X vs auto. model]
    |
    v
[Assumption: interpretable token states exist between denoising steps]
    |
    v
[Method: train a token bottleneck to map latent -> tokens, run case studies]
    |
    v
[Evidence: variable transparency drops to 1.1X; algorithmic cases show smearing, non-chronological reasoning]
    |
    v
[Conclusion: variable transparency fixable, algorithmic transparency requires new tools]
The Increment
One sentence: Before this paper, DiffusionGemma was assumed to be fundamentally opaque; after this paper, we know that variable transparency can be restored to near-autoregressive levels, but algorithmic transparency reveals previously unknown reasoning patterns that complicate process-level understanding.
Core Mechanism
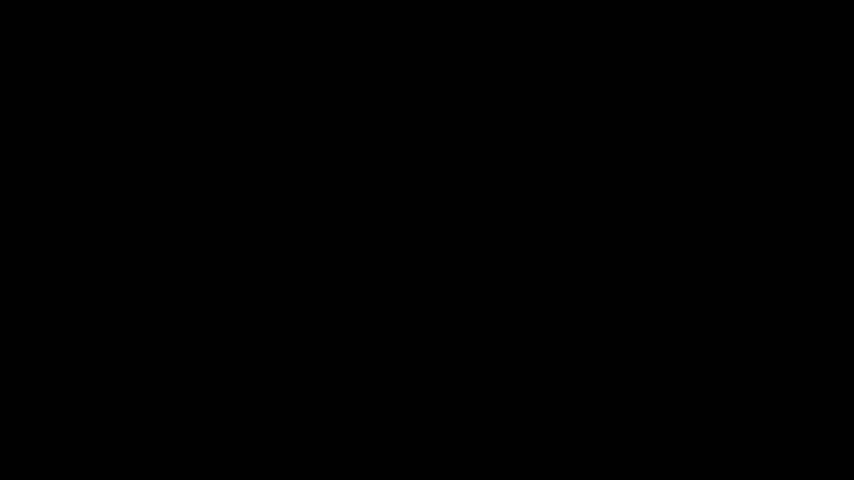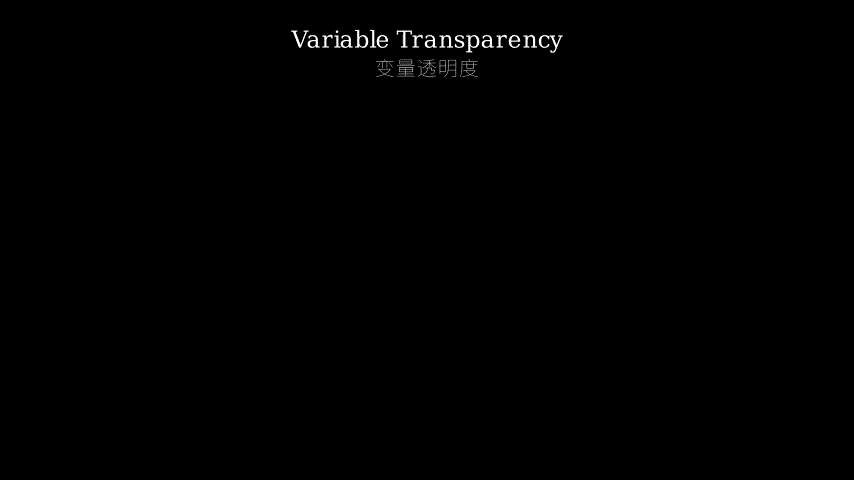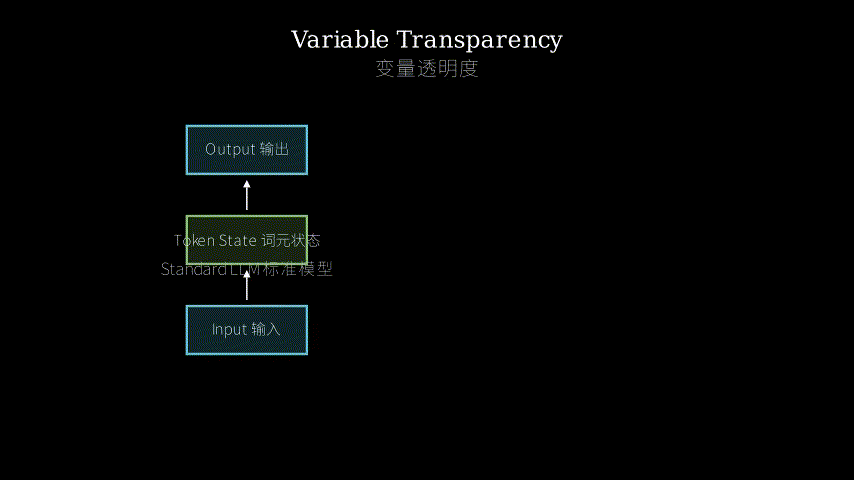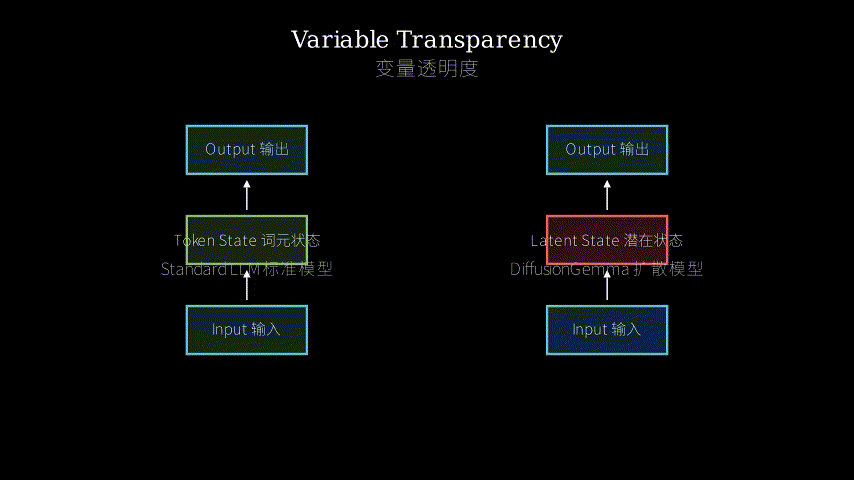
The authors first measure “opaque serial depth” — the amount of computation that happens between interpretable model states. Naively, DiffusionGemma’s depth is 28.6× higher than Gemma 4 because each denoising step’s latent vector is not a discrete token. To recover interpretability, they train a “token bottleneck”: a small learned projection that maps the continuous latent representation at each denoising step into a sequence of tokens. This bottleneck is trained end-to-end on the final output objective (no loss in downstream performance), acting as a translator that forces the model to expose its intermediate state in human-readable form. Once each denoising step has an associated token sequence, the opaque serial depth collapses to 1.1× that of Gemma 4.
However, algorithmic transparency remains harder. In an autoregressive model, token predictions are made left-to-right; you can trace a causal chain. In a diffusion model, every token prediction on the canvas can change at every denoising step, enabling distributed algorithms that rewrite earlier decisions. To explore this, the authors conduct a suite of interpretability case studies — probing how token representations evolve across steps, and tracking attention patterns. They discover qualitatively novel phenomena: non-chronological reasoning (a token’s final semantics appear before its position’s content is finalized), token and sequence smearing (information about one token bleeds into neighboring positions mid-denoising), and intermediate-context reasoning (the model holds a partial interpretation of the entire sequence before settling on the final tokens).
[Input: noisy token canvas]
    |
    v
[Denoising step 1: latent z_1]
    |
    +--token bottleneck--> [interpretable tokens T_1]   (variable transparency)
    |
    v
[Denoising step 2: latent z_2]
    |
    +--token bottleneck--> [interpretable tokens T_2]
    |
    v
[.....continue.....]
    |
    v
[Final clean tokens]
Think of it like editing a movie. The raw diffusion process is a continuous stream of frames (latent vectors) — too fast to follow. The token bottleneck acts like a “keyframe extractor”: it picks representative frames and labels the main objects in each. With keyframes, you can now understand the story scene by scene (variable transparency). But the actual film editing is not linear: the director might show a character’s reaction before the event that causes it (non-chronological reasoning), or blend two scenes together (smearing). The case studies help reveal these unconventional editing techniques. Without the keyframes you’d see nothing; with them you at least know that the director is doing something odd, even if you don’t fully understand how they planned the edit.
Key Concepts
-
Variable Transparency: How well we understand a snapshot of the model’s computational state at a given time. In autoregressive models, the state *is the token sequence — trivial. In diffusion models, the state is a continuous tensor; readability is near zero. The token bottleneck restores readability by converting the tensor into a token sequence, giving us a snapshot we can inspect.
-
Algorithmic Transparency: Can we reconstruct the reasoning process (the sequence of operations) the model used to arrive at its output? Even with perfect snapshots, if the model rewrites all tokens simultaneously, the algorithm that leads from noisy to clean is not a simple left-to-right chain. The paper’s case studies begin to map this algorithm by observing how token representations change across steps — e.g., seeing the same token appear in different positions at different times (smearing).
-
Opaque Serial Depth: A quantitative proxy for transparency. Count the number of serial operations (e.g., transformer blocks) that happen between two interpretable states. For autoregressive, each token output is interpretable, so depth = blocks per token. For diffusion, if we treat each denoising step’s latent as opaque, depth = steps × blocks per step. The token bottleneck makes each denoising step’s output interpretable, so depth simply becomes steps (compared to autoregressive’s token count). In their setup, this ratio drops from 28.6 to 1.1.
Framework Shift
Before (autoregressive):             After (diffusion with bottleneck):
[Input] -> [token_1] -> [token_2]    [noisy canvas] -> [denoise step 1] -> [bottleneck -> tokens]
          (transparent)                                (opaque latent)
                                           |
                                           v
                                     [denoise step 2] -> [bottleneck -> tokens]
                                           |
                                           v
                                     [final canvas] (interpretable after bottleneck)
One sentence: From single-step causal generation to multi-step iterative refinement with a learned decoder, the core shift is that we can recover stepwise interpretability by forcing the model to express its intermediate states through a token bottleneck, but the algorithm itself becomes inherently parallel and non-chronological.
Expert Assessment
Problem choice: Real gap. As diffusion language models enter production, understanding their internals is urgent. Prior interpretability work almost exclusively targeted autoregressive models. This paper fills that gap cleanly.
Method maturity: Clever hack (token bottleneck) rather than deep theoretical insight. It works but feels like a band-aid: you’re training an auxiliary decoder to expose what the model is “thinking”. Could there be a more principled way? Perhaps, but this is pragmatic. The case studies are exploratory and qualitative, not rigorous causal tests, which limits maturity.
Experimental integrity: Baselines are fair (Gemma 4, same token count). The opaque serial depth metric is reasonable. The monitorability experiment (downstream task usefulness) is a nice check. Red flag: the algorithmic transparency case studies lack intervention-based validation — they just show patterns, not causal arrows.
Writing quality: Clear structure. The decomposition of transparency is pedagogically strong. The weakest section is the case studies — they read more like observations than experiments. Adding causal tracing or logit lens-style analyses would have elevated the paper.
Verdict: Weak accept — timely problem, solid variable transparency result, but algorithmic transparency claims remain preliminary.
Takeaways
- Token bottleneck trick: When you need to inspect a latent-space model, train a small decoder to map intermediate latents to tokens. This can be done without hurting end performance and gives you immediate visibility.
- Non-chronological reasoning awareness: If you are debugging a diffusion LLM, don’t assume that earlier denoising steps hold the final interpretation of later tokens. Use attention or representation tracking to detect smearing.
- Monitorability comparison: For downstream tasks that only care about final outputs (e.g., classification using hidden states), diffusion models are as monitorable as autoregressive ones — no special adaptation needed.
论文: 2606.20560 作者: Joshua Engels, Callum McDougall, Bilal Chughtai, Janos Kramar, Senthoran Rajamanoharan, Cindy Wu, Arthur Conmy, Asic Q Chen, Jean Tarbouriech, Min Ma 分类: cs.LG, cs.AI
缺口
现有的LLM可解释性研究几乎全部集中在自回归模型上(例如Gemma),每个生成的token都是一个可检查的步骤。 但DiffusionGemma在连续潜空间中执行大量计算,跨越多个去噪步骤。 那么,缺乏离散token快照是否意味着扩散模型天生更难理解? 此前扩散模型的可解释性工作(如图像领域)侧重于特征可视化,而非重构token层面的算法推理。 本文首次将透明度分解为变量透明度和算法透明度,并提出了通过token瓶颈恢复变量透明度的具体方法。
[问题: 不透明序列深度是自回归模型的28.6倍]
    |
    v
[假设: 去噪步骤之间存在可解释的token状态]
    |
    v
[方法: 训练一个token瓶颈将潜变量映射为token序列; 并进行案例研究]
    |
    v
[证据: 变量透明度降至1.1倍; 算法层面发现涂抹、非时间顺序推理等新现象]
    |
    v
[结论: 变量透明度可修复; 算法透明度需要新工具]
增量
一句话: 本文之前,人们认为DiffusionGemma本质上是黑箱;本文之后,我们发现变量透明度可以恢复到接近自回归模型的水平,但算法透明度揭示了之前未知的推理模式,使得过程理解更加复杂。
核心机制
作者首先量化了”不透明序列深度”——即可解释状态之间发生的串行计算量。 直观上,DiffusionGemma的深度是Gemma 4的28.6倍,因为每个去噪步骤的潜变量不是一个离散token。 为了恢复可解释性,他们训练了一个”token瓶颈”:一个小的可学习映射,将每个去噪步骤的连续潜表示压缩为一个token序列。 这个瓶颈在最终输出目标上进行端到端训练(不影响下游性能),作为一个翻译器,强制模型以人类可读的形式暴露其中间状态。 一旦每个去噪步骤都有了对应的token序列,不透明序列深度就骤降至Gemma 4的1.1倍。
然而,算法透明度仍然困难。 在自回归模型中,token从左到右逐次预测,可以追踪因果链。 在扩散模型中,画布上的每个token预测都会在每个去噪步骤中改变,这使得模型可以实现分布式算法,改写早期决策。 为了探索这一点,作者进行了一系列可解释性案例研究——探查token表示如何随步骤演变,追踪注意力模式。 他们发现了定性新颖的现象:非时间顺序推理(一个token最终语义在其位置内容确定之前就已出现)、token和序列涂抹(一个token的信息在去噪过程中溢出到相邻位置)、以及中间上下文推理(模型在最终确定token之前对整个序列有部分解释)。
[输入: 噪声token画布]
    |
    v
[去噪步骤1: 潜变量 z_1]
    |
    +--token瓶颈--> [可解释token序列 T_1]   (变量透明度)
    |
    v
[去噪步骤2: 潜变量 z_2]
    |
    +--token瓶颈--> [可解释token序列 T_2]
    |
    v
[......继续......]
    |
    v
[最终干净token]
想象你在剪辑一部电影。原始的扩散过程是连续的帧流(潜向量)——太快了,看不清。token瓶颈就像是”关键帧提取器”:它挑选出代表性的帧,并给每帧中的主要物体打上标签。有了关键帧,你就能按场景理解故事了(变量透明度)。但实际的电影剪辑不是线性的:导演可能会在事件发生之前就展示角色的反应(非时间顺序推理),或把两个场景叠在一起(涂抹)。案例研究帮助我们暴露这些非常规的剪辑技巧。没有关键帧你什么都看不到;有了关键帧,你至少知道导演在做一些奇怪的事情,尽管不一定完全理解他是如何规划剪辑的。
关键概念
-
变量透明度:我们对模型某个时刻计算状态快照的理解程度。在自回归模型中,状态就是token序列——非常透明。在扩散模型中,状态是一个连续张量;可读性几乎为零。token瓶颈通过将张量转换为token序列来恢复可读性,给我们一个可以检查的快照。
-
算法透明度:我们能否重构模型得出最终输出的推理过程(操作序列)?即使有完美的快照,如果模型同时重写所有token,从噪声到干净状态的算法也不是简单的从左到右链条。本文的案例研究通过观察token表示在步骤间的变化开始绘制这一算法——例如,看到同一个token在不同时间出现在不同位置(涂抹)。
-
不透明序列深度:透明度的量化代理。计算两个可解释状态之间的串行操作数量(例如transformer块数)。对于自回归,每个token输出都是可解释的,因此深度 = 每个token的块数。对于扩散,如果我们将每个去噪步骤的潜状态视为不透明,深度 = 步骤数 × 每步块数。token瓶颈使每个去噪步骤的输出变得可解释,于是深度变成步骤数(与自回归的token数相当)。在他们的设置中,这个比率从28.6下降到1.1。
框架转变
之前(自回归模型):              之后(带瓶颈的扩散模型):
[输入] -> [token_1] -> [token_2]    [噪声画布] -> [去噪步骤1] -> [瓶颈 -> token序列]
          (透明)                                   (不透明潜变量)
                                         |
                                         v
                                   [去噪步骤2] -> [瓶颈 -> token序列]
                                         |
                                         v
                                   [最终画布](经过瓶颈后可解释)
一句话:从单步因果生成到带学习解码器的多步迭代细化,核心转变在于我们可以通过强制模型通过token瓶颈表达中间状态来恢复逐步可解释性,但算法本身变得本质并行且非时间顺序。
专家评审
选题眼光: 这是真缺口。随着扩散语言模型进入应用,理解其内部机制非常紧迫。之前的可解释性工作几乎只关注自回归模型。本文干净地填补了这一空白。
方法成熟度: 巧劲而非深层次理论洞察。token瓶颈是实用的hack,但感觉像创可贴:你训练一个辅助解码器来暴露模型的”想法”。有没有更原理性的方法?也许有,但本文的做法很务实。案例研究是探索性和定性的,不是严格的因果验证,限制了成熟度。
实验诚意: 基线公平(Gemma 4,相同token数量)。不透明序列深度指标合理。监控性实验(下游任务有用性)是一个不错的检验。值得警惕之处:算法透明度的案例研究缺乏基于干预的验证——它们只是展示了模式,没有因果箭头。
写作功力: 结构清晰。透明度的分解在教学方法上很强。最薄弱的环节是案例研究部分——它们读起来更像是观察而非实验。添加因果追踪或logit lens式分析会让论文提升一个档次。
判决: 弱接收 — 问题及时,变量透明度结果扎实,但算法透明度的主张仍属初步。
要点总结
- token瓶颈技巧:当你需要检查潜空间模型的中间状态时,训练一个小型解码器将中间潜变量映射为token。这可以在不损害最终性能的情况下进行,并立即提供可见性。
- 非时间顺序推理意识:如果你在调试扩散LLM,不要假设较早的去噪步骤持有后来token的最终解释。使用注意力或表示追踪来检测涂抹现象。
- 监控性对比:对于只关心最终输出的下游任务(例如使用隐藏状态进行分类),扩散模型和自回归模型的监控性相当——无需特殊适配。