Paper: 2604.25907 Authors: Chu-Cheng Lin, Eugene Ie Categories: cs.LG, cs.AI
The Gap
Reinforcement learning from verifiable rewards (RLVR) trains reasoning models by rewarding correct outputs. But when a model first encounters a new task where it almost never succeeds (low p₀), RLVR stalls—the model needs Ω(1/p₀) gradient steps just to escape this “cold start.” Supervised fine-tuning (SFT) on correct trajectories escapes faster but memorizes noise. No existing method smoothly trades off between these extremes.
Problem: RLVR stalls when p0 is small
   |
   v
Observation: RLVR (exploit) vs SFT (explore) differ in gradient amplification
   |
   v
Method: Tsallis q-log creates loss family J_Q interpolating between them
   |
   v
Evidence: GARL (q=0.75) escapes cold start; PAFT stabilizes warm start
   |
   v
Conclusion: Tunable q trades escape speed vs noise memorization
The Increment
One sentence: Before, you chose between RLVR (fast when warm, stuck when cold) or SFT (escapes cold but memorizes noise)—now you dial a knob q to get the right balance for your task’s temperature.
Core Mechanism
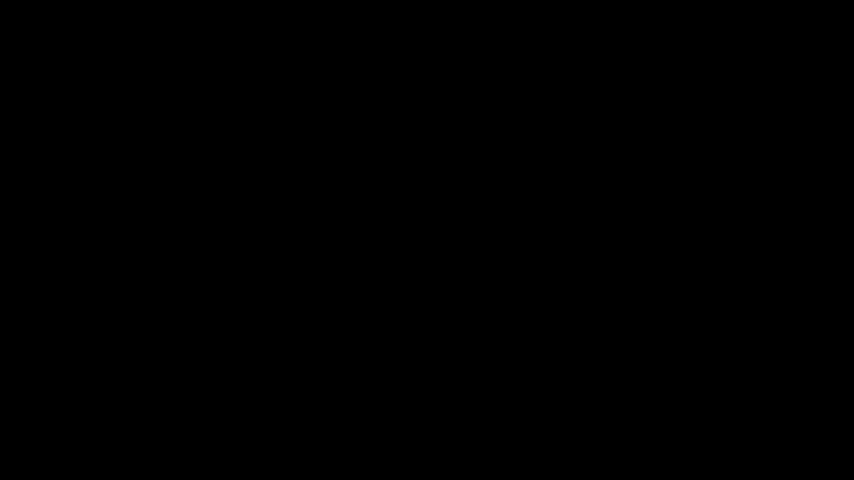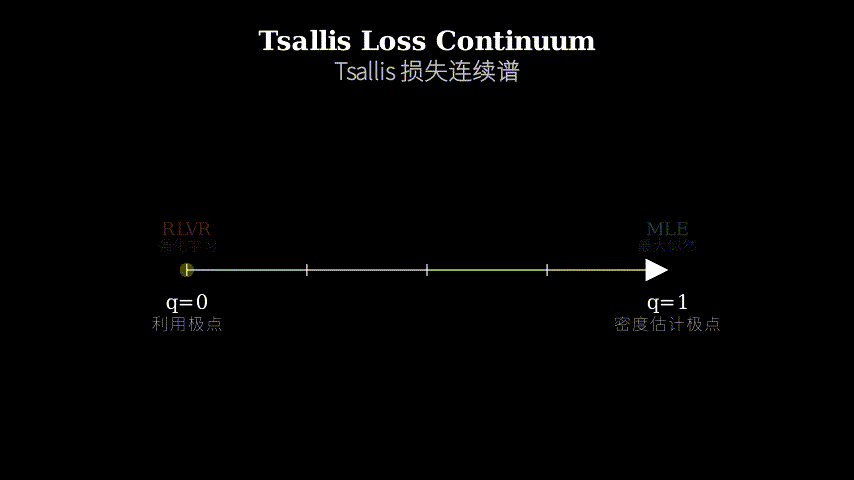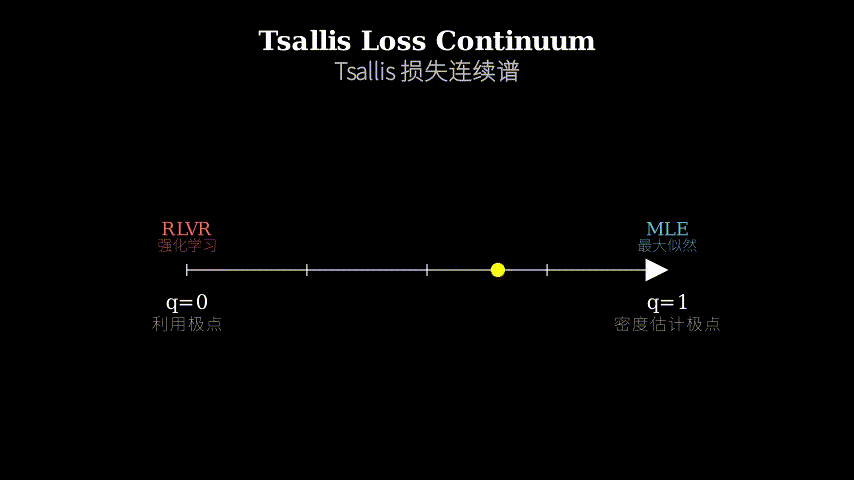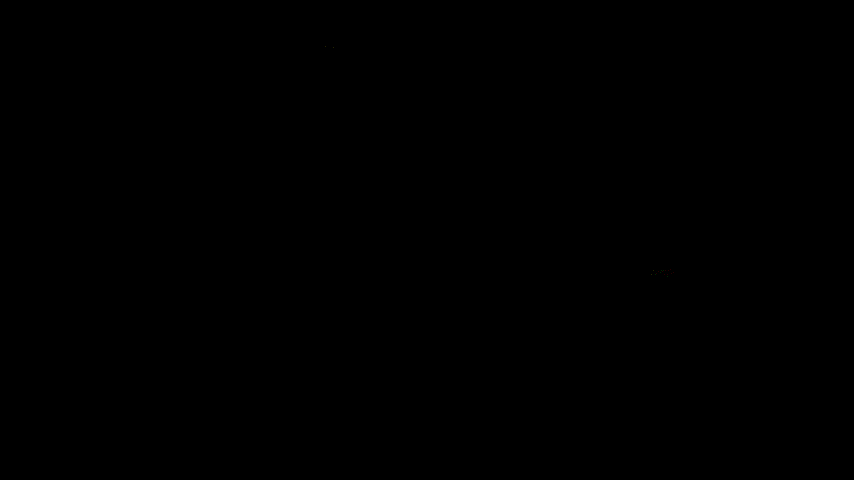
The paper defines a loss family J_Q using the Tsallis q-logarithm. At q=0, you get standard RLVR that only reinforces successful trajectories. At q=1, you get log-marginal-likelihood that considers all possible trajectories weighted by their probability. The key insight: all q values share the same gradient direction, differing only by a scalar amplification factor P_θ^(-q), where P_θ is the probability of generating any correct answer.
This amplification is what controls cold-start escape. Under gradient flow, RLVR (q=0) needs Ω(1/p₀) time to escape because it only learns from rare successes. The density-estimation pole (q=1) escapes in Θ(log(1/p₀)) time because it learns from all attempts. Intermediate q values smoothly interpolate this tradeoff.
Since P_θ is intractable (requires summing over all correct trajectories), the paper derives two Monte Carlo estimators. GARL samples from the prior distribution and amplifies the RL gradient by the estimated P_θ^(-q). PAFT importance-resamples from the posterior and runs standard SFT with attenuated gradients. Both have bias O(q/(M·P_θ^(q+1))) where M is sample size.
Input task with success probability p0
   |
   v
Choose q in [0,1]:  q=0 (exploit) <-----> q=1 (explore)
   |                    |                      |
   v                    v                      v
Compute gradient:   RLVR only          Considers all
direction same,     on successes       trajectories
amplification       |                  |
differs by P_θ^-q   |                  |
   |                v                  v
   +----------> Escape time:      Escape time:
                Ω(1/p0)            Θ(log(1/p0))
                     |                  |
                     v                  v
                Estimate P_θ with Monte Carlo
                     |
                     +---> GARL: sample from prior, amplify RL gradient
                     |
                     +---> PAFT: importance-sample from posterior, run SFT
Think of training a reasoning model like teaching someone to solve puzzles. RLVR is like only praising correct solutions—if they almost never get it right initially, they learn glacially slow. SFT is like showing them every attempt you made (including wrong ones) and saying “learn from all of this”—they improve faster but might memorize your specific mistakes.
The Tsallis loss is like having a dial on your teaching style. At q=0, you’re pure RLVR (only praise success). At q=1, you’re showing everything. At q=0.75, you’re mostly praising success but occasionally saying “here’s what I tried, notice the pattern.” The P_θ^(-q) amplification is the volume knob—when success is rare (small P_θ), turning up q automatically increases the learning signal without you manually adjusting the learning rate.
GARL and PAFT are two ways to implement this teaching style when you can’t actually observe all possible solution attempts. GARL says “let me try solving it myself a few times, then amplify the lesson based on how hard this problem is.” PAFT says “let me collect a bunch of my successful attempts, then teach you from those but downweight the lesson based on how easy they were to find.”
Key Concepts
-
Tsallis q-logarithm: A generalization of the natural logarithm with a parameter q. When q=1, it’s the regular log. When q=0, it becomes (x-1), which is the basis of standard RL rewards. The formula is log_q(x) = (x^(1-q) - 1)/(1-q). The key property: it creates a continuous family of functions that smoothly interpolate between different learning behaviors. Think of it like a dimmer switch for how much you care about rare events—regular log (q=1) cares a lot about everything, while q=0 only cares about what actually happened.
-
Gradient amplification: All members of the J_Q family produce gradients pointing in the same direction, but scaled by P_θ^(-q). This isn’t just a learning rate adjustment—it’s instance-specific reweighting. When P_θ is small (hard problem, model struggling), the amplification is large, automatically giving more learning signal. When P_θ is large (easy problem, model confident), amplification is small. This is why intermediate q values escape cold start faster than pure RLVR: they amplify the gradient more when the model needs it most, without requiring manual learning rate schedules.
-
Cold start vs warm start: Cold start means the model’s initial success probability p₀ is very small (say, 1% or less). The model is essentially guessing randomly and rarely stumbles on correct answers. Warm start means p₀ is reasonable (say, 20%+), so the model has some signal to learn from. The paper shows that RLVR’s Ω(1/p₀) escape time means if p₀=0.01, you need at least 100 gradient steps just to start making progress. With q=0.75, escape time drops to roughly Θ(log(100))≈5 steps. This isn’t just faster—it’s the difference between practical and impractical.
Framework Shift
Before (RLVR):                       After (Tsallis J_Q):

Only learn from success:             Learn from all attempts,
                                     weighted by q:
  [correct] ---> +reward
  [wrong]   ---> (ignored)             q=0: [correct] ---> +reward
                                              [wrong]   ---> (ignored)
Gradient:
  direction: toward success            q=0.5: [correct] ---> ++reward
  magnitude: fixed by LR                      [wrong]   ---> +small signal

Escape time: Ω(1/p0)                   q=1: [correct] ---> +++reward
                                              [wrong]   ---> ++signal
When p0=0.01:
  ~100 steps to escape                 Gradient:
                                         direction: same as RLVR
                                         magnitude: P_θ^-q * (LR)

                                       Escape time: Θ(log(1/p0))

                                       When p0=0.01, q=0.75:
                                         ~5 steps to escape
From binary feedback to continuous modulation, the core shift is automatic gradient amplification that responds to task difficulty without manual tuning.
Expert Assessment
Problem choice: Real gap. Cold-start stalling in RLVR is a known pain point in post-training reasoning models, especially as we push toward harder tasks. The paper doesn’t manufacture the problem—practitioners genuinely face the choice between RLVR (principled but slow) and SFT (fast but noisy). Positioning this as a continuum rather than a binary choice is the right framing.
Method maturity: Clever insight with solid theory. The Tsallis connection is elegant—it’s not just “let’s try mixing RLVR and SFT,” it’s a principled family with provable escape-time bounds. The two estimators (GARL/PAFT) show the authors thought through implementation. However, the bias term O(q/(M·P_θ^(q+1))) means you need large M when P_θ is small, which is exactly when you’re in cold start. The paper doesn’t deeply explore this chicken-and-egg problem.
Experimental integrity: Baselines are fair (GRPO is standard), but the experimental section reveals instability issues. GARL destabilizes on HotPotQA and MuSiQue during training—that’s a red flag the paper acknowledges but doesn’t fully resolve. The switch to PAFT for stability is pragmatic but suggests the method isn’t fully baked. Numbers are honest: they show where GRPO fails entirely (good) and where their method also struggles (also good). The maj@16 metric is appropriate for reasoning tasks.
Writing quality: The theory section (Tsallis loss, escape-time analysis) is excellent. The experimental section feels rushed—Figure 2 shows training curves but doesn’t explain why GARL destabilizes or how to predict when to use GARL vs PAFT. The paper would benefit from a decision tree: “Use GARL when X, use PAFT when Y.” The related work section is thin—doesn’t engage with recent work on process supervision or outcome-based RL variants.
Verdict: weak accept — Solid theoretical contribution with practical impact on cold-start problems, but experimental instability and incomplete guidance on when to use which estimator prevent this from being a strong accept.
Takeaways
Steal the amplification pattern: Even if you don’t use Tsallis loss, the idea of instance-specific gradient amplification based on task difficulty (P_θ^(-q)) transfers. If you’re training any model with sparse rewards, consider reweighting gradients by estimated success probability rather than using a fixed learning rate.
The q=0.75 heuristic: The paper consistently finds q=0.75 works well across tasks. This isn’t arbitrary—it’s roughly the point where you get 80% of the cold-start speedup with manageable noise. If you’re tuning a similar interpolation parameter, start there.
GARL for cold, PAFT for warm: The paper’s instability issues teach a lesson: aggressive gradient amplification (GARL) works when you’re desperate for signal (cold start), but once you have traction, you need semantic coherence (PAFT). This pattern likely applies beyond this specific method—early training wants quantity of signal, late training wants quality.
Don’t ignore the bias term: The O(q/(M·P_θ^(q+1))) bias means you need exponentially more samples as P_θ shrinks. If you’re adapting this, budget your compute accordingly—cold start is exactly when estimation is hardest.
论文: 2604.25907 作者: Chu-Cheng Lin, Eugene Ie 分类: cs.LG, cs.AI
缺口
可验证奖励强化学习(RLVR)通过奖励正确输出来训练推理模型。
但当模型首次遇到几乎从不成功的新任务(低 p₀)时,RLVR 会停滞——模型需要 Ω(1/p₀) 个梯度步才能逃离这种”冷启动”。
在正确轨迹上进行监督微调(SFT)逃离得更快,但会记住噪声。
现有方法无法在这两个极端之间平滑权衡。
问题:p0 很小时 RLVR 停滞
   |
   v
观察:RLVR(利用)vs SFT(探索)在梯度放大上不同
   |
   v
方法:Tsallis q-对数创建损失函数族 J_Q 在两者间插值
   |
   v
证据:GARL (q=0.75) 逃离冷启动;PAFT 稳定热启动
   |
   v
结论:可调 q 在逃离速度与噪声记忆间权衡
增量
一句话: 以前你要在 RLVR(热时快、冷时卡)和 SFT(逃离冷启动但记住噪声)之间二选一——现在你转动旋钮 q 就能为任务温度找到合适平衡。
核心机制
论文用 Tsallis q-对数定义了损失函数族 J_Q。
在 q=0 时,你得到标准 RLVR,只强化成功轨迹。
在 q=1 时,你得到对数边际似然,考虑所有可能轨迹并按概率加权。
关键洞察:所有 q 值共享相同的梯度方向,仅在标量放大因子 P_θ^(-q) 上不同,其中 P_θ 是生成任何正确答案的概率。
这个放大机制控制冷启动逃离。
在梯度流下,RLVR (q=0) 需要 Ω(1/p₀) 时间逃离,因为它只从罕见成功中学习。
密度估计极点 (q=1) 在 Θ(log(1/p₀)) 时间内逃离,因为它从所有尝试中学习。
中间 q 值平滑插值这种权衡。
由于 P_θ 难以计算(需要对所有正确轨迹求和),论文推导了两个蒙特卡洛估计器。
GARL 从先验分布采样并用估计的 P_θ^(-q) 放大 RL 梯度。
PAFT 从后验重要性重采样并运行标准 SFT,梯度衰减。
两者都有偏差 O(q/(M·P_θ^(q+1))),其中 M 是样本大小。
输入成功概率为 p0 的任务
   |
   v
选择 q ∈ [0,1]:  q=0 (利用) <-----> q=1 (探索)
   |                    |                      |
   v                    v                      v
计算梯度:          仅 RLVR              考虑所有
方向相同,          对成功               轨迹
放大因子            |                    |
因 P_θ^-q 不同      |                    |
   |                v                    v
   +----------> 逃离时间:            逃离时间:
                Ω(1/p0)              Θ(log(1/p0))
                     |                    |
                     v                    v
                用蒙特卡洛估计 P_θ
                     |
                     +---> GARL: 从先验采样,放大 RL 梯度
                     |
                     +---> PAFT: 从后验重要性采样,运行 SFT
把训练推理模型想象成教人解谜题。
RLVR 就像只表扬正确答案——如果他们最初几乎从不答对,学习会慢得像冰川。
SFT 就像展示你做的每次尝试(包括错的)并说”从这一切中学习”——他们进步更快但可能记住你的具体错误。
Tsallis 损失就像在教学风格上有个旋钮。
在 q=0 时,你是纯 RLVR(只表扬成功)。
在 q=1 时,你展示一切。
在 q=0.75 时,你主要表扬成功但偶尔说”这是我试过的,注意模式”。
P_θ^(-q) 放大是音量旋钮——当成功罕见(P_θ 小)时,调高 q 会自动增加学习信号,无需手动调整学习率。
GARL 和 PAFT 是两种实现这种教学风格的方法,当你实际上无法观察所有可能的解答尝试时。
GARL 说”让我自己试着解几次,然后根据这个问题有多难来放大教训”。
PAFT 说”让我收集一堆我的成功尝试,然后从中教你,但根据它们有多容易找到来降低教训的权重”。
关键概念
- Tsallis q-对数: 自然对数的推广,带参数 q。
当 q=1 时,它是常规对数。
当 q=0 时,它变成 (x-1),这是标准 RL 奖励的基础。
公式是 log_q(x) = (x^(1-q) - 1)/(1-q)。
关键性质:它创建了一个连续函数族,在不同学习行为间平滑插值。
把它想象成一个调光开关,控制你对罕见事件的关心程度——常规对数 (q=1) 非常关心一切,而 q=0 只关心实际发生的事。
- 梯度放大: J_Q 族的所有成员产生指向相同方向的梯度,但按 P_θ^(-q) 缩放。
这不只是学习率调整——它是实例特定的重新加权。
当 P_θ 小(难题,模型挣扎)时,放大很大,自动给出更多学习信号。
当 P_θ 大(简单题,模型自信)时,放大很小。
这就是为什么中间 q 值比纯 RLVR 更快逃离冷启动:它们在模型最需要时放大梯度更多,无需手动学习率调度。
- 冷启动 vs 热启动: 冷启动意味着模型的初始成功概率 p₀ 非常小(比如 1% 或更少)。
模型基本上在随机猜测,很少偶然找到正确答案。
热启动意味着 p₀ 合理(比如 20%+),所以模型有一些信号可学。
论文表明 RLVR 的 Ω(1/p₀) 逃离时间意味着如果 p₀=0.01,你至少需要 100 个梯度步才能开始取得进展。
用 q=0.75,逃离时间降到大约 Θ(log(100))≈5 步。
这不只是更快——这是实用与不实用的区别。
框架转变
之前(RLVR):                      之后(Tsallis J_Q):

只从成功中学习:                     从所有尝试中学习,
                                     按 q 加权:
  [正确] ---> +奖励
  [错误] ---> (忽略)                  q=0: [正确] ---> +奖励
                                             [错误] ---> (忽略)
梯度:
  方向:朝向成功                       q=0.5: [正确] ---> ++奖励
  幅度:由学习率固定                          [错误] ---> +小信号

逃离时间:Ω(1/p0)                     q=1: [正确] ---> +++奖励
                                             [错误] ---> ++信号
当 p0=0.01 时:
  ~100 步逃离                          梯度:
                                         方向:与 RLVR 相同
                                         幅度:P_θ^-q * (学习率)

                                       逃离时间:Θ(log(1/p0))

                                       当 p0=0.01, q=0.75 时:
                                         ~5 步逃离
从二元反馈到连续调制,核心转变是自动梯度放大,响应任务难度而无需手动调优。
专家评审
选题眼光: 真实缺口。
RLVR 中的冷启动停滞是后训练推理模型中的已知痛点,尤其是当我们推向更难任务时。
论文没有制造问题——实践者确实面临 RLVR(原则性但慢)和 SFT(快但有噪声)之间的选择。
将其定位为连续统而非二元选择是正确的框架。
方法成熟度: 巧妙洞察加扎实理论。
Tsallis 连接很优雅——这不只是”让我们试试混合 RLVR 和 SFT”,而是一个有可证明逃离时间界的原则性函数族。
两个估计器(GARL/PAFT)表明作者考虑了实现。
然而,偏差项 O(q/(M·P_θ^(q+1))) 意味着当 P_θ 小时你需要大 M,而这正是你处于冷启动时。
论文没有深入探讨这个先有鸡还是先有蛋的问题。
实验诚意: 基线公平(GRPO 是标准),但实验部分揭示了不稳定性问题。
GARL 在 HotPotQA 和 MuSiQue 上训练期间不稳定——这是论文承认但未完全解决的危险信号。
为稳定性切换到 PAFT 是务实的,但表明方法还不够成熟。
数字是诚实的:它们展示了 GRPO 完全失败的地方(好)以及他们的方法也挣扎的地方(也好)。
maj@16 指标适合推理任务。
写作功力: 理论部分(Tsallis 损失、逃离时间分析)很出色。
实验部分感觉仓促——图 2 显示训练曲线但没有解释为什么 GARL 不稳定或如何预测何时使用 GARL vs PAFT。
论文会受益于决策树:“当 X 时使用 GARL,当 Y 时使用 PAFT”。
相关工作部分很薄——没有与最近关于过程监督或基于结果的 RL 变体的工作交流。
判决: 弱接收 — 扎实的理论贡献对冷启动问题有实际影响,但实验不稳定性和关于何时使用哪个估计器的不完整指导阻止这成为强接收。
要点总结
偷走放大模式: 即使你不用 Tsallis 损失,基于任务难度(P_θ^(-q))的实例特定梯度放大想法也能迁移。
如果你在训练任何有稀疏奖励的模型,考虑按估计成功概率重新加权梯度,而不是使用固定学习率。
q=0.75 启发式: 论文一致发现 q=0.75 在各任务上效果好。
这不是任意的——它大致是你获得 80% 冷启动加速且噪声可管理的点。
如果你在调优类似的插值参数,从那里开始。
冷用 GARL,热用 PAFT: 论文的不稳定性问题教了一课:激进的梯度放大(GARL)在你迫切需要信号(冷启动)时有效,但一旦你有了牵引力,你需要语义连贯性(PAFT)。
这种模式可能适用于这个特定方法之外——早期训练想要信号的数量,后期训练想要质量。
别忽略偏差项: O(q/(M·P_θ^(q+1))) 偏差意味着随着 P_θ 缩小你需要指数级更多样本。
如果你在改编这个,相应地预算你的计算——冷启动正是估计最难的时候。