Paper: 2604.15294 Authors: Zhen Yang, Ping Jian, Zhongbin Guo, Zuming Zhang, Chengzhi Li, Yonghong Deng, Xinyue Zhang, Wenpeng Lu Categories: cs.AI
The Gap
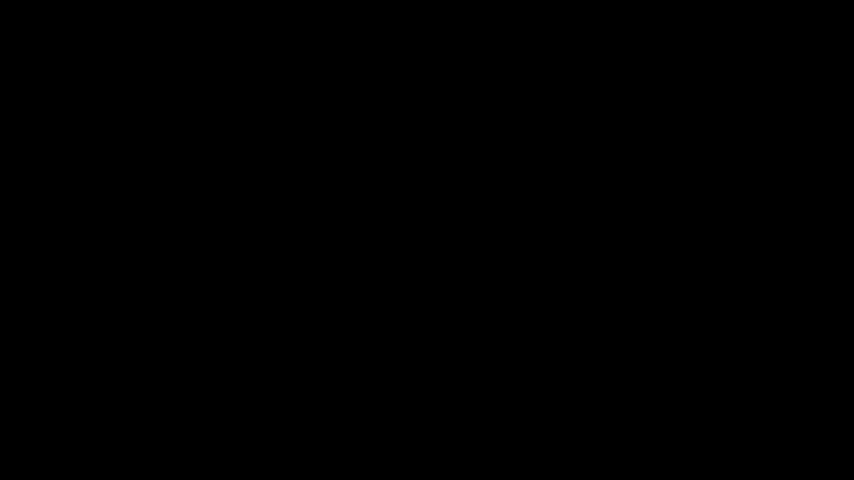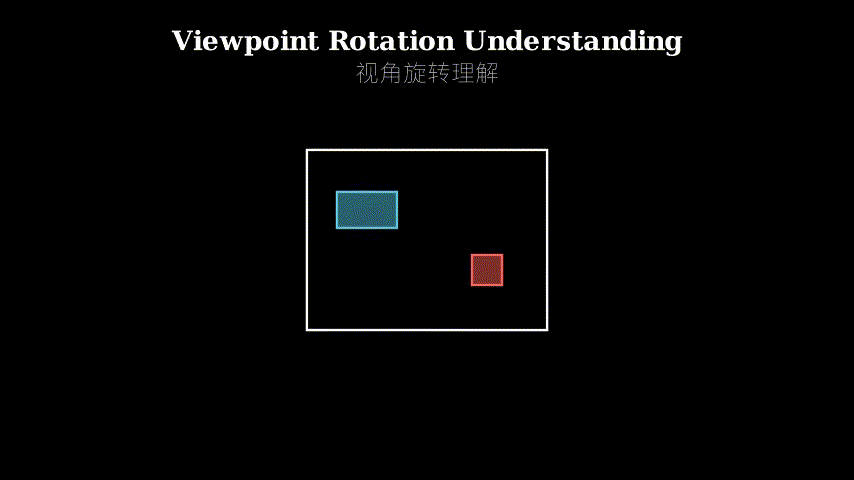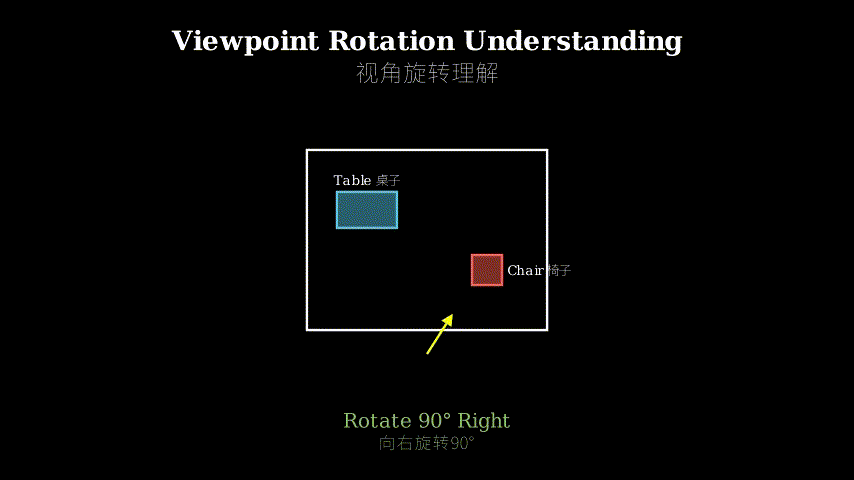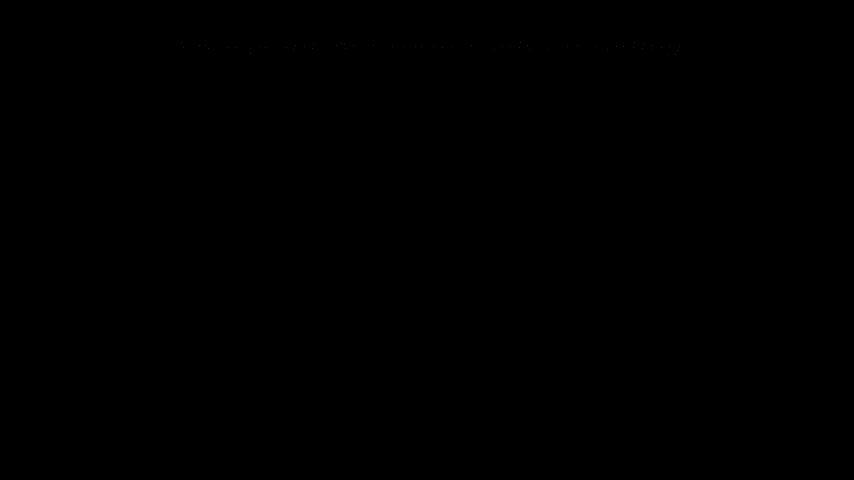
Spatial intelligence research has focused on visual-spatial tasks where models see images. But what about pure linguistic spatial reasoning? Prior work assumes vision is necessary for spatial understanding, leaving unexplored whether language alone suffices. This paper targets viewpoint rotation understanding (VRU)—a fundamental capability where you track your orientation and predict what you’d see after turning, using only text descriptions.
Problem: Spatial intelligence studied only with vision
         |
         v
Assumption: Language alone might encode spatial reasoning
         |
         v
Method: VRU task + layer-wise probing + head intervention
         |
         v
Evidence: Models encode position but fail binding
         |
         v
Conclusion: Selective fine-tuning fixes key attention heads
The Increment
One sentence: Before—we assumed spatial reasoning needs vision; after—we know LLMs encode spatial position but hallucinate because they can’t bind position to observation.
Core Mechanism
The method has three stages. First, create a VRU dataset where models read text like “you’re facing north, you see a tree; turn 90° right, you see a house” and must predict final viewpoint and observation. Second, probe each transformer layer to see if hidden states contain viewpoint information (they do). Third, systematically ablate attention heads to find which ones are causally responsible for VRU performance, then selectively fine-tune only those heads.
Input text sequence
    |
    v
[Layer 1] --probe--> viewpoint info present?
[Layer 2] --probe--> viewpoint info present?
    ...
[Layer N] --probe--> viewpoint info present?
    |
    v
Attention heads --ablate--> find causal heads
    |
    v
Fine-tune only causal heads --> improved VRU
Think of it like debugging a GPS navigation system. The GPS receives turn-by-turn instructions (text input), internally tracks your position (hidden states encode viewpoint), but displays the wrong street view (fails to bind position to observation). You run diagnostics on each circuit board (layer probing) and find the position tracker works fine. Then you test each wire connection (attention head ablation) to find which ones misroute the signal between position tracker and display. Finally, you resolder only those specific connections (selective fine-tuning) without touching the rest of the working system.
Key Concepts
-
Viewpoint Rotation Understanding (VRU): Imagine you’re blindfolded in a room. Someone tells you “there’s a chair in front of you, now turn 90° left, there’s a table in front of you.” Can you track where you’re facing and what you’d see? That’s VRU. It’s the ability to maintain a mental model of orientation and environment through sequential textual descriptions of rotations and observations. Humans do this effortlessly; models struggle because they must integrate rotation commands with spatial memory without visual anchors.
-
Layer-wise Probing: You train a simple classifier on each layer’s hidden states to predict viewpoint. If the classifier succeeds, that layer “knows” the viewpoint. It’s like checking each floor of a building to see if the information you need is stored there. The probe doesn’t change the model—it just reads what’s already encoded. This reveals where in the network spatial information lives.
-
Head-wise Causal Intervention: Attention heads are like specialized processors. You systematically disable each one and measure performance drop. Big drop = that head is critical. It’s A/B testing at the neuron level. Unlike correlation (probing), this establishes causation: “this specific head is responsible for binding viewpoint to observation.” Then you can surgically fix just that component.
Framework Shift
Before (mainstream approach):        After (this paper):

Visual input required                Text-only input
     |                                    |
     v                                    v
Spatial reasoning                    Spatial reasoning
     |                                    |
     v                                    v
Black box evaluation                 Mechanistic diagnosis
                                          |
                                          +---> Probing
                                          +---> Intervention
                                          +---> Targeted repair
From “spatial intelligence needs vision” to “language encodes space but fails at binding,” the core shift is treating spatial reasoning as a dissectable cognitive process rather than a monolithic capability.
Expert Assessment
Problem choice: Real gap. Spatial intelligence is hot, but everyone’s throwing images at models. Testing pure linguistic spatial reasoning is overdue and reveals a fundamental limitation. It sits at the intersection of spatial AI and interpretability—both active areas.
Method maturity: The probing and intervention pipeline is standard interpretability toolkit, not novel. But applying it to spatial reasoning is clever. The selective fine-tuning is the only methodological contribution, and it’s incremental. They could’ve explored why binding fails more deeply—maybe attention patterns, maybe positional encodings.
Experimental integrity: Baselines are fair (GPT-4, Claude, Gemini, LLaVA). The 100% human accuracy vs <50% model accuracy is stark. But the dataset is small-scale and synthetic. Real-world spatial language is messier. The fine-tuning experiments lack ablations on how many heads to tune or what happens with different learning rates.
Writing quality: The interpretability analysis (Section 4) is dense and could use more intuition-building. The related work undersells how much prior work exists on spatial reasoning in NLP. The conclusion oversells the fix—selective fine-tuning helps but doesn’t close the gap to human performance.
Verdict: weak accept — Solid diagnostic work on an underexplored problem, but the fix is incremental and the dataset is limited.
Takeaways
Steal the diagnostic pipeline: probe layers to confirm information is encoded, then ablate components to find where processing fails. This two-step “encoding vs. processing” distinction applies beyond spatial reasoning—use it for any task where models have the knowledge but produce wrong outputs. The selective fine-tuning idea is practical: if you identify 5-10 critical attention heads via intervention, you can fix specific failures without full retraining. Also, the VRU task itself is a clean benchmark for spatial reasoning that doesn’t require vision—useful for testing pure language models.
论文: 2604.15294 作者: Zhen Yang, Ping Jian, Zhongbin Guo, Zuming Zhang, Chengzhi Li, Yonghong Deng, Xinyue Zhang, Wenpeng Lu 分类: cs.AI
缺口
空间智能研究一直聚焦于视觉-空间任务,模型需要看到图像。
但纯语言的空间推理呢?
先前工作假设视觉是空间理解的必要条件,未曾探索语言本身是否足够。
本文针对视角旋转理解(VRU)——一种基础能力,你需要仅通过文本描述追踪自己的朝向并预测转身后会看到什么。
问题:空间智能研究仅依赖视觉
         |
         v
假设:语言本身可能编码空间推理
         |
         v
方法:VRU任务 + 逐层探针 + 注意力头干预
         |
         v
证据:模型编码位置但绑定失败
         |
         v
结论:选择性微调修复关键注意力头
增量
一句话: 之前——我们以为空间推理需要视觉;
现在——我们知道大语言模型能编码空间位置但因无法将位置与观察绑定而产生幻觉。
核心机制
方法分三个阶段。
首先,创建VRU数据集,模型读取文本如”你面朝北,看到一棵树;
向右转90°,看到一座房子”,必须预测最终视角和观察。
其次,探测每个Transformer层,看隐藏状态是否包含视角信息(确实包含)。
第三,系统性地消融注意力头,找出哪些对VRU性能有因果作用,然后仅选择性微调这些头。
输入文本序列
    |
    v
[第1层] --探针--> 视角信息存在?
[第2层] --探针--> 视角信息存在?
    ...
[第N层] --探针--> 视角信息存在?
    |
    v
注意力头 --消融--> 找到因果头
    |
    v
仅微调因果头 --> VRU性能提升
把它想象成调试GPS导航系统。
GPS接收逐步指令(文本输入),内部追踪你的位置(隐藏状态编码视角),但显示错误的街景(无法将位置与观察绑定)。
你对每块电路板运行诊断(逐层探针),发现位置追踪器工作正常。
然后测试每根线路连接(注意力头消融),找出哪些将位置追踪器和显示器之间的信号误导了。
最后,你只重新焊接那些特定连接(选择性微调),不触碰系统其余正常工作的部分。
关键概念
- 视角旋转理解(VRU): 想象你被蒙住眼睛站在房间里。
有人告诉你”你前面有把椅子,现在向左转90°,你前面有张桌子。
“你能追踪自己面朝哪里、会看到什么吗?
这就是VRU。
它是通过连续的旋转和观察文本描述维持方向和环境心理模型的能力。
人类毫不费力就能做到;
模型挣扎是因为它们必须在没有视觉锚点的情况下整合旋转命令和空间记忆。
- 逐层探针: 你在每层的隐藏状态上训练一个简单分类器来预测视角。
如果分类器成功,那层就”知道”视角。
就像检查大楼的每一层,看你需要的信息是否存储在那里。
探针不改变模型——它只读取已经编码的内容。
这揭示了空间信息在网络中的位置。
- 注意力头因果干预: 注意力头像专用处理器。
你系统性地禁用每一个,测量性能下降。
下降大=该头至关重要。
这是神经元级别的A/B测试。
与相关性(探针)不同,这建立因果关系:“这个特定的头负责将视角与观察绑定。
“然后你可以精准修复那个组件。
框架转变
之前(主流方法):                之后(本文方法):

需要视觉输入                      仅文本输入
     |                                |
     v                                v
空间推理                          空间推理
     |                                |
     v                                v
黑盒评估                          机制诊断
                                      |
                                      +---> 探针
                                      +---> 干预
                                      +---> 定向修复
从”空间智能需要视觉”到”语言编码空间但绑定失败”,核心转变是将空间推理视为可解剖的认知过程,而非单一能力。
专家评审
选题眼光: 真实缺口。
空间智能很热,但所有人都在给模型喂图像。
测试纯语言空间推理早该做了,揭示了一个基础局限。
它处于空间AI和可解释性的交叉点——两个都是活跃领域。
方法成熟度: 探针和干预流程是标准可解释性工具包,不新颖。
但应用到空间推理上很巧妙。
选择性微调是唯一的方法贡献,而且是增量式的。
他们本可以更深入探索绑定为何失败——也许是注意力模式,也许是位置编码。
实验诚意: 基线公平(GPT-4、Claude、Gemini、LLaVA)。
人类100%准确率 vs 模型<50%准确率对比鲜明。
但数据集小规模且合成。
真实世界的空间语言更混乱。
微调实验缺少对调多少头或不同学习率会怎样的消融。
写作功力: 可解释性分析(第4节)密集,需要更多直觉构建。
相关工作低估了NLP中空间推理的先前工作量。
结论夸大了修复效果——选择性微调有帮助但未缩小与人类性能的差距。
判决: 弱接收 — 对未充分探索问题的扎实诊断工作,但修复是增量式的,数据集有限。
要点总结
偷走诊断流程:探测层以确认信息已编码,然后消融组件找出处理失败的位置。
这种”编码 vs 处理”的两步区分超越空间推理——用于任何模型有知识但产生错误输出的任务。
选择性微调想法很实用:如果你通过干预识别出5-10个关键注意力头,可以修复特定失败而无需完全重训。
此外,VRU任务本身是不需要视觉的空间推理清晰基准——对测试纯语言模型有用。