Paper: 2606.17043 Authors: Tongyan Fang, Siyuan Huang, Naiyu Fang, Ganlong Zhao, Zhongjin Luo, Jianbo Liu, Xiaogang Wang, Ying Dong, Hongsheng Li Categories: cs.RO, cs.LG
The Gap
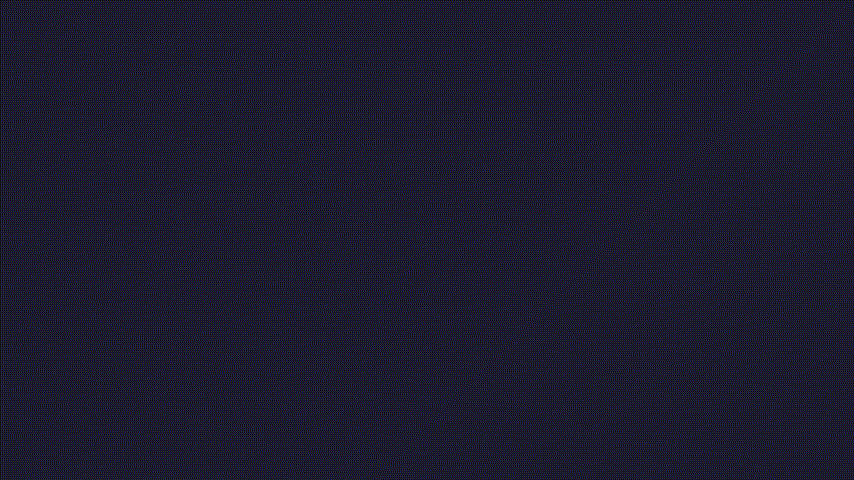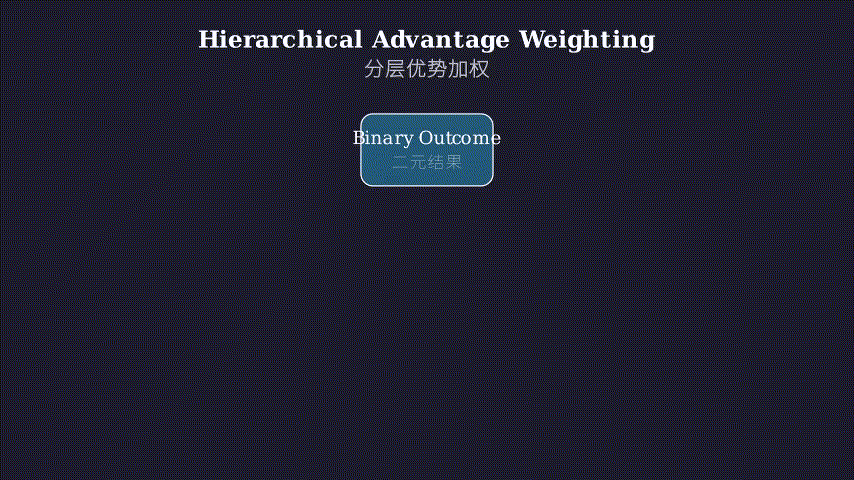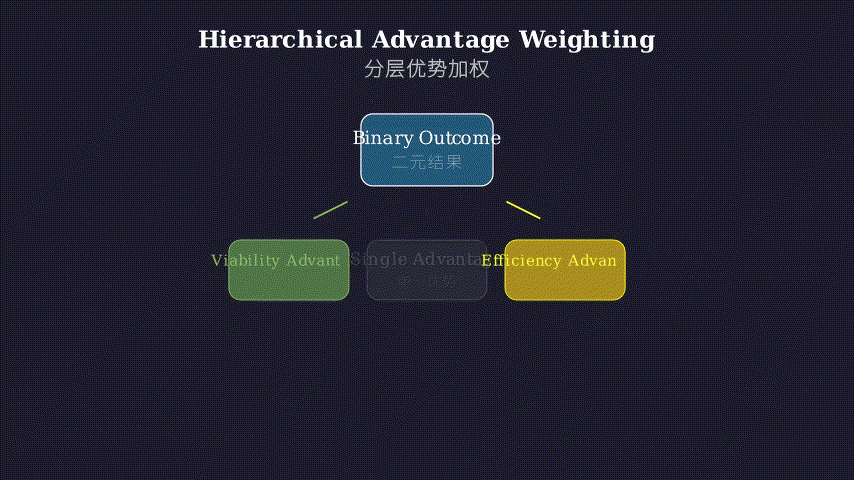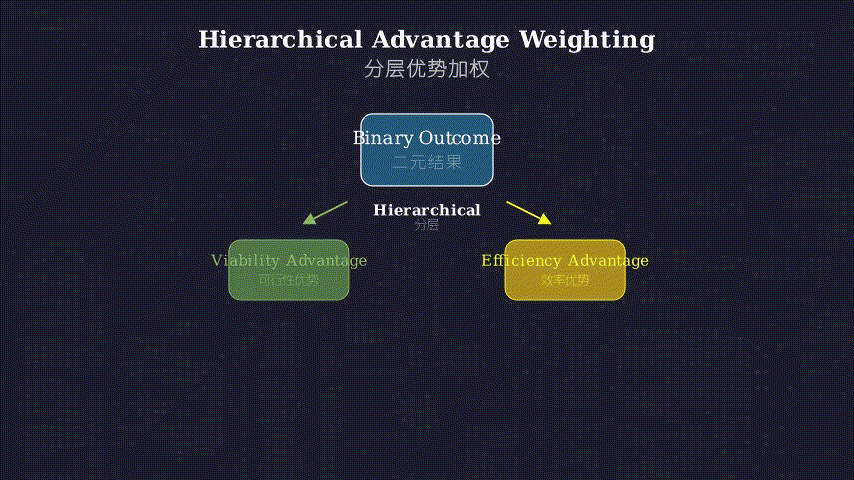
Most prior work fine-tunes pretrained VLA policies by compressing the single binary outcome (success/failure) of each episode into a scalar reward or advantage and applying it uniformly across all timesteps. This conflates two distinct objectives: viability (can the task be completed at all?) and efficiency (how fast is the completion?). Once the policy achieves basic success, the binary label provides no gradient to distinguish quick completions from slow ones. Additionally, real-world rollouts mix autonomous segments with human intervention segments; naively assigning the episode outcome to all transitions corrupts credit assignment across these boundaries. Methods like Advantage Weighted Regression (AWR) or simple reward shaping ignore this hierarchical structure entirely.
The gap is: a method that can extract separate supervision for viability and efficiency from a single binary label, while correctly handling intervention-contaminated data.
Problem: Sparse binary outcome conflates viability & efficiency, ignores intervention boundaries
     |
     v
Assumption: Two critics can be trained on different data subsets (autonomous segments only for efficiency)
     |
     v
Method: HABC = dual critics + state-adaptive gate + intervention-aware credit
     |
     v
Evidence: Real robot bimanual tasks: success jumps from 36%/44%/12% to 92%/88%/38%
     |
     v
Conclusion: Separating objectives and explicitly modeling intervention boundaries yields large gains
The Increment
One sentence: Before this paper, fine-tuning from sparse outcomes treated all transitions uniformly and conflated viability with efficiency; after this paper, the actor receives per-transition weights that adaptively prioritize viability or efficiency via two separate critics, and only autonomous segments contribute to training.
Core Mechanism
HABC trains two independent critics. The viability critic is trained only on autonomous segments (no human intervention) using the episode’s final binary outcome as the target. The efficiency critic is trained only on autonomous segments from successful episodes, using completion time (negative step count) as the reward. Each critic yields a one-step advantage: and . A state-adaptive gate blends them: . When success is uncertain, is high and viability dominates; once success is likely, the gate shifts toward efficiency. The combined advantage is exponentiated to produce per-transition weights for the behavior cloning loss on the actor.
Intervention-aware credit assignment further excludes any transitions belonging to human intervention segments from both critic and actor updates, preventing the episode outcome from leaking across the autonomous/intervention boundary.
Data flow: rollout -> segment into auto/inter -> label each auto segment by final outcome -> compute advantages on auto segments only -> gate merge -> weight actor loss.
         +------------------+
         |  Rollout Buffer   |
         +--------+---------+
                  |
          +-------v-------+
          | Segment into   |
          | auto & inter   |
          +-------+-------+
                  |
        +---------+---------+
        |                   |
  +-----v-----+       +-----v-----+
  | Auto segs  |       | Inter segs |
  +-----+-----+       +-----+-----+
        |                   (discarded)
  +-----v-----+
  | Label by   |
  | final res  |
  +-----+-----+
        |
  +-----v-----+
  | Viability  |      +-------------+
  | critic V_v |<-----| Auto segs   |
  +-----+-----+      | (all)       |
        |            +-------------+
  +-----v-----+
  | Efficiency |      +-------------+
  | critic V_e |<-----| Success auto|
  +-----+-----+      | segs only   |
        |            +-------------+
  +-----v-----+
  | State gate g_t|-- merge A_v and A_e
  +-----+-----+
        |
  +-----v-----+
  | Combined A |
  +-----+-----+
        |
  +-----v-----+
  | Weighted BC|
  | actor loss  |
  +------------+
Structural metaphor: Think of a restaurant kitchen. Chef A (viability critic) cares only whether the main dish is cooked correctly (not burnt, flavour balanced). He judges each step based on the final outcome (success/failure) and only observes his own actions (autonomous segments), ignoring the sous-chef’s interventions. Chef B (efficiency critic) cares only about speed and judges only successful dishes (because failed dishes have no speed measure). The head chef (state-adaptive gate) decides moment-to-moment: if the dish might fail, listen to Chef A; if it’s already on track, listen to Chef B for faster service. The junior cook (actor) adjusts her technique based on the head chef’s blended feedback. Each role maps directly: chef A = viability critic, chef B = efficiency critic, head chef = gate, junior cook = actor, intervention = sous-chef stepping in (ignored).
Key Concepts
-
Objective conflating: When a single scalar reward is used, signals from different goals (viability, efficiency) are summed. A slow successful trajectory still gets positive reward, but no better than a fast one. This makes the policy ignore efficiency after basic success. HABC separates the two objectives into independent critics and uses a gate to balance them per state.
-
Intervention-aware credit assignment: In real robot training, a human operator may take over when the robot makes a mistake. Naive methods assign the episode’s outcome to all timesteps, including the human’s actions. If the human saves a failing episode, the policy learns to mimic human behaviour rather than correct its own. HABC restricts outcome labels to autonomous segments only, avoiding this contamination.
Framework Shift
Before (mainstream approach):        After (this paper):
+--------+     +--------+           +--------+     +----------+
| Sparse | --> | Single |           | Sparse | --> | Dual Adv |
| binary |     | Adv    |           | binary |     | (V+E)    |
+--------+     +--------+           +--------+     +----------+
                     |                                |
              +------v------+                  +------v------+
              | Weighted BC |                  | Gated weight|
              | all steps   |                  | auto only   |
              +-------------+                  +-------------+
                                       +-------------------+
                                       | Intervention-aware |
                                       | filtering         |
                                       +-------------------+
One sentence: From a single scalar advantage applied uniformly across all transitions to two separate advantages adaptively blended per state with explicit exclusion of intervention segments, the core shift is disentangling objectives and temporal credit.
Expert Assessment
Problem choice: Real gap. Fine-tuning VLAs from sparse binary feedback is a common practical challenge. The field has ignored both the viability/efficiency distinction and the intervention boundary problem. This paper targets a genuine weakness in current offline-to-online pipelines.
Method maturity: Clever but not radical. Training two critics and an adaptive gate is a sensible engineering solution, not a theoretical breakthrough. The intervention-aware filtering is the most practically valuable piece. Simpler approaches (e.g., using success-region time as a reward for a single critic) might work too, but the gate likely adds robustness. Overall moderate maturity.
Experimental integrity: Only SFT baselines are reported in the abstract. For a fair assessment, comparisons against AWR, IQL, and standard reward shaping are needed. The absolute gains (36% -> 92%, etc.) are large, but only three tasks are shown, and no variance or multiple seeds are mentioned. The hardest task (12% to 38%) still has low absolute success, which may indicate fundamental difficulty rather than method weakness. Task definitions are not given in the abstract, so reproducibility is uncertain.
Writing quality: The abstract is clear and focused. However, without reading the full paper, it’s hard to judge whether the method details (gate network architecture, critic training stability) are sufficiently described. The “SFT baseline” is weak; a longer paper should include more baselines and ablations.
Verdict: Weak accept — addresses a real problem with a reasonable design, but experimental scope is limited and novelty is moderate. Worth attention for practitioners, not for theorists.
Takeaways
- For any RL fine-tuning with sparse binary feedback, consider splitting viability and efficiency into separate critics. It’s a cheap addition that can give clearer gradients.
- Always isolate autonomous segments when human intervention exists. Failing to do so pollutes the credit assignment and can mislead the policy.
- A state-adaptive gate is a simple and effective fusion strategy that can be reused in other multi-objective learning contexts.
- You can train two critics from a single binary label by using different data subsets (all auto segs vs. only successful auto segs). This trick generalizes.
论文: 2606.17043 作者: Tongyan Fang, Siyuan Huang, Naiyu Fang, Ganlong Zhao, Zhongjin Luo, Jianbo Liu, Xiaogang Wang, Ying Dong, Hongsheng Li 分类: cs.RO, cs.LG
缺口
大多数现有工作将每个回合的单个二元结果(成功/失败)压缩为标量奖励或优势,并统一应用到所有时间步上。 这混淆了两个不同的目标:生存能力(能否完成任务)和效率(完成速度)。 一旦策略学会基本成功,二元标签就无法提供区分快速完成和慢速完成的梯度。 此外,真实场景的 rollout 混合了自主段和人类干预段,天真的将回合结果分配到所有过渡会跨边界引入错误的信用分配。 Advantage Weighted Regression (AWR) 和简单的奖励塑造方法完全忽略了这一层次结构。
本论文要填补的缺口是:需要一种方法,能从单个二元标签中提取针对生存能力和效率的独立监督