Paper: 2604.28196 Authors: Xin Zhou, Dingkang Liang, Xiwu Chen, Feiyang Tan, Dingyuan Zhang, Hengshuang Zhao, Xiang Bai Categories: cs.CV
The Gap
Existing driving world models split into two camps. One camp (like UniAD, VAD) focuses on future scene generation—predicting where objects will be—but treats the present as a black box. They simulate forward in time but can’t answer “what is that object?” or “why did it move there?” The other camp uses Large Language Models for reasoning about scenes, but LLMs live in text space. They can tell you “the pedestrian might cross” but can’t predict the actual 3D trajectory or geometry evolution. You get either physics without semantics or semantics without physics.
The core problem: understanding (what/why) and prediction (where/when) require different representations. Scene understanding wants high-level semantic features compatible with language models. Future prediction needs dense geometric representations that capture spatial structure. Prior work treats these as separate tasks with separate models.
Problem: Semantic reasoning <--gap--> Geometric prediction
         (LLM space)                   (3D space)
            |                              |
            v                              v
Assumption: Can we unify them in one model?
            |
            v
Method: Shared BEV backbone + dual branches
        + knowledge transfer + temporal bridge
            |
            v
Evidence: Outperforms specialists on both tasks
          (nuScenes, Waymo benchmarks)
            |
            v
Conclusion: Unified model > separate models
            (synergy between understanding & prediction)
The Increment
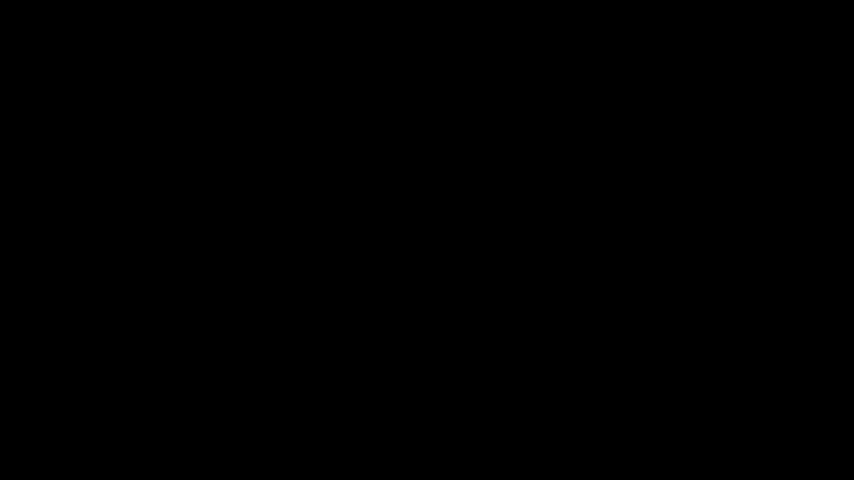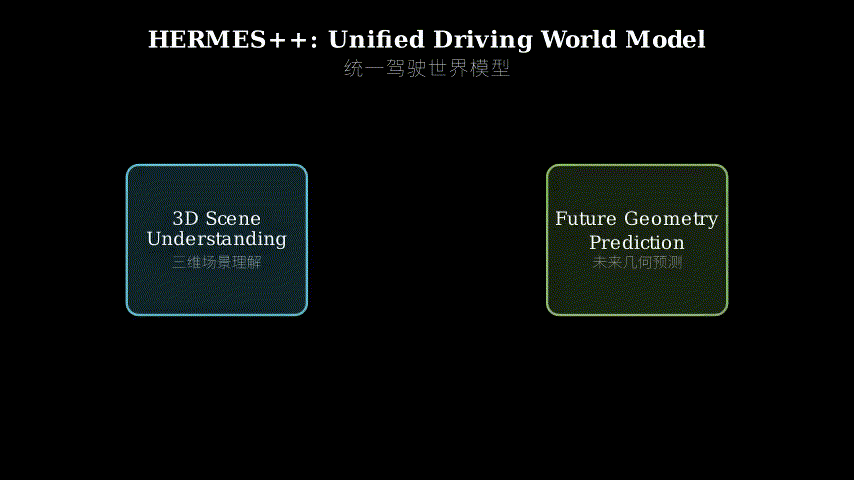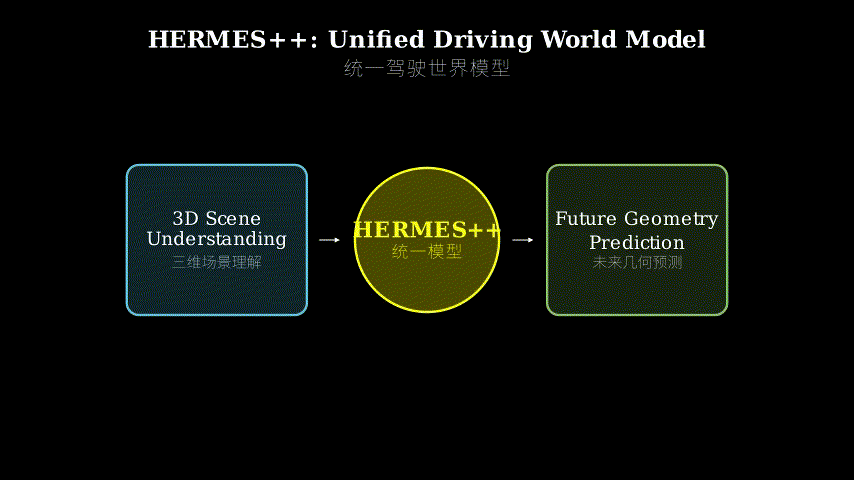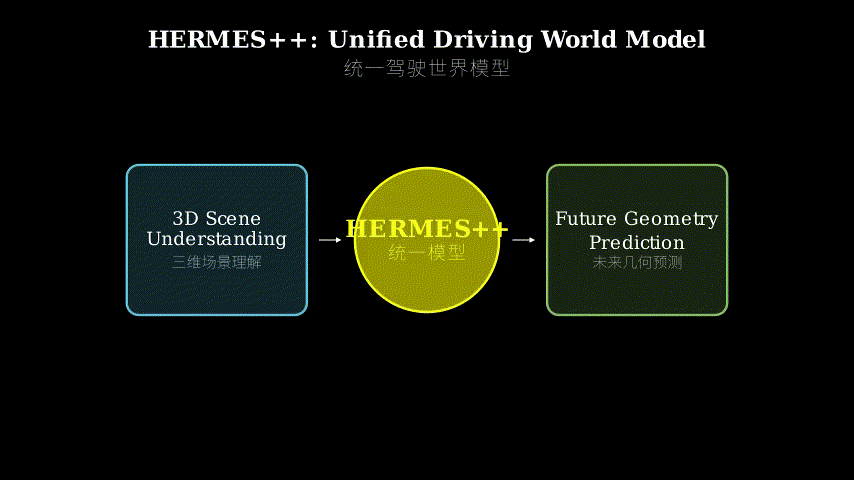
One sentence: Before HERMES++, you needed separate models for “what’s in the scene” and “where things will go”—now one model does both by making LLM reasoning guide geometric prediction.
Core Mechanism
The architecture has three main components working in sequence. First, a BEV (bird’s-eye view) encoder processes multi-view camera images and converts them into a unified spatial representation—think of it as creating a top-down map from multiple camera angles. This BEV representation is crucial because it’s structured enough for geometric operations but also compatible with language model processing.
Second, the model splits into two branches that share this BEV backbone. The understanding branch uses LLM-enhanced world queries—learnable tokens that extract semantic information and pass through a language model to get high-level scene interpretation. The prediction branch takes the same BEV features but processes them through a different path focused on geometric evolution. Here’s the clever part: the understanding branch’s output (semantic context) gets injected into the prediction branch through a “Current-to-Future Link” module. This is where semantic reasoning guides geometric prediction.
Third, to keep the predicted geometry physically plausible, they use Joint Geometric Optimization—a dual regularization strategy. Explicit constraints enforce known geometric rules (like ground plane consistency), while implicit latent regularization aligns the model’s internal representations with geometry-aware priors learned during training. The prediction branch outputs future point clouds, while the understanding branch outputs semantic labels and relationships.
Multi-view Images
      |
      v
  [BEV Encoder] --> shared spatial representation
      |
      +------------------+------------------+
      |                                     |
      v                                     v
[Understanding Branch]              [Prediction Branch]
  LLM-enhanced queries              Geometric decoder
      |                                     ^
      |                                     |
      +---> [Current-to-Future Link] ------+
            (semantic guides geometry)
                                            |
                                            v
                                    [Joint Geometric Opt]
                                    (explicit + implicit)
                                            |
                                            v
                                    Future Point Clouds
Think of HERMES++ like a film director working with both a screenwriter and a cinematographer. The BEV encoder is the raw footage—all the visual information captured from multiple angles. The understanding branch (screenwriter) interprets what’s happening: “the pedestrian is waiting to cross, the car is slowing down.” The prediction branch (cinematographer) plans the next shots: “the pedestrian will be here, the car will be there.” The Current-to-Future Link is the director’s notes—the screenwriter’s interpretation directly informs how the cinematographer frames future shots. Without the director (the link), the cinematographer might predict physically plausible but contextually wrong movements (a car accelerating when it should brake). The Joint Geometric Optimization is like the continuity editor, ensuring the predicted shots don’t violate physical laws (cars don’t float, objects don’t teleport).
Key Concepts
-
BEV (Bird’s-Eye View) Representation: Imagine you’re playing a strategy game where the camera looks straight down at the battlefield. That’s BEV—a top-down 2D grid where each cell contains information about what’s at that location in 3D space. Why is this useful? Multi-view cameras give you fragmented perspectives (front, left, right, back), but BEV consolidates them into one coherent spatial map. It’s like taking four photos of a room from different corners and stitching them into a floor plan. For autonomous driving, BEV naturally aligns with how we think about navigation (lanes, intersections, distances) and it’s computationally efficient because you’re working in 2D instead of full 3D. The key trick: BEV preserves spatial relationships (what’s next to what, how far apart) while being structured enough that language models can process it.
-
Current-to-Future Link: This is the bridge between “what I understand now” and “what I predict next.” In most models, understanding and prediction are separate—like having a weather analyst and a fortune teller who never talk. The Current-to-Future Link makes them collaborate. Concretely, it takes semantic features from the understanding branch (high-level concepts like “pedestrian intending to cross”) and injects them into the prediction branch’s geometric processing. It’s implemented as a cross-attention mechanism where future queries attend to current semantic context. Example: without this link, the model might predict a pedestrian continues walking straight (geometrically plausible). With the link, semantic understanding says “pedestrian is looking at phone, likely to stop,” so the geometric prediction adjusts accordingly.
-
Joint Geometric Optimization: Predicting future geometry is tricky because there are infinite ways to arrange points in 3D space, but only a tiny fraction are physically valid. This optimization strategy enforces validity through two complementary mechanisms. Explicit constraints are hard rules: “predicted points must lie on or above the ground plane,” “object boundaries must be continuous,” “motion must respect physics.” These are implemented as loss terms during training. Implicit regularization is softer: the model learns latent representations that naturally favor plausible geometries by training on real-world data. It’s like teaching someone to draw faces—you can give explicit rules (eyes above nose, nose above mouth) but they also develop an implicit sense of “this looks right” from seeing thousands of examples. Together, these prevent the model from generating nonsensical futures (cars sinking into the ground, objects fragmenting).
Framework Shift
Before (mainstream approach):        After (HERMES++):

Task 1: Scene Understanding          Unified Model:
[Images] -> [Specialist Model A]     [Images]
         -> Semantic Labels                |
                                           v
Task 2: Future Prediction            [Shared BEV Encoder]
[Images] -> [Specialist Model B]          |
         -> Future Geometry          +----+----+
                                     |         |
(Two separate models,                v         v
 no information sharing)        [Understand] [Predict]
                                     |         ^
                                     +----+----+
                                          |
                                    Semantic guides
                                    geometric evolution
From parallel specialists to collaborative branches, the core shift is making semantic understanding a first-class input to geometric prediction rather than treating them as independent tasks.
Expert Assessment
Problem choice: This is a real gap, not manufactured. The autonomous driving community has been building increasingly sophisticated future prediction models (occupancy forecasting, trajectory prediction) while separately developing scene understanding systems. The insight that these should inform each other is obvious in hindsight but underexplored in practice. It sits at a natural convergence point in the field’s trajectory—LLMs are mature enough to handle structured spatial inputs, and geometric prediction has hit a ceiling without semantic context.
Method maturity: The approach is more architectural engineering than algorithmic breakthrough. The individual components (BEV encoding, cross-attention, geometric losses) are established techniques. The contribution is in the integration—showing that these pieces can work together synergistically. There’s a risk of over-engineering (four major components, each with hyperparameters), but the ablations suggest each piece pulls its weight. A simpler approach might be to just condition a prediction model on LLM embeddings, but the authors argue (convincingly) that bidirectional information flow matters.
Experimental integrity: The baselines are fair—they compare against strong specialists (BEVFormer for understanding, OccWorld for prediction) rather than strawmen. The numbers are solid across multiple benchmarks (nuScenes, Waymo). One yellow flag: the “outperforms specialists” claim is true on average but not uniformly—some specialist models still win on specific metrics. The paper is honest about this in tables but the abstract oversells slightly. The ablations are thorough, showing each component’s contribution. No major red flags, but I’d want to see failure case analysis (when does the semantic-geometric coupling hurt rather than help?).
Writing quality: The paper front-loads motivation well but buries implementation details. Section 3.3 (Joint Geometric Optimization) is dense and would benefit from a concrete example walkthrough. The related work section is comprehensive but reads like a literature dump—cutting it by 30% and integrating key comparisons into the method section would improve flow. The figures are clear but Figure 3 (architecture diagram) tries to show too much at once. Breaking it into two figures (understanding branch, prediction branch) would help. The experimental section is well-structured.
Verdict: weak accept — Solid integration work with thorough experiments, but the novelty is in composition rather than invention, and the complexity cost is non-trivial.
Takeaways
Cross-task knowledge transfer via attention: The Current-to-Future Link pattern is generalizable. If you have two related tasks (detection + tracking, segmentation + depth, etc.), instead of training separate models, use cross-attention to let one task’s features inform the other. The key is identifying which direction the information should flow and at what layer.
BEV as a universal interface: For any multi-view spatial reasoning problem, BEV is a strong default representation. It’s more structured than image features, more efficient than full 3D voxels, and compatible with both geometric operations and language model processing. If you’re working with camera arrays (robotics, surveillance, AR), consider BEV as your intermediate representation.
Dual regularization for structured prediction: When predicting structured outputs (geometry, graphs, sequences), combine explicit constraints (hard rules you know) with implicit regularization (learned priors from data). Explicit constraints prevent catastrophic failures; implicit regularization handles the long tail of edge cases you didn’t think to encode.
When to unify vs specialize: This paper shows unification wins when tasks share underlying structure (spatial reasoning) and one task’s output is a natural input to the other (semantics → geometry). But unification has costs—more complex training, harder debugging, potential for negative transfer. The decision heuristic: unify when the tasks have asymmetric information flow (one clearly informs the other), not just when they’re vaguely related.
论文: 2604.28196 作者: Xin Zhou, Dingkang Liang, Xiwu Chen, Feiyang Tan, Dingyuan Zhang, Hengshuang Zhao, Xiang Bai 分类: cs.CV
缺口
现有的驾驶世界模型分成两个阵营。
一个阵营(如UniAD、VAD)专注于未来场景生成——预测物体会在哪里——但把当前场景当黑盒处理。
它们能向前模拟时间,却答不出”那是什么物体?“或”它为什么那样移动?“另一个阵营用大语言模型推理场景,但LLM活在文本空间。
它们能告诉你”行人可能会过马路”,却预测不了实际的3D轨迹或几何演化。
你要么得到没有语义的物理,要么得到没有物理的语义。
核心问题:理解(是什么/为什么)和预测(在哪里/何时)需要不同的表示。
场景理解想要与语言模型兼容的高层语义特征。
未来预测需要捕捉空间结构的密集几何表示。
以往工作把这两者当成独立任务,用独立模型处理。
问题:语义推理 <--鸿沟--> 几何预测
     (LLM空间)            (3D空间)
        |                    |
        v                    v
假设:能否在一个模型中统一?
        |
        v
方法:共享BEV主干 + 双分支
     + 知识迁移 + 时间桥接
        |
        v
证据:在两个任务上都超越专家模型
     (nuScenes、Waymo基准)
        |
        v
结论:统一模型 > 独立模型
     (理解与预测的协同)
增量
一句话:HERMES++之前,你需要独立模型来回答”场景里有什么”和”东西会去哪”——现在一个模型通过让LLM推理引导几何预测来完成两者。
核心机制
架构有三个按顺序工作的主要组件。
首先,BEV(鸟瞰图)编码器处理多视角相机图像,将它们转换成统一的空间表示——可以想象成从多个相机角度创建一张俯视地图。
这个BEV表示至关重要,因为它既足够结构化可以做几何运算,又与语言模型处理兼容。
其次,模型分成两个共享这个BEV主干的分支。
理解分支使用LLM增强的世界查询——可学习的token,提取语义信息并通过语言模型获得高层场景解释。
预测分支采用相同的BEV特征,但通过专注于几何演化的不同路径处理。
巧妙之处在于:理解分支的输出(语义上下文)通过”当前到未来链接”模块注入预测分支。
这就是语义推理引导几何预测的地方。
第三,为了保持预测几何的物理合理性,他们使用联合几何优化——一种双重正则化策略。
显式约束强制执行已知的几何规则(如地面平面一致性),而隐式潜在正则化将模型的内部表示与训练期间学到的几何感知先验对齐。
预测分支输出未来点云,理解分支输出语义标签和关系。
多视角图像
    |
    v
[BEV编码器] --> 共享空间表示
    |
    +------------------+------------------+
    |                                     |
    v                                     v
[理解分支]                          [预测分支]
 LLM增强查询                        几何解码器
    |                                     ^
    |                                     |
    +---> [当前到未来链接] ---------------+
          (语义引导几何)
                                          |
                                          v
                                  [联合几何优化]
                                  (显式+隐式)
                                          |
                                          v
                                  未来点云
把HERMES++想象成一个同时与编剧和摄影师合作的电影导演。
BEV编码器是原始素材——从多个角度捕获的所有视觉信息。
理解分支(编剧)解释正在发生什么:“行人在等待过马路,汽车在减速。“预测分支(摄影师)规划下一个镜头:“行人会在这里,汽车会在那里。“当前到未来链接是导演的笔记——编剧的解释直接告知摄影师如何构图未来镜头。
没有导演(链接),摄影师可能预测物理上合理但上下文错误的运动(汽车应该刹车时却加速)。
联合几何优化就像连续性剪辑师,确保预测的镜头不违反物理定律(汽车不会漂浮,物体不会瞬移)。
关键概念
- BEV(鸟瞰图)表示:想象你在玩一个策略游戏,相机直接俯视战场。
这就是BEV——一个俯视的2D网格,每个单元格包含该位置在3D空间中的信息。
为什么有用?多视角相机给你碎片化的视角(前、左、右、后),但BEV将它们整合成一个连贯的空间地图。
就像从房间的四个角拍四张照片,然后拼接成平面图。
对于自动驾驶,BEV自然对齐我们思考导航的方式(车道、交叉口、距离),而且计算高效,因为你在2D而非完整3D中工作。
关键技巧:BEV保留空间关系(什么挨着什么,相距多远),同时足够结构化让语言模型能处理。
- 当前到未来链接:这是”我现在理解的”和”我接下来预测的”之间的桥梁。
在大多数模型中,理解和预测是分离的——就像有个气象分析师和算命先生从不交谈。
当前到未来链接让他们协作。
具体来说,它从理解分支获取语义特征(如”行人打算过马路”的高层概念),并注入预测分支的几何处理中。
它实现为交叉注意力机制,未来查询关注当前语义上下文。
例子:没有这个链接,模型可能预测行人继续直走(几何上合理)。
有了链接,语义理解说”行人在看手机,可能会停下”,所以几何预测相应调整。
- 联合几何优化:预测未来几何很棘手,因为在3D空间中排列点有无限种方式,但只有极小部分是物理有效的。
这个优化策略通过两个互补机制强制有效性。
显式约束是硬规则:“预测点必须在地面平面上或之上”,“物体边界必须连续”,“运动必须遵守物理”。
这些在训练期间作为损失项实现。
隐式正则化更柔和:模型通过在真实世界数据上训练,学习自然偏好合理几何的潜在表示。
就像教人画脸——你可以给显式规则(眼睛在鼻子上方,鼻子在嘴上方),但他们也从看数千个例子中发展出”这看起来对”的隐式感觉。
两者结合,防止模型生成荒谬的未来(汽车沉入地面,物体碎裂)。
框架转变
之前(主流方法):                之后(HERMES++):

任务1:场景理解                   统一模型:
[图像] -> [专家模型A]             [图像]
       -> 语义标签                     |
                                       v
任务2:未来预测                   [共享BEV编码器]
[图像] -> [专家模型B]                  |
       -> 未来几何                +----+----+
                                  |         |
(两个独立模型,                   v         v
 无信息共享)                 [理解]     [预测]
                                  |         ^
                                  +----+----+
                                       |
                                  语义引导
                                  几何演化
从并行专家到协作分支,核心转变是让语义理解成为几何预测的一等输入,而非将它们当作独立任务。
专家评审
选题眼光:这是真缺口,不是人造的。
自动驾驶社区一直在构建越来越复杂的未来预测模型(占用预测、轨迹预测),同时独立开发场景理解系统。
这两者应该相互告知的洞见事后看来显而易见,但实践中探索不足。
它处于该领域发展轨迹的自然汇聚点——LLM已经成熟到可以处理结构化空间输入,而几何预测在没有语义上下文的情况下已经触及天花板。
方法成熟度:这个方法更多是架构工程而非算法突破。
单个组件(BEV编码、交叉注意力、几何损失)都是成熟技术。
贡献在于集成——展示这些部分可以协同工作。
有过度工程的风险(四个主要组件,每个都有超参数),但消融实验表明每个部分都发挥作用。
更简单的方法可能是直接用LLM嵌入来条件化预测模型,但作者(令人信服地)论证双向信息流很重要。
实验诚意:基线公平——他们与强大的专家模型(理解用BEVFormer,预测用OccWorld)比较,而非稻草人。
数字在多个基准(nuScenes、Waymo)上都扎实。
一个黄色警告:“超越专家”的说法平均而言是真的,但并非一致——某些专家模型在特定指标上仍然获胜。
论文在表格中对此诚实,但摘要略有夸大。
消融实验彻底,展示了每个组件的贡献。
没有重大红旗,但我想看失败案例分析(语义-几何耦合何时有害而非有益?)。
写作功力:论文前面动机铺垫得好,但埋没了实现细节。
3.3节(联合几何优化)密集,需要具体例子演示。
相关工作部分全面但读起来像文献堆砌——削减30%并将关键比较整合到方法部分会改善流畅度。
图表清晰,但图3(架构图)试图一次展示太多。
拆成两张图(理解分支、预测分支)会有帮助。
实验部分结构良好。
判决:弱接收 — 扎实的集成工作配以彻底的实验,但新颖性在于组合而非发明,复杂性成本不可忽视。
要点总结
通过注意力的跨任务知识迁移:当前到未来链接模式可推广。
如果你有两个相关任务(检测+跟踪,分割+深度等),与其训练独立模型,不如用交叉注意力让一个任务的特征告知另一个。
关键是识别信息应该流向哪个方向以及在哪一层。
BEV作为通用接口:对于任何多视角空间推理问题,BEV是强大的默认表示。
它比图像特征更结构化,比完整3D体素更高效,且与几何运算和语言模型处理都兼容。
如果你在处理相机阵列(机器人、监控、AR),考虑BEV作为中间表示。
结构化预测的双重正则化:预测结构化输出(几何、图、序列)时,结合显式约束(你知道的硬规则)和隐式正则化(从数据学到的先验)。
显式约束防止灾难性失败;隐式正则化处理你没想到编码的长尾边缘情况。
何时统一vs专门化:本文展示当任务共享底层结构(空间推理)且一个任务的输出是另一个的自然输入(语义→几何)时,统一获胜。
但统一有成本——更复杂的训练、更难调试、潜在的负迁移。
决策启发式:当任务有非对称信息流(一个明确告知另一个)时统一,而非仅仅因为它们模糊相关。