Paper: 2605.26109 Authors: Jiraphon Yenphraphai, Jianqi Chen, Jian Wang, Gordon Qian, Sergey Tulyakov, Rameen Abdal, Raymond A. Yeh, Peter Wonka, Chaoyang Wang Categories: cs.CV
The Gap
Existing video-to-4D methods (like 4DGen, Consistent4D) generate dynamic meshes by training from scratch on video data. They handle common cases reasonably well but collapse on edge cases: topology changes (a cloth tearing), transparent materials (glass, water), thin structures (hair, wires), and inner surfaces (inside of a cup). Meanwhile, Trellis2 excels at these rare cases in the 3D domain because it was trained on massive diverse 3D data. The gap: how do you get temporal consistency for 4D generation without throwing away Trellis2’s hard-won quality on edge cases?
Problem: Video-to-4D fails on rare cases
   |
   v
Observation: Trellis2 handles rare cases in 3D
   |
   v
Challenge: Extend to 4D without losing 3D quality
   |
   +---> Method: Anchor on Trellis2-generated first frame
   |            + Cross-frame attention (sliding window)
   |            + 4D temporal encoding (reuse spatial RoPE)
   |
   v
Evidence: Outperforms baselines on ActionBench + complex dynamics
   |
   v
Conclusion: Inheritance > training from scratch for rare cases
The Increment
One sentence: Before Helix4D, video-to-4D meant choosing between temporal consistency and quality on edge cases; after Helix4D, you get both by anchoring temporal models on a strong 3D prior.
Core Mechanism
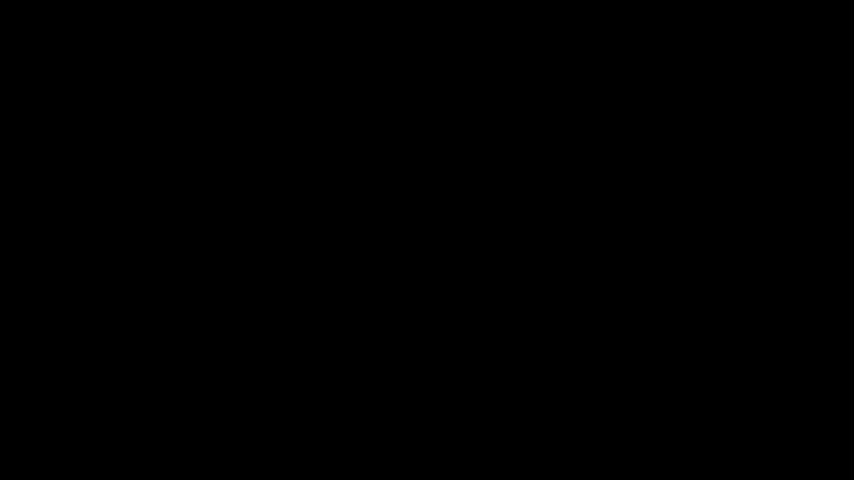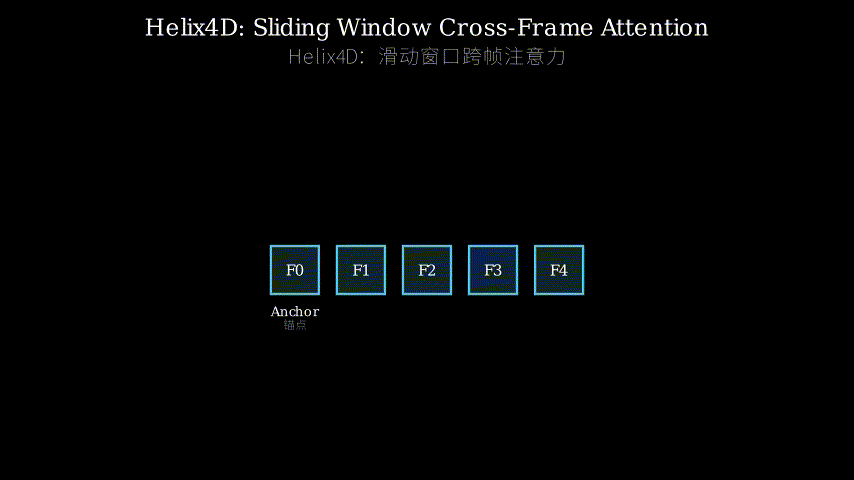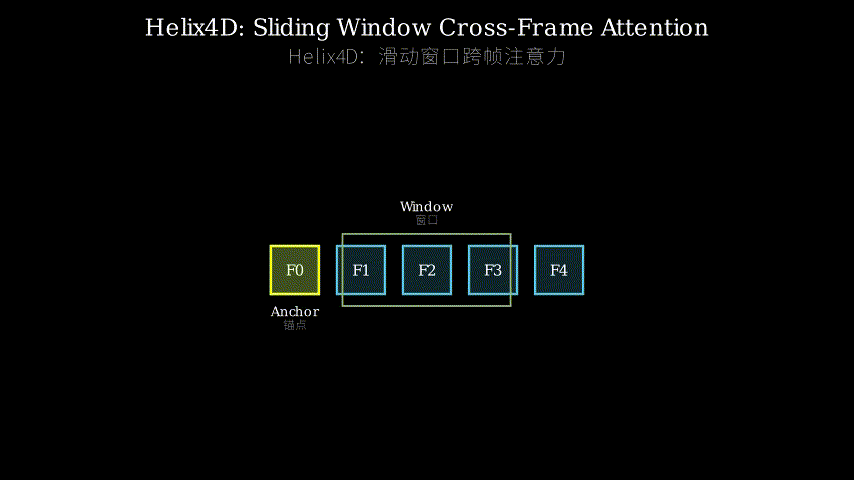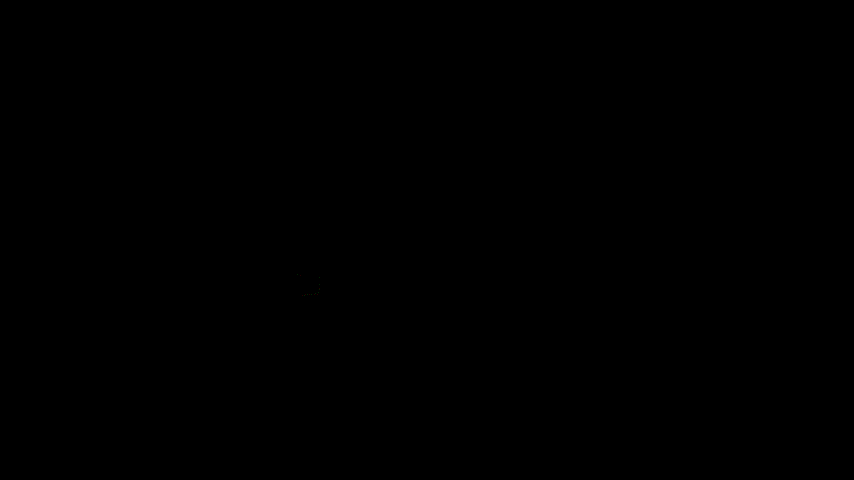
Helix4D starts by generating the first frame using the pretrained Trellis2 model. This frame becomes an anchor—a high-quality reference that subsequent frames attend to. For each new frame, the model uses sliding-window cross-frame attention: it looks at the previous frame (for temporal smoothness) and the first frame (for quality inheritance). The attention mechanism lets later frames “borrow” Trellis2’s understanding of transparent materials, thin structures, and inner surfaces without retraining.
To inject temporal information, Helix4D repurposes the existing 3D positional encoding (RoPE). RoPE encodes spatial positions using sine/cosine waves at different frequencies. High-frequency bands capture fine spatial details; low-frequency bands are redundant for spatial positioning. Helix4D steals these low-frequency bands and reassigns them to encode time. This extends the encoding from 3D to 4D without adding parameters or breaking the pretrained spatial understanding.
The data flows like this: video frames → first frame generated by Trellis2 → subsequent frames generated by Helix4D with cross-attention to first frame and previous frame → dynamic mesh sequence. The cross-frame attention acts as a quality bridge, letting the model inherit capabilities it never trained for.
Video frames:  [F0] [F1] [F2] [F3] ...
                 |    |    |    |
                 v    |    |    |
              Trellis2|    |    |
                 |    |    |    |
                 v    v    v    v
              [M0]-->[M1]-->[M2]-->[M3] ...
                 ^    ^    ^    ^
                 |    |    |    |
              Anchor  |    |    |
                 +----+----+----+  (cross-frame attention)
                      |    |    |
                   Sliding window
Think of Helix4D as a relay race where the first runner is a champion (Trellis2). The first runner sets a gold-standard pace and hands off the baton. Each subsequent runner (frame generator) doesn’t just take the baton from the previous runner—they also keep glancing back at the champion to remember what good form looks like. The champion’s technique (quality on rare cases) propagates through the race via these backward glances (cross-frame attention). The temporal encoding is like adding a timestamp to each runner’s position without changing the track layout—you reuse the existing lane markers (low-frequency spatial bands) to encode time.
Key Concepts
-
Cross-frame attention anchored on first frame: Attention mechanisms let a model decide which parts of the input to focus on. In video generation, you typically attend to the previous frame for smoothness. Helix4D adds a second attention path to the first frame. Why? The first frame is generated by Trellis2, which has seen millions of 3D examples including rare cases. By attending to this frame throughout the sequence, later frames can “ask” the first frame how to handle transparent glass or inner surfaces—capabilities they didn’t train for. It’s like keeping an expert consultant on call: you don’t need to learn everything yourself if you can query someone who already knows.
-
Repurposing RoPE bands for temporal encoding: RoPE (Rotary Position Embedding) encodes 3D positions by rotating feature vectors at different frequencies. High frequencies distinguish nearby points; low frequencies are coarse and somewhat redundant. Helix4D notices that the lowest-frequency bands don’t add much spatial precision, so it reassigns them to encode time instead. This is parameter-free: you’re not adding new weights, just reinterpreting existing ones. Imagine a piano with 88 keys. The lowest octave is rarely used for melody. Helix4D says: “Let’s use those low notes to encode rhythm (time) instead of pitch (space).” The high notes still handle spatial detail; the low notes now handle temporal progression.
Framework Shift
Before (train from scratch):        After (Helix4D):

Video --> [4D Model] --> Meshes     Video --> [Trellis2] --> F0 (anchor)
          (trained on                         |
           video data)                        v
                                      [Helix4D] <--+
          Fails on rare cases          |          |
          (transparent, thin, etc)     v          |
                                      F1 ------> F2 --> ...
                                       ^          ^
                                       |          |
                                    Cross-frame attention
                                    to F0 (inherits quality)
From training a 4D model on video data to anchoring a 4D model on a strong 3D prior, the core shift is inheritance over learning.
Expert Assessment
Problem choice: Real gap. Video-to-4D is an active area, and the failure modes (topology changes, transparent materials) are well-documented in prior work. The insight to leverage Trellis2’s 3D quality is pragmatic—standing on the shoulders of a strong prior rather than reinventing the wheel.
Method maturity: Clever reuse of existing components. The cross-frame attention design is straightforward but well-motivated. Repurposing RoPE bands for time is elegant—no new parameters, no architectural surgery. However, the paper doesn’t deeply explore failure modes of the anchor strategy. What happens when the first frame itself is poor? Does the quality inheritance become a liability?
Experimental integrity: Baselines are reasonable (4DGen, Consistent4D). The custom “complex dynamics” test set is necessary since existing benchmarks don’t stress rare cases, but it’s not publicly released, which limits reproducibility. Quantitative metrics (FID, temporal consistency) are standard. Qualitative results look strong, but the paper leans heavily on cherry-picked examples. More ablation on when the method fails would strengthen the claims.
Writing quality: The two-question framing (how to share info across frames, how to inject time) is clear. The method section is dense but logical. The related work section is thin—doesn’t position the work relative to other 3D-to-4D lifting approaches or temporal attention variants. The experiments section could use a failure case analysis. Rewriting the ablation study to include negative results would elevate the paper from “this works” to “this works because X, and here’s where it breaks.”
Verdict: weak accept — Solid engineering contribution with a clear practical win, but lacks depth in understanding when and why the approach fails.
Takeaways
Anchor on strong priors when extending to new domains: If you have a model that excels in domain A (3D) and want to extend to domain B (4D), don’t throw away A’s knowledge. Use A’s output as an anchor and let B attend to it. This pattern applies beyond vision—text-to-speech models could anchor on high-quality phoneme predictions, code generation could anchor on type-checked snippets.
Repurpose redundant dimensions in learned encodings: Positional encodings often have redundancy (low-frequency bands in RoPE, unused embedding dimensions). Before adding parameters for a new signal (time, modality, etc.), check if you can reassign existing capacity. It’s parameter-efficient and preserves pretrained structure.
Sliding-window + anchor attention for temporal models: Pure sliding-window attention (attend to previous frame) gives smoothness but drifts. Pure global attention (attend to all frames) is expensive and dilutes focus. Sliding-window + anchor (attend to previous + first frame) balances locality and global coherence. Useful for any sequential generation task where the first element sets a quality bar.
论文: 2605.26109 作者: Jiraphon Yenphraphai, Jianqi Chen, Jian Wang, Gordon Qian, Sergey Tulyakov, Rameen Abdal, Raymond A. Yeh, Peter Wonka, Chaoyang Wang 分类: cs.CV
缺口
现有的视频转4D方法(如4DGen、Consistent4D)通过在视频数据上从头训练来生成动态网格。
它们在常见情况下表现尚可,但在边缘情况下崩溃:拓扑变化(布料撕裂)、透明材质(玻璃、水)、细薄结构(头发、电线)、内表面(杯子内部)。
与此同时,Trellis2在3D领域擅长处理这些罕见情况,因为它在海量多样的3D数据上训练过。
缺口在于:如何在获得4D生成的时间一致性的同时,不丢掉Trellis2在边缘情况上来之不易的质量?
问题:视频转4D在罕见情况下失效
   |
   v
观察:Trellis2在3D中处理罕见情况很好
   |
   v
挑战:扩展到4D而不损失3D质量
   |
   +---> 方法:锚定在Trellis2生成的首帧
   |            + 跨帧注意力(滑动窗口)
   |            + 4D时间编码(复用空间RoPE)
   |
   v
证据:在ActionBench和复杂动态集上超越基线
   |
   v
结论:继承 > 从头训练(针对罕见情况)
增量
一句话: Helix4D之前,视频转4D意味着在时间一致性和边缘情况质量之间二选一;
Helix4D之后,通过将时间模型锚定在强3D先验上,两者兼得。
核心机制
Helix4D首先使用预训练的Trellis2模型生成第一帧。
这一帧成为锚点——一个高质量参考,后续帧会关注它。
对于每个新帧,模型使用滑动窗口跨帧注意力:它查看前一帧(保证时间平滑)和第一帧(继承质量)。
注意力机制让后续帧能”借用”Trellis2对透明材质、细薄结构和内表面的理解,无需重新训练。
为了注入时间信息,Helix4D重新利用现有的3D位置编码(RoPE)。
RoPE使用不同频率的正弦/余弦波编码空间位置。
高频段捕捉精细空间细节;
低频段对空间定位来说是冗余的。
Helix4D”偷走”这些低频段,重新分配它们来编码时间。
这将编码从3D扩展到4D,不增加参数,也不破坏预训练的空间理解。
数据流动如下:视频帧 → Trellis2生成首帧 → Helix4D生成后续帧(跨注意力到首帧和前一帧)→ 动态网格序列。
跨帧注意力充当质量桥梁,让模型继承它从未训练过的能力。
视频帧:  [F0] [F1] [F2] [F3] ...
           |    |    |    |
           v    |    |    |
        Trellis2|    |    |
           |    |    |    |
           v    v    v    v
        [M0]-->[M1]-->[M2]-->[M3] ...
           ^    ^    ^    ^
           |    |    |    |
        锚点    |    |    |
           +----+----+----+  (跨帧注意力)
                |    |    |
             滑动窗口
把Helix4D想象成接力赛,第一棒是冠军选手(Trellis2)。
第一棒设定了金标准的节奏并交出接力棒。
每个后续选手(帧生成器)不仅从前一个选手那里接棒——他们还不断回头看冠军,记住什么是好的姿态。
冠军的技术(罕见情况下的质量)通过这些回望(跨帧注意力)在整个比赛中传播。
时间编码就像给每个选手的位置加上时间戳,而不改变赛道布局——你复用现有的车道标记(低频空间段)来编码时间。
关键概念
- 锚定在首帧的跨帧注意力: 注意力机制让模型决定关注输入的哪些部分。
在视频生成中,通常关注前一帧以保证平滑。
Helix4D增加了第二条注意力路径到首帧。
为什么?
首帧由Trellis2生成,它见过数百万个3D样本,包括罕见情况。
通过在整个序列中关注这一帧,后续帧可以”询问”首帧如何处理透明玻璃或内表面——它们没训练过的能力。
这就像随时待命的专家顾问:如果你能查询已经知道的人,就不需要自己学会所有东西。
- 重新利用RoPE频段进行时间编码: RoPE(旋转位置嵌入)通过在不同频率上旋转特征向量来编码3D位置。
高频区分相邻点;
低频粗糙且有些冗余。
Helix4D注意到最低频段对空间精度贡献不大,于是将它们重新分配来编码时间。
这是零参数的:你不是添加新权重,只是重新解释现有的。
想象一架有88个键的钢琴。
最低八度很少用于旋律。
Helix4D说:“让我们用这些低音来编码节奏(时间)而不是音高(空间)。
“高音仍然处理空间细节;
低音现在处理时间进展。
框架转变
之前(从头训练):              之后(Helix4D):

视频 --> [4D模型] --> 网格      视频 --> [Trellis2] --> F0(锚点)
         (在视频数据                      |
          上训练)                         v
                                  [Helix4D] <--+
         在罕见情况下失效            |          |
         (透明、细薄等)              v          |
                                   F1 ------> F2 --> ...
                                    ^          ^
                                    |          |
                                 跨帧注意力
                                 到F0(继承质量)
从在视频数据上训练4D模型到将4D模型锚定在强3D先验上,核心转变是继承而非学习。
专家评审
选题眼光: 真实缺口。
视频转4D是活跃领域,失效模式(拓扑变化、透明材质)在先前工作中有充分记录。
利用Trellis2的3D质量的洞察很务实——站在强先验的肩膀上,而不是重新发明轮子。
方法成熟度: 巧妙复用现有组件。
跨帧注意力设计直接但动机充分。
重新利用RoPE频段编码时间很优雅——无新参数,无架构手术。
但论文没有深入探索锚定策略的失效模式。
当首帧本身质量差时会怎样?
质量继承会变成负担吗?
实验诚意: 基线合理(4DGen、Consistent4D)。
自定义的”复杂动态”测试集是必要的,因为现有基准不强调罕见情况,但它未公开发布,限制了可复现性。
定量指标(FID、时间一致性)是标准的。
定性结果看起来很强,但论文严重依赖精选样例。
更多关于方法何时失效的消融实验会加强论证。
写作功力: 两个问题的框架(如何跨帧共享信息、如何注入时间)很清晰。
方法部分密集但逻辑清楚。
相关工作部分单薄——没有相对于其他3D到4D提升方法或时间注意力变体定位工作。
实验部分可以加入失败案例分析。
重写消融研究以包含负面结果,会将论文从”这有效”提升到”这有效是因为X,这里是它崩溃的地方”。
判决: 弱接收 — 扎实的工程贡献,有明确的实用价值,但缺乏对方法何时及为何失效的深入理解。
要点总结
扩展到新领域时锚定在强先验上: 如果你有一个在领域A(3D)表现出色的模型,想扩展到领域B(4D),不要丢掉A的知识。
使用A的输出作为锚点,让B关注它。
这个模式超越视觉——文本转语音模型可以锚定在高质量音素预测上,代码生成可以锚定在类型检查过的片段上。
重新利用学习编码中的冗余维度: 位置编码通常有冗余(RoPE中的低频段、未使用的嵌入维度)。
在为新信号(时间、模态等)添加参数之前,检查是否可以重新分配现有容量。
这是参数高效的,并保留预训练结构。
时间模型的滑动窗口+锚点注意力: 纯滑动窗口注意力(关注前一帧)给出平滑但会漂移。
纯全局注意力(关注所有帧)昂贵且稀释焦点。
滑动窗口+锚点(关注前一帧+首帧)平衡局部性和全局一致性。
对任何首元素设定质量标准的序列生成任务都有用。