Paper: 2605.13821 Authors: Jiayi Zhang, Yongfeng Gu, Jianhao Ruan, Maojia Song, Yiran Peng, Zhiguang Han, Jinyu Xiang, Zhitao Wang, Caiyin Yang, Yixi Ouyang Categories: cs.AI, cs.LG
The Gap
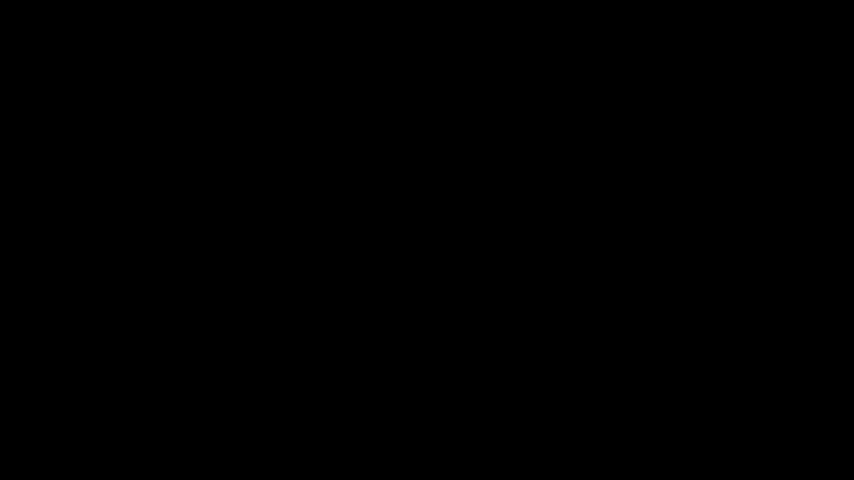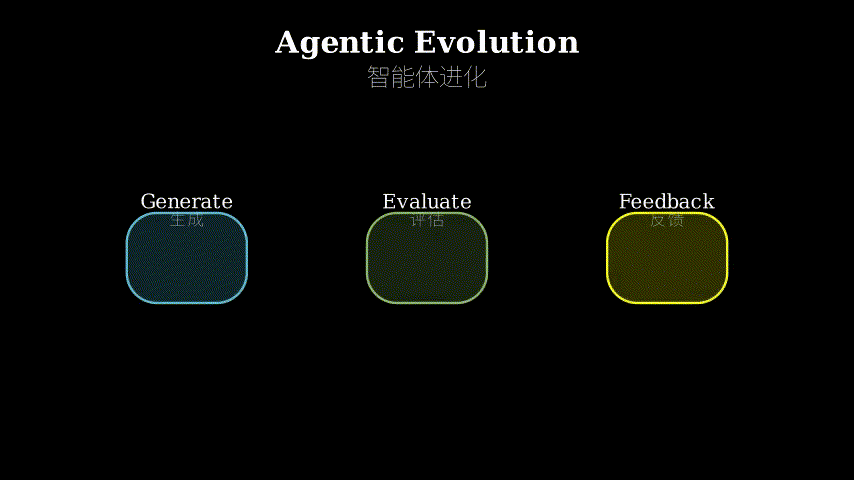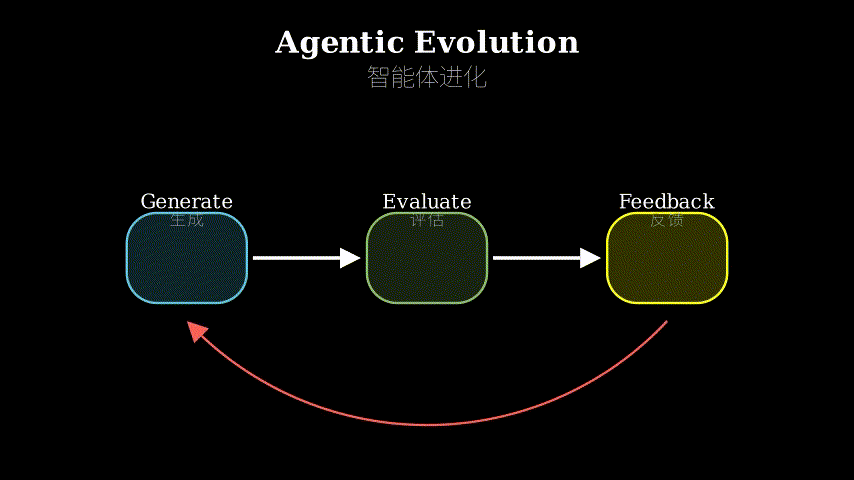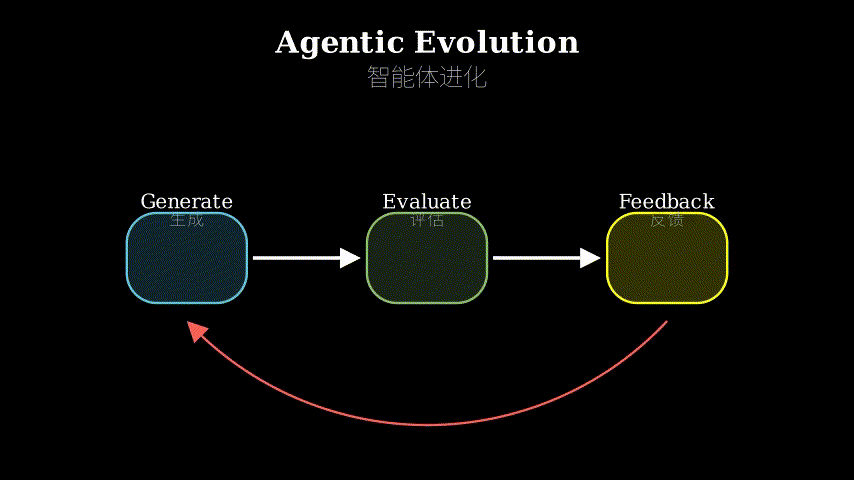
Agentic evolution systems iteratively generate candidates, evaluate them, and use feedback to improve. Two camps exist: hand-designed procedures (modular but rigid, can’t adapt their own logic) and general-purpose agents (flexible but drift over long horizons, can’t stabilize what they’ve learned). Both accumulate rich evidence—candidates, feedback, traces, failures—but lack a stable interface to make this evidence actionable for revising the evolution mechanism itself. The core problem: existing systems operate within a fixed evolution strategy rather than on the strategy.
Problem: Evolution systems can't revise their own search logic
   |
   v
Assumption: Accumulated evidence (traces, failures) contains
            signals about how to improve the evolution process
   |
   v
Method: Formulate evolution as environment with process-level state
        Meta-agent edits the procedure/context, not the candidate
   |
   v
Evidence: 26% improvement over strongest baseline on benchmarks
          SOTA on open-ended optimization tasks
   |
   v
Conclusion: Meta-editing the evolution process outperforms
            direct candidate generation
The Increment
One sentence: Before AEvo, evolution systems generated better candidates; after AEvo, they generate better candidate generators.
Core Mechanism
AEvo treats the entire evolution process as an interactive environment. The accumulated context—all past candidates, evaluations, feedback, and execution traces—becomes the state of this environment. A meta-agent observes this state but doesn’t act by proposing the next candidate directly. Instead, it edits the procedure or agent context that will control future evolution steps.
For procedure-based evolution (fixed algorithms with modular steps), the meta-agent rewrites code blocks, adjusts hyperparameters, or reorders operations. For agent-based evolution (LLM agents with prompts and memory), it edits system prompts, refines memory structures, or injects learned heuristics. The key architectural choice: the meta-agent’s action space is the evolution mechanism itself, not the solution space.
Evolution Context (State)
+-----------------------+
| Past candidates       |
| Evaluation scores     |      Meta-Agent
| Feedback traces       | <--- observes
| Failure patterns      |          |
+-----------------------+          | edits
         |                         v
         |              +---------------------+
         |              | Procedure code      |
         +------------> | or Agent context    |
           feeds into   +---------------------+
                                 |
                                 | controls
                                 v
                        Next Evolution Step
                        (generates candidate)
Think of AEvo as a film director who doesn’t act in the movie but rewrites the script between takes. The actors (evolution procedures or agents) perform scenes (generate candidates). The director watches dailies (accumulated evidence), notices what’s working and what’s not, then edits the script (procedure code or agent prompts) to improve future takes. The actors don’t know they’re being directed—they just follow the updated script. Over time, the script evolves to encode successful patterns and avoid repeated mistakes. The director’s job isn’t to perform better; it’s to make the performers better.
Key Concepts
-
Process-level state: Traditional RL treats each candidate generation as a state. AEvo lifts the abstraction: the *entire evolution history is the state. This includes not just “what candidates were tried” but “how they were generated, what feedback they received, which patterns failed repeatedly.” The state is a compressed representation of the search trajectory, not a point in the solution space. This shift enables the meta-agent to reason about the evolution strategy itself rather than individual solutions.
-
Meta-editing: Instead of the agent saying “try candidate X next,” it says “change line 47 of the mutation function to prioritize diversity” or “add this heuristic to the system prompt: avoid solutions that failed in iteration 3-5.” The action is a diff to the evolution mechanism. This creates a stable interface: whether you’re evolving code, workflows, or scientific hypotheses, the meta-agent’s job is the same—edit the thing that generates candidates. The evolution mechanism becomes a first-class object that can be inspected, versioned, and improved.
-
Harnessing: The paper uses this term to mean “making accumulated evidence actionable.” Raw evolution traces are noise unless you have a mechanism to extract patterns and inject them back into the process. AEvo harnesses evidence by giving the meta-agent read access to the full context and write access to the evolution logic. It’s the difference between a system that forgets its mistakes and one that debugs its own search strategy.
Framework Shift
Before (direct evolution):          After (AEvo meta-editing):

  Agent/Procedure                     Meta-Agent
        |                                  |
        | generates                        | observes context
        v                                  | edits mechanism
    Candidate -----> Evaluate              v
        ^                |              Procedure/Agent
        |                |                  |
        +--- feedback ---+                  | generates
                                            v
                                        Candidate
                                            |
                                            v
                                        Evaluate
                                            |
                                            v
                                    Update context
                                            |
                                            v
                                    (loop back to meta-agent)
From “agent proposes, environment evaluates” to “meta-agent edits the proposer, proposer generates, environment evaluates, meta-agent observes and edits again”—the core shift is closing the loop at the mechanism level, not just the candidate level.
Expert Assessment
Problem choice: Real gap. The field has been stuck in a local optimum: either you hand-design evolution strategies (genetic algorithms, MCTS variants) that can’t adapt, or you use LLM agents that adapt too much and lose coherence. The insight that accumulated evidence should inform the evolution mechanism itself is obvious in hindsight but underexplored. This sits at the intersection of meta-learning and program synthesis, which is fertile ground.
Method maturity: The core idea—treat evolution as an environment and edit the mechanism—is elegant. But the implementation feels like two separate systems duct-taped together (one for procedure-based, one for agent-based). The paper doesn’t deeply explore what makes a good meta-editing action space or how to prevent the meta-agent from overfitting to recent failures. The approach is more “let’s try this” than “here’s a principled framework with theoretical guarantees.” That said, the empirical results suggest the idea has legs.
Experimental integrity: Baselines are reasonable (EoH, FunSearch, Reflexion, LATS, OpenHands). The 26% improvement is on a composite metric across benchmarks, which is solid but not jaw-dropping. The open-ended optimization tasks (code generation, workflow design, scientific discovery) are where AEvo shines, but the paper doesn’t report variance or failure modes. I’d want to see: how often does the meta-agent make things worse? How sensitive is performance to the meta-agent’s prompt? The ablation studies are thin—no breakdown of which types of edits contribute most.
Writing quality: The abstract and introduction are crisp. The method section buries the lede—Figure 2 should come earlier, and the distinction between procedure-based and agent-based evolution needs a clearer motivation upfront. The related work section is a laundry list rather than a narrative. The experiments section front-loads numbers without enough qualitative analysis of *what the meta-agent learned to edit. Rewriting Section 4 to lead with case studies (show me three edits the meta-agent made and why they worked) would make the paper twice as compelling.
Verdict: weak accept — The idea is sound and the results are promising, but the execution feels like a v1.0 that needs refinement. The paper opens a new design space (meta-editing evolution mechanisms) but doesn’t fully explore it. Worth publishing to seed the conversation, but I’d expect follow-up work to tighten the framework and dig deeper into what makes meta-editing effective.
Takeaways
Actionable idea: Treat your optimization loop as a first-class object. If you’re running any iterative search (hyperparameter tuning, prompt engineering, architecture search), log not just the results but the *strategy you used to generate each candidate. Then periodically step back and ask: “What patterns am I seeing? How should I adjust my search strategy?” You don’t need a fancy meta-agent—a human doing this manually will outperform blind iteration.
Technical trick: The process-level state representation is clever. Instead of feeding the meta-agent raw logs, AEvo compresses the evolution history into structured summaries (e.g., “mutation X failed 3 times, diversity dropped after iteration 5”). If you’re building any system that learns from its own execution traces, invest in good state compression. Raw logs are too noisy; hand-crafted features are too brittle. Learn a compressed representation that highlights actionable patterns.
Framework shift: The paper’s real contribution is reframing evolution from “search in solution space” to “search in strategy space.” This applies beyond AI: any domain where you iteratively refine solutions (drug discovery, engineering design, policy optimization) can benefit from explicitly modeling and improving the refinement process itself. The meta-level is where the leverage is.
论文: 2605.13821 作者: Jiayi Zhang, Yongfeng Gu, Jianhao Ruan, Maojia Song, Yiran Peng, Zhiguang Han, Jinyu Xiang, Zhitao Wang, Caiyin Yang, Yixi Ouyang 分类: cs.AI, cs.LG
缺口
智能体进化系统通过迭代生成候选方案、评估、利用反馈来改进。
现有两大阵营:手工设计的过程(模块化但僵化,无法调整自身逻辑)和通用智能体(灵活但长期漂移,无法稳定已学到的东西)。
两者都积累了丰富证据——候选方案、反馈、轨迹、失败案例——但缺乏稳定接口来让这些证据真正作用于修订进化机制本身。
核心问题:现有系统在固定的进化策略之内运作,而非作用于策略本身。
问题:进化系统无法修订自己的搜索逻辑
   |
   v
假设:积累的证据(轨迹、失败)包含如何改进进化过程的信号
   |
   v
方法:将进化建模为带过程级状态的环境
      元智能体编辑过程/上下文,而非候选方案
   |
   v
证据:比最强基线提升26%
      在开放式优化任务上达到SOTA
   |
   v
结论:元编辑进化过程优于直接生成候选方案
增量
一句话: AEvo之前,进化系统生成更好的候选方案;AEvo之后,它们生成更好的候选方案生成器。
核心机制
AEvo将整个进化过程视为交互式环境。
积累的上下文——所有过去的候选方案、评估、反馈、执行轨迹——成为这个环境的状态。
元智能体观察这个状态,但不直接提出下一个候选方案。
相反,它编辑将控制未来进化步骤的过程或智能体上下文。
对于基于过程的进化(带模块化步骤的固定算法),元智能体重写代码块、调整超参数或重排操作。
对于基于智能体的进化(带提示词和记忆的LLM智能体),它编辑系统提示、优化记忆结构或注入学到的启发式规则。
关键架构选择:元智能体的动作空间是进化机制本身,而非解空间。
进化上下文(状态)
+-----------------------+
| 过去的候选方案        |
| 评估分数              |      元智能体
| 反馈轨迹              | <--- 观察
| 失败模式              |          |
+-----------------------+          | 编辑
         |                         v
         |              +---------------------+
         |              | 过程代码            |
         +------------> | 或智能体上下文      |
           输入         +---------------------+
                                 |
                                 | 控制
                                 v
                        下一个进化步骤
                        (生成候选方案)
把AEvo想象成电影导演,他不在电影里演戏,而是在拍摄间隙改写剧本。
演员(进化过程或智能体)表演场景(生成候选方案)。
导演观看样片(积累的证据),注意到什么有效什么无效,然后编辑剧本(过程代码或智能体提示词)来改进未来的拍摄。
演员不知道自己被导演——他们只是遵循更新后的剧本。
随着时间推移,剧本进化到编码成功模式并避免重复错误。
导演的工作不是表演得更好,而是让表演者变得更好。
关键概念
- 过程级状态: 传统强化学习将每次候选方案生成视为一个状态。
AEvo提升了抽象层次:整个进化历史是状态。
这不仅包括”尝试了哪些候选方案”,还包括”它们如何生成、收到什么反馈、哪些模式反复失败”。
状态是搜索轨迹的压缩表示,而非解空间中的一个点。
这种转变使元智能体能够推理进化策略本身,而非单个解。
- 元编辑: 智能体不是说”下一个尝试候选方案X”,而是说”把变异函数的第47行改成优先考虑多样性”或”在系统提示中加入这条启发式规则:避免在迭代3-5中失败的解”。
动作是对进化机制的差异修改。
这创建了稳定接口:无论你在进化代码、工作流还是科学假设,元智能体的工作都一样——编辑生成候选方案的东西。
进化机制成为可检查、可版本化、可改进的一等对象。
- 驾驭(Harnessing): 论文用这个词表示”让积累的证据变得可操作”。
原始进化轨迹是噪声,除非你有机制提取模式并注入回过程。
AEvo通过给元智能体对完整上下文的读权限和对进化逻辑的写权限来驾驭证据。
这是遗忘错误的系统和调试自己搜索策略的系统之间的区别。
框架转变
之前(直接进化):              之后(AEvo元编辑):

  智能体/过程                     元智能体
        |                              |
        | 生成                         | 观察上下文
        v                              | 编辑机制
    候选方案 -----> 评估               v
        ^                |          过程/智能体
        |                |              |
        +--- 反馈 -------+              | 生成
                                        v
                                    候选方案
                                        |
                                        v
                                    评估
                                        |
                                        v
                                    更新上下文
                                        |
                                        v
                                (循环回元智能体)
从”智能体提议,环境评估”到”元智能体编辑提议者,提议者生成,环境评估,元智能体观察并再次编辑”——核心转变是在机制层面而非候选方案层面闭环。
专家评审
选题眼光: 真实缺口。
该领域一直困在局部最优:要么手工设计无法适应的进化策略(遗传算法、蒙特卡洛树搜索变体),要么使用适应过度而失去连贯性的LLM智能体。
积累的证据应该告知进化机制本身这一洞见事后看来显而易见,但探索不足。
这处于元学习和程序合成的交叉点,是肥沃的土壤。
方法成熟度: 核心想法——将进化视为环境并编辑机制——很优雅。
但实现感觉像两个独立系统用胶带粘在一起(一个用于基于过程,一个用于基于智能体)。
论文没有深入探索什么构成好的元编辑动作空间,或如何防止元智能体过拟合最近的失败。
这种方法更像是”试试这个”而非”这是有理论保证的原则性框架”。
话虽如此,实证结果表明这个想法有潜力。
实验诚意: 基线合理(EoH、FunSearch、Reflexion、LATS、OpenHands)。
26%的提升是跨基准的综合指标,扎实但不惊艳。
开放式优化任务(代码生成、工作流设计、科学发现)是AEvo的亮点,但论文没有报告方差或失败模式。
我想看:元智能体多久会让事情变糟?性能对元智能体提示词有多敏感?消融研究很薄——没有分解哪些类型的编辑贡献最大。
写作功力: 摘要和引言简洁。
方法部分埋没了重点——图2应该更早出现,基于过程和基于智能体的进化之间的区别需要更清晰的前置动机。
相关工作部分是清单而非叙事。
实验部分前置数字,没有足够的定性分析元智能体学会编辑什么。
重写第4节,以案例研究开头(给我看三个元智能体做的编辑以及为什么有效)会让论文吸引力翻倍。
判决: 弱接收 — 想法扎实,结果有希望,但执行感觉像需要改进的v1.0。
论文打开了新的设计空间(元编辑进化机制)但没有充分探索。
值得发表以播种对话,但我期待后续工作收紧框架并深入挖掘什么让元编辑有效。
要点总结
可操作想法: 将你的优化循环视为一等对象。
如果你在运行任何迭代搜索(超参数调优、提示词工程、架构搜索),不仅记录结果,还要记录你用来生成每个候选方案的策略。
然后定期退后一步问:“我看到什么模式?我应该如何调整搜索策略?“你不需要花哨的元智能体——人类手动做这件事就会胜过盲目迭代。
技术技巧: 过程级状态表示很巧妙。
AEvo不是给元智能体喂原始日志,而是将进化历史压缩成结构化摘要(例如”变异X失败3次,迭代5后多样性下降”)。
如果你在构建任何从自己执行轨迹学习的系统,投资于好的状态压缩。
原始日志太嘈杂;手工特征太脆弱。
学习突出可操作模式的压缩表示。
框架转变: 论文的真正贡献是将进化从”在解空间搜索”重构为”在策略空间搜索”。
这超越了AI:任何迭代优化解的领域(药物发现、工程设计、政策优化)都能从显式建模和改进优化过程本身中受益。
元层面才是杠杆所在。