Paper: 2606.06493 Authors: Lizhi Yang, Junheng Li, Nehar Poddar, Yiling Hou, Gio Huh, Robert Griffin, Georgia Gkioxari, Aaron Ames Categories: cs.RO, cs.AI, cs.LG
The Gap
Existing humanoid whole-body controllers speak the wrong language. Task planners think in terms of “pick up the cup” or “open the drawer,” but controllers demand dense kinematic trajectories—joint angles at every timestep, end-effector poses in 3D space, contact force profiles. It’s like asking someone to describe a walk to the grocery store by specifying the firing pattern of every motor neuron. The planning-control interface is fundamentally mismatched.
Prior approaches tried brute-forcing this gap: either (1) train specialized controllers for each task (doesn’t scale), (2) have planners generate dense reference trajectories (planners aren’t good at low-level motion synthesis), or (3) use high-level commands but sacrifice manipulation precision (can’t do fine-grained tasks). The core tension: expressiveness vs. planability. Dense interfaces are expressive but unplannable. Sparse interfaces are plannable but not expressive enough for real manipulation.
Problem: Planning-Control Interface Mismatch
    |
    v
Assumption: A compact command space CAN be both
            plannable AND expressive if designed right
    |
    v
Method: Define 6D task-space targets + distill
        three specialist teachers into one student
    |
    v
Evidence: Matches SOTA tracking, largest manipulation
          workspace, zero-shot VLM-driven tasks on hardware
    |
    v
Conclusion: Task-space interface bridges semantic
            planning and low-level control
The Increment
One sentence: Before HANDOFF, you needed different controllers for walking, manipulating, and recovering from falls—now one policy handles all three via a compact 6D command interface that planners can actually use.
Core Mechanism
HANDOFF defines a command interface with just six numbers: 3D position and 3D orientation for key body parts (hands, pelvis, torso). That’s it. No joint angles, no dense trajectories. A planner says “left hand to (0.5, 0.3, 1.2) facing down” and the controller figures out the full-body motion.
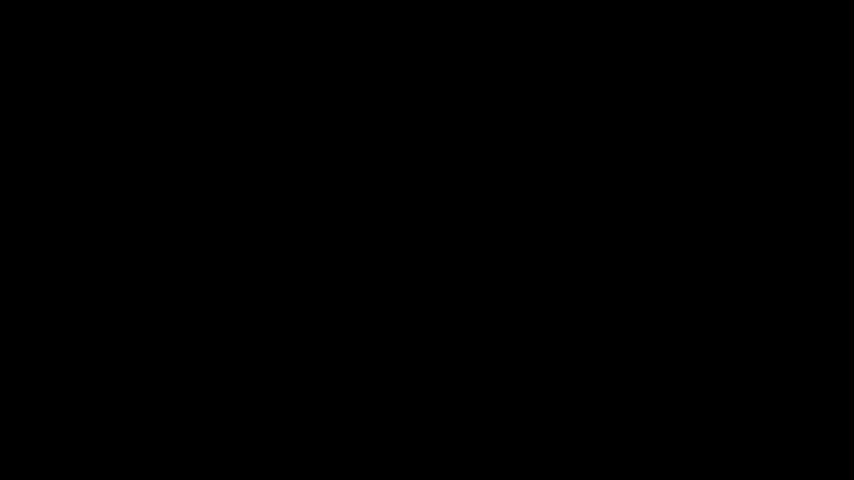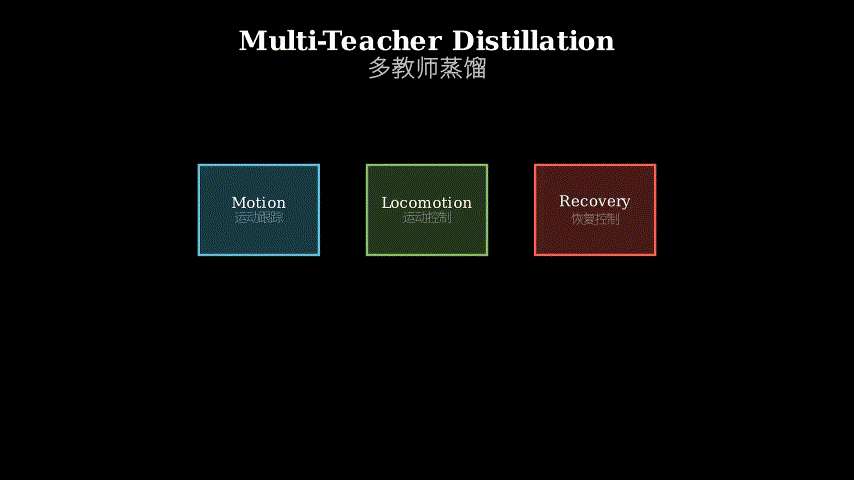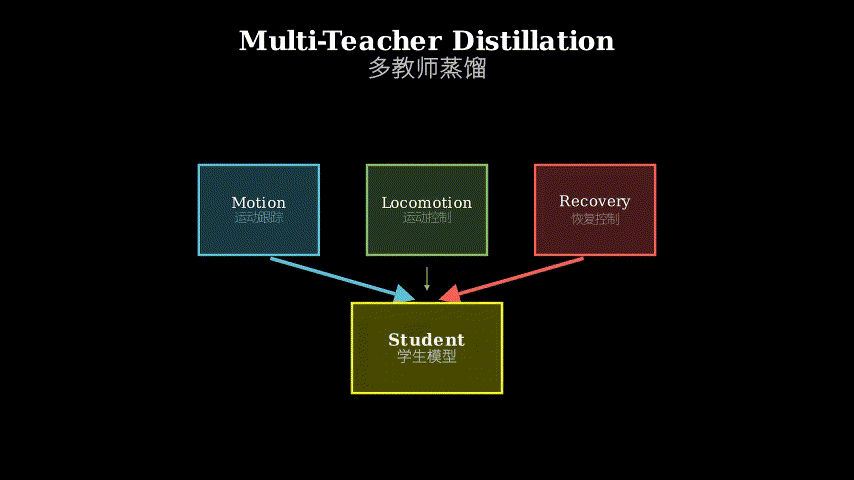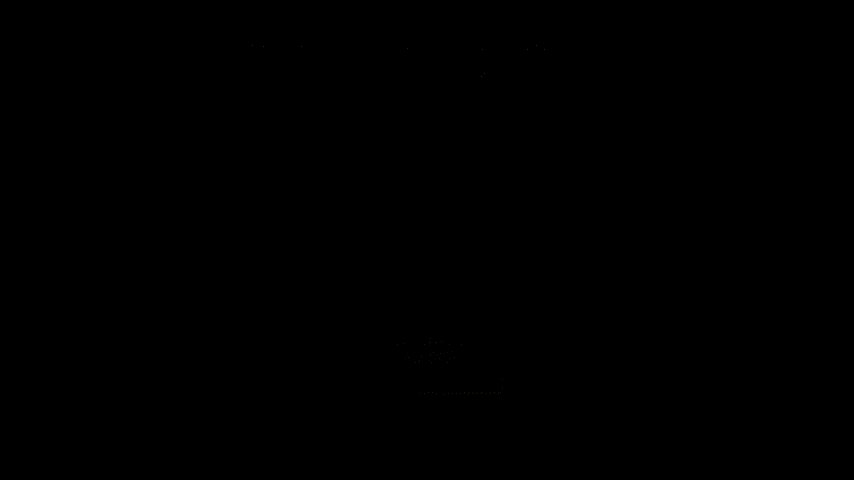
To build a controller that responds to these commands robustly, the authors train three specialist teachers: (1) a motion-tracking expert that follows reference data with safety constraints, (2) a locomotion expert for stable walking, (3) a fall-recovery expert. Each teacher has its own training regime and excels in its domain. Then they distill all three into a single student policy via multi-teacher KL distillation with context-conditioned gating. The gating network looks at the current command and robot state, then blends teacher distributions—mostly tracking during manipulation, mostly locomotion during walking, mostly fall-recovery when tipping over.
Command Interface (6D task-space targets)
    |
    v
   [Context: state + command]
    |
    +---> Gating Network
    |         |
    |         v
    |    [w1, w2, w3] (teacher weights)
    |         |
    +----+----+----+
    |    |    |    |
    v    v    v    v
Teacher1 Teacher2 Teacher3
(track) (walk)  (recover)
    |    |    |
    +----+----+
         |
         v
    Student Policy
    (outputs joint torques)
Think of HANDOFF like a restaurant kitchen with three specialized chefs and one expeditor. The motion-tracking chef is a perfectionist—trained on carefully curated demos, knows every recipe by heart, but panics under pressure. The locomotion chef handles the grill—steady, robust, keeps things moving even when orders pile up. The fall-recovery chef is the closer—comes in when everything’s going wrong and salvages the meal.
The expeditor (gating network) reads each order (command + state) and decides which chef should lead. “Table 5 wants precision plating”—motion chef takes point. “Rush order, need it walking out fast”—locomotion chef leads. “Dropped a pan, kitchen’s on fire”—fall-recovery chef takes over. The expeditor doesn’t have the skills of any individual chef, but knows when to defer to each specialist. Over time (via distillation), the expeditor internalizes enough of each chef’s moves to coordinate smoothly without constantly checking back.
The key insight: you don’t need one superhuman chef. You need specialization + smart coordination. Each teacher trains in its comfort zone with data suited to its strengths. The student learns when to trust which teacher, blending their strengths into a unified response.
Key Concepts
-
Task-space control: Instead of controlling joint angles directly (configuration space), you specify where you want end-effectors or body parts to be in 3D Cartesian space. The controller then solves for joint configurations that achieve those targets. It’s the difference between telling a robot “bend elbow 45°, rotate shoulder 30°” versus “put your hand on the table.” Task-space is intuitive and compositional—you can specify independent goals for different body parts without worrying about joint coupling. The challenge: task-space targets underconstrain the full robot state (many joint configurations can achieve the same hand position), so the controller must also handle secondary objectives like balance, collision avoidance, and joint limits. HANDOFF’s 6D interface (position + orientation for key parts) is task-space, which is why planners can synthesize commands without deep kinematics knowledge.
-
Knowledge distillation: Training a student network to mimic a teacher network’s behavior. Standard distillation uses one teacher; multi-teacher distillation blends multiple teachers. The student minimizes KL divergence between its output distribution and a weighted combination of teacher distributions. Why bother? Teachers can be slow, specialized, or impractical for deployment. The student is fast, general, and deployable. In HANDOFF, each teacher is an expert trained with different data or objectives (tracking clean demos, walking robustly, recovering from falls). The student learns to approximate all three, gated by context, into one policy. The distillation isn’t lossless—the student won’t perfectly match any single teacher—but it gets “good enough” across all domains without needing explicit task identification or controller switching at runtime.
-
Safety filtering: Before using motion-capture data to train the tracking teacher, HANDOFF filters out unsafe states—configurations where the robot is close to joint limits, self-collision, or kinematically infeasible poses. This is crucial because human motion data often contains states unreachable by the robot (humans have different kinematics and mass distribution). Training on raw mocap would teach the policy to chase impossible targets, leading to instability. Safety filtering is a preprocessing step: run inverse kinematics on mocap, check constraints, keep only feasible clips. The tracking teacher then learns from a cleaned dataset, so it never tries to imitate physically impossible moves. The tradeoff: you lose some expressiveness (can’t do every human motion), but gain stability (the policy stays within safe operating bounds).
Framework Shift
Before (mainstream approach):        After (HANDOFF):

  Task Planner                         Task Planner
       |                                    |
       v                                    v
  [dense trajectories]                [6D task-space targets]
   joint angles x T steps               (hand pos/ori, pelvis, torso)
       |                                    |
       v                                    v
  Task-Specific Controller    Single Context-Gated Controller
  (walk controller,            (gating -> teacher weights ->
   manip controller,            student action)
   recovery controller)              |
       |                             v
       +---> switch manually    [unified action output]
       |
       v
  [action output per task]
One sentence: From task-specific controllers with dense planner interfaces to one unified controller with a compact, semantic interface.
Expert Assessment
Problem choice: Real and well-motivated. The planning-control interface is a genuine bottleneck in deploying humanoids beyond scripted demos. Prior work either sacrificed generality (task-specific controllers) or precision (overly coarse commands). Positioning this as an interface design problem, not just a controller architecture problem, is sharp thinking.
Method maturity: Solid engineering with one clever insight (context-gated multi-teacher distillation) and one pragmatic choice (6D task-space interface). The gating scheme is elegant—learn when to trust which teacher rather than hand-coding mode switches. However, the paper leans heavily on three strong teachers. If any teacher is weak, the student inherits that weakness. The motion-tracking teacher requires safety-filtered mocap, which is labor-intensive to curate. The method works but isn’t radically simpler than prior approaches—it shifts complexity from runtime switching to training-time distillation.
Experimental integrity: Fair baselines, honest numbers. The velocity tracking comparison (Figure 4) shows HANDOFF matches but doesn’t exceed SOTA, which is refreshing honesty. The manipulation workspace claim (Figure 5) is strong and well-visualized. Hardware demos (Figure 6) are diverse and demonstrate zero-shot generalization from VLM commands, though we don’t see failure modes or how often it works versus fails. One red flag: no ablation on gating. How much does context-conditioned gating help versus uniform teacher weighting? The paper would be stronger with a “no gating” baseline to isolate the contribution of the gating network versus just ensemble distillation.
Writing quality: Clear and well-structured. The interface design motivation (Section 3.1) is excellent. The related work section efficiently positions the contribution. However, Section 4.3 (training details) is dense and rushed—key hyperparameters buried in text rather than a table. The hardware experiments (Section 5.2) feel undercooked—seven task roll-outs shown, but no statistics on success rates, no discussion of what the VLM planner struggles with. Rewriting Section 5 with more quantitative rigor (success rates, failure analysis, timing breakdowns) would elevate the paper significantly.
Verdict: Weak accept — Strong problem framing and solid execution, but missing ablations and undercooked hardware evaluation prevent this from being a clear accept. The core idea (compact interface + gated distillation) is useful, but the paper doesn’t fully characterize when it works versus when it breaks.
Takeaways
For roboticists: The 6D task-space interface (position + orientation for key body parts) is immediately reusable. It’s plannable, modular, and expressive enough for diverse manipulation. If you’re building a humanoid system, this interface beats dense joint trajectories or end-effector-only commands.
For ML practitioners: Context-conditioned gating for multi-teacher distillation is a clean trick. Instead of training separate models or hand-coding mode switches, learn a gating network that blends teacher distributions based on input context. This scales to domains beyond robotics—anywhere you have multiple specialists and want one unified model.
For system builders: The separation of concerns (teachers train in their comfort zone, student learns coordination) is architecturally clean. You can iterate on individual teachers (e.g., improve fall-recovery with new data) without retraining the whole system, then re-distill. The modular teacher-student structure makes the system evolvable.
What NOT to steal: The safety filtering pipeline is paper-specific. Unless you’re training on human mocap for humanoid tracking, you don’t need it. The VLM agentic planner (Section 5.2) is underspecified—cool demo, but not enough detail to reproduce.
论文: 2606.06493 作者: Lizhi Yang, Junheng Li, Nehar Poddar, Yiling Hou, Gio Huh, Robert Griffin, Georgia Gkioxari, Aaron Ames 分类: cs.RO, cs.AI, cs.LG
缺口
现有的人形机器人全身控制器说的是”错误的语言”。
任务规划器思考的是”拿起杯子”或”打开抽屉”,但控制器要求的是密集的运动学轨迹——每个时间步的关节角度、3D空间中的末端执行器位姿、接触力分布。
这就像要求某人通过指定每个运动神经元的放电模式来描述去杂货店的路线。
规划-控制接口存在根本性的不匹配。
先前的方法试图暴力解决这个鸿沟:要么(1)为每个任务训练专用控制器(不可扩展),要么(2)让规划器生成密集参考轨迹(规划器不擅长低级运动合成),要么(3)使用高级指令但牺牲操作精度(无法完成精细任务)。
核心张力在于:表达力与可规划性。
密集接口表达力强但无法规划。
稀疏接口可规划但对真实操作任务表达力不足。
问题:规划-控制接口不匹配
    |
    v
假设:紧凑的指令空间可以同时做到
      可规划和有表达力(如果设计得当)
    |
    v
方法:定义6D任务空间目标 + 将三个
      专家教师蒸馏成一个学生策略
    |
    v
证据:匹配最优跟踪性能,最大的操作
      工作空间,硬件上零样本VLM驱动任务
    |
    v
结论:任务空间接口弥合了语义
      规划和低级控制之间的鸿沟
增量
一句话:HANDOFF之前,你需要不同的控制器来行走、操作和从跌倒中恢复——现在一个策略通过规划器能实际使用的紧凑6D指令接口处理所有三种情况。
核心机制
HANDOFF定义了一个只有六个数字的指令接口:关键身体部位(手、骨盆、躯干)的3D位置和3D方向。
就这些。
没有关节角度,没有密集轨迹。
规划器说”左手到(0.5, 0.3, 1.2)朝下”,控制器计算出全身运动。
为了构建一个对这些指令做出鲁棒响应的控制器,作者训练了三个专家教师:(1)带安全约束的运动跟踪专家,跟随参考数据; (2)用于稳定行走的运动专家; (3)跌倒恢复专家。
每个教师都有自己的训练方案,在各自领域表现出色。
然后他们通过上下文条件门控方案下的多教师KL蒸馏将所有三者蒸馏成单一学生策略。
门控网络查看当前指令和机器人状态,然后混合教师分布——操作时主要跟踪,行走时主要运动,倾倒时主要跌倒恢复。
指令接口(6D任务空间目标)
    |
    v
   [上下文:状态 + 指令]
    |
    +---> 门控网络
    |         |
    |         v
    |    [w1, w2, w3](教师权重)
    |         |
    +----+----+----+
    |    |    |    |
    v    v    v    v
教师1  教师2  教师3
(跟踪)(行走)(恢复)
    |    |    |
    +----+----+
         |
         v
    学生策略
    (输出关节力矩)
把HANDOFF想象成一个有三位专业厨师和一位传菜员的餐厅厨房。
运动跟踪厨师是完美主义者——在精心策划的演示上训练,烂熟于心每个菜谱,但压力下会惊慌失措。
运动厨师负责烤架——稳定、强健,即使订单堆积也能保持运转。
跌倒恢复厨师是收尾者——当一切出错时介入并挽救局面。
传菜员(门控网络)读取每个订单(指令+状态)并决定哪位厨师应该主导。
“5号桌想要精致摆盘”——运动厨师担纲。
“急单,需要快速上菜”——运动厨师领衔。
“掉了锅,厨房着火了”——跌倒恢复厨师接管。
传菜员没有任何单个厨师的技能,但知道何时求助于每位专家。
随着时间推移(通过蒸馏),传菜员内化了每位厨师的足够动作,可以流畅协调而无需不断回查。
关键洞察:你不需要一个超人厨师。
你需要专业化+智能协调。
每个教师在其舒适区用适合其优势的数据训练。
学生学习何时信任哪个教师,将他们的优势混合成统一响应。
关键概念
- 任务空间控制:与直接控制关节角度(构型空间)不同,你指定希望末端执行器或身体部位在3D笛卡尔空间中的位置。
控制器然后求解实现这些目标的关节配置。
这就像告诉机器人”把手放在桌子上”和”弯曲肘部45°、旋转肩膀30°“的区别。
任务空间直观且可组合——你可以为不同身体部位指定独立目标,而无需担心关节耦合。
挑战在于:任务空间目标欠约束完整机器人状态(许多关节配置可以实现相同的手部位置),因此控制器还必须处理次要目标,如平衡、碰撞避免和关节限制。
HANDOFF的6D接口(关键部位的位置+方向)是任务空间的,这就是规划器无需深入运动学知识就能合成指令的原因。
- 知识蒸馏:训练学生网络模仿教师网络的行为。
标准蒸馏使用一个教师; 多教师蒸馏混合多个教师。
学生最小化其输出分布与教师分布加权组合之间的KL散度。
为什么要这样做? 教师可能很慢、专业化或不适合部署。
学生快速、通用且可部署。
在HANDOFF中,每个教师都是用不同数据或目标训练的专家(跟踪干净演示、鲁棒行走、从跌倒中恢复)。
学生学习将所有三者近似为一个策略,由上下文门控。
蒸馏不是无损的——学生不会完美匹配任何单个教师——但在所有领域都”足够好”,无需在运行时进行显式任务识别或控制器切换。
- 安全过滤:在使用动作捕捉数据训练跟踪教师之前,HANDOFF过滤掉不安全状态——机器人接近关节限制、自碰撞或运动学上不可行的姿态的配置。
这至关重要,因为人类运动数据通常包含机器人无法到达的状态(人类有不同的运动学和质量分布)。
在原始动捕数据上训练会教策略追逐不可能的目标,导致不稳定。
安全过滤是一个预处理步骤:对动捕运行逆运动学,检查约束,只保留可行片段。
跟踪教师然后从清理过的数据集学习,因此它永远不会尝试模仿物理上不可能的动作。
权衡:你失去了一些表达力(无法做所有人类动作),但获得了稳定性(策略保持在安全操作范围内)。
框架转变
之前(主流方法):                之后(HANDOFF):

  任务规划器                        任务规划器
       |                                |
       v                                v
  [密集轨迹]                       [6D任务空间目标]
   关节角度 x T步                  (手部位置/方向,骨盆,躯干)
       |                                |
       v                                v
  任务特定控制器              单一上下文门控控制器
  (行走控制器,                (门控 -> 教师权重 ->
   操作控制器,                 学生动作)
   恢复控制器)                      |
       |                             v
       +---> 手动切换           [统一动作输出]
       |
       v
  [每任务动作输出]
一句话:从具有密集规划器接口的任务特定控制器到具有紧凑语义接口的统一控制器。
专家评审
选题眼光:真实且动机充分。
规划-控制接口确实是在脚本演示之外部署人形机器人的真正瓶颈。
先前的工作要么牺牲通用性(任务特定控制器),要么牺牲精度(过于粗糙的指令)。
将此定位为接口设计问题而非仅仅控制器架构问题,是敏锐的思考。
方法成熟度:扎实的工程加上一个聪明的洞察(上下文门控多教师蒸馏)和一个务实的选择(6D任务空间接口)。
门控方案优雅——学习何时信任哪个教师,而不是手工编码模式切换。
然而,论文严重依赖三个强教师。
如果任何教师较弱,学生会继承该弱点。
运动跟踪教师需要安全过滤的动捕数据,这是劳动密集型的策划工作。
该方法有效但并不比先前方法简单得多——它将复杂性从运行时切换转移到训练时蒸馏。
实验诚意:公平的基线,诚实的数字。
速度跟踪比较(图4)显示HANDOFF匹配但未超过最优水平,这是令人耳目一新的诚实。
操作工作空间声明(图5)强大且可视化良好。
硬件演示(图6)多样化,展示了从VLM指令的零样本泛化,尽管我们没有看到失败模式或它成功与失败的频率。
一个危险信号:没有门控的消融实验。
上下文条件门控相比统一教师加权有多大帮助? 论文如果有”无门控”基线来隔离门控网络的贡献与集成蒸馏会更强。
写作功力:清晰且结构良好。
接口设计动机(3.1节)出色。
相关工作部分有效地定位了贡献。
然而,4.3节(训练细节)密集且仓促——关键超参数埋在文本中而不是表格中。
硬件实验(5.2节)感觉未充分展开——展示了七个任务展开,但没有成功率统计,没有讨论VLM规划器的困难之处。
重写第5节使其具有更多定量严谨性(成功率、失败分析、时间分解)将显著提升论文水平。
判决:弱接收 — 强问题框架和扎实执行,但缺少消融实验和不够充分的硬件评估阻止这成为明确接收。
核心想法(紧凑接口+门控蒸馏)有用,但论文没有完全描述它何时有效与何时失效。
要点总结
对机器人研究者:6D任务空间接口(关键身体部位的位置+方向)可立即重用。
它可规划、模块化,且对多样化操作具有足够表达力。
如果你正在构建人形机器人系统,这个接口优于密集关节轨迹或仅末端执行器指令。
对机器学习实践者:用于多教师蒸馏的上下文条件门控是一个干净的技巧。
与其训练单独模型或手工编码模式切换,不如学习一个基于输入上下文混合教师分布的门控网络。
这可扩展到机器人技术之外的领域——任何你有多个专家并希望一个统一模型的地方。
对系统构建者:关注点分离(教师在其舒适区训练,学生学习协调)在架构上是干净的。
你可以迭代单个教师(例如,用新数据改进跌倒恢复)而无需重新训练整个系统,然后重新蒸馏。
模块化的教师-学生结构使系统可演化。
不要偷的东西:安全过滤流程是特定于论文的。
除非你在为人形跟踪在人类动捕上训练,否则你不需要它。
VLM代理规划器(5.2节)规格不足——很酷的演示,但没有足够细节来复现。