
Paper: 2603.05465 Authors: Sai Akhil Kogilathota, Sripadha Vallabha E G, Luzhe Sun, Jiawei Zhou Categories: cs.CV
The Gap
Vision-language models confidently describe things that aren’t there. Show them a photo of a dog, they might tell you about a cat. Ask about a street scene, they’ll invent pedestrians. Current hallucination detection methods—like CHAIR, POPE, or self-consistency checks—all share a fatal flaw: they wait until after the model has generated text. By then, you’ve already paid the computational cost of decoding, and the damage is done. Some approaches try to fix hallucinations mid-generation using contrastive decoding or attention manipulation, but these still require partial generation and add overhead to every token.
The core question nobody had answered: can you tell if a model is about to hallucinate before it outputs anything?
Problem: VLMs hallucinate + detection happens post-generation
   |
   v
Assumption: Hallucination risk is encoded in pre-generation states
   |
   v
Method: Train probes on internal representations (visual/vision-token/query-token)
   |
   v
Evidence: 0.93 AUROC on multiple models without decoding
   |
   v
Conclusion: Pre-generation detection is viable + layer/modality varies by architecture
The Increment
One sentence: Before this paper, you had to generate text to detect hallucinations; after it, you can predict hallucination risk from a single forward pass before any decoding.
Core Mechanism
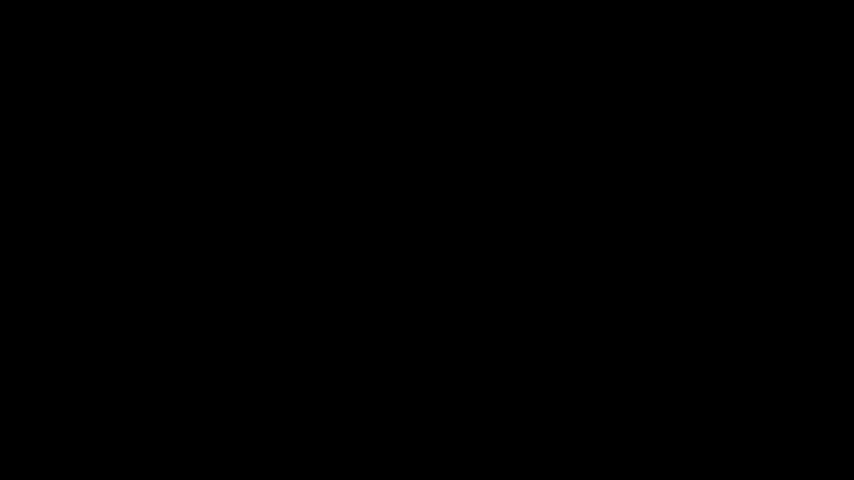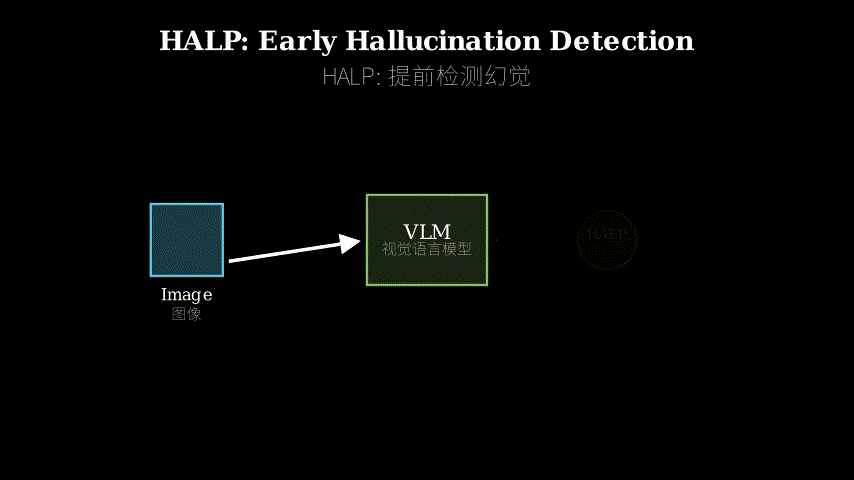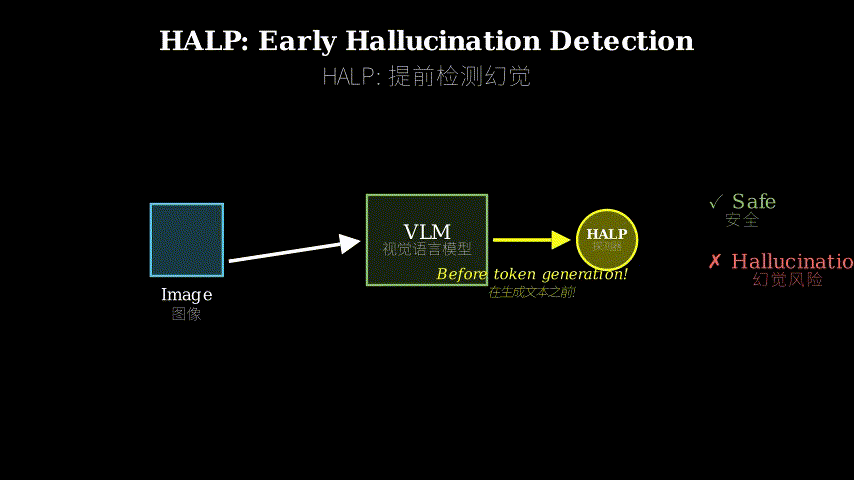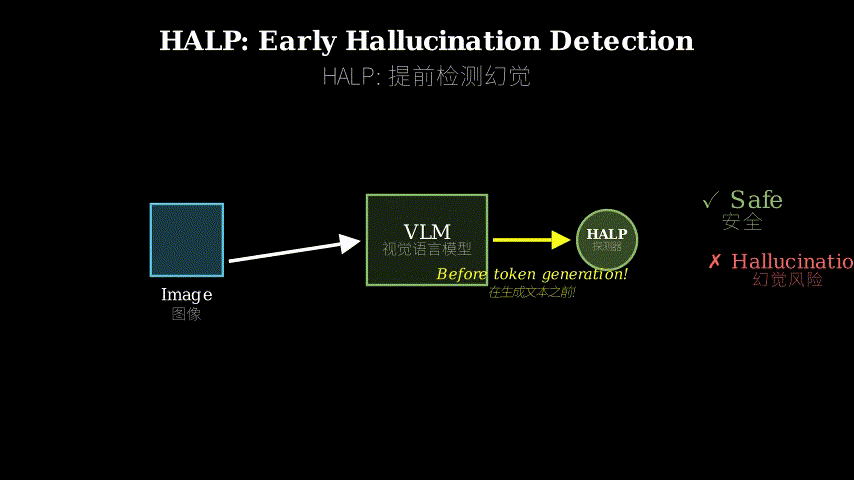
HALP extracts three types of internal representations from vision-language models and trains lightweight classifiers on them. First, visual-only features come straight from the vision encoder before any text interaction—these are the raw visual embeddings. Second, vision-token representations are extracted from within the text decoder after visual information has been projected into the language model’s space. Third, query-token representations capture the fused state right before generation begins, where the model has processed both the image and the input query.
For each representation type, the authors extract features at multiple layers (early, middle, late) and train simple probes—logistic regression or small MLPs—to classify whether the model will hallucinate on a given input. The training data comes from existing hallucination benchmarks where ground truth labels indicate whether a model’s response contains fabricated content.
Image + Query
    |
    v
[Vision Encoder] -----> (i) Visual-only features
    |                        |
    v                        v
[Projection] -----> (ii) Vision-token repr.    [Probe]
    |                        |                     |
    v                        v                     v
[Text Decoder] ---> (iii) Query-token repr. --> Hallucination
    |                                            prediction
    v
[Generation] <--- (we never reach here)
Think of it like airport security screening. Traditional methods are like checking passengers after they’ve boarded the plane—you catch problems, but the flight is already delayed. HALP is the metal detector at the entrance: it scans internal “signals” (representations) before anyone gets on board (before generation). The visual-only features are like checking someone’s ID photo—pure visual information. Vision-token representations are like checking their boarding pass after it’s been stamped—visual info that’s been processed into the system’s format. Query-token representations are like the final security checkpoint where they’ve shown both ID and boarding pass and are about to enter the gate—the last moment before the irreversible action (generation) begins. The probe is the security officer who’s learned to spot suspicious patterns in these signals.
Key Concepts
-
Internal Representations: When a vision-language model processes an image and query, it doesn’t jump straight to generating text. Instead, it builds up layers of internal understanding—numerical vectors that encode what the model “thinks” about the input at different stages. Early layers might capture basic visual features like edges and colors. Middle layers might recognize objects. Late layers integrate visual and textual context to prepare for generation. These representations are like the model’s internal notes before it commits to an answer. The key insight: if the model is confused or uncertain (hallucination-prone), that confusion shows up in these internal states before any text appears.
-
Probing: Instead of trying to interpret what these internal representations mean directly, you train a simple classifier—a probe—to predict outcomes from them. It’s like training a dog to sniff for drugs without teaching it chemistry. You show the probe thousands of examples: “when the internal state looks like this, the model hallucinated; when it looks like that, it didn’t.” The probe learns patterns that correlate with hallucination risk. Crucially, probes are lightweight (logistic regression or tiny neural nets), so they add minimal overhead. They’re diagnostic tools, not part of the main model.
-
Pre-generation Detection: Traditional approaches are reactive—they analyze generated text for inconsistencies or check it against the image. Pre-generation detection is predictive—it assesses risk before committing to generation. Imagine a chess player who can tell they’re about to blunder before moving the piece, versus one who only realizes after the move is made. The practical win: you can abort generation early, route the query to a more reliable model, or switch to a safer decoding strategy—all before wasting compute on a doomed output.
Framework Shift
Before (mainstream approach):        After (this paper):

Image + Query                        Image + Query
    |                                    |
    v                                    v
[VLM generates text]                 [Single forward pass]
    |                                    |
    v                                    v
"The cat is on the mat"              [Extract internal repr.]
    |                                    |
    v                                    v
[Post-hoc detection]                 [Probe predicts risk]
    |                                    |
    v                                    v
"Wait, there's no cat!"              "High hallucination risk"
    |                                    |
    v                                    v
(too late, already generated)        (abort or reroute)
From post-mortem analysis to pre-flight risk assessment, the core shift is moving the detection boundary from after generation to before it.
Expert Assessment
Problem choice: This is a real gap with practical stakes. Hallucination detection is a bottleneck for deploying VLMs in high-stakes domains (medical imaging, autonomous vehicles, accessibility tools). Post-generation detection is expensive and doesn’t prevent bad outputs from being generated in the first place. The timing is right—VLMs are mature enough that people care about reliability, not just capability.
Method maturity: The approach is refreshingly simple—train probes on internal states. No architectural changes, no complex decoding schemes. The insight is clever: hallucination risk should be detectable in the model’s “uncertainty” before it commits. However, the paper doesn’t deeply investigate why certain layers work better for certain architectures. The probe design is basic (logistic regression, small MLPs), which is fine for a proof of concept but leaves room for more sophisticated uncertainty quantification methods.
Experimental integrity: The evaluation spans eight models and multiple benchmarks (POPE, CHAIR, MMHal-Bench), which is solid coverage. The AUROC numbers are strong (0.93 on some models), but there’s a catch: performance varies wildly by architecture (0.79 on Qwen2.5-VL vs 0.93 on Gemma-3). The paper acknowledges this but doesn’t fully explain it—are some architectures inherently more “readable” for probing? The baselines are fair (comparing against post-generation methods), but I’d want to see ablations on probe complexity and training data size. One red flag: no discussion of adversarial robustness—can you fool the probe by crafting inputs that look safe internally but still hallucinate?
Writing quality: The abstract and intro are crisp. The method section is clear but could use more intuition about why different representation types matter. The results section is thorough but repetitive—tables could be condensed. The biggest missed opportunity: no failure analysis. When does the probe fail? What kinds of hallucinations slip through? A single figure showing failure modes would make this paper twice as useful.
Verdict: weak accept — Solid empirical contribution with practical value, but lacks depth in explaining architectural variance and failure modes.
Takeaways
The transferable idea: internal representations encode uncertainty before it manifests in output. This applies beyond hallucination detection. You could probe for toxicity risk before generating offensive text, factual errors before answering questions, or reasoning failures before solving math problems. The key is identifying the right layer and modality for your architecture—this paper shows it’s not universal (late query tokens work for most models, but not all).
Concrete technique: if you’re deploying a VLM in production, train a lightweight probe on your specific model and task. Collect a dataset of (input, did_it_hallucinate) pairs, extract internal states at multiple layers, and train a classifier. Use it as a gatekeeper: high-risk queries get routed to a more expensive but reliable model, or trigger human review. The computational overhead is minimal (one forward pass + probe inference), and you avoid generating garbage in the first place.
The architectural insight: where hallucination risk lives varies by model design. If your VLM has a strong vision encoder, visual-only features might be predictive. If it relies heavily on cross-modal fusion, query tokens are your best bet. Don’t assume one size fits all—profile your model.
论文: 2603.05465 作者: Sai Akhil Kogilathota, Sripadha Vallabha E G, Luzhe Sun, Jiawei Zhou 分类: cs.CV
缺口
视觉语言模型会自信地描述不存在的东西。
给它看一张狗的照片,它可能告诉你有只猫。
问它街景里有什么,它会凭空编造出行人。
当前的幻觉检测方法——比如CHAIR、POPE或自洽性检查——都有一个致命缺陷:它们等到模型生成文本之后才开始工作。
到那时,你已经付出了解码的计算成本,损害已经造成。
有些方法试图在生成过程中通过对比解码或注意力操控来修复幻觉,但这些仍然需要部分生成,并且给每个token都增加了开销。
核心问题一直没人回答:能否在模型输出任何东西之前就判断它是否会产生幻觉?
问题: VLM产生幻觉 + 检测发生在生成之后
   |
   v
假设: 幻觉风险编码在生成前的状态中
   |
   v
方法: 在内部表征上训练探针(视觉/视觉token/查询token)
   |
   v
证据: 多个模型上达到0.93 AUROC,无需解码
   |
   v
结论: 生成前检测可行 + 层级/模态因架构而异
增量
一句话: 这篇论文之前,你必须生成文本才能检测幻觉;之后,你可以在任何解码之前通过单次前向传播预测幻觉风险。
核心机制
HALP从视觉语言模型中提取三类内部表征,并在其上训练轻量级分类器。
首先,纯视觉特征直接来自视觉编码器,在任何文本交互之前——这些是原始的视觉嵌入。
其次,视觉token表征从文本解码器内部提取,此时视觉信息已经被投影到语言模型的空间中。
第三,查询token表征捕获生成开始前的融合状态,此时模型已经处理了图像和输入查询。
对于每种表征类型,作者在多个层级(早期、中期、晚期)提取特征,并训练简单的探针——逻辑回归或小型MLP——来分类模型在给定输入上是否会产生幻觉。
训练数据来自现有的幻觉基准测试,其中真实标签指示模型的响应是否包含虚构内容。
图像 + 查询
    |
    v
[视觉编码器] -----> (i) 纯视觉特征
    |                        |
    v                        v
[投影层] -----> (ii) 视觉token表征    [探针]
    |                        |                     |
    v                        v                     v
[文本解码器] ---> (iii) 查询token表征 --> 幻觉预测
    |
    v
[生成] <--- (我们永远不会到达这里)
把它想象成机场安检。
传统方法就像在乘客登机后才检查——你能发现问题,但航班已经延误了。
HALP是入口处的金属探测器:它在任何人登机(生成)之前扫描内部”信号”(表征)。
纯视觉特征就像检查某人的身份证照片——纯粹的视觉信息。
视觉token表征就像检查盖过章的登机牌——已被处理成系统格式的视觉信息。
查询token表征就像最后的安检关口,他们已经出示了身份证和登机牌,即将进入登机口——这是不可逆行动(生成)开始前的最后时刻。
探针就是那个学会从这些信号中识别可疑模式的安检员。
关键概念
- 内部表征: 当视觉语言模型处理图像和查询时,它不会直接跳到生成文本。
相反,它会逐层构建内部理解——编码模型在不同阶段对输入”想法”的数值向量。
早期层可能捕获边缘和颜色等基本视觉特征。
中间层可能识别物体。
晚期层整合视觉和文本上下文,为生成做准备。
这些表征就像模型在给出答案之前的内部笔记。
关键洞察:如果模型困惑或不确定(容易产生幻觉),这种困惑会在任何文本出现之前就显现在这些内部状态中。
- 探针技术: 与其试图直接解释这些内部表征的含义,不如训练一个简单的分类器——探针——从中预测结果。
这就像训练狗嗅毒品而不教它化学。
你给探针展示成千上万个例子:“当内部状态看起来像这样时,模型产生了幻觉;当看起来像那样时,没有。“探针学习与幻觉风险相关的模式。
关键是,探针是轻量级的(逻辑回归或微型神经网络),所以它们增加的开销很小。
它们是诊断工具,不是主模型的一部分。
- 生成前检测: 传统方法是被动的——它们分析生成的文本是否存在不一致或对照图像检查。
生成前检测是预测性的——它在提交生成之前评估风险。
想象一个国际象棋选手能在移动棋子之前就知道自己要犯错,而不是移动后才意识到。
实际收益:你可以提前中止生成,将查询路由到更可靠的模型,或切换到更安全的解码策略——所有这些都在浪费计算资源生成注定失败的输出之前完成。
框架转变
之前(主流方法):                  之后(本文方法):

图像 + 查询                      图像 + 查询
    |                                |
    v                                v
[VLM生成文本]                    [单次前向传播]
    |                                |
    v                                v
"猫在垫子上"                     [提取内部表征]
    |                                |
    v                                v
[事后检测]                       [探针预测风险]
    |                                |
    v                                v
"等等,没有猫!"                   "高幻觉风险"
    |                                |
    v                                v
(太晚了,已经生成)                (中止或重新路由)
从事后分析到起飞前风险评估,核心转变是将检测边界从生成之后移到生成之前。
专家评审
选题眼光: 这是一个有实际意义的真缺口。
幻觉检测是在高风险领域(医学影像、自动驾驶、辅助工具)部署VLM的瓶颈。
生成后检测成本高昂,而且无法阻止糟糕的输出被生成出来。
时机恰当——VLM已经足够成熟,人们开始关心可靠性,而不仅仅是能力。
方法成熟度: 方法令人耳目一新地简单——在内部状态上训练探针。
无需架构改变,无需复杂的解码方案。
洞察很巧妙:幻觉风险应该在模型”提交”之前的”不确定性”中可检测。
然而,论文没有深入研究为什么某些层级对某些架构效果更好。
探针设计很基础(逻辑回归、小型MLP),这对概念验证来说没问题,但为更复杂的不确定性量化方法留下了空间。
实验诚意: 评估涵盖八个模型和多个基准测试(POPE、CHAIR、MMHal-Bench),覆盖面相当扎实。
AUROC数字很强(某些模型上达到0.93),但有个问题:性能因架构而异(Qwen2.5-VL上0.79 vs Gemma-3上0.93)。
论文承认了这一点但没有充分解释——是某些架构天生更”可读”以供探测吗?基线是公平的(与生成后方法比较),但我想看到关于探针复杂度和训练数据规模的消融实验。
一个警示信号:没有讨论对抗鲁棒性——你能通过精心设计看起来内部安全但仍会产生幻觉的输入来欺骗探针吗?
写作功力: 摘要和引言简洁明了。
方法部分清晰但可以增加更多关于为什么不同表征类型重要的直觉。
结果部分详尽但重复——表格可以压缩。
最大的遗憾:没有失败分析。
探针什么时候失败?什么样的幻觉会漏网?一张展示失败模式的图就能让这篇论文的实用性翻倍。
判决: 弱接收 — 扎实的实证贡献,有实用价值,但在解释架构差异和失败模式方面缺乏深度。
要点总结
可迁移的想法:内部表征在不确定性表现为输出之前就对其进行了编码。
这适用于幻觉检测之外的场景。
你可以在生成冒犯性文本之前探测毒性风险,在回答问题之前探测事实错误,或在解决数学问题之前探测推理失败。
关键是为你的架构识别正确的层级和模态——本文表明这不是通用的(晚期查询token对大多数模型有效,但不是全部)。
具体技术:如果你在生产环境中部署VLM,在你的特定模型和任务上训练一个轻量级探针。
收集一个(输入,是否产生幻觉)对的数据集,在多个层级提取内部状态,并训练一个分类器。
将其用作守门员:高风险查询被路由到更昂贵但更可靠的模型,或触发人工审查。
计算开销很小(一次前向传播+探针推理),而且你从一开始就避免了生成垃圾。
架构洞察:幻觉风险存在的位置因模型设计而异。
如果你的VLM有强大的视觉编码器,纯视觉特征可能具有预测性。
如果它严重依赖跨模态融合,查询token是你的最佳选择。
不要假设一刀切——对你的模型进行剖析。