
Paper: 2603.15583 Authors: Junyoung Seo, Hyunwook Choi, Minkyung Kwon, Jinhyeok Choi, Siyoon Jin, Gayoung Lee, Junho Kim, JoungBin Lee, Geonmo Gu, Dongyoon Han Categories: cs.CV
The Gap
Existing world models like GAIA-1, DriveDreamer, and GenAD synthesize driving videos by imagining everything from scratch. They produce visually plausible scenes but these environments are entirely artificial—the buildings, streets, and landmarks don’t correspond to any real location. This limits their utility for applications requiring spatial fidelity: autonomous vehicle testing in specific cities, urban planning simulations, or location-aware scenario generation. The fundamental limitation is that prior models operate in a vacuum, disconnected from geographic reality.
Problem: Synthetic world models lack spatial grounding
   |
   v
Assumption: Real street-view images can anchor generation
   |
   v
Method: Retrieval-augmented conditioning + temporal alignment
   |
   v
Evidence: Outperforms baselines on spatial fidelity across 3 cities
   |
   v
Conclusion: Real-world grounding enables city-scale simulation
The Increment
One sentence: Before this paper, world models imagined plausible but fictional environments; after, they can render videos of actual cities by anchoring generation to retrieved street-view images.
Core Mechanism
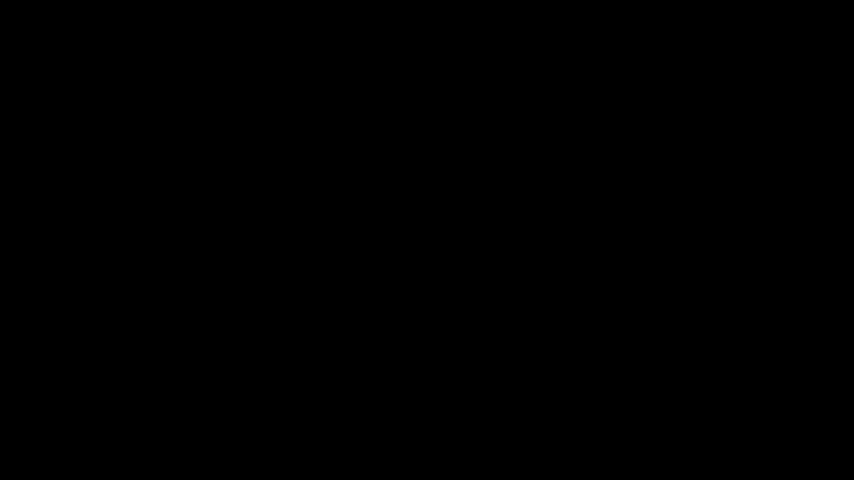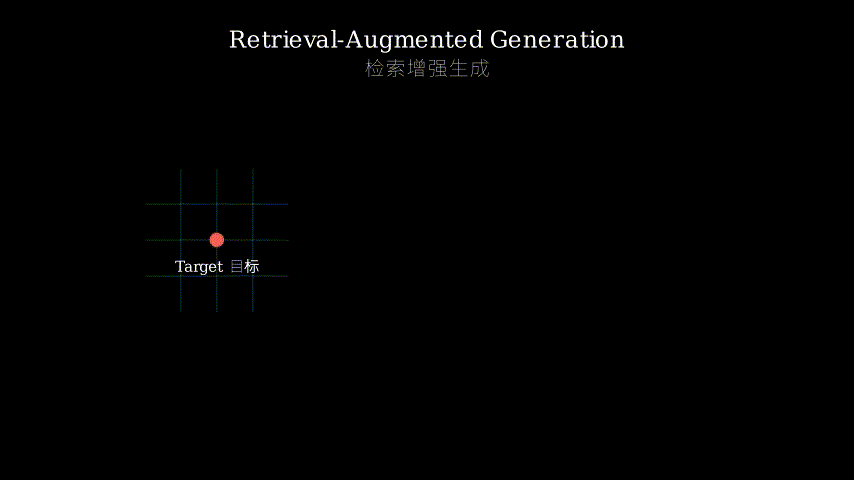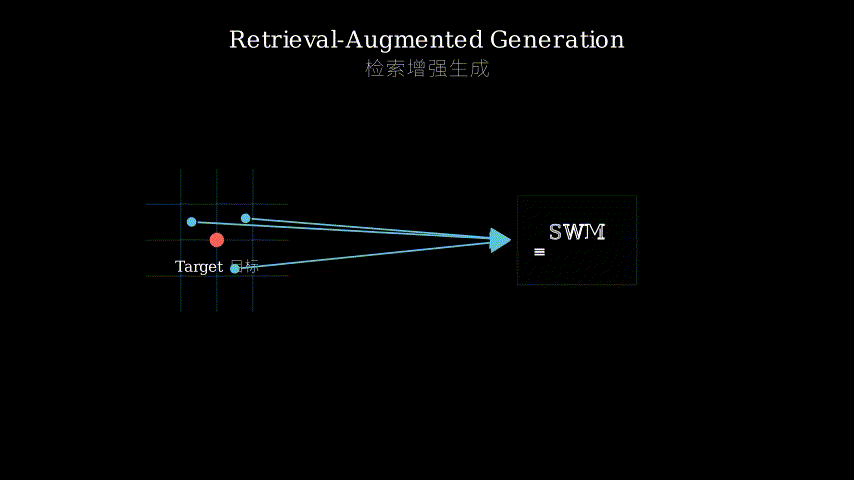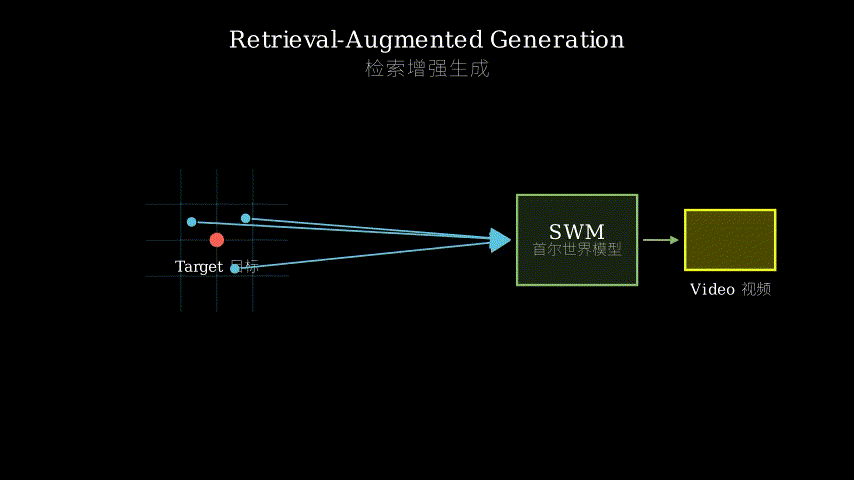
SWM operates through three interconnected stages. First, given a target trajectory through Seoul, it retrieves nearby street-view images from a database indexed by GPS coordinates. These retrieved images serve as spatial anchors—visual evidence of what actually exists at those locations. Second, it processes these anchors through cross-temporal pairing, deliberately misaligning the temporal correspondence between reference images and target frames to force the model to learn dynamic scene understanding rather than simple frame copying. Third, it feeds these processed anchors into an autoregressive video generator that produces each frame conditioned on both previous frames and the retrieved spatial context.
The data pipeline addresses sparsity through view interpolation. Street-view captures happen at sparse intervals (every few meters), but training requires dense video sequences. SWM synthesizes intermediate views by interpolating between sparse captures, creating coherent training videos. For diverse trajectories beyond vehicle-mounted captures, they generate a large-scale synthetic dataset with varied camera movements—turns, elevation changes, different speeds—all registered to Seoul’s actual geography.
For long-horizon generation (hundreds of meters), SWM introduces Virtual Lookahead Sink: at each generation chunk, it retrieves an image from a future location along the trajectory and uses it as an additional conditioning signal. This acts like a compass, continuously re-grounding the generation to prevent spatial drift over long sequences.
Trajectory Input
   |
   v
[GPS Coordinates] ---> Retrieval Database
   |                        |
   v                        v
[Retrieved Images] <--- [Street-view Index]
   |
   v
Cross-temporal Pairing (temporal misalignment)
   |
   v
[Spatial Anchors] + [Previous Frames] + [Lookahead Image]
   |                                           |
   +-------------------------------------------+
   |
   v
Autoregressive Video Generator
   |
   v
Generated Frame ---> (loop for next frame)
Think of SWM like a tour guide navigating a city with a photo album. Traditional world models are like guides who describe the city entirely from imagination—they might describe plausible buildings and streets, but nothing corresponds to reality. SWM is like a guide who carries a photo album indexed by location. As you walk, the guide pulls out photos taken near your current position and uses them as reference points: “See this building in the photo? That’s what’s actually here.” The cross-temporal pairing is like deliberately using photos taken at different times of day or seasons, forcing the guide to understand the underlying structure rather than just memorizing specific lighting conditions. The Virtual Lookahead Sink is like the guide occasionally checking photos from a few blocks ahead to ensure you’re heading in the right direction and won’t drift off course. The view interpolation is like filling gaps between sparse photos by intelligently blending nearby shots to create a smooth visual journey.
Key Concepts
-
Cross-temporal Pairing: When you retrieve a street-view image from location A to condition generation at location A, the naive approach would match them temporally—use a summer photo for summer generation, morning photo for morning. But this creates a shortcut: the model learns to copy lighting and weather rather than understanding spatial structure. Cross-temporal pairing deliberately breaks this correspondence—it might use a winter reference image to generate a summer scene at the same location. This forces the model to extract geometric and structural information (building shapes, road layout) while ignoring temporal attributes (lighting, weather, traffic). It’s like learning to recognize your house by its architecture rather than by whether the lights are on. The model must learn: “This is what exists here, regardless of when.”
-
Virtual Lookahead Sink: Autoregressive generation accumulates errors—each frame depends on previous frames, so mistakes compound over long sequences. In spatial terms, this manifests as drift: after generating 100 frames, you might end up in the wrong neighborhood. The Virtual Lookahead Sink addresses this by retrieving an image from a future location (say, 50 meters ahead) and using it as an additional conditioning signal. It’s like hiking with both a map of where you are and a photo of your destination—the destination photo keeps you oriented even if you take small wrong turns. Technically, this future image acts as a “sink” that pulls the generation trajectory toward the correct spatial location, preventing accumulated drift from derailing long-horizon sequences.
-
Retrieval-Augmented Conditioning: Instead of generating everything from learned parameters, the model retrieves actual images from a database and conditions generation on them. This is fundamentally different from pure generative models. Think of it like the difference between drawing a portrait from memory versus drawing while looking at a reference photo. The reference photo (retrieved image) provides ground truth about spatial structure, while the generative model handles dynamics, viewpoint changes, and temporal evolution. The retrieval database acts as an external memory that stores real-world visual facts, while the neural network learns to interpret and animate those facts.
Framework Shift
Before (mainstream approach):        After (this paper):

[Learned Parameters]                 [Learned Parameters] + [Retrieval DB]
        |                                     |                    |
        v                                     v                    v
  Imagine Scene                        Query Location -----> Get Real Images
        |                                     |                    |
        v                                     +--------------------+
  Generate Video                                     |
   (fictional)                                       v
                                              Condition on Reality
                                                     |
                                                     v
                                              Generate Video
                                               (grounded)
From imagination-based synthesis to retrieval-augmented grounding, the core shift is anchoring generation in external visual evidence rather than purely internal representations.
Expert Assessment
Problem choice: This is a genuine gap with practical implications. Autonomous vehicle companies need to test in specific cities, not generic environments. Urban planners want to visualize changes to actual locations. The problem sits at the intersection of world models (hot area) and practical deployment (real need). Not manufactured.
Method maturity: The core insight—using retrieval for spatial grounding—is elegant and somewhat obvious in hindsight. The engineering around it (cross-temporal pairing, lookahead sink, view interpolation) shows thoughtful problem-solving rather than brute force. However, the reliance on pre-existing street-view databases limits generalization. What about cities without comprehensive street-view coverage? The synthetic data generation for diverse trajectories feels like a workaround for data limitations rather than a principled solution.
Experimental integrity: Baselines are reasonable (recent world models), but the evaluation heavily favors their approach by design—of course a retrieval-based method wins on spatial fidelity when compared to imagination-based methods. The more interesting question is: how much does retrieval help versus just training on more Seoul-specific data? The ablations address some of this, but I’d want to see comparisons against models trained exclusively on Seoul without retrieval. The three-city evaluation (Seoul, Busan, Ann Arbor) is good for generalization claims, but details on data availability per city are sparse.
Writing quality: The paper front-loads motivation well but buries important technical details. The cross-temporal pairing mechanism deserves earlier, clearer explanation—it’s central to why this works. The synthetic data generation section feels rushed; given its importance for trajectory diversity, it warrants more depth. The related work section could better position this against retrieval-augmented generation in other domains (not just world models).
Verdict: weak accept — Solid contribution with clear practical value, but the method feels more like careful engineering of existing components than a fundamental breakthrough; the evaluation could be more rigorous about isolating the retrieval contribution.
Takeaways
The cross-temporal pairing trick transfers broadly: whenever you have paired data with both spatial and temporal dimensions, deliberately misaligning the temporal correspondence forces models to learn spatial structure. This applies to any domain where you want to disentangle “what exists” from “what it looks like right now”—medical imaging across different scanners, satellite imagery across seasons, or audio across recording conditions.
The Virtual Lookahead Sink pattern—conditioning on future states to prevent drift—is applicable beyond video generation. Any autoregressive process over spatial or structured domains can benefit: trajectory prediction (condition on destination), code generation (condition on function signature), or long-form text generation (condition on outline points).
The broader lesson: when your domain has external ground truth available (maps, databases, knowledge graphs), retrieval-augmented approaches can outperform pure generation by anchoring outputs in reality. The key is designing the conditioning mechanism so the model learns to interpret and animate the retrieved information rather than just copying it.
论文: 2603.15583 作者: Junyoung Seo, Hyunwook Choi, Minkyung Kwon, Jinhyeok Choi, Siyoon Jin, Gayoung Lee, Junho Kim, JoungBin Lee, Geonmo Gu, Dongyoon Han 分类: cs.CV
缺口
现有的世界模型如 GAIA-1、DriveDreamer 和 GenAD 通过从零想象来合成驾驶视频。
它们生成视觉上可信的场景,但这些环境完全是人造的——建筑、街道和地标不对应任何真实位置。
这限制了它们在需要空间保真度的应用中的效用:特定城市的自动驾驶测试、城市规划模拟、或位置感知的场景生成。
根本局限在于先前的模型在真空中运作,与地理现实脱节。
问题:合成世界模型缺乏空间锚定
   |
   v
假设:真实街景图像可以锚定生成
   |
   v
方法:检索增强条件 + 时间对齐
   |
   v
证据:在3个城市的空间保真度上优于基线
   |
   v
结论:真实世界锚定使城市尺度模拟成为可能
增量
一句话: 这篇论文之前,世界模型想象出可信但虚构的环境;之后,它们能通过锚定到检索的街景图像来渲染真实城市的视频。
核心机制
SWM 通过三个相互关联的阶段运作。
首先,给定一条穿过首尔的目标轨迹,它从按 GPS 坐标索引的数据库中检索附近的街景图像。
这些检索的图像充当空间锚点——那些位置实际存在什么的视觉证据。
其次,它通过跨时间配对处理这些锚点,故意错配参考图像和目标帧之间的时间对应关系,迫使模型学习动态场景理解而非简单的帧复制。
第三,它将这些处理过的锚点输入自回归视频生成器,该生成器在先前帧和检索的空间上下文的条件下生成每一帧。
数据管道通过视图插值解决稀疏性问题。
街景捕获发生在稀疏间隔(每隔几米),但训练需要密集的视频序列。
SWM 通过在稀疏捕获之间插值来合成中间视图,创建连贯的训练视频。
对于超出车载捕获的多样化轨迹,他们生成了一个大规模合成数据集,包含各种相机运动——转弯、高度变化、不同速度——全部注册到首尔的实际地理位置。
对于长距离生成(数百米),SWM 引入了虚拟前瞻汇聚点:在每个生成块,它从轨迹上的未来位置检索图像,并将其用作额外的条件信号。
这就像一个指南针,持续将生成重新锚定,防止长序列上的空间漂移。
轨迹输入
   |
   v
[GPS 坐标] ---> 检索数据库
   |                  |
   v                  v
[检索图像] <--- [街景索引]
   |
   v
跨时间配对(时间错配)
   |
   v
[空间锚点] + [先前帧] + [前瞻图像]
   |                            |
   +----------------------------+
   |
   v
自回归视频生成器
   |
   v
生成帧 ---> (循环到下一帧)
把 SWM 想象成一个带着相册导航城市的导游。
传统世界模型就像完全凭想象描述城市的导游——他们可能描述出可信的建筑和街道,但没有任何东西对应现实。
SWM 就像一个携带按位置索引的相册的导游。
当你行走时,导游会拿出在你当前位置附近拍摄的照片作为参考点:“看这张照片里的建筑?那就是这里实际存在的。
“跨时间配对就像故意使用在不同时间或季节拍摄的照片,迫使导游理解底层结构而不是仅仅记住特定的光照条件。
虚拟前瞻汇聚点就像导游偶尔检查前方几个街区的照片,确保你朝着正确的方向前进,不会偏离路线。
视图插值就像通过智能混合附近的照片来填补稀疏照片之间的空白,创造平滑的视觉旅程。
关键概念
- 跨时间配对: 当你从位置 A 检索街景图像来条件化位置 A 的生成时,朴素的方法会在时间上匹配它们——用夏天的照片生成夏天,用早晨的照片生成早晨。
但这创造了一个捷径:模型学会复制光照和天气而不是理解空间结构。
跨时间配对故意打破这种对应关系——它可能使用冬天的参考图像来生成同一位置的夏天场景。
这迫使模型提取几何和结构信息(建筑形状、道路布局),同时忽略时间属性(光照、天气、交通)。
这就像通过建筑来识别你的房子,而不是通过灯是否开着。
模型必须学习:“这是这里存在的东西,无论何时。
”
- 虚拟前瞻汇聚点: 自回归生成会累积误差——每一帧依赖于先前的帧,所以错误会复合在长序列上。
在空间术语中,这表现为漂移:生成100帧后,你可能最终到了错误的街区。
虚拟前瞻汇聚点通过从未来位置(比如前方50米)检索图像并将其用作额外的条件信号来解决这个问题。
这就像徒步旅行时既有你所在位置的地图,又有目的地的照片——目的地照片让你保持方向,即使你走了一些小弯路。
从技术上讲,这个未来图像充当”汇聚点”,将生成轨迹拉向正确的空间位置,防止累积漂移破坏长距离序列。
- 检索增强条件: 模型不是从学习的参数生成所有内容,而是从数据库检索实际图像并在其条件下生成。
这与纯生成模型有根本不同。
想想凭记忆画肖像和看着参考照片画之间的区别。
参考照片(检索图像)提供关于空间结构的真实信息,而生成模型处理动态、视角变化和时间演化。
检索数据库充当存储真实世界视觉事实的外部记忆,而神经网络学习解释和动画化这些事实。
框架转变
之前(主流方法):                之后(本文方法):

[学习参数]                        [学习参数] + [检索数据库]
     |                                  |              |
     v                                  v              v
想象场景                          查询位置 -----> 获取真实图像
     |                                  |              |
     v                                  +--------------+
生成视频                                      |
(虚构)                                      v
                                       基于现实条件化
                                              |
                                              v
                                         生成视频
                                         (锚定)
从基于想象的合成到检索增强的锚定,核心转变是将生成锚定在外部视觉证据中,而不是纯粹的内部表示。
专家评审
选题眼光: 这是一个有实际意义的真实缺口。
自动驾驶公司需要在特定城市测试,而不是通用环境。
城市规划者想要可视化对实际位置的改变。
这个问题位于世界模型(热门领域)和实际部署(真实需求)的交叉点。
不是人造的。
方法成熟度: 核心洞察——使用检索进行空间锚定——是优雅的,事后看来有些显而易见。
围绕它的工程(跨时间配对、前瞻汇聚点、视图插值)展示了深思熟虑的问题解决,而不是蛮力。
然而,对预先存在的街景数据库的依赖限制了泛化。
没有全面街景覆盖的城市怎么办?用于多样化轨迹的合成数据生成感觉像是数据限制的变通方法,而不是原则性解决方案。
实验诚意: 基线是合理的(最近的世界模型),但评估在设计上严重偏向他们的方法——当然,与基于想象的方法相比,基于检索的方法在空间保真度上获胜。
更有趣的问题是:与仅在更多首尔特定数据上训练相比,检索有多大帮助?消融研究解决了其中一些问题,但我想看到与专门在首尔训练但不使用检索的模型的比较。
三城市评估(首尔、釜山、安娜堡)对泛化声明很好,但每个城市的数据可用性细节很少。
写作功力: 论文很好地前置了动机,但埋没了重要的技术细节。
跨时间配对机制值得更早、更清晰的解释——它是这个工作的核心。
合成数据生成部分感觉仓促;鉴于其对轨迹多样性的重要性,它值得更深入。
相关工作部分可以更好地将其定位在其他领域的检索增强生成(不仅仅是世界模型)中。
判决: 弱接收 — 具有明确实用价值的扎实贡献,但方法感觉更像是对现有组件的仔细工程,而不是根本性突破;评估可以更严格地隔离检索贡献。
要点总结
跨时间配对技巧可以广泛迁移:每当你有同时具有空间和时间维度的配对数据时,故意错配时间对应关系会迫使模型学习空间结构。
这适用于任何你想要解耦”存在什么”和”现在看起来如何”的领域——不同扫描仪的医学成像、不同季节的卫星图像、或不同录音条件的音频。
虚拟前瞻汇聚点模式——基于未来状态条件化以防止漂移——适用于视频生成之外。
任何在空间或结构化域上的自回归过程都可以受益:轨迹预测(基于目的地条件化)、代码生成(基于函数签名条件化)、或长文本生成(基于大纲点条件化)。
更广泛的教训:当你的领域有可用的外部真实信息(地图、数据库、知识图谱)时,检索增强方法可以通过将输出锚定在现实中来优于纯生成。
关键是设计条件化机制,使模型学会解释和动画化检索的信息,而不是仅仅复制它。