Paper: 2607.21580 Authors: Vedant Shah, Onkar Susladkar, Tushar Prakash, Kiet Nguyen, Tianjio Yu, Adheesh Juvekar, Muntasir Waheed, Ismini Lourentzou Categories: cs.CV, cs.AI
The Gap
Existing controllable video generation research has hit a wall with input specification. The dominant methods are either text-only (ambiguous for complex interactions) or trajectory-based (e.g., drag-to-move). The latter requires users to manually draw precise motion paths for *every single object. This approach crumbles under scene complexity: it doesn’t scale, becomes ambiguous during occlusions, and tells the model where things move pixel-by-pixel, but not what relationship they have (e.g., “A pushes B,” “C follows D”). This is a fundamental interface limitation, not just a model capacity issue.
The logical path from gap to conclusion is:
Problem: Existing control interfaces (text, trajectories) are imprecise or unscalable for multi-object interaction.
     |
     v
Assumption: A structured, semantic representation of object relationships can provide better control.
     |
     v
Method: Introduce GraphVid, which uses a Scene Graph as a conditional interface. Also, create a new dataset (GraphVid-Bench) with structured annotations.
     |
     v
Evidence: GraphVid outperforms a strong trajectory-based baseline (Motion-I2V) on FID, FVD, PSNR, SSIM while using less data and fewer parameters.
     |
     v
Conclusion: Structured semantic interfaces (like scene graphs) are a powerful, underexplored paradigm for controllable video generation.
The Increment
One sentence: Before this paper, specifying precise multi-object interactions in video generation required tedious, pixel-level trajectory drawing; after, users can define high-level relational graphs (e.g., “person_A high-fives person_B”) and let the model handle the complex motion synthesis.
Core Mechanism
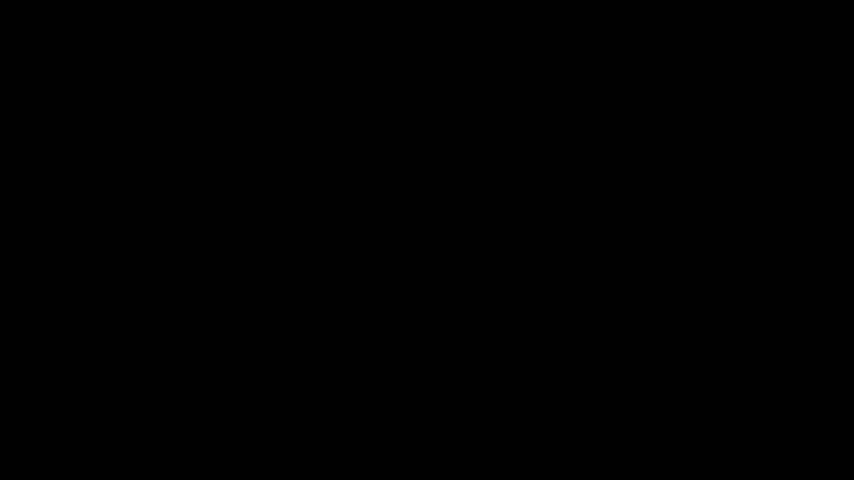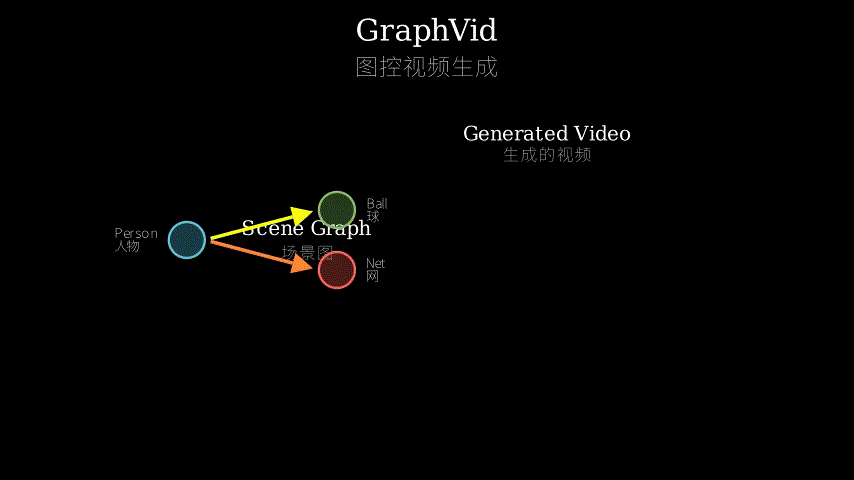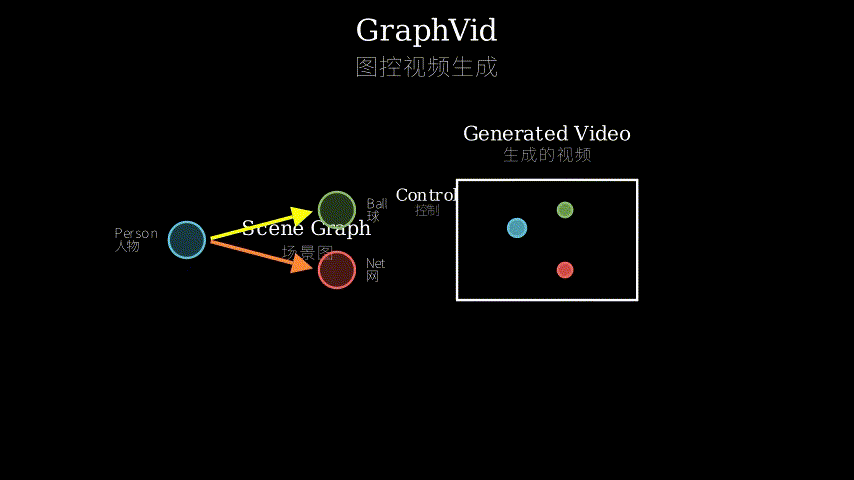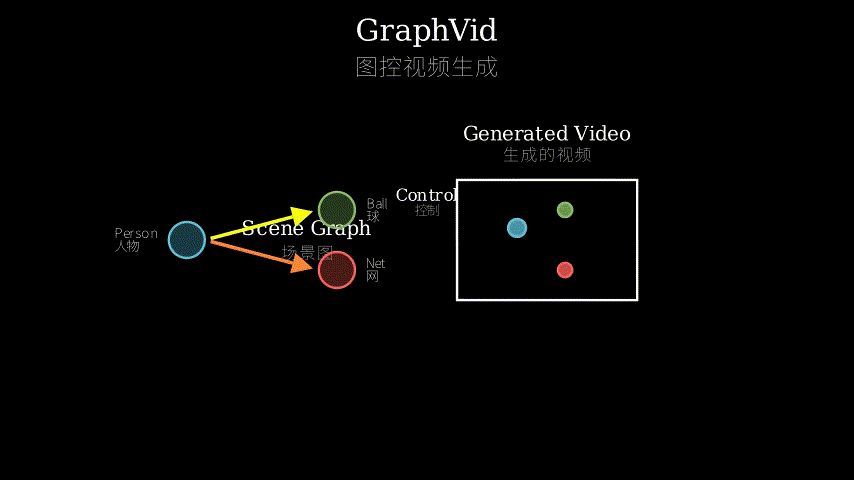
GraphVid is an image-to-video diffusion model conditioned on a scene graph. The pipeline has three key stages: 1) Graph Encoding, 2) Cross-Attention Fusion, and 3) Video Decoding. First, the user provides an initial image and a scene graph specifying objects and their relationships (e.g., (Object_A, interacts_with, Object_B)). This graph is processed by a Scene Graph Transformer into rich node and edge embeddings. These embeddings are not just labels; they encode spatial and semantic context about the relationships.
During the video denoising process (in the diffusion U-Net), these graph embeddings are injected via cross-attention mechanisms. This means that at every denoising step, the model “looks at” the graph embeddings to understand which objects are interacting and how. This is fundamentally different from a single text prompt; it provides a structured, disentangled signal for each relationship in the scene. The model then synthesizes the video frames conditioned on this graph-aware signal and the initial image, learning to translate semantic relations into plausible motions.
[User Input]---->[Scene Graph + Image]
                       |
                       v
             [Scene Graph Encoder]
                 (Node/Edge Embeddings)
                       |
                       v
[Diffusion U-Net]<----| (Cross-Attention Injection at multiple scales)
      ^                |
      |                v
 [Noisy Video] [Graph-Conditioned Denoising]
      |                |
      v                v
[Clean Video]<----[Output Video]
Structural Metaphor: Think of it like a play director with a script and actors.
- The initial image is the stage set.
- The scene graph is the director’s script. It doesn’t specify every step (trajectory), but defines character roles (nodes) and their key interactions (“fight scene with,” “hand object to” - edges).
- The Scene Graph Encoder is the director interpreting the script, understanding character motivations and dynamics.
- The Cross-Attention mechanism in the U-Net is the director giving real-time instructions to the actors (pixels) during filming. At each moment (denoising step), the director checks the script to ensure the actors are performing the right relationship.
- The final video is the filmed scene that follows the director’s high-level instructions, with actors moving naturally and interactively. You don’t need to choreograph every footstep; you define the drama, and the system choreographs it.
Key Concepts
-
Scene Graph as Control Interface: Forget pixels or text. A scene graph is a small network diagram where circles (nodes) are objects (e.g., “car,” “person”) and arrows (edges) are labeled relationships (“behind,” “holding,” “collision_course”). This is the core idea: the user’s intent is expressed not as a single sentence or a squiggle, but as a structured map of *who is doing what to whom. This directly encodes the multi-object interactions that were previously ambiguous. Example: For a scene of a robot handing a tool to a human, the graph is:
[robot] --(hands_tool_to)--> [human], which is far clearer than describing the motion paths of both the robot arm and the human hand. -
Graph Relation Propagation: This is the technical heart. The model doesn’t just see the graph; it learns how the *meaning of an edge (the relationship) influences the motion of the connected nodes over time. During training, the model sees many examples where a “push” edge leads to specific joint motion patterns between objects. During inference, it propagates this understanding through the cross-attention layers, so that when it’s generating a frame, it “remembers” that object A is supposed to be “pushing” object B, synthesizing appropriate velocities and deformations for both.
Framework Shift
Before (mainstream approach):        After (this paper):
User: Draw precise motion paths      User: Draw a semantic relationship graph
for each object.                     (Object A -> Relation -> Object B).
     |                                    |
     v                                    v
Control Signal: Pixel-level          Control Signal: High-level, structured
trajectories (per-object).           object relationships.
     |                                    |
     v                                    v
Model: Learns to move pixels         Model: Learns to synthesize interactions
along given paths. Ambiguous         that fulfill graph semantics. More
under occlusion. Poor scaling.       scalable to complex scenes.
From pixel-motion specification to semantic-relation specification, the core shift is *moving the control interface from the how (motion trajectory) to the what (object relationship).
Expert Assessment
Problem choice: Excellent. This is a real and underappreciated gap. The field has focused heavily on model architecture and training objectives, but the *human-AI interface for control is often an afterthought. Fixating on pixel trajectories is a dead end for usability. This paper correctly identifies semantic structure as a better interface and tackles it head-on.
Method maturity: A clever, well-motivated integration of known parts (Scene Graph Transformers, diffusion cross-attention) rather than a brute-force new architecture. The insight is in the framing and the interface design. However, the method likely inherits limitations from scene graphs themselves—they can be cumbersome to define for highly dynamic or fluid scenes (e.g., a flock of birds). A simpler approach might have been overlooked: can the model learn to extract or infer such a graph from video data in a self-supervised way, reducing user burden?
Experimental integrity: The numbers are compelling, especially the PSNR/SSIM jumps, which suggest more precise control. Reducing FID/FVD while improving controllability is a strong signal. Red flags: 1) The comparison is primarily against one strong baseline (Motion-I2V). How does it fare against other recent non-trajectory methods? 2) GraphVid-Bench is curated by them; while they describe the process, this is a common point of bias. The results need validation on broader benchmarks. 3) The “less data/parameters” claim is great for efficiency but needs context—is the baseline just bloated?
Writing quality: Clear and well-structured. The abstract and intro effectively sell the story. A section that could elevate it: A deeper failure case analysis. When does the graph condition break down? What kinds of relationships are hard to model? Showing limitations would bolster credibility more than just reporting metrics. The related work could also better position this within the broader “controllable generation” taxonomy beyond just video.
Verdict: Weak Accept — It presents a compelling and clean idea (graph-as-interface) that fills a genuine gap, with solid initial results. The main weakness is the scope of evaluation (single main baseline, proprietary benchmark). It’s a strong conceptual contribution that should spark follow-up work.
Takeaways
- Steal the Interface Design Philosophy: The most transferable idea is: when designing a generative control system, think about the *structure of human intent. Can you move from a flat signal (text, points) to a structured representation (graphs, trees, programs) that better mirrors how users conceptualize the problem? This applies to image editing, audio synthesis, and 3D generation.
- Small Data, Smart Conditioning: GraphVid achieves strong results with less data. The takeaway is that a well-chosen, semantically rich conditional signal (the graph) can be more data-efficient than a weak, ambiguous signal (pixel trajectories) paired with more data. For practitioners, investing in a better conditional input design might yield better returns than simply scaling up data and compute.
- The “Director” Pattern: For any multi-agent or multi-object generation task, consider the “director” pattern: separate the high-level script/relations from the low-level execution. Use an encoder to interpret the script and a mechanism (like cross-attention) to enforce it during generation. This modularity can make systems more controllable and debuggable.
论文: 2607.21580 作者: Vedant Shah, Onkar Susladkar, Tushar Prakash, Kiet Nguyen, Tianjio Yu, Adheesh Juvekar, Muntasir Waheed, Ismini Lourentzou 分类: cs.CV, cs.AI
缺口
现有可控视频生成研究在输入规格上碰壁了。主流方法要么是纯文本(对复杂交互描述模糊),要么是基于轨迹的(如拖拽移动)。后者要求用户为**每一个物体手绘精确的运动轨迹。这种方法在场景复杂性面前崩溃:无法扩展,在遮挡时产生歧义,并且只能告诉模型像素该去哪*,却无法表达物体间有什么关系(如“A推B”、“C跟随D”)。这是一个根本性的接口限制,而不仅仅是模型容量问题。
从缺口到结论的逻辑路径如下:
问题:现有控制接口(文本、轨迹)对多物体交互不精确或不具扩展性。
     |
     v
假设:一种结构化的物体关系语义表示可以提供更好的控制。
     |
     v
方法:提出GraphVid,使用场景图作为条件接口。同时,创建带结构化标注的新数据集GraphVid-Bench。
     |
     v
证据:GraphVid在FID、FVD、PSNR、SSIM指标上优于基于轨迹的强基线Motion-I2V,同时使用更少数据和参数。
     |
     v
结论:结构化语义接口(如场景图)是可控视频生成中一个强大且未被充分探索的范式。
增量
一句话: 这篇论文之前,要精确指定视频中的多物体交互需要繁琐的像素级轨迹绘制;之后,用户只需定义高层关系图(如“人物_A与人物_B击掌”),让模型来处理复杂的动作合成。
核心机制
GraphVid是一个以场景图为条件的图像到视频扩散模型。流程有三个关键阶段:1) 图编码,2) 交叉注意力融合,3) 视频解码。首先,用户提供一张初始图像和一个指定物体及其关系(例如,(物体A, 交互, 物体B))的场景图。这个图通过一个场景图转换器被处理成丰富的节点和边嵌入。这些嵌入不仅仅是标签;它们编码了关系的语义和空间上下文。
在视频去噪过程(在扩散U-Net中)中,这些图嵌入通过交叉注意力机制被注入。这意味着在每一个去噪步骤中,模型都会“查看”图嵌入,以理解哪些物体在交互以及如何交互。这与单一的文本提示有本质区别;它为场景中的每一个关系都提供了结构化的、解耦的信号。模型随后在这些图感知信号和初始图像的条件下合成视频帧,学习将语义关系转化为合理的运动。
[用户输入]---->[场景图 + 图像]
                     |
                     v
             [场景图编码器]
               (节点/边嵌入)
                     |
                     v
[扩散U-Net]<--------| (多尺度交叉注意力注入)
     ^               |
     |               v
 [带噪视频] [图条件化去噪]
     |               |
     v               v
[干净视频]<-----[输出视频]
结构比喻:可以把它想象成一个拿着剧本和演员表的导演。
- 初始图像是舞台布景。
- 场景图是导演的剧本。它不规定每个动作细节(轨迹),而是定义了角色(节点)和他们的关键交互(边,如“与…打斗”、“把…递给”)。
- 场景图编码器是导演在解读剧本,理解角色动机和动态。
- U-Net中的交叉注意力机制是导演在拍摄过程中实时给演员(像素)下指令。在每一刻(去噪步骤),导演都会核对剧本,以确保演员表演的是正确的关系。
- 最终视频是拍摄完成的场景,遵循了导演的高层指令,演员的移动自然而富有交互性。你不需要编排每一个脚步;你定义戏剧冲突,系统来编排动作。
关键概念
-
场景图作为控制接口:忘掉像素或文本。场景图是一个小的网络图,其中圆圈(节点)是物体(如“汽车”、“人”),箭头(边)标记着关系(“在…后面”、“拿着”、“碰撞轨迹”)。这是核心思想:用户的意图不是通过一个句子或一个涂鸦表达,而是通过一个结构化的**谁对谁做了什么*的地图来表达。这直接编码了先前模糊的多物体交互。例如:对于一个机器人递工具给人类的场景,图是:
[机器人] --(递工具给)--> [人类],这比描述机器人手臂和人类手掌各自的运动轨迹要清晰得多。 -
图关系传播:这是技术核心。模型不仅仅“看到”图;它学习边的含义(关系)如何影响相连节点的运动。在训练过程中,模型看到许多例子,其中“推”的边导致物体间特定的联合运动模式。在推理时,它通过交叉注意力层传播这种理解,这样在生成某一帧时,它会“记住”物体A应该“推”物体B,从而为两者合成合适的速度和形变。
框架转变
之前(主流方法):                   之后(本文方法):
用户:为每个物体绘制精确的运动轨迹。用户:绘制语义关系图(物体A -> 关系 -> 物体B)。
     |                               |
     v                               v
控制信号:像素级轨迹(每个物体)。控制信号:高层、结构化的物体关系。
     |                               |
     v                               v
模型:学习将像素沿给定轨迹移动。  模型:学习合成满足图语义的交互。
遮挡时歧义。扩展性差。            对复杂场景更具扩展性。
从像素运动规格到语义关系规格,核心转变是将控制接口从“如何动”(运动轨迹)转移到“是什么关系”(物体交互)。
专家评审
选题眼光:极佳。这是一个真实且被低估的缺口。领域过度关注模型架构和训练目标,但人机交互的控制接口常常被事后考虑。执着于像素轨迹是条死路。本文正确地将语义结构识别为更优的接口,并直接攻克它。
方法成熟度:巧妙整合了已知组件(场景图转换器、扩散交叉注意力),而非蛮力创造新架构。洞见在于框架设计和接口定义。然而,该方法可能继承场景图自身的局限性——对于高度动态或流体场景(如鸟群),定义场景图可能很繁琐。是否有一种更简单的方法被忽略了:模型能否以自监督的方式从视频数据中学习提取或推断这种图,从而减轻用户负担?
实验诚意:数据很有说服力,特别是PSNR/SSIM的跃升,暗示了更精确的控制。在提升可控性的同时降低FID/FVD是一个强烈信号。值得警惕之处:1) 对比主要针对一个强基线(Motion-I2V)。它与其他近期的非轨迹方法相比如何?2) GraphVid-Bench由他们自己策划;虽然描述了过程,但这是常见的偏差来源。结果需要在更广泛的基准上得到验证。3) “更少数据/参数”的声明对效率是好事,但需要背景——基线是否过于臃肿?
写作功力:清晰且结构良好。摘要和引言有效地讲述了故事。重写可提升论文的部分:更深入的失败案例分析。图条件何时会失效?哪些关系难以建模?展示局限性比仅仅报告指标更能增强可信度。相关工作部分也可以更好地将其定位在更广泛的“可控生成”分类法中,而不仅仅是视频。
判决:弱接收 — 它提出了一个引人入胜且清晰的创意(图作为接口),填补了一个真实的缺口,并展示了扎实的初步结果。主要弱点是评估范围(单一主要基线、专有基准)。这是一个强有力的概念性贡献,必将引发后续工作。
要点总结
- 借鉴接口设计哲学:最具迁移性的想法是:在设计生成控制系统时,思考人类意图的结构。能否从扁平信号(文本、点)转向结构化表示(图、树、程序),从而更好地反映用户构思问题的方式?这适用于图像编辑、音频合成和3D生成。
- 小数据,巧条件:GraphVid用更少的数据取得了强劲结果。启示是:一个精心选择、语义丰富的条件信号(图)可以比一个弱、模糊的信号(像素轨迹)加上更多数据更高效。对实践者而言,投资于更好的条件输入设计可能比单纯扩大数据和计算规模带来更好的回报。
- “导演”模式:对于任何多智能体或多物体生成任务,可以考虑“导演”模式:将高层剧本/关系与低层执行分离。使用编码器解读剧本,并使用一种机制(如交叉注意力)在生成过程中强制执行它。这种模块化可以让系统更可控、更易调试。