Paper: 2604.26893 Authors: Fangqiang Fan, Zhicheng Zhao, Xiaoliang Ma, Chenglong Li, Jin Tang Categories: cs.CV
The Gap
Existing UAV RGBT semantic segmentation methods assume pre-aligned sensor inputs. But real UAV platforms have sensor parallax and vibration — thermal and RGB cameras see the same scene from slightly different angles and times, creating pixel-level misalignment. Prior work either ignores this (degrading performance) or uses rigid alignment (failing when appearance differs across modalities). Meanwhile, aerial views create severe confusion among visually similar categories (asphalt vs concrete, different vehicle types) that standard segmentation networks struggle with.
Problem: Misaligned sensors + fine-grained confusion
    |
    v
Assumption: Shared structure exists despite appearance differences
            Category relationships encode disambiguation cues
    |
    v
Method: Decouple structure/appearance -> align in structure space
        Encode category taxonomy -> graph reasoning
    |
    v
Evidence: +4.2% mIoU over best baseline on new 25K-pair benchmark
          Largest gains on rare/similar categories
    |
    v
Conclusion: Explicit structural decoupling + semantic priors
            outperform end-to-end alignment
The Increment
One sentence: Before — assume aligned inputs or use appearance-based alignment; after — decouple modality structure from appearance and align in shared geometric space while using category graphs to resolve semantic ambiguity.
Core Mechanism
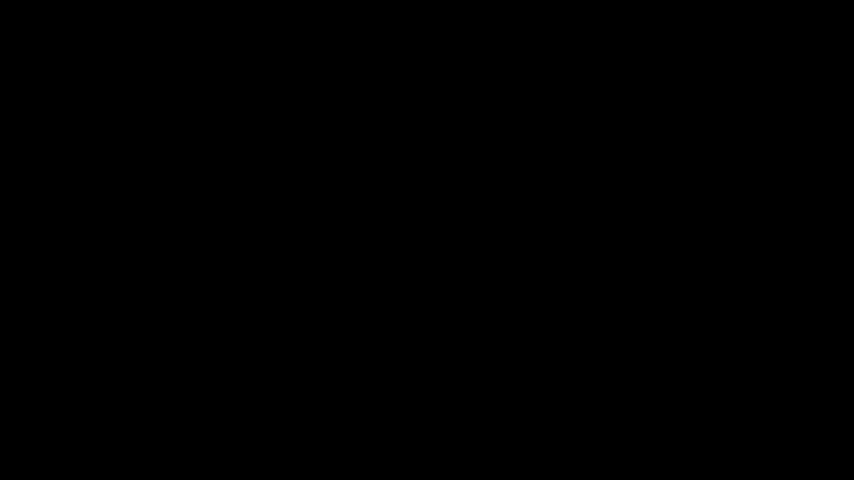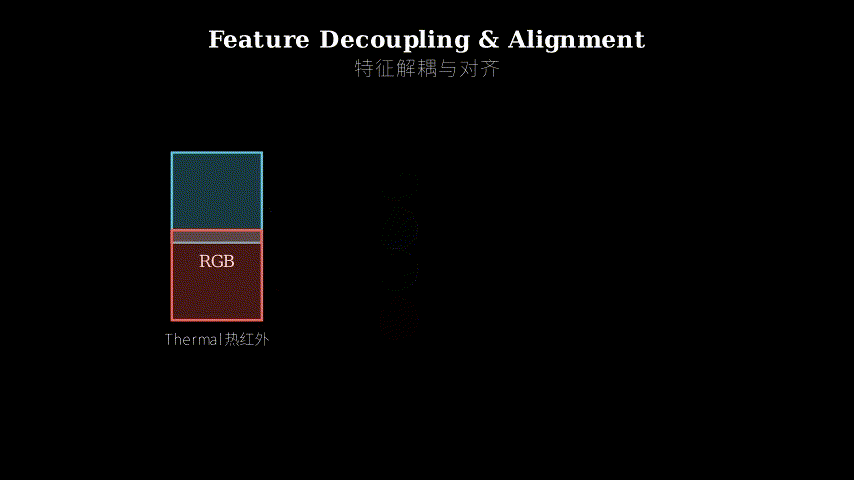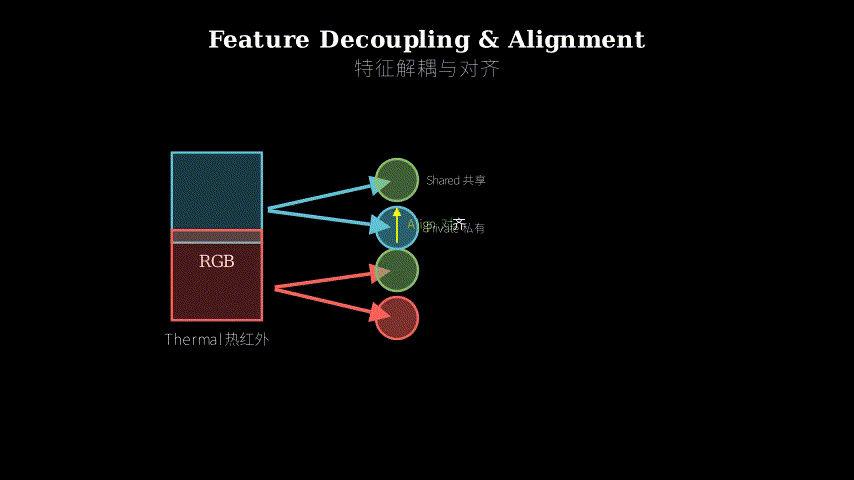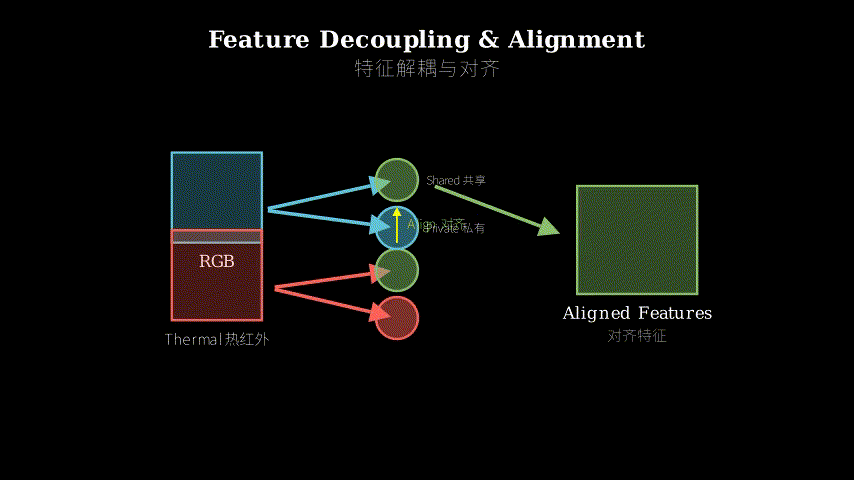
GSCNet has two main components working in sequence. First, the Feature Decoupling and Alignment Module (FDAM) splits each modality’s features into two streams: shared structural information (edges, shapes, spatial layout) and private perceptual information (color, thermal intensity). It then performs deformable convolution-based alignment only on the shared structural features, where geometric correspondence is clearer. The private streams stay separate to preserve modality-specific cues. After alignment, features are fused.
Second, the Semantic Graph Calibration Module (SGCM) takes the fused features and builds a graph where nodes are semantic categories and edges encode two types of relationships: hierarchical taxonomy (vehicle → car/truck/bus) and spatial co-occurrence patterns (roads often adjacent to buildings). The module uses graph attention to propagate information between related categories, calibrating predictions for visually ambiguous or rare classes by borrowing context from their graph neighbors.
The network processes both modalities through a shared backbone, applies FDAM at multiple scales to handle misalignment at different resolutions, then feeds the aligned features into SGCM before final prediction. The category graph is constructed once from training data statistics and remains fixed during inference.
Think of it like a translation bureau with two specialists. The first specialist (FDAM) is a structural linguist who ignores vocabulary and focuses only on sentence structure — subject-verb-object patterns that exist across languages. When aligning a French and English document that are slightly offset, she matches based on grammatical structure, not word appearance. The second specialist (SGCM) is a domain expert with a taxonomy chart on the wall showing how concepts relate (mammals → carnivores → cats). When encountering an ambiguous term, she checks the chart: “This word appears near ‘whiskers’ and ‘purring’, and those co-occur with ‘feline’ in our taxonomy, so it’s probably ‘cat’ not ‘dog’.” The structural linguist handles spatial drift, the domain expert handles semantic confusion.
Key Concepts
-
Feature decoupling: Splitting a learned representation into orthogonal subspaces where each captures a different aspect of the input. Here, one subspace captures geometry (edges, boundaries, spatial relationships) that should be consistent across RGB and thermal views, while another captures appearance (color, texture, thermal signature) that differs by modality. The key insight is that alignment is easier in the geometric subspace because a building’s outline looks similar in both modalities, but its color and thermal emission do not. Implemented via separate convolutional branches with different receptive fields and activation patterns.
-
Deformable alignment: Instead of shifting the entire feature map by a fixed offset (rigid alignment), learn per-pixel offsets that allow local warping. Imagine overlaying two photos of the same scene taken from slightly different angles — you can’t just slide one over the other; you need to stretch and compress different regions. Deformable convolution learns these local deformations by predicting 2D offset vectors for each spatial location, then sampling features at those offset positions. This handles non-uniform misalignment caused by parallax (closer objects shift more than distant ones).
-
Semantic graph with co-occurrence priors: A graph where nodes represent categories and edges represent relationships. Two types of edges: (1) hierarchical — parent-child in a taxonomy tree (vehicle → car), encoding that cars inherit vehicle properties; (2) co-occurrence — categories that frequently appear together in UAV scenes (road + car, water + boat). During inference, graph attention lets a node (category) aggregate information from its neighbors, so a rare category with few training examples can borrow features from related common categories. The graph structure is extracted from training data: co-occurrence edges connect categories that appear in the same image above a threshold frequency.
Framework Shift
Before (mainstream approach):        After (this paper):

RGB ----\                            RGB ---> [Decouple] ---> Structure --\
         [Concat] --> [Segment]                                            [Align] --> [Fuse]
Thermal /                            Thermal > [Decouple] --> Structure --/       |
                                                                                   v
(Assumes alignment                                                          [Graph Reasoning]
 or ignores it)                                                                    |
                                                                                   v
                                                                            [Calibrated Prediction]

                                     (Explicit structure/appearance split
                                      + semantic relationship encoding)
One sentence: From treating modalities as black-box feature sources to explicitly modeling what should align (structure) versus what should stay separate (appearance), plus encoding category relationships as graph priors rather than learning them implicitly.
Expert Assessment
Problem choice: Real gap. UAV RGBT datasets do have misalignment — sensor parallax is physics, not a dataset artifact. The fine-grained confusion problem (asphalt vs concrete from 100m up) is also genuine. However, the paper couples two somewhat independent problems (alignment + disambiguation), which makes it harder to isolate what drives improvements.
Method maturity: The decoupling idea is sound but not deeply novel — disentangled representations have been explored in domain adaptation and multi-modal learning. The execution here is competent: using separate conv branches for structure/appearance is straightforward. The graph module is more interesting — explicitly encoding taxonomy and co-occurrence is cleaner than hoping a transformer learns it. But the graph construction (threshold-based co-occurrence) is simplistic; more sophisticated methods exist (PMI, conditional probability). The deformable alignment is standard practice, not a contribution.
Experimental integrity: The benchmark (URTF) is the paper’s strongest contribution — 25K pairs, 61 categories, real misalignment. That’s valuable for the community. Baselines are reasonable (recent RGBT segmentation methods), though none are specifically designed for misalignment, making comparisons somewhat unfair. Ablations are thorough, showing both modules contribute. However, no comparison with traditional alignment methods (optical flow, feature matching) before segmentation — would a two-stage approach (align first, then segment) work as well? The gains are modest (+4.2% mIoU) but consistent across categories.
Writing quality: The paper is dense and tries to pack too much (two modules, a benchmark, extensive experiments) into limited space. The FDAM description is vague — “shared structural and private perceptual components” sounds good but the actual implementation (which conv layers, what loss enforces decoupling?) is underspecified. The SGCM section is clearer. The related work section is a laundry list, not a narrative. Rewriting Section 3.1 (FDAM) with concrete architectural details and a diagram showing what “decoupling” means in terms of network layers would help significantly.
Verdict: weak accept — The benchmark is a solid contribution and the problem is real. The method is competent but not groundbreaking. The coupling of two problems (alignment + disambiguation) makes it hard to assess cleanly, and the writing could be sharper. Useful for practitioners working on UAV perception, less impactful for the broader vision community.
Takeaways
Decouple before aligning: When aligning multi-modal data with appearance differences, don’t align raw features. Split into structure (geometry, edges) and appearance (color, texture) first, align only the structure. This reduces interference from modality-specific appearance. Applicable beyond RGBT — think RGB-depth, RGB-LiDAR, even cross-domain alignment (synthetic-to-real).
Encode domain structure explicitly: If your domain has known category relationships (taxonomy, co-occurrence, physical constraints), encode them as a graph and use graph reasoning rather than hoping a neural network learns them from scratch. Especially useful for long-tail categories with few examples — they can borrow from related common categories.
Benchmark construction matters: The URTF dataset with realistic misalignment is arguably more valuable than the method. If you’re working on a problem where existing benchmarks don’t reflect real-world conditions (alignment, lighting, occlusion), building a better benchmark can have more impact than a marginal method improvement.
论文: 2604.26893 作者: Fangqiang Fan, Zhicheng Zhao, Xiaoliang Ma, Chenglong Li, Jin Tang 分类: cs.CV
缺口
现有的无人机 RGBT 语义分割方法假设传感器输入已经对齐。
但真实的无人机平台存在传感器视差和振动——热红外和可见光相机从略微不同的角度和时刻观察同一场景,造成像素级错位。
先前工作要么忽略这一点(性能下降),要么使用刚性对齐(当模态间外观差异大时失效)。
同时,航拍视角造成视觉相似类别间的严重混淆(沥青 vs 混凝土,不同车辆类型),标准分割网络难以应对。
问题:传感器错位 + 细粒度混淆
    |
    v
假设:尽管外观不同,共享结构仍然存在
      类别关系编码了消歧线索
    |
    v
方法:解耦结构/外观 -> 在结构空间对齐
      编码类别分类法 -> 图推理
    |
    v
证据:在新的 25K 对基准上比最佳基线高 4.2% mIoU
      在稀有/相似类别上提升最大
    |
    v
结论:显式结构解耦 + 语义先验
      优于端到端对齐
增量
一句话: 之前——假设输入已对齐或使用基于外观的对齐;
之后——将模态结构与外观解耦,在共享几何空间中对齐,同时使用类别图解决语义歧义。
核心机制
GSCNet 有两个依次工作的主要组件。
首先,特征解耦与对齐模块(FDAM)将每个模态的特征分成两个流:共享结构信息(边缘、形状、空间布局)和私有感知信息(颜色、热强度)。
然后仅在共享结构特征上执行基于可变形卷积的对齐,因为几何对应关系在那里更清晰。
私有流保持分离以保留模态特定的线索。
对齐后,特征被融合。
其次,语义图校准模块(SGCM)接收融合特征并构建一个图,其中节点是语义类别,边编码两种关系:层次分类法(车辆 → 轿车/卡车/公交车)和空间共现模式(道路常与建筑相邻)。
该模块使用图注意力在相关类别间传播信息,通过从图邻居借用上下文来校准视觉模糊或稀有类别的预测。
网络通过共享主干处理两种模态,在多个尺度应用 FDAM 以处理不同分辨率的错位,然后将对齐的特征送入 SGCM,最后进行预测。
类别图从训练数据统计中构建一次,在推理期间保持固定。
把它想象成一个有两位专家的翻译局。
第一位专家(FDAM)是结构语言学家,她忽略词汇,只关注句子结构——跨语言存在的主谓宾模式。
当对齐略有偏移的法语和英语文档时,她基于语法结构匹配,而非单词外观。
第二位专家(SGCM)是领域专家,墙上挂着分类图,显示概念如何关联(哺乳动物 → 食肉动物 → 猫)。
遇到歧义术语时,她查看图表:“这个词出现在’胡须’和’呼噜声’附近,而这些在我们的分类法中与’猫科’共现,所以可能是’猫’而非’狗’。”
结构语言学家处理空间漂移,领域专家处理语义混淆。
关键概念
- 特征解耦: 将学习到的表示分割成正交子空间,每个子空间捕获输入的不同方面。
这里,一个子空间捕获几何(边缘、边界、空间关系),在 RGB 和热红外视图中应该一致;
另一个捕获外观(颜色、纹理、热特征),因模态而异。
关键洞察是在几何子空间中对齐更容易,因为建筑物的轮廓在两种模态中看起来相似,但其颜色和热辐射不同。
通过具有不同感受野和激活模式的独立卷积分支实现。
- 可变形对齐: 不是将整个特征图按固定偏移量移动(刚性对齐),而是学习允许局部变形的逐像素偏移。
想象叠加从略微不同角度拍摄的同一场景的两张照片——你不能只是将一张滑过另一张;
你需要拉伸和压缩不同区域。
可变形卷积通过为每个空间位置预测 2D 偏移向量来学习这些局部变形,然后在这些偏移位置采样特征。
这处理由视差引起的非均匀错位(近处物体比远处物体移动更多)。
- 带共现先验的语义图: 一个图,其中节点表示类别,边表示关系。
两种类型的边:(1)层次——分类树中的父子关系(车辆 → 轿车),编码轿车继承车辆属性;
(2)共现——在无人机场景中频繁一起出现的类别(道路 + 汽车,水 + 船)。
在推理期间,图注意力让节点(类别)从其邻居聚合信息,因此训练样本少的稀有类别可以从相关的常见类别借用特征。
图结构从训练数据中提取:共现边连接在同一图像中出现频率超过阈值的类别。
框架转变
之前(主流方法):                之后(本文方法):

RGB ----\                         RGB ---> [解耦] ---> 结构 --\
         [拼接] --> [分割]                                      [对齐] --> [融合]
热红外 /                          热红外 > [解耦] --> 结构 --/       |
                                                                     v
(假设对齐                                                    [图推理]
 或忽略它)                                                        |
                                                                     v
                                                             [校准预测]

                                  (显式结构/外观分离
                                   + 语义关系编码)
一句话: 从将模态视为黑盒特征源,到显式建模什么应该对齐(结构)与什么应该保持分离(外观),加上将类别关系编码为图先验而非隐式学习。
专家评审
选题眼光: 真实缺口。
无人机 RGBT 数据集确实存在错位——传感器视差是物理现象,不是数据集伪影。
细粒度混淆问题(从 100 米高空区分沥青与混凝土)也是真实的。
然而,论文耦合了两个相对独立的问题(对齐 + 消歧),这使得难以隔离什么驱动了改进。
方法成熟度: 解耦思想合理但不算深度创新——解耦表示在领域自适应和多模态学习中已被探索。
这里的执行是称职的:使用独立卷积分支处理结构/外观很直接。
图模块更有趣——显式编码分类法和共现比期望 transformer 学习它更清晰。
但图构建(基于阈值的共现)过于简单;
存在更复杂的方法(PMI、条件概率)。
可变形对齐是标准做法,不是贡献。
实验诚意: 基准(URTF)是论文最强的贡献——25K 对,61 个类别,真实错位。
这对社区很有价值。
基线合理(最近的 RGBT 分割方法),尽管没有专门为错位设计,使比较有些不公平。
消融实验彻底,显示两个模块都有贡献。
然而,没有与分割前的传统对齐方法(光流、特征匹配)比较——两阶段方法(先对齐,再分割)效果如何?
提升适度(+4.2% mIoU)但在各类别间一致。
写作功力: 论文密集,试图在有限空间内塞入太多内容(两个模块、一个基准、大量实验)。
FDAM 描述含糊——“共享结构和私有感知组件”听起来不错,但实际实现(哪些卷积层,什么损失强制解耦?)
规定不足。
SGCM 部分更清晰。
相关工作部分是清单,不是叙述。
重写 3.1 节(FDAM),提供具体架构细节和显示”解耦”在网络层面意味着什么的图表,会有很大帮助。
判决: 弱接收——基准是扎实的贡献,问题是真实的。
方法称职但不具突破性。
两个问题的耦合(对齐 + 消歧)使得难以清晰评估,写作可以更锐利。
对从事无人机感知的实践者有用,对更广泛的视觉社区影响较小。
要点总结
对齐前先解耦: 当对齐具有外观差异的多模态数据时,不要对齐原始特征。
先分成结构(几何、边缘)和外观(颜色、纹理),仅对齐结构。
这减少了模态特定外观的干扰。
适用于 RGBT 之外——想想 RGB-深度、RGB-LiDAR,甚至跨域对齐(合成到真实)。
显式编码领域结构: 如果你的领域有已知的类别关系(分类法、共现、物理约束),将它们编码为图并使用图推理,而不是期望神经网络从头学习。
对训练样本少的长尾类别特别有用——它们可以从相关的常见类别借用。
基准构建很重要: 具有真实错位的 URTF 数据集可以说比方法更有价值。
如果你在处理现有基准不反映真实世界条件(对齐、光照、遮挡)的问题,构建更好的基准可能比边际方法改进产生更大影响。