Paper: 2606.24839
Authors: Tian Zheng, Kai-Tai Hsu
Categories: cs.AI, stat.AP
The Gap
Most LLM evaluation today focuses on single-turn responses: benchmarks like MMLU, TruthfulQA, or HumanEval compare a generated answer to a ground-truth label. But agentic systems — those that write code, run it, inspect intermediate results, and produce verbal diagnostics — generate outputs that are fundamentally harder to grade. A correct numerical answer might hide behind a wrong reasoning path, or a correct reasoning path might produce a number that doesn’t match the expected format.
The community has two common responses: (1) use a simple heuristic (e.g., extract the last number from the output) and accept high false-negative rates; (2) pay humans to inspect every output line-by-line, which is expensive and slow. Neither scales to repeated evaluations during development.
This paper asks: Can we build an automated grader that is both precise and recallful? And when the grader disagrees with human judgment, is it a real system error or a grading artifact? The authors propose a three-layer cascade that combines strict regex matching, a lenient LLM-based judge, and a snippet-based human inspection step, and they measure exactly where each layer fails. The key insight is to treat the grader as part of the evaluation pipeline — and to debug the grader just as you would debug a model.
[Problem: agent output = code + number + text; hard to grade]
          |
          v
[Assumption: grading artifacts != system errors; need separation]
          |
          v
[Method: 3-layer cascade (strict regex + lenient LLM + human)]
          |
          v
[Evidence: 100% precision, 97% recall on 70 tasks; nudge raises pass rate]
          |
          v
[Conclusion: reliable grading = parser robustness + nudge strategy + metadata awareness]
The Increment
One sentence: Before, evaluating agentic analysis systems meant either fragile last-number extraction (27% recall) or expensive full human review; after this paper, we have a validated cascade that achieves 100% precision and 97% recall, along with a concrete nudge recipe that works without re-injecting the original question.
Core Mechanism
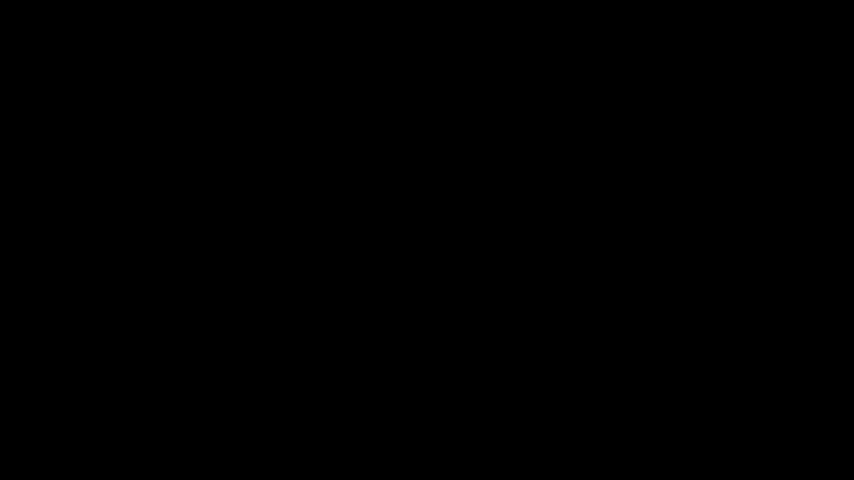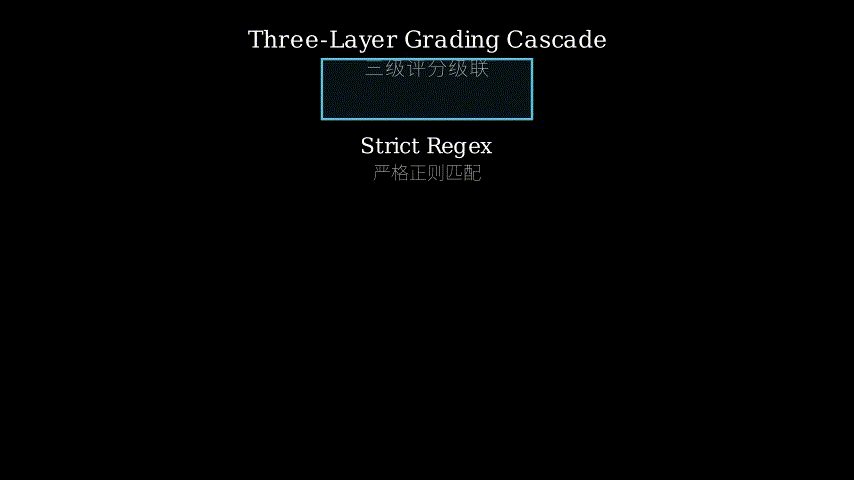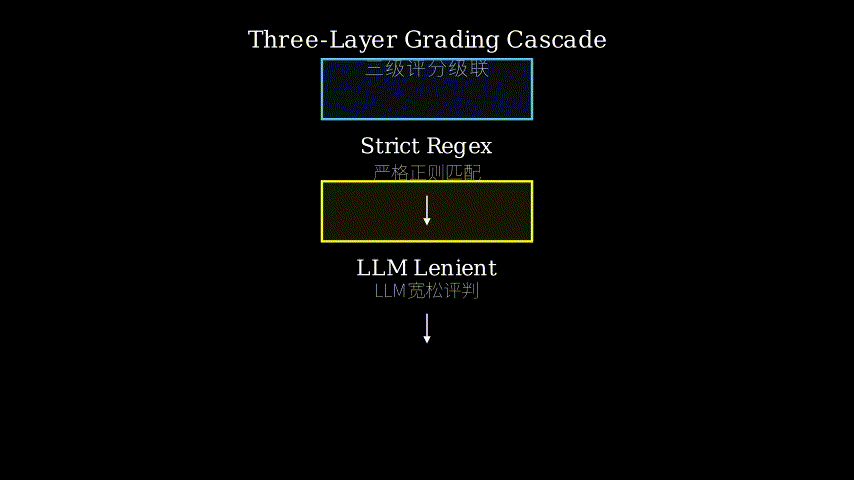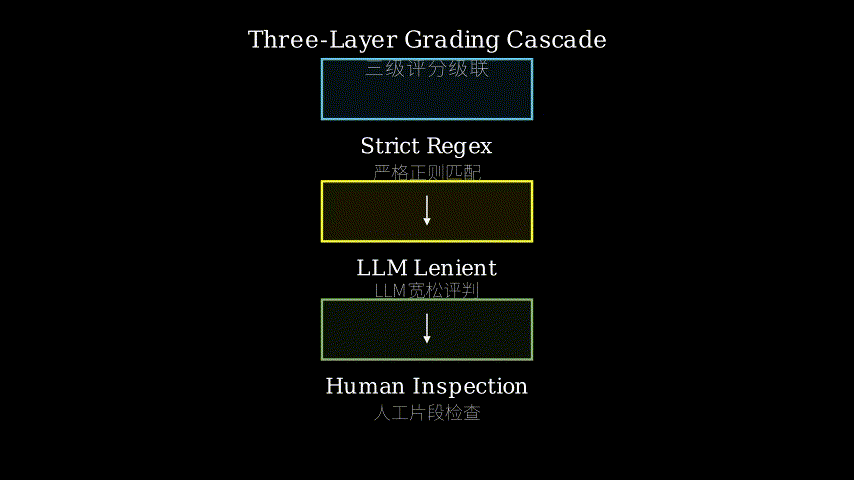
The evaluation works in three stages, each with a different failure profile. The pipeline receives an agent’s raw output (which may contain code, print statements, and a final answer) and a ground-truth label.
Stage 1 — Strict Regex: The system first applies a regex that extracts the answer using a keyword-anchored pattern (e.g., look for “the answer is X” or “result = Y”). If the pattern matches cleanly, the extracted value is compared directly to the ground truth. This stage is fast, deterministic, and achieves 100% precision (no false positives in their study), but its recall depends entirely on extraction accuracy. By switching from a naive last-number heuristic to keyword-anchored extraction, they boosted recall by 60 percentage points (e.g., from ~27% to ~87% on some tasks).
Stage 2 — Lenient LLM: If strict regex fails (no match or mismatch), the output is sent to an LLM-based judge (GPT-4) that reads the entire output and decides whether the system’s numerical answer is consistent with the ground truth. The LLM is instructed to be lenient: ignore format differences, rounding, or extra diagnostics. This stage is parser-independent — it never extracts a string, just judges agreement. It achieves 97% recall against human labels, though it sometimes hallucinates approval when the answer is wrong.
Stage 3 — Human Snippet Inspection: For the remaining borderline cases (where both automated graders agree on a mismatch, or where the LLM is uncertain), a human inspects a short snippet around the answer region. This is cheaper than reading the full output.
An additional layer is an iterative nudge mechanism: when the LLM grader cannot decide (e.g., the output lacks an explicit number), the system sends a prompt like “Please output your answer as a floating point number.” The agent regenerates its response, which often resolves the ambiguity. Crucially, they tested nudging with and without re-injecting the original question — re-injection provided no benefit, confirming that the nudge works as a pure answer-template cue.
[agent output]
     |
     v
+-----------------+
| Stage 1: Regex  |--match--> pass/fail
| (keyword-anchor)|
+-----------------+
     | no match
     v
+-----------------+
| Stage 2: LLM    |--judged--> pass/fail
| (lenient judge) |
+-----------------+
     | uncertain
     v
+-----------------+
| nudge mechanism |--agent regenerates---> back to Stage 1
| (template only) |
+-----------------+
     | still fail
     v
+-----------------+
| Stage 3: Human  |--final verdict
| (snippet only)  |
+-----------------+
Structural metaphor: Airport Security Lane
Think of the agent’s output as a passenger’s bag. The evaluation pipeline is a security checkpoint.
-
Stage 1 (Strict Regex) is the metal detector: fast, simple, and catches the most obvious threats (numbers in expected format). But it misses anything that isn’t metal (numbers wrapped in verbose text, spelled as words, etc.). The upgrade from last-number heuristic to keyword-anchored extraction is like adding a more sensitive calibration — now it also catches metal inside shoes.
-
Stage 2 (Lenient LLM) is the X-ray machine: it looks inside the bag, sees past the jumbled items, and can tell if the bottle of water is actually harmless (format differences). But it can misread a laptop as a book (false positive) or miss a tiny blade (false negative).
-
Seasoned agents (nudge mechanism) is the security officer saying “Please take out your laptop” — it guides the passenger to provide the answer in a cleaner form, without changing what’s in the bag. Re-injecting the original question would be like also asking “what airport are you flying from?” — irrelevant to the bag itself, and the paper showed it adds zero value.
-
Stage 3 (Human Snippet Inspection) is the manual bag search — only used for the few bags that still trigger alarms after the first two checks.
The mapping holds: each layer has a distinct failure mode, and the nudge is a cheap way to reduce the cases that reach the expensive human step.
Key Concepts
-
Evaluation Cascade: Combining multiple graders with complementary failure profiles. No single grader is perfect, but a cascade can maintain high precision (by rejecting only when confident) and high recall (by falling through to more flexible graders). The key design choice is the ordering — start with the cheapest, most precise grader, and only escalate when needed. This is not the same as ensemble averaging; it’s a sequential gating mechanism.
-
Keyword-Anchored Extraction (KAE): A parsing strategy that searches for answer-indicating keywords (e.g., “average is”, “result =”) and extracts the numerical value immediately after them, instead of blindly taking the last number in the output. Example: agent output: “I computed the mean. The average is 3.14.” Last-number heuristic would pick 3.14 anyway, but if the output has “The variance is 0.5” after, last-number picks 0.5 erroneously. KAE finds “average is” and correctly gets 3.14. This raised strict regex recall by 60pp — a massive gain from a simple change.
-
Nudge as Template Cue, Not Context Reminder: The nudge prompt (“Please output your answer as a floating point number.”) works because it tells the agent what format the grader expects, not because it reminds it of the problem. The authors showed that adding the original question to the nudge doesn’t improve success rates. This implies that agent failures are often formatting, not reasoning — a practical insight: prompt the agent for a cleaner output, rather than re-explaining the task.
Framework Shift
Before the cascade, evaluation was a binary: either you used a brittle regex (high false negatives) or you paid for human inspection (high cost). This paper reframes grading as a debuggable pipeline with known failure modes and automated escalation.
Before (mainstream approach):        After (this paper):

[agent output]                       [agent output]
     |                                     |
+----------+                         +----------+
| last-num |                         | keyword  |
| heuristic|---> pass/fail [?]       | anchored |---> pass/fail
+----------+                         +----------+
     | fail?                               | fail?
     v                                     v
[human full read]                    [LLM lenient]---> pass/fail
                                          | uncertain
                                          v
                                     [nudge] --> agent re-answer
                                          | still fail
                                          v
                                     [human snippet]
One sentence: From a single brittle heuristic or full human review to a multi-layer cascade with automated nudge and snippet-level human verification — the core shift is treating the grader as an active participant in the evaluation loop, with its own calibration and failure modes.
Expert Assessment
Problem choice: This is a real, not manufactured, gap. As agentic systems proliferate (AutoGPT, Code Interpreter, research agents), the community desperately needs practical evaluation methods. The paper targets a narrow but central pain point — grading format ambiguities — and provides actionable measurements. It sits at the intersection of evaluation methodology and prompt engineering, a spot that is currently underserved.
Method maturity: The approach is clever in its combination, not in any single component. Regex is old; LLM-as-judge is well-studied; nudge is prompt engineering. What’s new is the system-level design and the careful ablation (re-injection vs no re-injection). That’s a legitimate contribution but not a breakthrough algorithm. There are simpler approaches (e.g., asking the LLM to extract the answer first, then compare), but the cascade has a cleaner failure analysis.
Experimental integrity: The study uses 153 QRData tasks from DSGym, which is reasonable. 70 tasks had human labels; that’s modest but enough for initial conclusions. The claim of 100% precision (0/70 false positives) is striking — I’d want to see more tasks to confirm. The nudge experiment is well-designed: comparing with and without re-injection isolates the effect. One red flag: the automated graders’ “observed precision” may be inflated because the human label set is small and possibly biased toward clean examples. The authors acknowledge this. Overall, experiments are honest and transparent.
Writing quality: Clear and well-structured. The authors should have expanded Section 4 (Results) with more per-task breakdowns — the single aggregate number hides variance. The related work section is thin; they could situate themselves better w.r.t. other LLM-as-judge work. If I could rewrite one section, it would be the introduction: it moves too quickly into the method. A more motivational example (a realistic agent output that fails naive grading) would help.
Verdict: weak accept — A solid case study with practical, transferable insights for anyone building an evaluation pipeline for agentic systems. Not earth-shattering, but the nudge recipe alone is worth the read.
Takeaways
Here’s what you can steal for your own projects, right now:
-
Swap last-number heuristic for keyword-anchored extraction. If you’re grading any system that outputs numbers, write a regex that looks for ” = ” or “is ” before a numeral. You’ll gain ~60pp recall with zero precision cost.
-
Build a cascade, not a single grader. Start with the fastest/precisest (regex), fall through to an LLM judge, and only escalate to a human for the unresolved cases. The human only needs to see a snippet around the answer point — not the full output.
-
Use nudges that are pure template cues. If your agent fails to produce a parseable answer, re-prompt it with “output your final answer as a floating point number.” Do not re-inject the original question — it wastes tokens and doesn’t help. This single trick raised pass rates from 16% to 46%.
-
Track variable type in your metadata. The paper found that variable type (float, int, string) was the most predictive metadata for grading behavior. When designing evaluation tasks, include the expected output type in your ground-truth schema — it helps diagnose why a grader fails.
-
Treat your grader as a system under test. Document its failure modes (e.g., false negatives from format, false positives from LLM overconfidence). This paper gives you a template for doing that analysis.
论文: 2606.24839
作者: Tian Zheng, Kai-Tai Hsu
分类: cs.AI, stat.AP
缺口
目前大多数LLM评估聚焦在单轮回答上:MMLU、TruthfulQA或HumanEval等基准只比较生成的答案与标准标签。但智能数据分析系统会生成代码、运行结果和文字诊断,它们的输出根本上更难评分。正确的数值答案可能藏在错误的推理路径后面,或者正确的推理路径产生一个格式不匹配的数字。
社区有两种典型做法:(1)使用简单启发式(比如提取输出中的最后一个数字),接受高假阴性率;(2)让人逐行检查每一条输出,昂贵且缓慢。两者都无法在开发过程中重复扩展使用。
这篇论文的核心问题:能否造一个既精确又灵敏的自动评分器?当评分器与人工判断不一致时,是系统错了还是评分器错了? 作者提出三层级联,结合严格正则匹配、宽松LLM审稿和基于片段的人工检查,并精确测量了每一层的失败模式。关键在于把评分器视为评估管线的一部分——像调试模型一样调试评分器。
[问题:智能体输出 = 代码+数字+文字,评分困难]
          |
          v
[假设:评分伪影 ≠ 系统错误,需要分离]
          |
          v
[方法:三层级联(正则 + LLM + 人工)]
          |
          v
[证据:70个任务上,精度100%,召回97%;提示机制提高通过率]
          |
          v
[结论:可靠评分 = 稳健解析 + 提示策略 + 元数据感知]
增量
一句话: 之前,评估智能分析系统要么用脆弱的最后数字提取(召回27%),要么全人工审查(昂贵);这篇论文之后,我们有了一个经过验证的级联方案,精度100%,召回97%,还有一个具体的提示配方,且不需要重新注入原始问题。
核心机制
评估分为三个阶段,各有不同的失败特征。管线接收智能体的原始输出(可能包含代码、打印语句和最终答案)以及标准答案标签。
第一阶段——严格正则匹配:系统先用正则表达式从输出中提取答案,模式锚定在关键词上(比如”答案是X”或”结果 = Y”)。如果模式干净匹配,就直接与标准值比较。这一阶段快速、确定,精度100%(研究中零假阳性),但召回完全取决于提取的准确性。从朴素最后数字启发式换成关键词锚定提取后,召回率提升了60个百分点(例如从约27%提升到约87%)。
第二阶段——宽松LLM:如果严格正则失败(无匹配或值不匹配),输出被送到基于LLM的审稿器(GPT-4),它阅读整个输出,判断系统的数值答案是否与标准值一致。LLM被指示要宽松:忽略格式差异、四舍五入或多余的诊断信息。这一阶段与解析器无关——它从不提取字符串,只判断一致性。对人工标签的召回率达97%,尽管有时会误判(把错误答案当作正确)。
第三阶段——人工片段检查:对于剩下的边界案例(两个自动评分器都判断不一致,或LLM不确定),人工检查答案区域附近的一段简短输出。这比阅读整个输出便宜得多。
此外还有一个迭代提示机制:当LLM审稿器无法决定时(比如输出中缺少明确的数字),系统发送提示”请将答案输出为浮点数”。智能体重新生成答案,通常可以消除歧义。关键的是,他们对比了带和不带原始问题重新注入的提示——重新注入没有任何好处,这证实了提示作为纯答案模板的引导作用。
[智能体输出]
     |
     v
+---------------+
| 第一层:正则   |--匹配--> 通过/失败
|(关键词锚定)  |
+---------------+
     | 无匹配
     v
+---------------+
| 第二层:LLM   |--判断--> 通过/失败
|(宽松审稿器)  |
+---------------+
     | 不确定
     v
+---------------+
| 提示机制       |--智能体重生成--> 回第一层
|(仅模板)      |
+---------------+
     | 仍失败
     v
+---------------+
| 第三层:人工   |--最终判决
|(仅片段)      |
+---------------+
核喻:机场安检通道
把智能体的输出想象成旅客的行李。评估管线就是安检关卡。
-
第一层(严格正则) 是金属探测器:快速、简单,抓住最明显的威胁(格式正确的数字)。但会漏掉非金属的东西(包装在冗长文字中的数字,或者用单词表示的数值)。从最后数字启发式升级到关键词锚定提取,就像给探测器加了更灵敏的校准——现在也能抓到鞋子里的金属了。
-
第二层(宽松LLM) 是X光机:它能看透行李内部,忽视杂乱物品,判断那瓶水是否无害(格式差异)。但也可能把笔记本误读成书(假阳性),或者漏掉小刀(假阴性)。
-
熟练的提示机制 是安检员说”请把笔记本电脑拿出来”——它引导旅客以更干净的形式提供答案,但不改变行李的内容。重新注入原始问题就像同时问”你从哪个机场飞来的?“——与行李本身无关,论文表明这毫无价值。
-
第三层(人工片段检查) 是手动开包检查——只用于前两层仍然报警的少量情况。
映射成立:每一层有不同的失败模式,提示机制是减少进入昂贵人工步骤的廉价手段。
关键概念
-
评估级联:组合多个互补失败模式的评分器。没有单个评分器是完美的,但级联可以通过在自信时才拒绝来维持高精度,同时通过降级到更灵活的评分器来维持高召回。关键设计是顺序——从最便宜、最精确的评分器开始,只在必要时升级。这和集成平均不同,它是一个顺序门控机制。
-
关键词锚定提取(KAE):一种解析策略,搜索指示答案的关键词(如”平均值为”、“结果=”),提取紧跟其后的数值,而不是盲目取输出中的最后一个数字。举例:智能体输出:“我计算了均值。平均值是3.14。” 最后数字启发式也会正确取到3.14,但如果后面还有”方差是0.5”就会错取0.5。KAE找到”平均值是”,正确得到3.14。这让严格正则的召回提升了60个百分点——一个简单改动带来的巨大收益。
-
提示作为模板引导,而非上下文提醒:提示”请将答案输出为浮点数”之所以有效,是因为它告诉智能体评分器期待的格式,而不是因为它提醒了问题。作者证明在提示中加入原始问题并不会提高成功率。这意味着智能体的失败常常是格式问题,而非推理问题——实际启示:让智能体输出更干净的答案,而不是重新解释任务。
框架转变
在级联之前,评估是二元的:要么用脆弱的正则(高假阴性),要么付钱让人工审查(高成本)。这篇论文把评分重新定义为可调试的管线,具有已知的失败模式和自动升级。
之前(主流方法):              之后(本文方法):

[智能体输出]                     [智能体输出]
     |                                 |
+----------+                    +----------+
| 最后数字   |                    | 关键词     |
| 启发式    |---> 通过/失败[?]    | 锚定提取   |---> 通过/失败
+----------+                    +----------+
     | 失败?                           | 失败?
     v                                 v
[人工全文阅读]                     [LLM宽松]---> 通过/失败
                                         | 不确定
                                         v
                                     [提示] --> 智能体重回答
                                         | 仍失败
                                         v
                                     [人工片段]
一句话:从单个脆弱启发式或全人工审查,到多层级联加自动提示和片段级人工验证——核心转变是把评分器视为评估循环中的主动参与者,有其自身的校准和失败模式。
专家评审
选题眼光: 这是一个真实的缺口,不是人造的。随着智能系统(AutoGPT、Code Interpreter、研究智能体)的普及,社区迫切需要实用的评估方法。论文聚焦在评分格式歧义这个狭窄但核心的痛点,提供了可操作的测量。它处于评估方法论与提示工程的交叉点,目前这个位置被关注不够。
方法成熟度: 思路在组合上聪明,而非单个组件。正则不新;LLM作为审稿器已被广泛研究;提示是提示工程。新的东西是系统级设计和仔细的消融实验(重新注入 vs 不重新注入)。这是合法的贡献,但不是突破性算法。存在更简单的方法(比如先让LLM提取答案再比较),但级联的失败分析更清晰。
实验诚意: 研究使用了DSGym的153个QRData任务,还算合理。70个任务有人工标签,数量适中但足以得出初步结论。声称100%精度(0/70假阳性)很引人注目——我希望能看到更多任务来确认。提示机制实验设计得很好:比较有无重新注入来隔离效果。一个值得警惕之处:自动评分器”观察精度”可能因为人工标签集较小且可能存在清洁偏差而被夸大。作者承认了这点。总体而言,实验诚实透明。
写作功力: 清晰且有结构。作者应该在第4节(结果)中多做一些按任务拆分的分析,单个聚合数字掩盖了方差。相关工作部分过于简略,他们可以更好地定位自己与其他LLM作为审稿器工作的关系。如果要重写一节,我会选引言:它太快地进入方法。一个更有动机的例子(一个真实的、在朴素评分下失败的智能体输出)会更有帮助。
判决: 弱接收 — 一个扎实的案例研究,为任何构建智能系统评估管线的人提供了可迁移的实用洞见。不是惊天动地,但仅凭提示配方就值得一读。
要点总结
以下是可以立刻偷走并在自己项目中使用的具体东西:
-
把最后数字启发式换成关键词锚定提取。如果你在给任何输出数字的系统评分,写一个正则表达式,查找” = “或”是”加后面的数字。你会在精度不变的情况下提升约60个百分点的召回。
-
构建级联,而非单个评分器。从最快最精确的开始(正则),降级到LLM审稿器,只有无法解决的情况才升级到人工。人工只需看答案点附近的一段,而非整个输出。
-
使用纯模板引导的提示。如果你的智能体无法产生可解析的答案,重新提示它”把你的最终答案输出为浮点数”。不要重新注入原始问题——浪费token且无帮助。仅仅这个技巧就把通过率从16%提升到46%。
-
在元数据中记录变量类型。论文发现变量类型(浮点、整数、字符串)是对评分行为预测能力最强的元数据。在设计评估任务时,在标准答案schema中包含预期输出类型——这有助于诊断评分器为什么失败。
-
把你的评分器当作待测系统。记录它的失败模式(例如格式导致的假阴性、LLM过度自信导致的假阳性)。这篇论文给了你一个做这种分析的样板。