Paper: 2605.30341 Authors: Keshigeyan Chandrasegaran, Kyle Sargent, Suchir Agarwal, Michael Jang, Michael Poli, Juan Carlos Niebles, Justin Johnson, Jiajun Wu, Li Fei-Fei Categories: cs.CV, cs.AI
The Gap
Visual generative modeling has hit a reproducibility wall. DALL-E, Stable Diffusion, and Imagen were trained on massive proprietary datasets (LAION-5B, internal Google data) that are either legally questionable, taken offline, or inaccessible. Academic labs can’t reproduce these results. Smaller datasets like ImageNet (1.2M images) are too limited for studying scaling laws. The field needs a large, legally clean, stable dataset that anyone can use.
Prior approaches: LAION scraped the web without verifying licenses (now offline due to CSAM concerns). Proprietary datasets are black boxes. Existing permissive datasets are too small to study modern scaling behavior.
Problem: Can't reproduce SOTA visual generation
   |
   v
Assumption: Need large + permissive + stable dataset
   |
   v
Method: Curate 100M CC-licensed images + VLM captions
   |
   v
Evidence: Train flow matching baseline, release benchmark
   |
   v
Conclusion: Reproducible research infrastructure for visual generation
The Increment
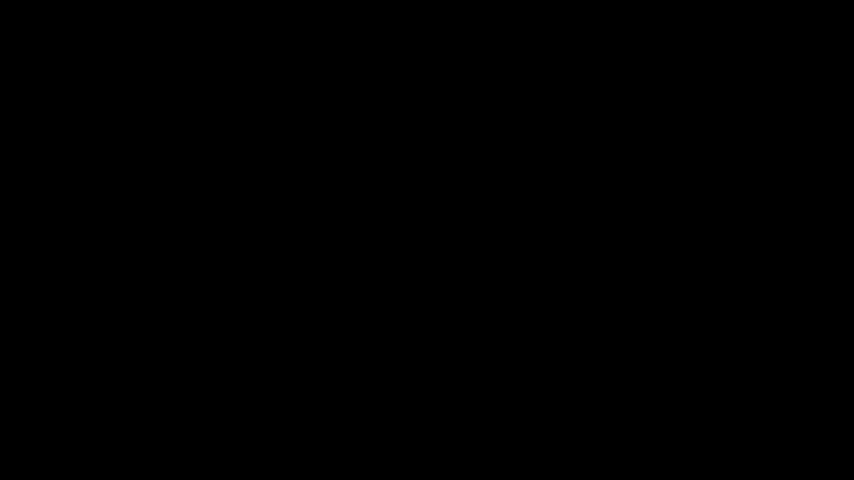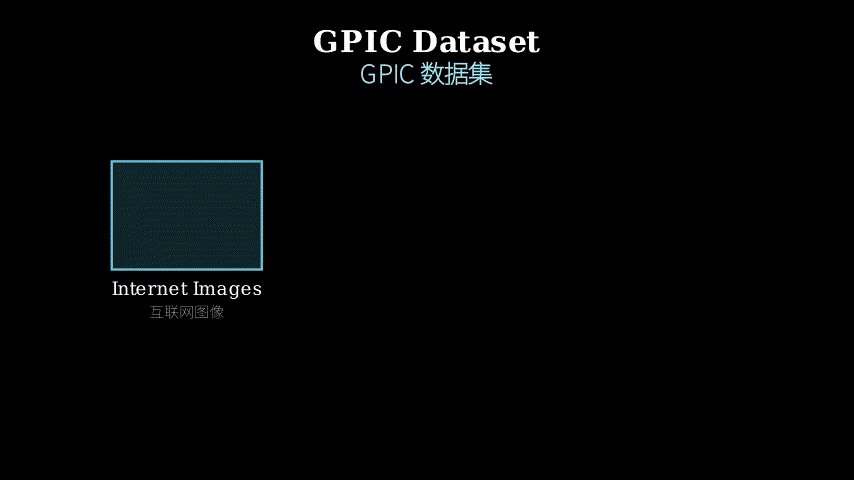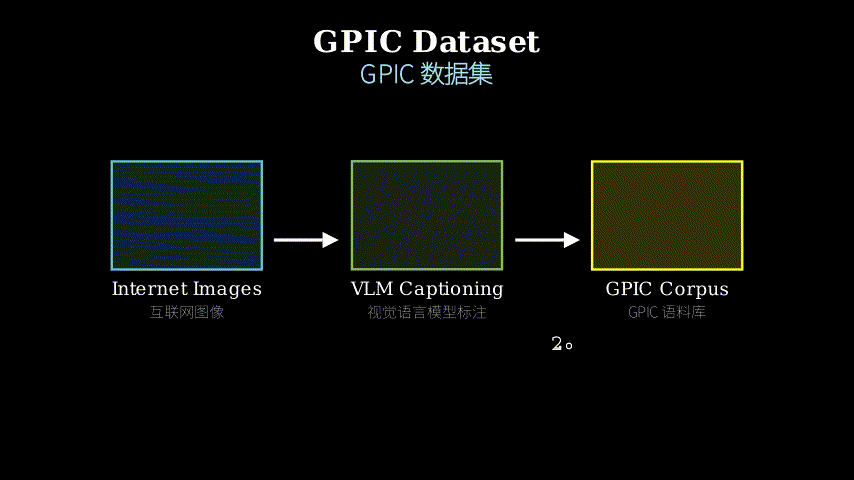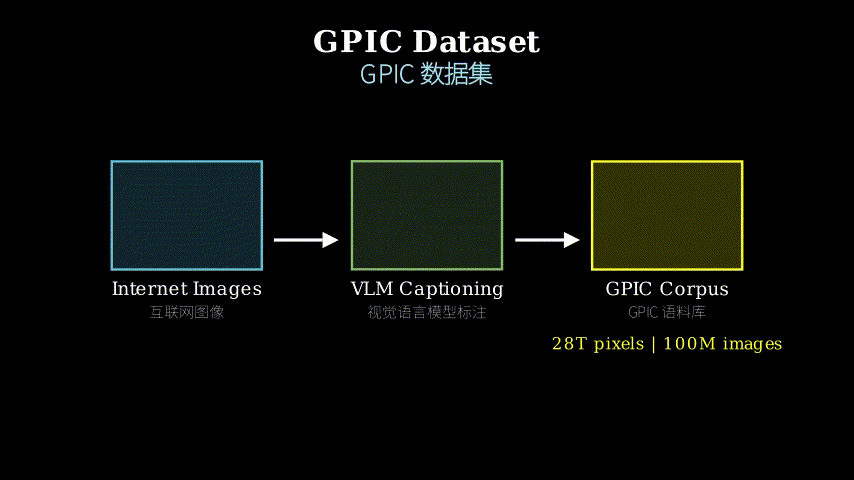
One sentence: Before GPIC, academic labs couldn’t legally train or reproduce large-scale visual generation models; after GPIC, they have a 28 trillion pixel corpus with commercial-use rights and a standardized benchmark.
Core Mechanism
GPIC is a data curation pipeline, not a model. It starts with Common Crawl, filters for Creative Commons licenses (CC0, CC-BY, CC-BY-SA), deduplicates using perceptual hashing, and captions images with a state-of-the-art vision-language model. The result: 100M training images, 200K validation, 1M test, all centrally hosted on Hugging Face.
The dataset includes a benchmarking protocol: FID, CLIP score, and human evaluation metrics. The authors train a pixel-space flow matching model as a reference baseline, establishing performance targets for future work.
Safety filtering removes NSFW content and personally identifiable information. Deduplication prevents train-test leakage. The entire pipeline is documented and reproducible.
Common Crawl --> License Filter --> Perceptual Hash --> VLM Caption --> Safety Filter
                 (CC0/BY/BY-SA)     (deduplicate)      (PaliGemma)     (NSFW/PII)
                                                                             |
                                                                             v
                                                                    100M train images
                                                                    200K val images
                                                                     1M test images
                                                                             |
                                                                             v
                                                                    Hugging Face Hub
Think of GPIC as a public library system. Before, researchers were photocopying books from private collections (LAION) or reading in locked archives (Google’s data). GPIC builds a new library: it acquires books with clear lending rights (CC licenses), catalogs them properly (VLM captions), removes damaged copies (deduplication), and makes everything available through a central branch (Hugging Face). The reference baseline is like the library publishing a reading guide so everyone knows what “good comprehension” looks like.
Key Concepts
-
Permissive licensing: Not all “free” images are legally usable. Creative Commons licenses come in flavors. CC0 (public domain) and CC-BY (attribution required) allow commercial use. CC-BY-NC (non-commercial) does not. GPIC only includes CC0, CC-BY, and CC-BY-SA (share-alike), ensuring researchers can train models and companies can deploy them without legal risk. This matters because LAION’s “fair use” defense collapsed when faced with actual lawsuits.
-
Perceptual hashing: Traditional deduplication compares exact pixel values, missing near-duplicates (crops, resizes, color shifts). Perceptual hashing converts images into compact fingerprints that are similar for visually similar images. GPIC uses this to remove duplicates across the train/val/test split, preventing models from memorizing test examples during training. Without this, FID scores would be artificially inflated.
-
Flow matching: A generative modeling approach that learns to transform noise into images by modeling the probability flow between distributions. Unlike diffusion models (which add noise step-by-step), flow matching directly learns the vector field that transports one distribution to another. The authors use this as their baseline because it’s simpler to implement and scales well, providing a clean reference point for future comparisons.
Framework Shift
Before (LAION era):                  After (GPIC):

Web scrape --> Hope licenses OK      CC filter --> Verified permissive
    |                                    |
    v                                    v
Train model --> Paper published      Train model --> Reproducible
    |                                    |
    v                                    v
Dataset offline --> Can't verify     Stable hosting --> Always available
    |                                    |
    v                                    v
Legal gray zone                      Commercial-use safe
From opportunistic scraping to intentional curation, the core shift is legal stability as a first-class research requirement.
Expert Assessment
Problem choice: Real and urgent. The LAION takedown exposed how fragile the research infrastructure was. This isn’t a manufactured gap—it’s a crisis that already happened. GPIC sits at the intersection of legal compliance and scientific reproducibility, both critical for the field’s maturity.
Method maturity: Straightforward engineering, not algorithmic novelty. The contribution is curation effort and infrastructure, not a clever trick. That’s appropriate here—the field needs a reliable dataset more than another model architecture. The flow matching baseline is competent but not groundbreaking; it’s there to establish a reference point, not push SOTA.
Experimental integrity: The benchmark protocol is solid. FID, CLIP score, and human eval are standard metrics. The baseline results are honest—they don’t claim SOTA, just provide a starting point. One concern: the VLM captioning quality isn’t deeply validated. If captions are noisy, downstream models will inherit that noise. The paper would benefit from a caption quality ablation.
Writing quality: Clear and functional, but the related work section is thin. The paper doesn’t engage deeply with prior dataset efforts (YFCC100M, Conceptual Captions) or explain why 100M images is the right scale. The safety filtering methodology is mentioned but not detailed—what’s the false positive rate? Which NSFW classifier was used? These gaps don’t invalidate the contribution but leave questions for practitioners.
Verdict: strong accept — The field needs this infrastructure, and the execution is competent. Not intellectually dazzling, but practically essential.
Takeaways
For dataset builders: Permissive licensing is now table stakes. If you’re curating data, verify licenses upfront rather than relying on fair use. GPIC’s pipeline (license filter → perceptual hash → safety filter) is a reusable template.
For generative modeling researchers: Use GPIC as your default benchmark. The standardized splits and metrics make results comparable across papers. If you’re training on proprietary data, run a GPIC ablation to show how much performance comes from data scale vs. model design.
For infrastructure teams: Centralized hosting (Hugging Face) matters. Decentralized datasets (torrents, scattered URLs) die when maintainers lose interest. If you’re releasing a dataset, host it somewhere stable and provide a DOI.
Transferable idea: “Legal stability as a feature” applies beyond vision. NLP has similar issues with web-scraped text (Common Crawl, C4). Audio and video generation will face this soon. The GPIC playbook—filter for permissive licenses, deduplicate, centrally host—works for any modality.
论文: 2605.30341 作者: Keshigeyan Chandrasegaran, Kyle Sargent, Suchir Agarwal, Michael Jang, Michael Poli, Juan Carlos Niebles, Justin Johnson, Jiajun Wu, Li Fei-Fei 分类: cs.CV, cs.AI
缺口
视觉生成模型研究撞上了可复现性的墙。
DALL-E、Stable Diffusion、Imagen 都是在大规模专有数据集上训练的(LAION-5B、谷歌内部数据),这些数据要么法律上有问题,要么已经下线,要么根本无法访问。
学术实验室无法复现这些结果。
ImageNet 这样的小数据集(120万图像)太有限,无法研究扩展规律。
该领域需要一个大规模、法律清白、稳定的数据集,任何人都能使用。
此前的方法:LAION 抓取网页但不验证许可证(现因 CSAM 问题下线)。
专有数据集是黑箱。
现有的开放许可数据集太小,无法研究现代扩展行为。
问题:无法复现 SOTA 视觉生成
   |
   v
假设:需要大规模 + 开放许可 + 稳定的数据集
   |
   v
方法:整理 1 亿张 CC 许可图像 + VLM 标注
   |
   v
证据:训练流匹配基线,发布基准测试
   |
   v
结论:视觉生成的可复现研究基础设施
增量
一句话:GPIC 之前,学术实验室无法合法训练或复现大规模视觉生成模型;GPIC 之后,他们有了一个包含 28 万亿像素、具有商业使用权的语料库和标准化基准测试。
核心机制
GPIC 是一个数据整理流水线,不是模型。
它从 Common Crawl 开始,筛选 Creative Commons 许可证(CC0、CC-BY、CC-BY-SA),使用感知哈希去重,用最先进的视觉-语言模型为图像生成标注。
结果:1 亿张训练图像、20 万张验证图像、100 万张测试图像,全部集中托管在 Hugging Face 上。
数据集包含一个基准测试协议:FID、CLIP 分数和人工评估指标。
作者训练了一个像素空间流匹配模型作为参考基线,为未来工作建立性能目标。
安全过滤移除 NSFW 内容和个人身份信息。
去重防止训练-测试泄漏。
整个流水线都有文档记录且可复现。
Common Crawl --> 许可证过滤 --> 感知哈希 --> VLM 标注 --> 安全过滤
                 (CC0/BY/BY-SA)  (去重)      (PaliGemma)   (NSFW/PII)
                                                                 |
                                                                 v
                                                        1 亿训练图像
                                                        20 万验证图像
                                                        100 万测试图像
                                                                 |
                                                                 v
                                                        Hugging Face Hub
把 GPIC 想象成一个公共图书馆系统。
以前,研究者从私人藏书中复印书籍(LAION),或在上锁的档案馆里阅读(谷歌的数据)。
GPIC 建立了一个新图书馆:它获取有明确借阅权的书籍(CC 许可证),妥善编目(VLM 标注),移除损坏的副本(去重),并通过中心分馆提供一切(Hugging Face)。
参考基线就像图书馆发布的阅读指南,让每个人都知道什么是”良好的理解”。
关键概念
- 开放许可:并非所有”免费”图像都可以合法使用。
Creative Commons 许可证有不同类型。
CC0(公有领域)和 CC-BY(需署名)允许商业使用。
CC-BY-NC(非商业)不允许。
GPIC 只包含 CC0、CC-BY 和 CC-BY-SA(相同方式共享),确保研究者可以训练模型,公司可以部署它们,没有法律风险。
这很重要,因为 LAION 的”合理使用”辩护在面对实际诉讼时崩溃了。
- 感知哈希:传统去重比较精确的像素值,会遗漏近似重复(裁剪、缩放、颜色变化)。
感知哈希将图像转换为紧凑的指纹,视觉上相似的图像具有相似的指纹。
GPIC 使用它来移除训练/验证/测试集中的重复项,防止模型在训练期间记住测试样本。
没有这个,FID 分数会被人为抬高。
- 流匹配:一种生成建模方法,通过建模分布之间的概率流来学习将噪声转换为图像。
与扩散模型(逐步添加噪声)不同,流匹配直接学习将一个分布传输到另一个分布的向量场。
作者使用它作为基线,因为它实现更简单且扩展性好,为未来比较提供了一个干净的参考点。
框架转变
之前(LAION 时代):              之后(GPIC):

网页抓取 --> 希望许可证没问题      CC 过滤 --> 验证开放许可
    |                                    |
    v                                    v
训练模型 --> 论文发表              训练模型 --> 可复现
    |                                    |
    v                                    v
数据集下线 --> 无法验证            稳定托管 --> 始终可用
    |                                    |
    v                                    v
法律灰色地带                       商业使用安全
从机会主义抓取到有意识整理,核心转变是将法律稳定性作为一等研究需求。
专家评审
选题眼光:真实且紧迫。
LAION 下线暴露了研究基础设施有多脆弱。
这不是人造缺口——这是已经发生的危机。
GPIC 处于法律合规和科学可复现性的交叉点,两者对该领域的成熟都至关重要。
方法成熟度:直接的工程,不是算法创新。
贡献是整理工作和基础设施,不是巧妙的技巧。
这在这里是合适的——该领域需要一个可靠的数据集,而不是另一个模型架构。
流匹配基线是称职的,但不是突破性的;它在那里是为了建立参考点,而不是推动 SOTA。
实验诚意:基准测试协议是扎实的。
FID、CLIP 分数和人工评估是标准指标。
基线结果是诚实的——他们不声称 SOTA,只是提供一个起点。
一个担忧:VLM 标注质量没有深入验证。
如果标注有噪声,下游模型会继承这种噪声。
论文将受益于标注质量消融实验。
写作功力:清晰且实用,但相关工作部分很薄。
论文没有深入讨论先前的数据集工作(YFCC100M、Conceptual Captions),也没有解释为什么 1 亿张图像是正确的规模。
安全过滤方法被提及但没有详细说明——误报率是多少?使用了哪个 NSFW 分类器?这些缺口不会使贡献无效,但给实践者留下了问题。
判决:强接收 — 该领域需要这个基础设施,执行是称职的。
不是智力上令人眼花缭乱,但实际上是必不可少的。
要点总结
对数据集构建者:开放许可现在是基本要求。
如果你在整理数据,请预先验证许可证,而不是依赖合理使用。
GPIC 的流水线(许可证过滤 → 感知哈希 → 安全过滤)是一个可重用的模板。
对生成建模研究者:使用 GPIC 作为你的默认基准测试。
标准化的划分和指标使论文之间的结果可比较。
如果你在专有数据上训练,运行 GPIC 消融实验以显示有多少性能来自数据规模与模型设计。
对基础设施团队:集中托管(Hugging Face)很重要。
去中心化数据集(种子、分散的 URL)在维护者失去兴趣时会消亡。
如果你要发布数据集,请将其托管在稳定的地方并提供 DOI。
可迁移的想法:“法律稳定性作为特性”适用于视觉之外。
NLP 在网页抓取文本(Common Crawl、C4)方面有类似问题。
音频和视频生成很快也会面临这个问题。
GPIC 的剧本——过滤开放许可证、去重、集中托管——适用于任何模态。