Paper: 2605.30352 Authors: Junyu Xie, Tengda Han, Weidi Xie, Andrew Zisserman Categories: cs.CV
The Gap
Moving Object Segmentation (MOS) methods have been stuck in a 2D+sequence paradigm: they rely on pre-computed optical flow or point trajectories (losing 3D geometry), and they treat “moving” as a video-level label (a car is either “moving throughout the video” or not), ignoring that objects start and stop moving at specific frames. This creates two concrete failures: (1) a parked car that drives away mid-video gets mislabeled for half its frames, and (2) depth ambiguities cause false positives when camera motion mimics object motion in 2D projections.
Prior work like OCLR and CaDeX use optical flow as input, which collapses 3D motion onto 2D image planes. MoCA-Mask uses point trajectories but still operates in 2D feature space. All treat motion as a sequence-level binary attribute, requiring objects to move consistently across the entire video to be detected.
Problem: 2D auxiliary inputs + sequence-level motion labels
   |
   v
Assumption: 3D geometry + frame-level motion state needed
   |
   v
Method: Direct RGB -> 3D scene representation -> per-frame motion queries
   |
   v
Evidence: +8.2% J&F on MOS benchmarks, 3.8x faster than multi-object baselines
   |
   v
Conclusion: Grounding in 3D space-time enables finer temporal control
The Increment
One sentence: Before GMOS, moving object segmentation required pre-computed 2D motion cues and treated motion as a video-level attribute; after GMOS, systems can segment moving objects directly from RGB with 3D awareness and frame-level temporal precision.
Core Mechanism
GMOS operates in three stages. First, a video encoder processes RGB frames into per-frame feature maps. Second, a 3D scene decoder lifts these 2D features into a volumetric representation using learned depth and camera pose estimation—this is where 3D grounding happens. Third, a motion query module samples this 3D volume at each frame and predicts per-object motion states (moving/static) and segmentation masks simultaneously.
The 3D scene decoder is the critical component. It doesn’t just stack 2D features; it explicitly models depth and camera motion to construct a consistent 3D representation across frames. When an object moves, its 3D position changes relative to this world-centric volume. The motion query module then asks: “At frame t, which 3D regions are changing position?” This question is answerable because the representation is grounded in 3D—camera motion is factored out, so only true object motion remains.
RGB Video (T frames)
   |
   v
[Video Encoder] --> 2D features per frame
   |
   v
[3D Scene Decoder] --> Volumetric representation
   |                    (depth + camera pose)
   v
[Motion Query Module] --> Per-frame motion state + masks
   |
   v
Output: \{mask_t, moving_t\} for each object at each frame t
Think of GMOS as a security system with depth-sensing cameras. Old systems (prior MOS methods) watch 2D video feeds and flag anything that moves on screen—but they can’t tell if motion is from an intruder walking or the camera panning. They also decide “this hallway has motion” for the entire night shift, missing when the intruder actually entered. GMOS builds a 3D map of the building first (the volumetric scene representation), then tracks which 3D positions change at each moment. Camera panning just rotates the viewpoint in the 3D map—it doesn’t create false alarms. And because it checks every frame independently, it knows the intruder entered at 2
AM, not just “sometime during the night.”Key Concepts
-
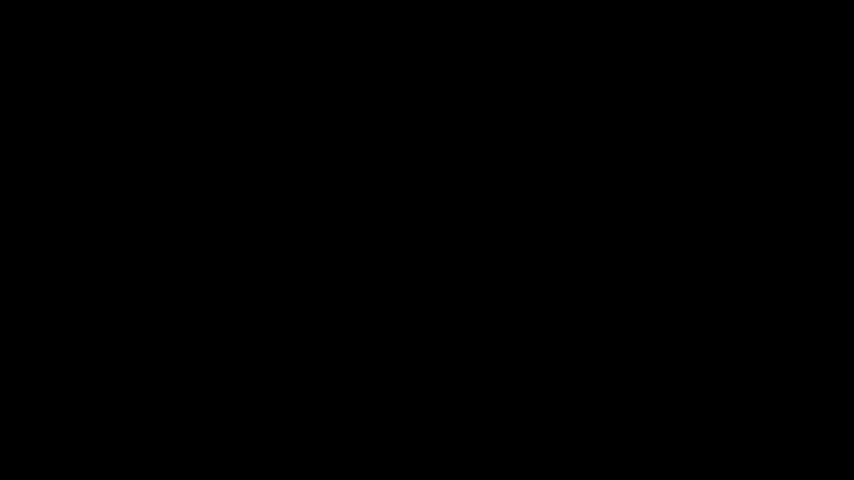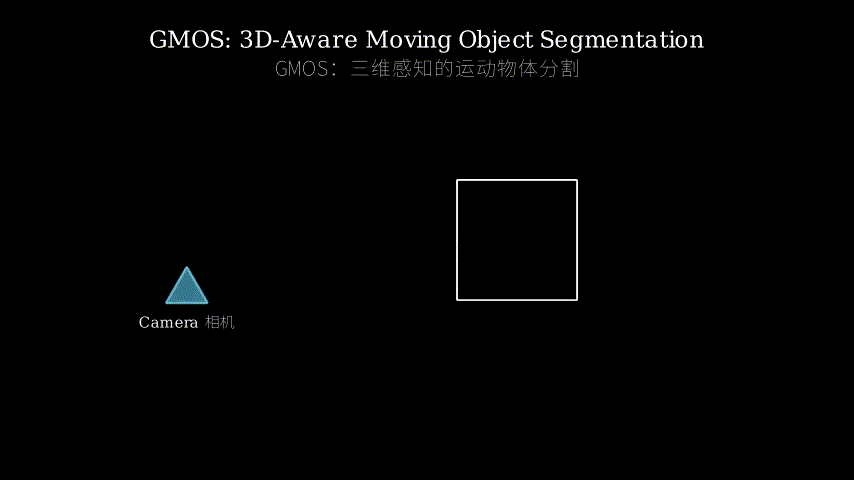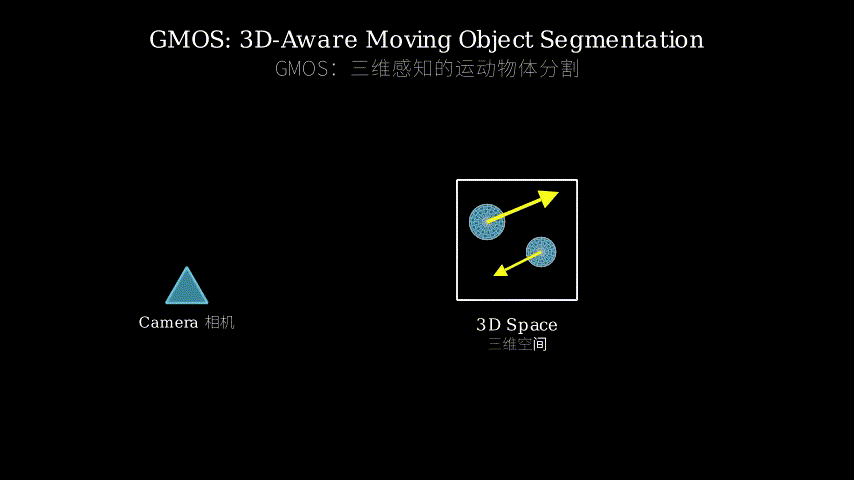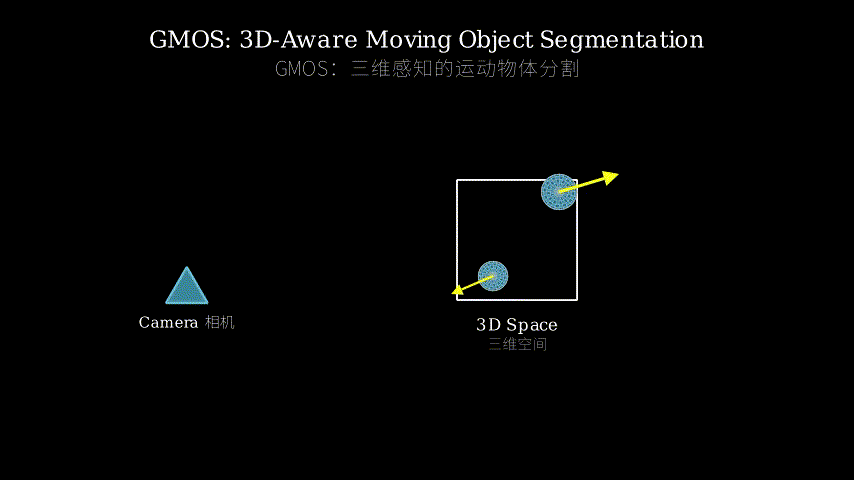
3D Scene Grounding: Instead of analyzing motion in 2D image coordinates where camera movement and object movement are entangled, GMOS lifts features into a 3D volumetric space where camera pose is explicitly modeled. Imagine watching a car from a moving train—in your 2D view, the car appears to move even if it’s parked. But if you know the train’s motion and reconstruct the 3D scene, you can tell the car is stationary in world coordinates. GMOS does this computationally: it estimates depth and camera trajectory, then represents the scene in 3D where only true object motion (not camera-induced apparent motion) shows up as position changes across frames.
-
Instantaneous Motion State: Prior MOS methods label objects as “moving” or “static” for an entire video sequence. But real objects transition—a person walks, stops, walks again. GMOS introduces per-frame motion queries that predict whether each object is moving at each specific frame. This is like the difference between saying “John exercised this week” (sequence-level) versus having a timestamped log showing John ran at 7 AM Monday, rested Tuesday, ran again Wednesday (frame-level). The latter enables precise temporal reasoning: you can ask “which objects were moving when the collision occurred?” rather than “which objects moved at some point in the video?”
-
GMOS-2K Dataset: Existing MOS datasets only have sequence-level motion labels (object X moves in video Y). The authors manually annotated 2,210 videos from five VOS benchmarks with per-frame motion states—for each object, marking which frames it’s actually moving versus static. This is tedious but necessary: without ground truth for instantaneous motion, you can’t train or evaluate frame-level motion prediction. It’s like the difference between a movie’s genre tag (action film) versus scene-by-scene annotations (action in minutes 5-12, dialogue in 13-20). The latter enables fine-grained analysis.
Framework Shift
Before (mainstream approach):        After (this paper):

Video --> [Optical Flow] ----+       Video --> [3D Scene Decoder]
          [Point Tracks]  ---|           |
                |              |         v
                v              |     Volumetric Repr.
          2D Motion Features   |         |
                |              |         v
                v              |     [Motion Query]
          [Sequence Classifier]|         |
                |              |         +---> Per-frame
                v              |               motion state
          Video-level label    |               + masks
          (moving/static)      |
                               |
Key: Pre-computed 2D cues,    Key: Direct RGB input,
     sequence-level motion         3D grounding,
                                   frame-level motion
From 2D+sequence to 3D+instantaneous, the core shift is replacing auxiliary motion inputs with learned 3D scene structure that enables frame-level motion reasoning.
Expert Assessment
Problem choice: Real gap. Sequence-level motion labels genuinely limit temporal reasoning—you can’t answer “when did the object start moving?” with current methods. The 3D grounding addresses a known failure mode (camera motion confounds 2D motion cues) that practitioners encounter in robotics and autonomous driving. This sits at the intersection of MOS and 3D scene understanding, a natural evolution as video models mature.
Method maturity: The 3D scene decoder is the clever bit—it’s not just depth estimation bolted on, but a learned volumetric representation that factors camera motion. However, the motion query module is fairly standard transformer queries. The design is clean but not groundbreaking; the real contribution is showing that 3D grounding + frame-level queries work better than 2D flow + sequence labels. No simpler approach is obviously overlooked, though one could question whether full volumetric reconstruction is necessary or if depth maps alone suffice (the paper doesn’t ablate this thoroughly).
Experimental integrity: Baselines are fair—they compare against recent MOS methods (OCLR, MoCA-Mask, CaDeX) and unsupervised VOS methods. The new MOS-I protocol with three metrics (temporal precision, recall, F1) is well-motivated. However, the GMOS-2K dataset annotations are single-annotator with no inter-rater reliability reported, which is a weakness for a dataset contribution. The speed comparisons are honest (they’re faster than multi-object methods but slower than single-object variants). One red flag: the paper doesn’t show failure cases or discuss when 3D grounding fails (e.g., textureless scenes where depth estimation degrades).
Writing quality: The abstract and introduction are crisp. The method section is dense—Figure 2 (architecture diagram) tries to show too much at once and would benefit from being split into separate diagrams for each stage. The related work section is thorough but reads like a literature review rather than positioning the contribution. The experimental section is strong, but the ablation study (Table 4) is buried and should be elevated—it’s where the 3D grounding claim is actually validated. Rewriting Section 3.2 (3D Scene Decoder) with a concrete example walkthrough would make the method much more accessible.
Verdict: weak accept — Solid contribution with real-world applicability, but the method is more “careful engineering of known components” than a conceptual breakthrough, and the dataset annotation quality needs validation.
Takeaways
Steal the 3D grounding pattern: If you’re working on any video understanding task where camera motion confounds your signal (action recognition, video anomaly detection, sports analytics), consider lifting 2D features into 3D before reasoning. The key is explicit camera pose estimation—don’t just use depth maps, model the camera trajectory so you can factor it out.
Frame-level queries beat sequence-level labels: When your task has temporal structure (objects transition between states), don’t collapse it into a single label. Use per-frame queries and let the model learn temporal consistency implicitly. This applies beyond MOS—think video captioning (what’s happening *now vs. summarizing the whole clip) or audio event detection (when did the glass break, not just “glass broke in this recording”).
Dataset annotation strategy: The GMOS-2K approach—taking existing datasets and adding finer-grained annotations—is cheaper than collecting new data. If your field has coarse labels (image-level tags, video-level categories), consider whether frame-level or region-level annotations would unlock new capabilities. The annotation cost is real but often feasible for 2K samples.
论文: 2605.30352 作者: Junyu Xie, Tengda Han, Weidi Xie, Andrew Zisserman 分类: cs.CV
缺口
运动物体分割(MOS)方法一直困在”二维+序列”范式里:它们依赖预计算的光流或点轨迹(丢失三维几何信息),并且把”运动”当作视频级标签(一辆车要么”整个视频都在动”,要么不动),忽略了物体在特定帧开始和停止运动。
这造成两个具体失效:(1)一辆停着的车在视频中途开走,有一半帧会被错误标注;(2)当相机运动在二维投影中模仿物体运动时,深度歧义导致误报。
此前的工作如 OCLR 和 CaDeX 使用光流作为输入,把三维运动压缩到二维图像平面上。
MoCA-Mask 使用点轨迹但仍在二维特征空间操作。
所有方法都把运动当作序列级二元属性,要求物体在整个视频中持续运动才能被检测到。
问题:二维辅助输入 + 序列级运动标签
   |
   v
假设:需要三维几何 + 帧级运动状态
   |
   v
方法:直接 RGB -> 三维场景表示 -> 逐帧运动查询
   |
   v
证据:MOS 基准上 +8.2% J&F,比多物体基线快 3.8 倍
   |
   v
结论:在三维时空中定位能实现更精细的时间控制
增量
一句话:GMOS 之前,运动物体分割需要预计算的二维运动线索并把运动当作视频级属性;GMOS 之后,系统能直接从 RGB 分割运动物体,具备三维感知和帧级时间精度。
核心机制
GMOS 分三个阶段运作。
第一,视频编码器把 RGB 帧处理成逐帧特征图。
第二,三维场景解码器用学习到的深度和相机位姿估计把这些二维特征提升到体积表示——这是三维定位发生的地方。
第三,运动查询模块在每一帧采样这个三维体积,同时预测每个物体的运动状态(运动/静止)和分割掩码。
三维场景解码器是关键组件。
它不只是堆叠二维特征;它显式建模深度和相机运动,构建跨帧一致的三维表示。
当物体移动时,它的三维位置相对于这个以世界为中心的体积发生变化。
运动查询模块然后问:“在第 t 帧,哪些三维区域在改变位置?“这个问题可以回答,因为表示是三维定位的——相机运动被分解出去,只剩下真实的物体运动。
RGB 视频(T 帧)
   |
   v
[视频编码器] --> 逐帧二维特征
   |
   v
[三维场景解码器] --> 体积表示
   |                   (深度 + 相机位姿)
   v
[运动查询模块] --> 逐帧运动状态 + 掩码
   |
   v
输出:每个物体在每帧 t 的 \{mask_t, moving_t\}
把 GMOS 想象成带深度感知摄像头的安防系统。
旧系统(之前的 MOS 方法)看二维视频流,标记屏幕上任何移动的东西——但它们分不清运动是入侵者走动还是相机平移。
它们还会判定”这条走廊整晚都有运动”,错过入侵者实际进入的时刻。
GMOS 先建立建筑物的三维地图(体积场景表示),然后追踪哪些三维位置在每个时刻发生变化。
相机平移只是旋转三维地图中的视角——不会产生误报。
因为它独立检查每一帧,它知道入侵者在凌晨 2:37 进入,而不只是”夜间某个时候”。
关键概念
- 三维场景定位:GMOS 不在二维图像坐标中分析运动(相机运动和物体运动纠缠在一起),而是把特征提升到三维体积空间,其中相机位姿被显式建模。
想象你在移动的火车上看一辆车——在你的二维视野中,即使车是停着的,它看起来也在动。
但如果你知道火车的运动并重建三维场景,你能判断车在世界坐标中是静止的。
GMOS 在计算上做这件事:它估计深度和相机轨迹,然后在三维中表示场景,只有真实的物体运动(不是相机引起的表观运动)会显示为跨帧的位置变化。
- 瞬时运动状态:之前的 MOS 方法把物体标记为整个视频序列的”运动”或”静止”。
但真实物体会转换——一个人走路、停下、再走。
GMOS 引入逐帧运动查询,预测每个物体在每个特定帧是否在运动。
这就像”约翰这周锻炼了”(序列级)和有时间戳日志显示约翰周一早上 7 点跑步、周二休息、周三再跑(帧级)的区别。
后者能实现精确的时间推理:你可以问”碰撞发生时哪些物体在运动?“而不是”哪些物体在视频中某个时候运动过?”
- GMOS-2K 数据集:现有 MOS 数据集只有序列级运动标签(物体 X 在视频 Y 中运动)。
作者手动标注了来自五个 VOS 基准的 2,210 个视频的逐帧运动状态——对每个物体,标记它实际运动和静止的帧。
这很繁琐但必要:没有瞬时运动的真值,你无法训练或评估帧级运动预测。
这就像电影的类型标签(动作片)和逐场景标注(5-12 分钟动作,13-20 分钟对话)的区别。
后者能实现细粒度分析。
框架转变
之前(主流方法):                之后(本文方法):

视频 --> [光流] --------+         视频 --> [三维场景解码器]
         [点轨迹] ------|             |
              |          |             v
              v          |         体积表示
        二维运动特征     |             |
              |          |             v
              v          |         [运动查询]
        [序列分类器]     |             |
              |          |             +---> 逐帧
              v          |                   运动状态
        视频级标签       |                   + 掩码
        (运动/静止)      |
                         |
关键:预计算二维线索,  关键:直接 RGB 输入,
      序列级运动              三维定位,
                              帧级运动
从二维+序列到三维+瞬时,核心转变是用学习到的三维场景结构替代辅助运动输入,实现帧级运动推理。
专家评审
选题眼光:真实缺口。
序列级运动标签确实限制了时间推理——你无法用现有方法回答”物体何时开始运动?“三维定位解决了一个已知的失效模式(相机运动混淆二维运动线索),这是机器人和自动驾驶从业者遇到的问题。
这处于 MOS 和三维场景理解的交叉点,是视频模型成熟的自然演进。
方法成熟度:三维场景解码器是巧妙之处——它不只是附加的深度估计,而是学习到的体积表示,分解相机运动。
但运动查询模块是相当标准的 transformer 查询。
设计干净但不算突破性;真正的贡献是展示三维定位+帧级查询比二维光流+序列标签效果更好。
没有明显被忽略的更简单方法,尽管可以质疑是否需要完整的体积重建,或者深度图是否足够(论文没有充分消融这一点)。
实验诚意:基线公平——他们与最近的 MOS 方法(OCLR、MoCA-Mask、CaDeX)和无监督 VOS 方法比较。
新的 MOS-I 协议有三个指标(时间精度、召回率、F1),动机充分。
但 GMOS-2K 数据集标注是单标注者,没有报告标注者间可靠性,这对数据集贡献是个弱点。
速度比较是诚实的(他们比多物体方法快,但比单物体变体慢)。
一个警示:论文没有展示失败案例或讨论三维定位何时失效(例如,深度估计退化的无纹理场景)。
写作功力:摘要和引言简洁。
方法部分密集——图 2(架构图)试图一次展示太多,应该拆分成每个阶段的独立图。
相关工作部分详尽但读起来像文献综述而非定位贡献。
实验部分强,但消融研究(表 4)被埋没了,应该提升——那是三维定位声明实际被验证的地方。
重写 3.2 节(三维场景解码器)并加入具体示例演练会让方法更易理解。
判决:弱接收 — 扎实的贡献,有实际应用价值,但方法更像是”已知组件的精心工程”而非概念突破,数据集标注质量需要验证。
要点总结
偷走三维定位模式:如果你在做任何相机运动混淆信号的视频理解任务(动作识别、视频异常检测、体育分析),考虑在推理前把二维特征提升到三维。
关键是显式的相机位姿估计——不只是用深度图,要建模相机轨迹以便分解它。
帧级查询胜过序列级标签:当你的任务有时间结构(物体在状态间转换),不要把它压缩成单个标签。
使用逐帧查询,让模型隐式学习时间一致性。
这适用于 MOS 之外——想想视频字幕(现在发生什么 vs. 总结整个片段)或音频事件检测(玻璃何时破碎,而不只是”这段录音中玻璃破了”)。
数据集标注策略:GMOS-2K 方法——拿现有数据集添加更细粒度的标注——比收集新数据便宜。
如果你的领域有粗粒度标签(图像级标签、视频级类别),考虑帧级或区域级标注是否会解锁新能力。
标注成本是真实的,但对 2K 样本通常可行。