Paper: 2606.24829 Authors: Chenrui Fan, Paolo Favaro Categories: cs.CV
The Gap
Mainstream T2V evaluation (FVD, CLIP score, aesthetic scores) treats each frame independently or checks temporal smoothness.
These metrics cannot tell whether a video that looks like a camera orbit actually corresponds to a single rigid 3D scene:
the chair might morph between frames, or the background might drift without the viewer noticing.
Prior 3D-aware benchmarks (e.g., DreamBooth-style multi-view datasets) either require ground-truth 3D or limit to synthetic data.
GeoT2V-Bench bridges this: it diagnoses, without ground-truth 3D, whether a camera-prompted T2V clip can support explicit rigid reconstruction.
[Problem: T2V videos look good but fail 3D consistency]
    |
    v
[Assumption: Visual plausibility != static 3D coherence]
    |
    v
[Method: Reconstruction pipeline with flexible + static GS]
    |
    v
[Evidence: 5-metric profile exposes orthogonal failure modes]
    |
    v
[Conclusion: Need holistic 3D consistency, not single score]
The Increment
One sentence: Before, no tool could tell you *why a camera-prompted video was wrong in 3D; now GeoT2V-Bench gives a continuous, multi-axis diagnosis.
Core Mechanism
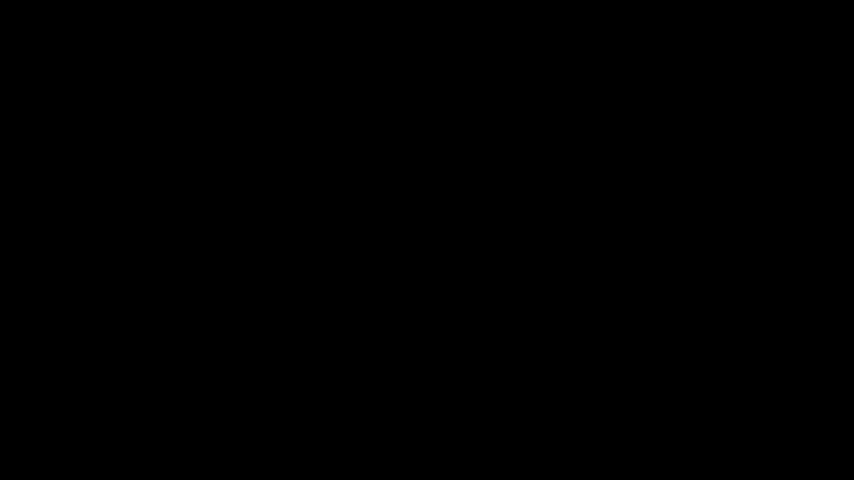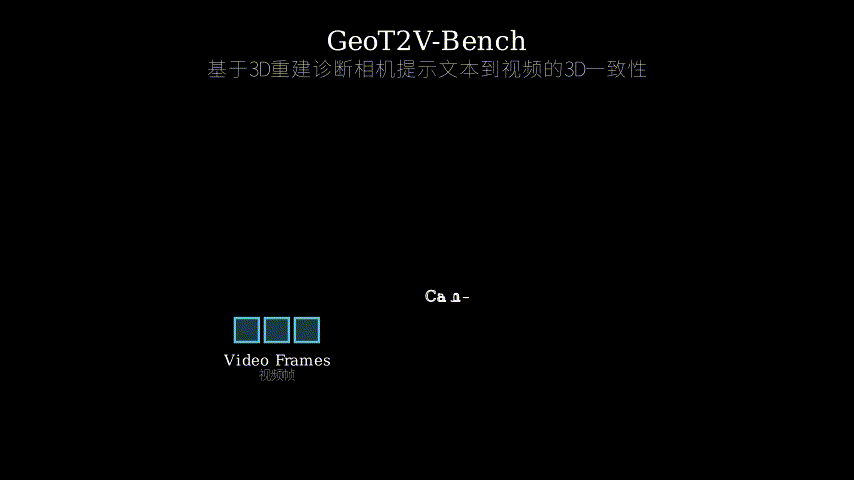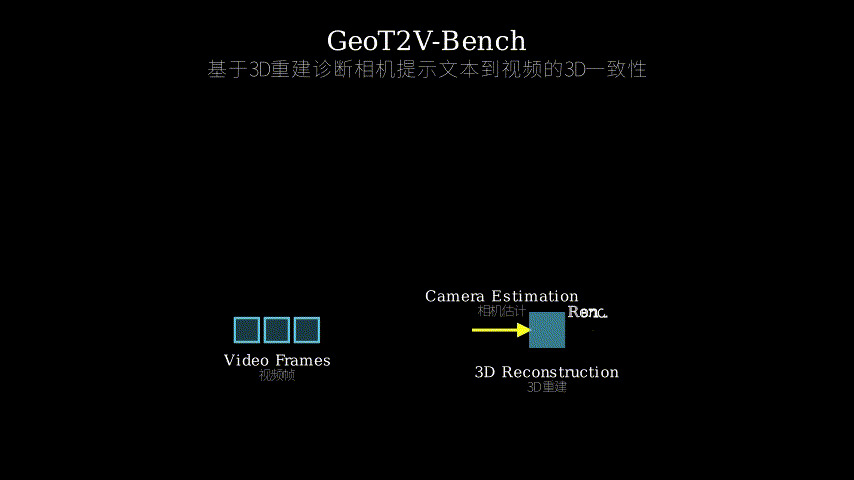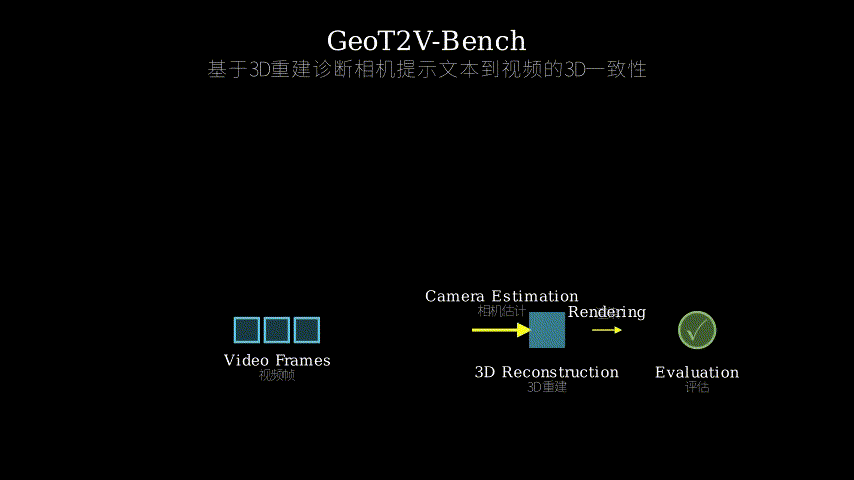
The pipeline runs on a single T2V clip (given a camera prompt) and outputs five continuous curves.
Step 1: Per-frame camera intrinsics & poses are estimated with VGGT-style geometry (a 3D-aware network).
Step 2: A Deformable Gaussian Splatting (DeformableGS) model is fitted to the whole clip – it can move each Gaussian per frame to explain motion.
Step 3: The temporal median of all Gaussians’ positions yields a *MedianGS proxy – a rigid static reconstruction under the assumption that non-rigid motion is noise.
Step 4: New frames are rendered from both models along the estimated camera path.
Step 5: Five metrics are computed per frame: apparent motion magnitude, trajectory deviation, MedianGS reconstruction error, optical flow agreement between MedianGS renders and the original video, and the gap between DeformableGS (flexible) and MedianGS (static) renderings.
The key insight: the five metrics rarely agree, so each catches a different failure type – e.g., wobbling trajectory, non-rigid object deformation, or static reconstruction collapse.
[Input: video frames + camera prompt]
    |
    v
[VGGT] -> intrinsics + poses per frame
    |
    v
[DeformableGS] -> per-frame deformable field (flexible)
    |
    v
[MedianGS] -> static proxy (median over time)
    |
    +--------------------+--------------------+
    |                    |                    |
[Render along path] [Render along path]  [Compare renders]
    |                    |                    |
[v] Apparent motion [v] Trajectory     [v] 5 metrics
Structural metaphor: Think of a film set’s “blueprint check.”
- VGGT is a laser rangefinder that measures where the camera was for each take.
- DeformableGS is a sculptor who can *push any patch of clay between frames — this captures if objects actually moved (e.g., an actor turning).
- MedianGS is a plaster cast that freezes the clay into one shape assuming the set is rigid.
- The five metrics are different inspectors: one checks if the camera path looks smooth (trajectory), another whether the plaster cast matches each raw video frame (static reconstruction error), a third whether the optical flow of the plaster video agrees with the original video, etc.
If the sculptor’s pushes are large but the plaster cast looks terrible, the video probably has dynamic deformation rather than a static scene. If the plaster cast looks fine but the trajectory is erratic, the camera prompt was ill-posed. The metaphor holds because each role has a distinct failure signature.
Key Concepts
-
DeformableGS: A 3D Gaussian representation where each Gaussian has a per-frame offset. It can model moving objects or drifting backgrounds. In this pipeline, its render quality acts as an *upper bound — if even the flexible model fails, the video is irrecoverably bad.
-
MedianGS: A static scene proxy created by taking the temporal median of each Gaussian’s position/scale from DeformableGS. It represents what the scene *should look like if all motion were removed. Its reconstruction error reveals how much non-rigid deformation exists.
-
Reconstruction Profile: Instead of a single pass/fail score, the benchmark outputs five curves over time (one per metric). The profile exposes *which kind of inconsistency plagues a video: e.g., high static-reconstruction error + low flow agreement = deep 3D inconsistency; high trajectory deviation = camera prompt misalignment.
Framework Shift
The old approach evaluates videos as sequences of images; the new approach evaluates them as candidate 3D captures.
Before (mainstream):              After (this paper):
[T2V clip]                        [T2V clip]
   |                                  |
[Frame-level metrics]             [3D reconstruction]
   |                                  |
[Single score]                    [5-axis profile]
   |                                  |
[Answer: "good" or "bad"]        [Answer: "which failure mode?"]
One sentence: From judging *visual appearance to diagnosing 3D consistency, the core shift is treating video as a multi-view capture rather than an animated flat image.
Expert Assessment
Problem choice: Real gap. As T2V with camera control matures, creators need to know if the output can be treated as a real scene. The field was lacking a diagnostic benchmark; this fills it logically. Sits exactly at the boundary between generation quality and 3D geometric correctness.
Method maturity: Clever combination of off-the-shelf components (VGGT, 3DGS) with a novel aggregation trick (MedianGS). The multi-metric profile is the main innovation, not the individual parts. There’s some brute force (fitting DeformableGS is expensive), but the authors are aware and provide completed reconstructions for reproducibility.
Experimental integrity: Fair – uses 4 seeds, 12 model configs (including open-weight like ZeroScope, ModelScope, etc.), 80 prompts from GeCo-Eval. The finding that metrics disagree is well-supported. One red flag: VGGT might be biased toward videos that resemble training data, but the authors use a fixed estimator, so comparisons across models remain valid.
Writing quality: Abstract and introduction are clear. The methodology section is dense but logically ordered. The experiments section could be improved by showing a single failure-mode visualization per metric (they provide some, but a dedicated “diagnosis card” per video would elevate the paper).
Verdict: weak accept — solid, needed benchmark, but the method is more diagnostic than generative; impact depends on adoption by the T2V community.
Takeaways
- MedianGS as cheap 3D consistency proxy: Anyone working with T2V can plug this into their own pipeline (after estimating cameras) to get a per-frame static reconstruction error without training a new model.
- Multi-metric profiles beat single scores: A pass/fail mask hides the specific failure. For debugging a T2V model, knowing it suffers from *static reconstruction collapse (high MedianGS error) vs camera drift (trajectory deviation) saves hours.
- Four-seed evaluation is a fair practice: Many benchmarks use one seed; the authors show that model ranking changes across seeds, so future benchmarks should adopt multi-seed evaluation.
论文: 2606.24829 作者: Chenrui Fan, Paolo Favaro 分类: cs.CV
缺口
主流T2V评估(FVD、CLIP分数、审美评分)将每一帧独立看待,或者只检查时间平滑性。
这些指标无法判断一个看起来像摄像机环绕的视频是否对应着同一个刚性3D场景:椅子可能在帧之间变形,背景可能在观众未察觉时漂移。
之前的3D感知基准(如DreamBooth风格的多视图数据集)要么需要3D真值,要么局限于合成数据。
GeoT2V-Bench填补了这个空白:它不需要3D真值,就能诊断一个相机提示的T2V片段能否支持显式的刚性重建。
[问题:T2V视频看起来好,但3D一致性差]
    |
    v
[假设:视觉合理性不等于静态3D一致性]
    |
    v
[方法:灵活+静态高斯泼溅的重建流水线]
    |
    v
[证据:5个维度指标暴露正交的失败模式]
    |
    v
[结论:需要整体3D一致性评估,而非单一分数]
增量
一句话:之前没有一个工具能告诉你相机提示视频在3D上到底哪里错了; 现在GeoT2V-Bench给出了连续的、多轴的诊断。
核心机制
流水线输入一个T2V片段(含相机提示),输出五条连续曲线。
第一步:通过VGGT风格几何估计网络获取每帧的相机内参和位姿。
第二步:对整个片段拟合一个可变形高斯泼溅模型(DeformableGS)——它允许每个高斯在每帧移动。
第三步:取所有高斯位置的时间中位数,得到一个MedianGS静态代理——假设非刚性运动是噪声。
第四步:沿估计的相机路径从两个模型分别渲染新帧。
第五步:每帧计算五个指标:表观运动幅度、轨迹偏差、MedianGS重建误差、MedianGS渲染与原始视频的光流一致性、以及灵活建模与静态建模的渲染差距。
关键洞察:五个指标很少一致,因此每个指标捕捉到不同类型的失败——比如轨迹抖动、对象非刚性变形、或静态重建崩溃。
[输入:视频帧 + 相机提示]
    |
    v
[VGGT] -> 每帧内参和位姿
    |
    v
[DeformableGS] -> 每帧可变形场(灵活)
    |
    v
[MedianGS] -> 静态代理(时间中位数)
    |
    +--------------------+--------------------+
    |                    |                    |
[沿路径渲染]        [沿路径渲染]         [比较渲染结果]
    |                    |                    |
[表观运动]        [轨迹]              [5个指标]
结构核喻:想象一次电影片场的“蓝图校验”。
- VGGT 是一台激光测距仪,测量每个镜头时相机的位置。
- DeformableGS 是一位可以任意推开粘土块的雕塑家——这捕捉了物体是否真的动了(比如演员转身)。
- MedianGS 是一个石膏模,把粘土冻成一个固定形状,假设场景是刚性的。
- 五个指标是五个不同检查员:一个看相机路径是否平滑(轨迹),另一个看石膏模是否匹配每个原始视频帧(静态重建误差),第三个看石膏视频的光流是否与原始视频一致,等等。
如果雕塑家的推动幅度很大但石膏模看起来很差,视频很可能存在动态变形而非静态场景。如果石膏模看起来没问题但轨迹乱七八糟,提示的相机运动有问题。这个比喻成立是因为每个角色都有独特的失败信号。
关键概念
-
可变形高斯泼溅(DeformableGS):一种3D高斯表示,每个高斯有每帧的偏移量。可以建模移动物体或背景漂移。在本流水线中,它的渲染质量充当一个上限——即使灵活模型也失败,说明视频不可救药。
-
中位数静态高斯(MedianGS):对DeformableGS每个高斯的位置/尺度取时间中位数得到的静态场景代理。它代表了去掉所有运动后场景应有的样子。它的重建误差暴露了非刚性变形的程度。
-
重建轮廓:不输出单一通过/未通过分数,而是每条指标随时间变化的五条曲线。轮廓能揭示视频在哪种不一致上栽跟头:比如静态重建误差高+光流一致性低=深度3D不一致;轨迹偏差高=相机提示错位。
框架转变
旧方法把视频当作图像序列评估;新方法把它当作候选3D拍摄物来评估。
之前(主流方法):             之后(本文方法):
[T2V片段]                     [T2V片段]
   |                              |
[单帧级指标]                  [3D重建]
   |                              |
[单一分数]                    [5轴轮廓]
   |                              |
[答案:"好"或"差"]           [答案:"哪种失败模式?"]
一句话:从评判视觉外观转向诊断3D一致性,核心转变是把视频当作多视图拍摄而非平面动画。
专家评审
选题眼光:真缺口。随着可控制相机的T2V逐渐成熟,创作者需要知道输出能否作真实场景使用。领域之前缺少诊断性基准;本文合理填补。位于生成质量与3D几何正确性的边界,位置恰当。
方法成熟度:巧妙组合现有组件(VGGT、3DGS)加上新颖的聚合技巧(MedianGS)。主要创新是多指标轮廓而非单个部件。存在一定蛮力(拟合DeformableGS计算量大),但作者意识到这点,并提供了完整重建结果供复现。
实验诚意:公平——使用4个随机种子、12个模型配置(包括ZeroScope、ModelScope等开放权重)、来自GeCo-Eval的80个提示。发现各指标不一致的结论有充分证据。一个值得注意的点:VGGT可能偏向与其训练数据相似的视频,但作者使用固定估计器,因此模型间比较仍然有效。
写作功力:摘要和引言清晰。方法部分密集但逻辑有序。实验部分可以改进:针对每条指标展示一个失败模式的单一可视化(作者已有示例,但设计一个每视频“诊断卡”会让论文提升一个档次)。
判决:弱接收——可靠且必要的基准,但方法偏诊断而非生成;影响力取决于T2V社区的采纳程度。
要点总结
- MedianGS作为廉价的3D一致性代理:任何做T2V的人可以在自己流水线中(估算相机后)插入这个技巧,无需训练新模型即可获得每帧静态重建误差。
- 多指标轮廓优于单一分数:通过/未通过的掩码隐藏了具体故障。调试T2V模型时,知道它受“静态重建崩溃”(高MedianGS误差)还是“相机漂移”(轨迹偏差)困扰,能节省数小时。
- 四种子评估是公平做法的范例:许多基准只用一种子;作者展示模型排名会因种子变化,未来基准应采纳多种子评估。