Paper: 2607.08769 Authors: Weijian Chen, Weibo Yao, Yuhang Zhang, Xiaolin Tang, Guo Wang, Weijun Zhang, Xitong Gao, Yihao Chen, Hongde Qin, Lu Qi Categories: cs.CV
The Gap
3D Gaussian Splatting (3DGS) is fantastic for real-time rendering but hits a wall when scaling to large outdoor scenes. The problem isn’t just data size—it’s computational. To manage this, existing methods partition the scene into blocks, assigning cameras to each block for parallel, local training. This works because standard pinhole cameras have a limited field of view (frustum). However, when you switch to panoramic images (using equirectangular projection, or ERP), everything is different. A single panoramic camera sees in all directions (360°). This “omnipresent visibility” is the killer: it shatters the assumption of local visibility. A single panoramic image touches almost every part of the scene, so no clean partitioning based on camera frustums is possible. You’re forced to train everything globally, which is computationally infeasible for large scenes. This paper identifies this parallax-driven, non-local visibility problem as the fundamental gap for scaling panoramic 3DGS.
Problem: Scalable outdoor 3DGS needs scene partitioning.
   |
   v
Prior methods: Partition based on local camera frustums.
   |
   v
Assumption fails: Panoramic (ERP) cameras have full 360-degree FOV.
   |
   v
Result: Non-local visibility -> Partitioning breaks -> Global training -> Doesn't scale.
   |
   v
Solution: PanoLOG with G^2PS: Partition geometry and gradients instead of frustums.
   |
   v
Evidence: SOTA rendering on new Pano360 benchmark with block-parallel training.
The Increment
One sentence: Before this paper, you couldn’t efficiently do block-parallel 3D Gaussian Splatting reconstruction on large panoramic scenes; after, you can, thanks to a partitioning strategy that works with geometry and gradients, not camera frustums.
Core Mechanism
PanoLOG operates in a coarse-to-fine, two-stage pipeline. The first stage is global coarse reconstruction. Here, the goal isn’t perfection—it’s to establish a rough but geometrically reliable scaffold of the entire scene. To handle the vast, unbounded nature of outdoor scenes (like skies), it uses a sky-sphere model. To give the initial Gaussian positions a good sense of depth and structure, it leverages panoramic monocular depth supervision. This stage outputs a preliminary Gaussian cloud and, crucially, a depth map that will guide the next stage.
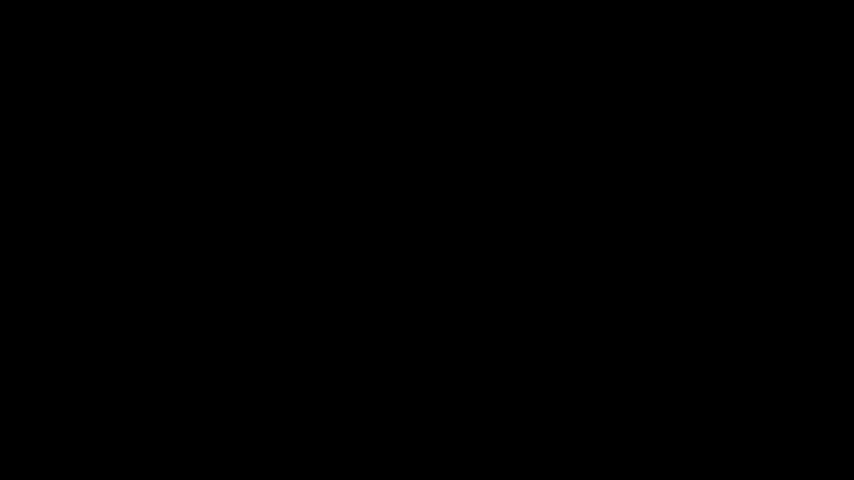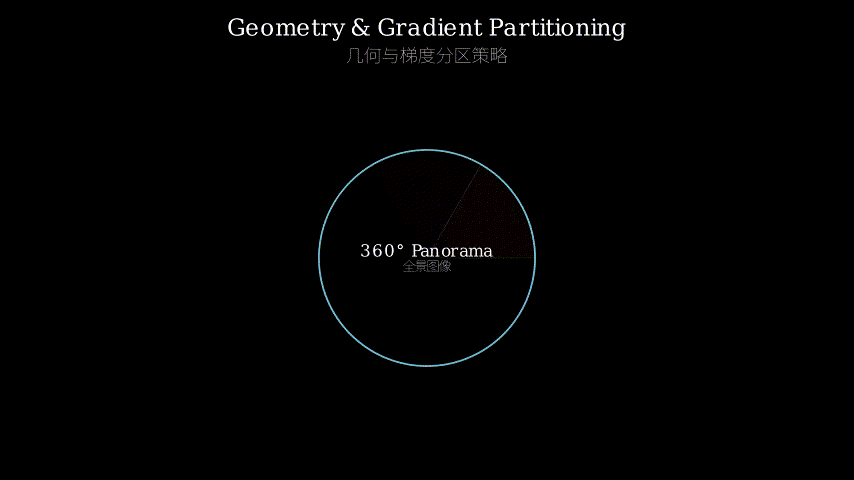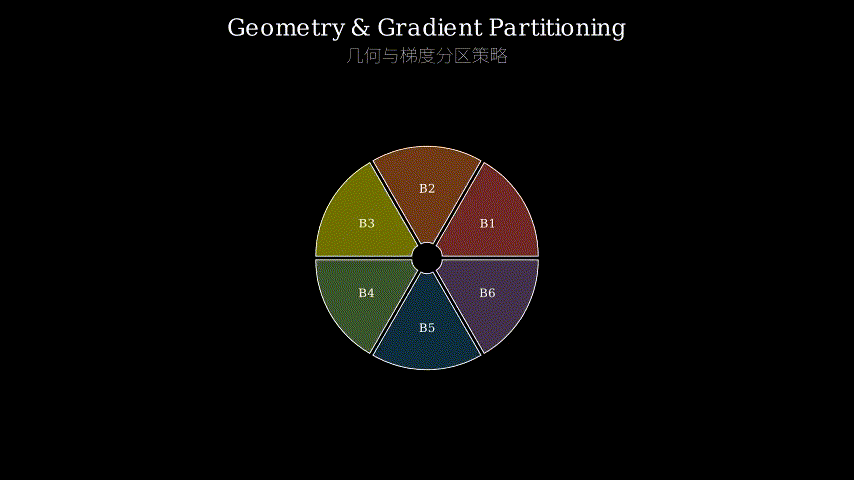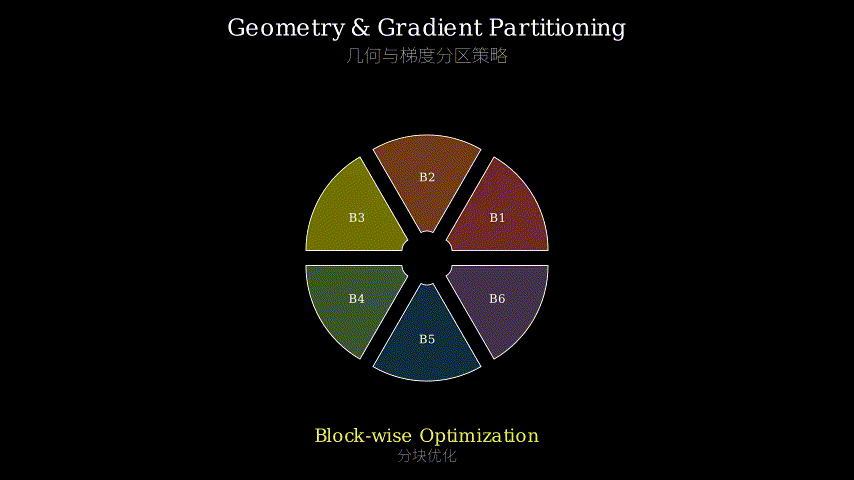
The second stage is where the magic happens: refinement with Geometry and Gradient-based Partitioning Strategy (G²PS). This is the core innovation that makes large-scale panoramic training feasible. G²PS builds adaptive bounding volumes (partitions) around regions of the scene. These volumes are not based on where cameras are looking (frustums), but on the parallax-driven uncertainty inherent in the 3D geometry itself. It identifies areas where the 3D structure is ambiguous or where many Gaussians contribute significantly to the render (high gradient importance). Cameras are then assigned to these volumes using a gradient-based importance scoring system—cameras that see a lot of the high-importance Gaussians in a volume get assigned there. This allows for clean, meaningful block partitions that respect the actual structure of the scene, enabling efficient parallel training.
Stage 1: Global Coarse
   [Panoramic Images + Monocular Depth]
                     |
                     v
         +-----------------------+
         | Sky-Sphere Model      |
         | + Gaussian Splatting  |
         +-----------------------+
                     |
                     v
       [Coarse Gaussian Cloud & Depth Map]

Stage 2: Refinement with G^2PS
   [Coarse Geometry]  [Raw Gradients]
          |                  |
          v                  v
   +------------------+   +--------------------+
   | Parallax-based   |   | Importance Scoring |
   | Uncertainty      |   | (Gradient Magnitude)|
   +------------------+   +--------------------+
                 \         /
                  v       v
          +---------------------+
          | Build Adaptive      |
          | Bounding Volumes    |
          +---------------------+
                   |
                   v
        [Assign Cameras to Volumes]
                   |
                   v
     [Block-Parallel Gaussian Optimization]
The structural metaphor: Think of building a giant mosaic from thousands of photos taken with a fisheye lens. The old way (frustum-based partitioning) would try to sort the photos by which *corner of the final mosaic they show. With a fisheye, every photo shows a bit of everything, so sorting is a nightmare—you end up having to look at all photos at once. PanoLOG’s G²PS is like a master mosaic artist who first sketches a rough outline of the whole image (coarse stage). Then, instead of sorting photos, they look at the tiles (Gaussians) themselves. They mark clusters of tiles where the color or shape is uncertain or very detailed (high gradient/uncertainty). Then, they assign each photo to the cluster of tiles it most clearly sees based on the angle and overlap. This way, you can work on different detailed clusters of the mosaic in parallel using the most relevant photos, even though each photo covers a wide area.
Key Concepts
- Equirectangular Projection (ERP): Imagine peeling the skin off an orange and laying it flat on a table. That flat rectangle is an ERP image. It captures the entire 360° sphere around the camera, but with heavy distortion, especially near the top (zenith) and bottom (nadir). In VR, your headset re-wraps this rectangle back into a sphere. For 3D reconstruction, this means every pixel in the image corresponds to a ray pointing in a specific direction, and the image as a whole covers *all directions from its capture point. This is why traditional, direction-limited camera assumptions fail.
- Parallax-driven Uncertainty: Parallax is the apparent shift of an object when viewed from different positions. In 3D, regions with high parallax (like foreground objects seen from multiple angles) have well-defined depth. Regions with low or consistent parallax (like a distant sky or a flat wall) are geometrically ambiguous—the 3D structure is uncertain. G²PS uses this uncertainty to decide where to partition: it groups Gaussians in these ambiguous or complex regions together, creating a volume that is coherently “hard to figure out.”
- Gradient-based Importance Scoring: During neural rendering training, you calculate how much each tiny Gaussian (a splat) contributes to the final image pixels by looking at the gradient of the loss. A large gradient for a Gaussian means tweaking it will significantly improve (or worsen) the render. G²PS uses this signal *before the fine-tuning stage, from the coarse model’s gradients. Cameras that are responsible for those high-gradient Gaussians (i.e., they see them clearly) are considered “important” for that volume and are assigned to refine it.
Framework Shift
Before (mainstream approach):           After (this paper):
Based on camera locations.              Based on scene geometry & gradient.

[Camera 1] [Camera 2] [Camera 3]       [Cluster A: Uncertain/G-high]
   |           |           |                    |
   v           v           v                    v
+-------+ +-------+ +-------+          +------------------+
|Frustum| |Frustum| |Frustum|          | Bounding Volume  |
| Block | | Block | | Block |          | (Gaussians +     |
+-------+ +-------+ +-------+          |  Assigned Cameras)|
                                        +------------------+
   Assumption: Camera FOV is local.     No assumption about camera FOV.
   Breaks for 360-degree cameras.       Works for any camera, especially ERP.
From X to Y, the core shift is partitioning the *reconstruction problem (3D Gaussians) instead of partitioning the observation space (camera views).
Expert Assessment
Problem choice: This is a genuine and practical bottleneck. The rise of 3DGS and the proliferation of 360° cameras (for VR, street-view, autonomous driving) made this gap inevitable. It’s a timely and well-defined engineering challenge for the field.
Method maturity: It’s a clever, necessary patch, not a brute-force hack. The coarse-to-fine approach is sound engineering. The novelty is in G²PS—using geometric uncertainty and gradient signals to drive partitioning is an insightful adaptation. A simpler approach might just use a fixed spatial grid, but that would ignore the actual data complexity, leading to poor load balancing. This is better.
Experimental integrity: The introduction of a new benchmark, Pano360, is a major positive contribution. Baselines seem fair, comparing against relevant 3DGS and NeRF partitioning methods. The numbers show clear gains in quality and scalability. The main potential red flag is that all experiments are on their own new dataset. While they justify this by the lack of an existing one, it’s always better to have multiple independent datasets. The claims on “state-of-the-art” are currently self-referential to their own benchmark.
Writing quality: The abstract and introduction are clear and effective. The method section, particularly the description of G²PS, could be more intuitive. It jumps into formulas quickly. The “how it works” story gets slightly lost in technicalities, which is why a metaphor is needed. Section 4 (Experiments) is thorough. The biggest missed opportunity is a more detailed failure analysis or limitations section.
Verdict: weak accept — It solves a real and specific problem with a reasonable method, provides a new community resource (benchmark), and demonstrates clear gains. It’s a solid incremental contribution for a CVPR/ICCV workshop or a mid-tier conference.
Takeaways
- Partitioning Strategy Transfer: The core idea of partitioning your *problem space (e.g., data features, model parameters) based on uncertainty or complexity gradients, rather than arbitrary input domains, is a powerful pattern. This could be applied in federated learning (partitioning by client data difficulty) or large-scale simulation (partitioning by regions of high dynamic complexity).
- Don’t Fight the Data, Guide with Geometry: If your input data has weird, non-standard properties (like 360° visibility), don’t try to force old pipelines to work. Instead, build a lightweight geometric proxy (like the coarse model with depth) first to understand the structure, and let that guide your core algorithm’s decisions.
- Benchmark Creation as Contribution: In new application spaces (like panoramic outdoor reconstruction), creating and open-sourcing a clean, well-structured benchmark is as valuable as the algorithmic method itself. It defines the field’s evaluation standard.
论文: 2607.08769 作者: Weijian Chen, Weibo Yao, Yuhang Zhang, Xiaolin Tang, Guo Wang, Weijun Zhang, Xitong Gao, Yihao Chen, Hongde Qin, Lu Qi 分类: cs.CV
缺口
3D高斯溅射(3DGS)在实时渲染上很出色,但扩展到大型户外场景时就遇到了瓶颈。问题不只是数据量大,更是计算成本高昂。 为此,现有方法会将场景划分为多个区块,将摄像头分配给各区块进行并行、局部训练。 这之所以可行,是因为标准针孔摄像头视野(视锥)有限。 然而,当改用全景图像(使用等距柱状投影,即ERP)时,一切就不同了。 单个全景摄像头能看到所有方向(360度)。 这种”无处不在的可见性”是致命的:它打破了基于局部可见性的假设。 单张全景图像几乎触及场景的每个部分,因此无法基于摄像头视锥进行清晰的分区。 你被迫进行全局训练,这在大场景中计算上不可行。 本文将这一由视差驱动的非局部可见性问题确定为全景3DGS扩展的根本缺口。
问题:可扩展的户外3DGS需要场景分区。
   |
   v
既有方法:基于局部摄像头视锥分区。
   |
   v
假设失效:全景(ERP)摄像头具有全360度视野。
   |
   v
结果:非局部可见性 -> 分区失败 -> 全局训练 -> 无法扩展。
   |
   v
解决方案:PanoLOG与G^2PS:基于几何和梯度而非视锥进行分区。
   |
   v
证据:在新的Pano360基准上,使用区块并行训练达到最先进的渲染质量。
增量
一句话: 这篇论文之前,你无法对大型全景场景进行高效的区块并行3D高斯溅射重建;之后,你可以了,这得益于一种基于几何和梯度而非摄像头视锥的分区策略。
核心机制
PanoLOG采用由粗到精的两阶段流程。 第一阶段是全局粗重建。 此阶段的目标不是完美,而是建立整个场景的大致但几何上可靠的骨架。 为处理户外场景(如天空)的巨大、无界特性,它使用了天球模型。 为给初始高斯位置提供良好的深度和结构感,它利用了全景单目深度监督。 此阶段输出一个初步的高斯点云,以及一个至关重要的深度图,它将引导下一阶段。
第二阶段是魔法发生的地方:基于几何和梯度分区策略(G^2PS)的精细化。 这是使大规模全景训练可行的核心创新。 G^2PS围绕场景区域构建自适应包围体(分区)。 这些包围体并非基于摄像头看向哪里(视锥),而是基于3D几何本身固有的视差驱动不确定性。 它识别3D结构模糊或许多高斯体对渲染贡献显著(梯度重要性高)的区域。 然后,使用基于梯度的重要性评分系统将摄像头分配给这些体积——一个体积中,清晰看到许多高重要性高斯体的摄像头会被分配到那里。 这允许进行清晰、有意义的区块划分,尊重场景的实际结构,从而实现高效的并行训练。
阶段一:全局粗重建
   [全景图像 + 单目深度]
              |
              v
   +------------------------+
   | 天球模型                |
   | + 高斯溅射             |
   +------------------------+
              |
              v
    [粗略高斯点云 & 深度图]

阶段二:G^2PS 精细化
   [粗略几何]        [原始梯度]
       |                  |
       v                  v
+-----------------+  +-------------------+
| 基于视差的       |  | 重要性评分        |
| 不确定性         |  |(梯度幅度)        |
+-----------------+  +-------------------+
              \         /
               v       v
       +----------------------+
       | 构建自适应包围体      |
       +----------------------+
                |
                v
      [将摄像头分配给包围体]
                |
                v
    [区块并行的高斯优化]
核喻(结构性比喻): 想象用鱼眼镜头拍的成千上万张照片拼一幅巨型马赛克。 旧方法(基于视锥分区)会尝试根据照片显示马赛克的哪个角落来对照片分类。 用鱼眼镜头,每张照片都显示了所有内容的一点,所以分类是一场噩梦——你最终不得不同时看所有照片。 PanoLOG的G^2PS就像一位马赛克大师,他首先勾勒出整幅图像的粗略轮廓(粗略阶段)。 然后,他不再对照片分类,而是查看瓷砖(高斯体)本身。 他标记出颜色或形状不确定或非常精细的瓷砖集群(高梯度/不确定性)。 然后,他根据角度和重叠度,将每张照片分配给它最清晰看到的瓷砖集群。 这样,你就可以使用最相关的照片,并行地处理马赛克的不同精细集群,即使每张照片都覆盖了很大区域。
关键概念
- 等距柱状投影(ERP): 想象剥开一个橘子的皮,平铺在桌子上。那张扁平的矩形就是ERP图像。 它捕获了摄像头周围整个360度的球面,但存在严重畸变,尤其是在靠近天顶和天底的地方。 在VR中,头显会将这个矩形重新包裹成球体。 对于三维重建,这意味着图像中的每个像素都对应一个指向特定方向的射线,而整幅图像从其拍摄点覆盖了所有方向。 这就是传统的、方向受限的摄像头假设失效的原因。
- 视差驱动不确定性: 视差是从不同位置观看时物体的表观偏移。 在三维中,视差高的区域(如从多个角度看到的前景物体)具有明确的深度。 视差低或一致的区域(如远处的天空或平坦的墙壁)在几何上是模糊的——三维结构是不确定的。 G^2PS利用这种不确定性来决定在哪里分区:它将这些模糊或复杂区域中的高斯体分组在一起,创建一个连贯的”难以确定”的体积。
- 基于梯度的重要性评分: 在神经渲染训练中,通过查看损失的梯度,可以计算每个微小高斯体(一个溅点)对最终图像像素的贡献程度。 一个高斯体的大梯度意味着调整它将显著改善(或恶化)渲染效果。 G^2PS在精调阶段之前,利用粗模型的梯度信号。 负责这些高梯度高斯体的摄像头(即它们清晰看到这些高斯体)被认为是该体积的”重要”摄像头,并被分配去精化它。
框架转变
之前(主流方法):                  之后(本文方法):
基于摄像头位置。                    基于场景几何与梯度。
   |                                   |
[摄像头1] [摄像头2] [摄像头3]         [集群A:不确定/高梯度]
   |           |           |                   |
   v           v           v                   v
+-------+ +-------+ +-------+         +------------------+
|视锥体 | |视锥体 | |视锥体 |         | 包围体           |
| 区块  | | 区块  | | 区块  |         | (高斯体 +        |
+-------+ +-------+ +-------+         |  分配的摄像头)   |
                                       +------------------+
假设:摄像头视野是局部的。             不对摄像头视野做假设。
对360度摄像头失效。                    适用于任何摄像头,尤其是ERP。
从 X 到 Y,核心转变是对重建问题(三维高斯体)进行分区,而不是对观测空间(摄像头视图)进行分区。
专家评审
选题眼光: 这是一个真实且实际的瓶颈。 随着3DGS的兴起以及360度摄像头(用于VR、街景、自动驾驶)的普及,这个缺口变得不可避免。 对于该领域来说,这是一个及时且定义明确的工程挑战。
方法成熟度: 这是一个巧妙、必要的补丁,而非蛮力黑客。 由粗到精的方法是合理的工程思路。 新颖之处在于G^2PS——利用几何不确定性和梯度信号来驱动分区是一种有洞见的改编。 更简单的方法可能只是使用固定的空间网格,但这会忽略实际数据的复杂性,导致负载不均衡。 现在的方法更好。
实验诚意: 引入新的基准Pano360是一个重要的积极贡献。 基线看起来公平,与相关的3DGS和NeRF分区方法进行了比较。 数据在质量和可扩展性方面显示出明显的优势。 主要的潜在危险信号是所有实验都在他们自己的新数据集上进行。 虽然他们以缺乏现有数据集为由进行辩解,但拥有多个独立的数据集总是更好的。 关于”最先进”的说法目前仅相对于他们自己的基准而言。
写作功力: 摘要和引言清晰有效。 方法部分,特别是G^2PS的描述,可以更直观一些。 它很快就进入了公式。 “它是如何工作的”的故事在技术细节中有些丢失,这就是为什么需要一个比喻。 第4节(实验)很详尽。 最大的遗憾是没有一个更详细的失败分析或局限性部分。
判决: 弱接收 — 它用合理的方法解决了一个真实而具体的问题,提供了新的社区资源(基准),并展示了明显的收益。 对于CVPR/ICCV研讨会或中级会议来说,这是一个坚实的增量贡献。
要点总结
- 分区策略迁移: 基于不确定性或复杂性梯度对你的问题空间(例如,数据特征、模型参数)进行分区,而不是对任意输入域进行分区,这是一个强大的模式。 这可以应用于联邦学习(按客户端数据难度分区)或大规模模拟(按高动态复杂性区域分区)。
- 勿逆数据而行,以几何为引: 如果你的输入数据具有奇怪的、非标准的属性(如360度可见性),不要试图强行使用旧的管道。 相反,首先构建一个轻量级的几何代理(如带深度的粗略模型)来理解结构,并让它引导核心算法的决策。
- 创建基准即贡献: 在新的应用领域(如全景户外重建),创建并开源一个干净、结构良好的基准,其价值不亚于算法方法本身。 它定义了该领域的评估标准。