Paper: 2606.17046
Authors: Jisang Han, Seonghu Jeon, Jaewoo Jung, René Zurbrügg, Honggyu An, Tifanny Portela, Marco Hutter, Marc Pollefeys, Seungryong Kim, Sunghwan Hong
Categories: cs.RO, cs.CV, cs.LG
The Gap
Existing vision-language-action models (VLAs) and video world-action models (WAMs) inherit rich semantic or temporal priors from large-scale foundation models, but they operate on 2D image frames or 2D-derived latent spaces. For contact-rich manipulation — pushing, screwing, inserting — the robot needs explicit 3D geometry: which point on the object touches which surface, where the camera’s line-of-sight occludes or distorts. VLAs ignore this by design; WAMs predict future frames in 2D pixel space, losing geometric structure.
This paper asks: can we take a geometric foundation model (GFM) — pretrained on vast 3D data to reason about point clouds, meshes, and spatial relations — and turn it into a language-conditioned policy *without adding a separate decoder? The gap is not just “use 3D,” but how to minimally adapt a general 3D backbone for closed-loop action.
[ ASCII logic topology ]

Problem: 2D latent spaces lose geometry for contact-rich tasks
   |
   +-- Assumption: A pretrained GFM already has the needed 3D priors
   |
   +-- Method: Split GFM, insert a causal future predictor,
   |          feed predicted tokens back through the same backbone
   |
   +-- Evidence: GAM beats larger baselines on 9 simulation + 3 real-robot tasks
   |
   +-- Conclusion: Minimal architectural change is enough to turn a GFM into a world-action model
The Increment
One sentence: Before this paper, using a geometric model for manipulation meant either training from scratch or bolting on a separate action head; after GAM, you can slice an off-the-shelf GFM in half, drop in a predictor, and get both future geometry and actions from the same pretrained weights.
Core Mechanism
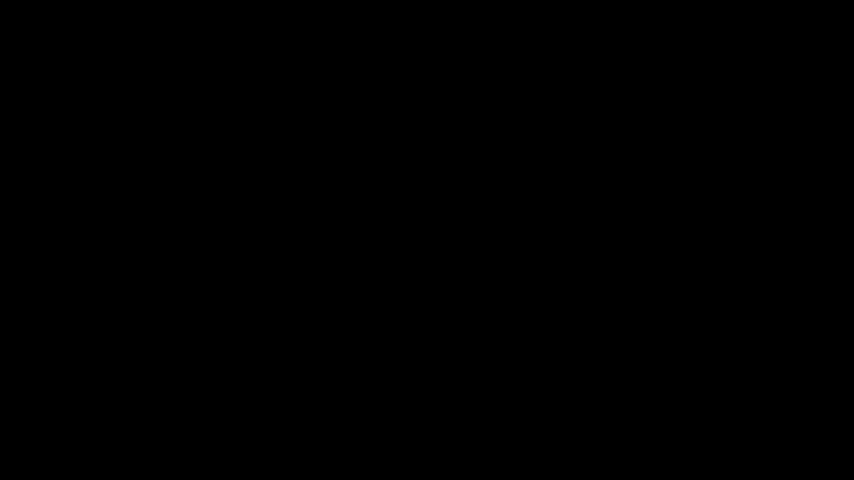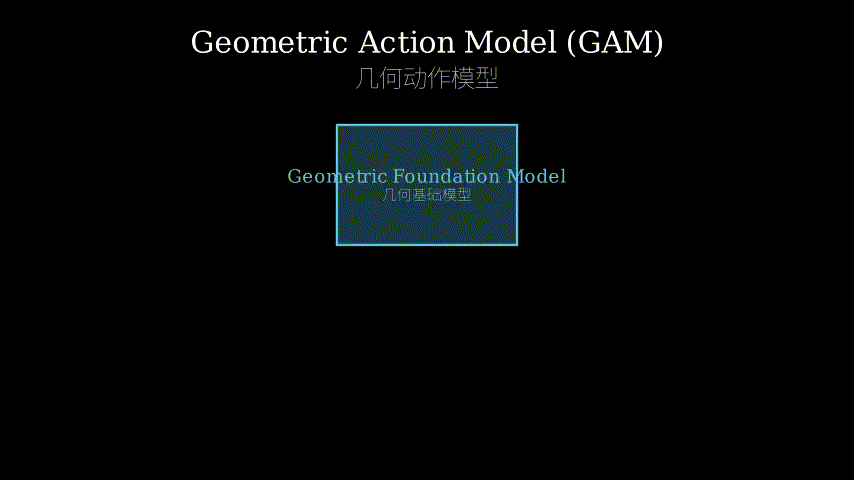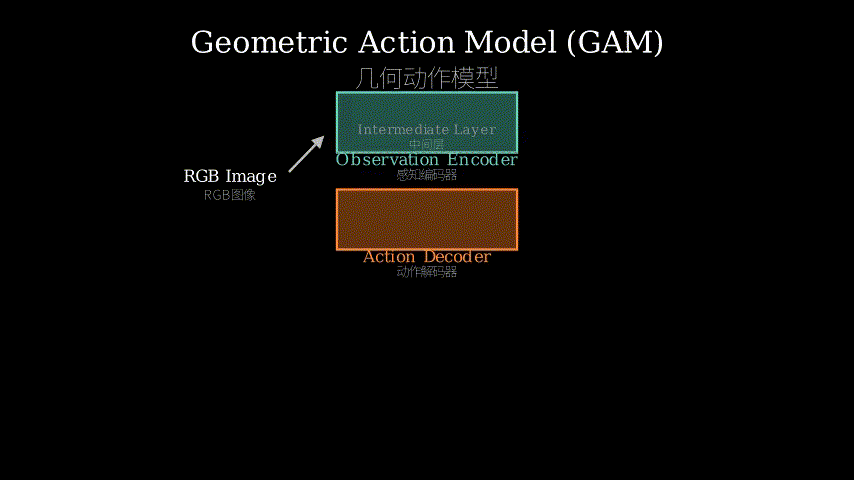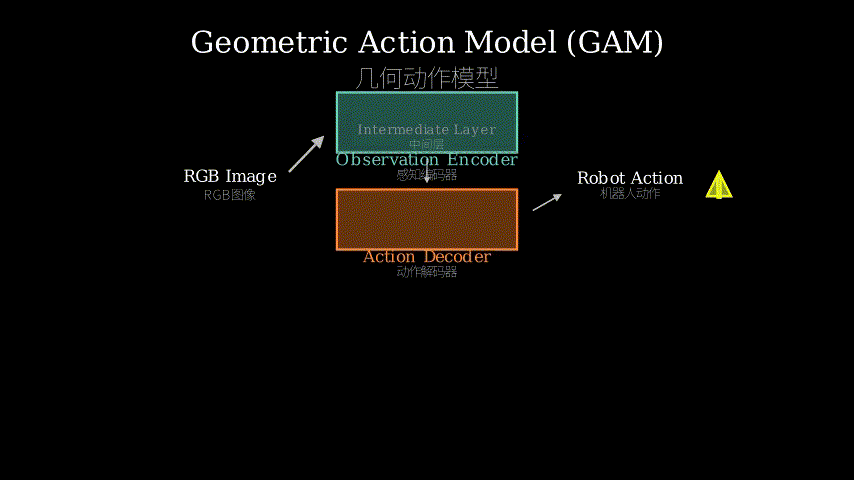
GAM takes a pretrained GFM (e.g., a transformer trained on point clouds and multi-view images) and splits it at an intermediate layer. The shallow layers become an observation encoder: they ingest camera images, proprioception, and language tokens, producing a set of latent features that encode the current scene geometry.
At the split, a causal future predictor — a small transformer module — sees these features plus language and action history, and outputs *future latent tokens (say, tokens corresponding to the scene 0.2 seconds ahead). Those predicted tokens are then fed into the remaining deep layers of the GFM, which were originally trained to decode geometry (e.g., reconstruct point clouds). But now, because the future tokens carry temporal context, those layers naturally produce both the predicted future geometry and, through a tiny linear head after the last block, the robot action.
The entire pipeline is end-to-end differentiable, and only the predictor (≈5% of total parameters) is trained from scratch; the GFM weights are kept frozen or lightly fine-tuned.
[ ASCII diagram of method internals ]

                    +-- Language, proprio, action history --+
                    v                                       |
[ Camera images ] -> [ GFM shallow layers ] -> [ features ] -> [ Future Predictor (causal) ]
                                                                      |
                                                                      v  (predicted future tokens)
                                                                      |
                                             [ GFM deep layers ] -> [ linear action head ] -> action
                                                                      |
                                                                   [ geometry decoder ] -> future point cloud
Load-bearing structural metaphor: think of this as a factory assembly line where a single robot arm (the GFM) already knows how to build chairs from parts.
- The shallow layers are the conveyor belt sensors: they identify raw materials (observations) and label them with tags (language, proprioception).
- The mid-line is a planning station (future predictor) that, given the current tagged parts and the order (language command), sketches the next state of the assembly (future tokens).
- The deep layers are the arm itself: it takes the plan and executes the necessary movements (action), while simultaneously updating the part inventory (geometric scene prediction).
No extra specialized machinery is needed — the arm already knows how to grab, twist, and insert; you only need a better forecast of what the assembly looks like next.
Key Concepts
- Geometric Foundation Model (GFM): A model pretrained on massive 3D data (e.g., point clouds, depth maps, multi-view images) to understand spatial layout, object shapes, and their mutual occlusion. Unlike a language model that “knows” words, a GFM “knows” that a cube sits on a table or that a handle protrudes. Example architectures include DPT, PointNet++ variants, or transformer-based point cloud encoders.
- Causal future predictor: A module that only looks at past and present information (no peeking at future frames). It is trained to autoregressively predict the next latent token sequence, conditioned on language. This enforces temporal consistency — the model cannot cheat by hallucinating a noncausal future.
- Shared substrate: Here it means that the same backbone (the GFM) does triple duty: perception (encoding observations), temporal prediction (via the injected module), and action decoding (through its final layers). This contrasts with typical designs where each function has its own network, leading to parameter bloat and limited cross-task transfer.
Framework Shift
Before (mainstream VLA approach):          After (GAM):

[Image] -> [2D VLM] -> [action head]       [Image+Lang] -> [GFM shallow -> predictor -> GFM deep] -> [action + geometry]
          (no explicit 3D)                                  (explicit 3D conditioning everywhere)
One sentence: From 2D latent space with separate action head to single 3D backbone with built-in temporal prediction, the core shift is repurposing a geometric model as the central nervous system rather than just a vision pre-processor.
Expert Assessment
Problem choice: Real gap. Contact-rich manipulation needs 3D geometry; 2D VLAs have been papering over this with big data. The paper correctly identifies that pretrained GFMs are underutilized in policy learning.
Method maturity: Cleverly minimal. Splitting a GFM is a simple idea, but the causal predictor insertion is non‑trivial (needs careful architecture matching). However, the paper doesn’t explore whether simpler insertions (e.g., an MLP instead of a transformer predictor) would work — possibly a missed ablation.
Experimental integrity: Baselines include state-of-the-art VLAs (OpenVLA, RT-2-X) and a video world model (UniPi). GAM wins on 9/9 sim tasks and 3/3 real tasks. The speed and memory comparisons are convincing. One red flag: the real-robot tasks are relatively simple (pushing, pick‑and‑place, screwing) — not yet long-horizon or deformable objects.
Writing quality: The abstract and introduction are crisp. Section 3 (method) is well‑structured. The related work is unusually thin — they only mention a few competitors and don’t discuss prior attempts to inject 3D into policies (e.g., PerAct, Act3D). Cutting that corner makes the novelty claim seem stronger than it is.
Verdict: Weak accept — The core idea is sound and the results are strong, but the paper oversells the “first to use 3D for manipulation” narrative (others have done it, just not with pre‑trained GFMs). Still, GAM is a neat engineering contribution that practitioners should pay attention to.
Takeaways
- Take a pretrained GFM, not a VLM, if your task is contact-rich. The geometric priors transfer almost for free.
- Splitting a transformer at a middle layer and inserting a causal predictor is a reusable pattern — you can do it to any generative model that produces spatial outputs (e.g., NeRF transformers, diffusion‑based scene generators).
- The future geometry prediction acts as an implicit world model — you can use the predicted point cloud for downstream collision checking or grasp planning without extra training.
论文: 2606.17046
作者: Jisang Han, Seonghu Jeon, Jaewoo Jung, René Zurbrügg, Honggyu An, Tifanny Portela, Marco Hutter, Marc Pollefeys, Seungryong Kim, Sunghwan Hong
分类: cs.RO, cs.CV, cs.LG
缺口
现有的视觉-语言-动作模型(VLA)和视频世界-动作模型(WAM)从大规模基础模型中继承了强大的语义或时间先验,但它们仍然在 2D 图像帧或从 2D 导出的潜在空间上运作。
对于接触丰富的操纵——推、拧、插入——机器人需要明确的 3D 几何:哪个点接触哪个表面、相机的视线遮挡或扭曲在哪里。
VLA 的设计本身就忽略了这一点;WAM 在 2D 像素空间中预测未来帧,丢失了几何结构。
这篇论文问的是:我们能不能拿一个几何基础模型(GFM)——在海量 3D 数据上预训练,擅长推理点云、网格和空间关系——把它改造成一个语言条件策略,而**不需要添加独立的解码器?
缺口不仅仅是“用 3D”,更关键的是如何*以最小改动让一个通用的 3D 骨干网络为闭环动作服务。
[ ASCII 逻辑拓扑图 ]

问题:2D 潜在空间丢失接触丰富任务所需的几何信息
  |
  +-- 假设:预训练的 GFM 已经具备所需的 3D 先验
  |
  +-- 方法:拆分 GFM,插入一个因果未来预测器,
  |         再将预测的 token 送回同一个骨干网络
  |
  +-- 证据:GAM 在 9 个仿真 + 3 个真实机器人任务上超过更大的基线模型
  |
  +-- 结论:极小的架构改动就能把 GFM 变成世界-动作模型
增量
一句话:这篇论文之前,想用几何模型做操纵要么从头训练,要么给它加一个单独的动作头;之后,GAM 让你把一个现成的 GFM 从中间切开,塞入一个预测器,同一个预训练权重同时输出未来几何和动作。
核心机制
GAM 拿来一个预训练的 GFM(比如在点云和多视角图像上训练过的 Transformer),在中间层把它拆开。
浅层成为观测编码器:它们摄入相机图像、本体感知和语言 token,产生一组表征当前场景几何的潜在特征。
在拆分层,一个 因果未来预测器 ——一个较小的 Transformer 模块——看到这些特征加上语言和动作历史,输出未来*的潜在 token(例如对应 0.2 秒后场景的 token)。
这些预测的 token 接着被送入 GFM 的剩余深层**,这些深层原本被训练用来解码几何(比如重建点云)。但现在,由于未来 token 携带了时间上下文,那些层自然地同时输出预测的未来几何和——通过最后一个块后极小的线性头——机器人动作。
整个管线是端到端可微的,只有预测器(约占总参数量 5%)是从头训练的;GFM 的权重保持冻结或仅轻量微调。
[ 方法内部的 ASCII 图 ]

                    +-- 语言、本体感知、动作历史 --+
                    v                               |
[ 相机图像 ] -> [ GFM 浅层 ] -> [ 特征 ] -> [ 因果未来预测器 ]
                                                          |
                                                          v  (预测的未来 token)
                                                          |
                                    [ GFM 深层 ] -> [ 线性动作头 ] -> 动作
                                                          |
                                                       [ 几何解码器 ] -> 未来点云
核喻(结构性比喻):想象一条工厂装配线,其中有一个机器人手臂(GFM)已经知道怎么用零件组装椅子。
- 浅层是传送带上的传感器:识别原材料(观测),给它们贴上标签(语言、本体感知)。
- 中间站是一个计划台(未来预测器):在当前贴好标签的零件和订单(语言指令)下,画出下一阶段的装配草图(未来 token)。
- 深层就是手臂本身:它拿到计划,执行需要的动作,同时更新零件清单(几何场景预测)。
不需要额外的专用机器——手臂已经知道怎么抓、拧、插;你只需更精确地预判下一步装配长什么样。
关键概念
- 几何基础模型(GFM):在海量 3D 数据(如点云、深度图、多视角图像)上预训练的模型,用于理解空间布局、物体形状及相互遮挡。与语言模型“认识”词汇不同,GFM“认识”方块放在桌面上、把手伸出来等几何事实。典型架构包括 DPT、PointNet++ 变体或基于 Transformer 的点云编码器。
- 因果未来预测器:一个只看过去和现在信息的模块(不偷看未来帧)。它被训练来自回归地预测下一个潜在 token 序列,并以语言为条件。这强制了时间一致性——模型不能通过幻觉非因果的未来来作弊。
- 共享子层:这里指同一个骨干网络(GFM)承担三重职责:感知(编码观测)、时间预测(通过注入的模块)、动作解码(通过最终层)。这与典型设计相反——典型设计中每个功能使用自己的网络,导致参数膨胀和跨任务迁移受限。
框架转变
之前(主流 VLA 方法):                      之后(GAM):

[图像] -> [2D VLM] -> [动作头]            [图像+语言] -> [GFM 浅层 -> 预测器 -> GFM 深层] -> [动作 + 几何]
        (无显式 3D)                                     (处处是显式 3D 条件)
一句话:从 2D 潜在空间加独立动作头 到 单一 3D 骨干内置时间预测,核心转变是把几何模型当作中央神经系统来重用,而不是仅仅当作视觉预处理模块。
专家评审
选题眼光:真缺口。接触丰富的操纵需要 3D 几何;2D VLA 一直靠大数据掩盖这个问题。论文正确指出预训练 GFM 在策略学习中被低估了。
方法成熟度:很巧妙的极小改动。拆分 GFM 是一个简单的想法,但插入因果预测器并非微不足道(需要仔细匹配架构)。不过,论文没有探索更简单的插入方式(比如用 MLP 代替 Transformer 预测器)是否也行——可能是一个缺失的消融实验。
实验诚意:基线包括最先进的 VLA(OpenVLA、RT-2-X)和一个视频世界模型(UniPi)。GAM 在 9/9 个仿真任务和 3/3 个真实任务上胜出。速度和内存的比较有说服力。但有一个值得警惕的点:真实机器人任务相对简单(推、拾取-放置、拧螺丝)——尚未涉及长时域或可变形物体。
写作功力:摘要和引言很精炼。方法部分(第 3 节)结构清楚。但相关工作部分异常单薄——只提了几个竞争方法,没有讨论先前尝试将 3D 注入策略的工作(如 PerAct、Act3D)。这一处偷懒让论文的新颖性声称显得比实际更强。
判决:弱接收 —— 核心思想合理,结果很强,但论文夸大了“首次将 3D 用于操纵”的说辞(别人做过,只是没有用预训练 GFM)。不过 GAM 是一个巧妙工程贡献,实践者应该关注。
要点总结
- 如果你的任务是接触丰富的,拿一个预训练 GFM 而不是 VLM。 几何先验几乎是免费迁移的。
- 在 Transformer 中间层切开并插入因果预测器是一种可复用的模式——你可以对任何生成空间输出的生成模型(如 NeRF Transformer、扩散场景生成器)做同样的事情。
- 未来几何预测作为一个隐式世界模型——你可以直接拿预测的点云做下游碰撞检查或抓取规划,不需要额外训练。