Paper: 2605.23888 Authors: Katharina Schmid, Nicolas von Lützow, Jozef Hladký, Angela Dai, Matthias Nießner Categories: cs.CV
The Gap
Multi-view 3D reconstruction has reached a point where methods can produce geometrically consistent meshes from posed RGB images. Neural radiance fields (NeRFs) and Gaussian splatting excel at novel view synthesis but struggle with complete, watertight geometry. Traditional multi-view stereo (MVS) produces meshes but lacks detail in textureless or occluded regions. Meanwhile, generative 3D models like Trellis have learned rich priors from large-scale 3D datasets, producing high-fidelity object meshes with complete geometry and PBR materials. The gap: these generative priors operate at object scale and don’t naturally extend to multi-view, scene-scale reconstruction where spatial extent is large and input views are sparse and irregularly distributed.
Problem: Object-level generative priors =/=> Scene-level reconstruction
   |
   v
Assumption: Chunk scenes into overlapping regions, condition generation
            on multi-view features via projection
   |
   v
Method: Spatially-localized generation + projection-based conditioning
   |
   v
Evidence: 16% improvement over baselines, high-fidelity PBR meshes
   |
   v
Conclusion: Generative priors scale to scenes when properly conditioned
The Increment
One sentence: Before this paper, generative 3D priors were confined to single objects; after, they can be applied to multi-view scene reconstruction by chunking space and projecting image features into a coherent 3D representation.
Core Mechanism
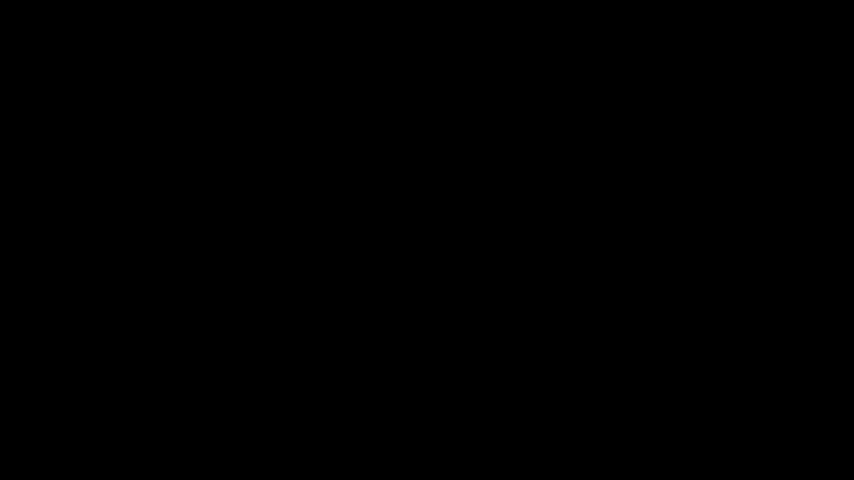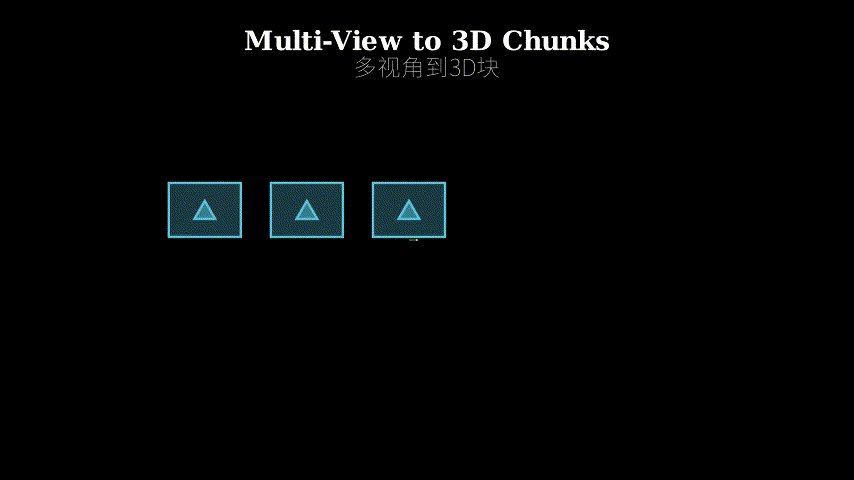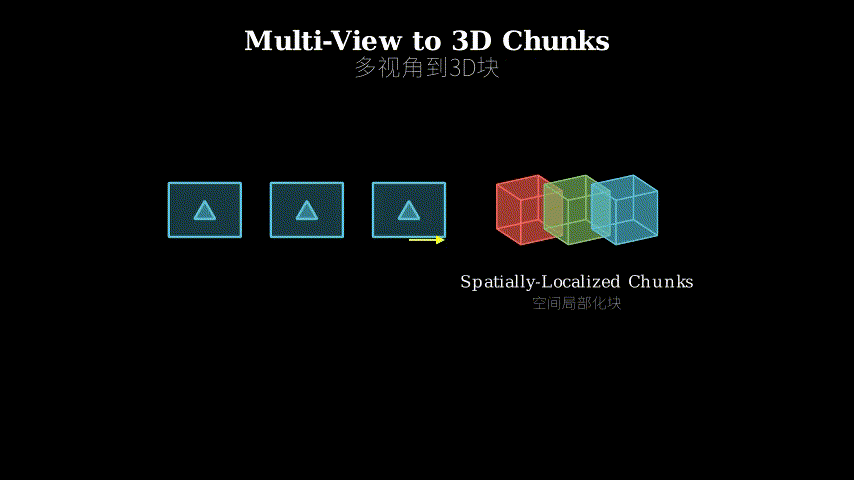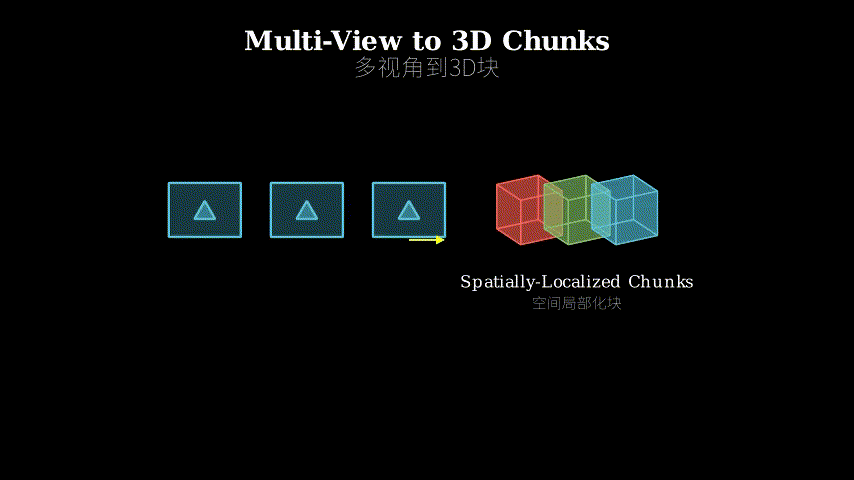
GenRecon operates in two stages. First, it tiles the scene into overlapping 3D chunks, each small enough for a generative model to handle. Second, for each chunk, it conditions the generative model (Trellis.2) using a projection-based mechanism: multi-view image features are lifted into a 3D voxel grid aligned with the chunk, then fed as conditioning input to the generative model’s denoising process.
The projection mechanism works by extracting features from each input view using a 2D encoder, then projecting these features into 3D space using camera poses. Features from multiple views are aggregated at each voxel location, creating a spatially-anchored 3D feature volume. This volume is independent of view ordering and provides dense conditioning even in regions visible to only a few cameras. The generative model then produces a structured latent representation (SLAT) for the chunk, which decodes into a mesh with PBR materials.
Input: Multi-view RGB images + camera poses
   |
   v
[2D Feature Extraction] ---> Per-view feature maps
   |
   v
[Projection + Aggregation] ---> 3D feature volume (chunk-aligned)
   |
   v
[Conditional Generation] ---> SLAT latent (via Trellis.2)
   |
   v
[Decoding] ---> PBR mesh for chunk
   |
   v
[Chunk Merging] ---> Full scene mesh
Think of it like assembling a large mosaic from photographs. You can’t print the entire mosaic at once—your printer (the generative model) only handles letter-sized pages (chunks). So you divide the mosaic into overlapping tiles. For each tile, you don’t just guess what should be there; you project the relevant parts of your reference photos onto that tile’s area, blending information from multiple angles. The printer then fills in the tile using both the projected photo evidence and its learned understanding of what mosaics should look like (the generative prior). Finally, you stitch the tiles together, using the overlaps to ensure seamless joins. The key insight: the projection step anchors the generative process to actual observations, preventing hallucination while preserving the prior’s ability to complete occluded regions.
Key Concepts
-
Projection-based conditioning: Instead of encoding multi-view images into a global latent code (which loses spatial information) or processing views sequentially (which creates order dependence), GenRecon projects 2D image features into 3D space using known camera geometry. Each voxel in the 3D volume accumulates features from all views that see that location. This creates a spatially-grounded conditioning signal: the generative model knows not just “what the scene looks like” but “what each specific region looks like from multiple viewpoints.” It’s the difference between describing a building from memory versus pointing at it from several street corners—the latter grounds your description in physical space.
-
Structured Latent (SLAT): Trellis.2 represents 3D shapes as SLATs—latent codes organized in a spatial grid rather than a single global vector. Each grid cell encodes local geometry and appearance. This structure is crucial for scene-scale generation: you can condition different spatial regions independently, generate them in parallel, and merge them coherently. A global latent would force the entire scene through a single bottleneck; SLAT lets you scale by dividing and conquering.
-
Chunk-based generation: Large scenes exceed the spatial extent that generative models can handle in one shot (both in terms of memory and learned prior distribution). GenRecon divides the scene into overlapping 3D chunks, generates each independently, then merges them. The overlap ensures smooth transitions—like shingles on a roof, each chunk covers part of its neighbor’s territory, allowing blending at boundaries. This scales generation from object-level (1-2 meters) to room-level (10+ meters) without retraining the base model.
Framework Shift
Before (mainstream approach):        After (this paper):

Multi-view images                    Multi-view images
       |                                    |
       v                                    v
  [MVS / NeRF]                    [Feature Projection]
       |                                    |
       v                                    v
  Geometry only                    3D Feature Volume
  (no strong prior)                        |
       |                                    v
       v                          [Chunked Generation]
  Incomplete mesh                   (with generative prior)
                                           |
                                           v
                                   Complete PBR mesh
[One sentence: From direct geometric reconstruction without priors to conditioning generative priors on multi-view observations, the core shift is treating reconstruction as spatially-grounded conditional generation rather than pure geometry estimation.]
Expert Assessment
Problem choice: This is a real gap. Generative 3D models have demonstrated impressive object-level quality, but their application to multi-view reconstruction has been limited. The problem sits at the intersection of two mature subfields (MVS and generative modeling) that haven’t been tightly coupled before. The timing is right—generative models are now good enough to provide useful priors, and the question of how to scale them to scenes is natural.
Method maturity: The approach is well-engineered rather than conceptually novel. Chunking is a standard scaling strategy, and projection-based feature aggregation has precedent in multi-view stereo. The contribution is in the integration: showing that you can condition a generative model this way and get coherent results. The method is somewhat brute-force (generate many chunks, merge them), but given the constraints of existing generative models, it’s a reasonable path. A simpler approach might be to fine-tune the generative model on scene-scale data, but that requires new datasets and training infrastructure.
Experimental integrity: The 16% improvement claim is based on standard metrics (Chamfer distance, F-score) against recent baselines (SuGaR, 2DGS, GOF). The baselines are fair—they represent the current state of multi-view reconstruction. However, the paper doesn’t deeply analyze failure modes or provide ablations on key design choices (e.g., chunk size, overlap amount, aggregation strategy). The results look strong visually, but quantitative analysis is somewhat surface-level. No red flags, but more rigor would strengthen the claims.
Writing quality: The paper is clearly written but front-loads technical details without sufficient motivation. The introduction jumps quickly into method description before establishing why projection-based conditioning is necessary. The related work section is thorough but could better position the work relative to concurrent efforts in scene-scale generation. The experiments section would benefit from failure case analysis—when does the method struggle? The supplementary material likely contains more detail, but the main paper should be more self-contained.
Verdict: weak accept — Solid engineering contribution that successfully bridges object-level generative priors to scene-scale reconstruction, with convincing results, but lacks conceptual novelty and deep experimental analysis.
Takeaways
Projection as a conditioning mechanism: When you have a generative model trained on one domain (objects) and want to apply it to another (scenes), don’t just feed it global features—project observations into the model’s native spatial structure. This pattern transfers: if you’re adapting a 2D generative model to video, project frame features into a 3D spacetime volume; if you’re adapting a text model to structured documents, project sentence embeddings into a document layout grid.
Chunking with overlap for spatial coherence: When scaling generation beyond the model’s training distribution, divide the output space into overlapping regions and blend at boundaries. The overlap size is a hyperparameter that trades off redundancy (more computation) against seam artifacts (less blending). This applies to any spatial generation task: large images, long videos, extended audio.
Structured latents for scalability: If you’re designing a generative model for data with spatial or temporal extent, avoid global latent codes. Use spatially-organized latents (grids, octrees, hash tables) so you can condition and generate different regions independently. This architectural choice determines whether your model can scale beyond its training resolution.
论文: 2605.23888 作者: Katharina Schmid, Nicolas von Lützow, Jozef Hladký, Angela Dai, Matthias Nießner 分类: cs.CV
缺口
多视角 3D 重建已经能从带位姿的 RGB 图像生成几何一致的网格。
神经辐射场(NeRF)和高斯点云擅长新视角合成,但难以产生完整的、水密的几何体。
传统的多视角立体视觉(MVS)能生成网格,但在无纹理或遮挡区域缺乏细节。
与此同时,像 Trellis 这样的生成式 3D 模型从大规模 3D 数据集中学到了丰富的先验,能生成高保真的物体网格,带有完整几何和 PBR 材质。
缺口在于:这些生成式先验在物体尺度上运作,无法自然扩展到多视角、场景尺度的重建——那里空间范围大,输入视角稀疏且分布不规则。
问题:物体级生成先验 =/=> 场景级重建
   |
   v
假设:将场景分块为重叠区域,通过投影用多视角特征
      条件化生成过程
   |
   v
方法:空间局部化生成 + 基于投影的条件化
   |
   v
证据:比基线提升 16%,高保真 PBR 网格
   |
   v
结论:生成先验在适当条件化下可扩展到场景
增量
一句话: 这篇论文之前,生成式 3D 先验局限于单个物体;之后,通过空间分块和将图像特征投影到连贯的 3D 表示中,它们可以应用于多视角场景重建。
核心机制
GenRecon 分两个阶段运作。
首先,它将场景切分为重叠的 3D 块,每块足够小,生成模型能够处理。
其次,对每个块,它使用基于投影的机制条件化生成模型(Trellis.2):多视角图像特征被提升到与块对齐的 3D 体素网格中,然后作为条件输入送入生成模型的去噪过程。
投影机制的工作方式是:用 2D 编码器从每个输入视角提取特征,然后使用相机位姿将这些特征投影到 3D 空间。
来自多个视角的特征在每个体素位置聚合,创建一个空间锚定的 3D 特征体。
这个体积独立于视角顺序,即使在只有少数相机可见的区域也能提供密集的条件化信号。
然后生成模型为该块生成结构化潜在表示(SLAT),解码为带 PBR 材质的网格。
输入:多视角 RGB 图像 + 相机位姿
   |
   v
[2D 特征提取] ---> 每视角特征图
   |
   v
[投影 + 聚合] ---> 3D 特征体(与块对齐)
   |
   v
[条件化生成] ---> SLAT 潜在表示(通过 Trellis.2)
   |
   v
[解码] ---> 块的 PBR 网格
   |
   v
[块合并] ---> 完整场景网格
把它想象成用照片拼装大型马赛克。
你不能一次打印整个马赛克——你的打印机(生成模型)只能处理信纸大小的页面(块)。
所以你把马赛克分成重叠的瓦片。
对每个瓦片,你不是凭空猜测应该放什么;你把参考照片的相关部分投影到该瓦片的区域上,融合来自多个角度的信息。
然后打印机使用投影的照片证据和它学到的马赛克应该是什么样子的理解(生成先验)来填充瓦片。
最后,你拼接瓦片,利用重叠部分确保无缝衔接。
关键洞察:投影步骤将生成过程锚定到实际观测上,防止幻觉,同时保留先验完成遮挡区域的能力。
关键概念
- 基于投影的条件化: 与其将多视角图像编码为全局潜在码(会丢失空间信息)或顺序处理视角(会产生顺序依赖),GenRecon 使用已知的相机几何将 2D 图像特征投影到 3D 空间。
3D 体中的每个体素从所有能看到该位置的视角累积特征。
这创建了一个空间基础的条件化信号:生成模型不仅知道”场景看起来是什么样”,还知道”每个特定区域从多个视角看起来是什么样”。
这就像凭记忆描述一栋建筑和从几个街角指着它描述的区别——后者将你的描述基于物理空间。
- 结构化潜在表示(SLAT): Trellis.2 将 3D 形状表示为 SLAT——在空间网格中组织的潜在码,而不是单个全局向量。
每个网格单元编码局部几何和外观。
这种结构对场景尺度生成至关重要:你可以独立条件化不同的空间区域,并行生成它们,并连贯地合并它们。
全局潜在表示会强制整个场景通过单一瓶颈;SLAT 让你通过分而治之来扩展。
- 基于块的生成: 大场景超出了生成模型一次能处理的空间范围(无论是内存还是学习到的先验分布)。
GenRecon 将场景分成重叠的 3D 块,独立生成每个块,然后合并它们。
重叠确保平滑过渡——就像屋顶上的瓦片,每块覆盖邻居的部分领地,允许在边界处混合。
这将生成从物体级(1-2 米)扩展到房间级(10+ 米),无需重新训练基础模型。
框架转变
之前(主流方法):                之后(本文方法):

多视角图像                        多视角图像
       |                                |
       v                                v
  [MVS / NeRF]                  [特征投影]
       |                                |
       v                                v
  仅几何                          3D 特征体
  (无强先验)                           |
       |                                v
       v                        [分块生成]
  不完整网格                    (带生成先验)
                                       |
                                       v
                                 完整 PBR 网格
[一句话:从无先验的直接几何重建到在多视角观测上条件化生成先验,核心转变是将重建视为空间基础的条件化生成,而非纯几何估计。
]
专家评审
选题眼光: 这是真实的缺口。
生成式 3D 模型已展示出令人印象深刻的物体级质量,但它们在多视角重建中的应用一直受限。
问题位于两个成熟子领域(MVS 和生成建模)的交叉点,它们之前没有被紧密耦合。
时机恰当——生成模型现在足够好,可以提供有用的先验,如何将它们扩展到场景是自然的问题。
方法成熟度: 这个方法工程化良好,而非概念上新颖。
分块是标准的扩展策略,基于投影的特征聚合在多视角立体视觉中有先例。
贡献在于集成:展示你可以用这种方式条件化生成模型并获得连贯结果。
方法有些蛮力(生成许多块,合并它们),但考虑到现有生成模型的约束,这是合理的路径。
更简单的方法可能是在场景尺度数据上微调生成模型,但那需要新数据集和训练基础设施。
实验诚意: 16% 的改进声明基于标准指标(Chamfer 距离、F-score)对比最近的基线(SuGaR、2DGS、GOF)。
基线是公平的——它们代表多视角重建的当前状态。
然而,论文没有深入分析失败模式或提供关键设计选择的消融实验(例如块大小、重叠量、聚合策略)。
结果在视觉上看起来很强,但定量分析有些表面。
没有危险信号,但更严格的分析会加强声明。
写作功力: 论文写得清楚,但在充分动机之前就前置了技术细节。
引言在建立为什么需要基于投影的条件化之前就快速跳入方法描述。
相关工作部分很全面,但可以更好地将工作相对于场景尺度生成的并行努力定位。
实验部分会受益于失败案例分析——方法何时挣扎?补充材料可能包含更多细节,但主论文应该更自包含。
判决: 弱接收 — 扎实的工程贡献,成功地将物体级生成先验桥接到场景尺度重建,结果令人信服,但缺乏概念新颖性和深入的实验分析。
要点总结
投影作为条件化机制: 当你有一个在某个领域(物体)上训练的生成模型,想将它应用到另一个领域(场景)时,不要只是喂给它全局特征——将观测投影到模型的原生空间结构中。
这个模式可迁移:如果你要将 2D 生成模型适配到视频,将帧特征投影到 3D 时空体中;如果你要将文本模型适配到结构化文档,将句子嵌入投影到文档布局网格中。
带重叠的分块以实现空间连贯性: 当将生成扩展到超出模型训练分布时,将输出空间分成重叠区域并在边界处混合。
重叠大小是一个超参数,在冗余(更多计算)和接缝伪影(更少混合)之间权衡。
这适用于任何空间生成任务:大图像、长视频、扩展音频。
结构化潜在表示以实现可扩展性: 如果你正在为具有空间或时间范围的数据设计生成模型,避免全局潜在码。
使用空间组织的潜在表示(网格、八叉树、哈希表),这样你可以独立条件化和生成不同区域。
这个架构选择决定了你的模型能否扩展到超出其训练分辨率。